Tag: Apache 2.0
-
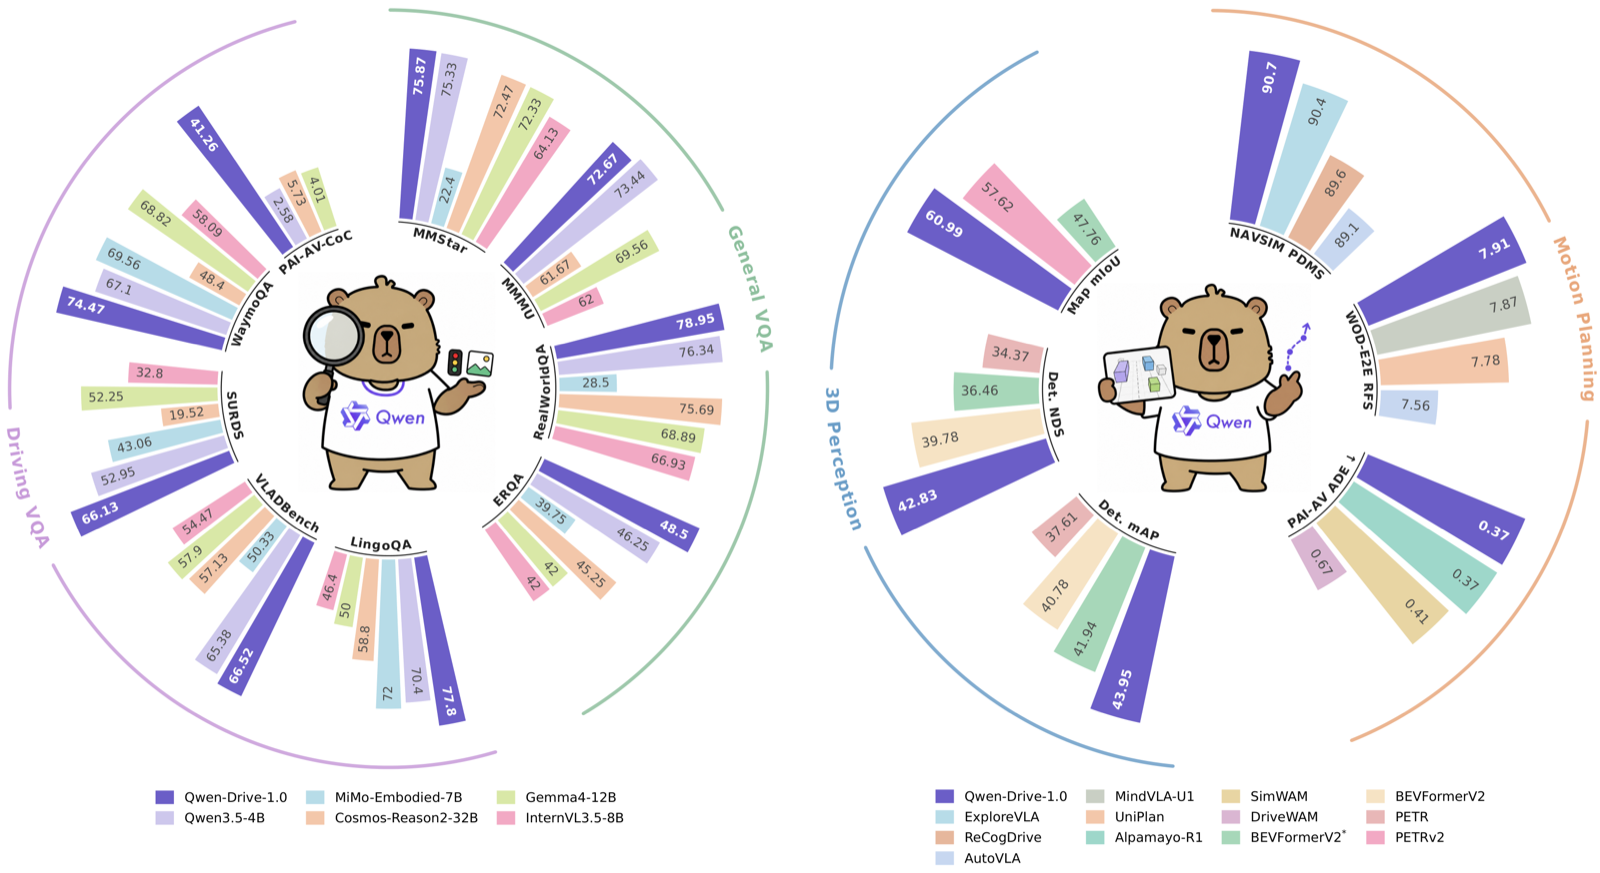
Qwen-Drive-1.0-4B: Alibaba Open-Weights a Driving Foundation Model
Alibaba’s Qwen team released Qwen-Drive-1.0-4B on September 7, 2026 — an open-weight vision-language foundation model for autonomous driving that puts 3D perception, driving question-answering, and motion planning inside a single 5-billion-parameter system. Developed with Huazhong University of Science and Technology and published under Apache 2.0 on Hugging Face, ModelScope, and GitHub, it is the Qwen […]
-
Qwen3.8-27B: Frontier Agentic Scores on a Single Consumer GPU
Alibaba released Qwen3.8-27B on August 14, 2026 — a 27-billion-parameter dense vision-language model under Apache 2.0, published on Hugging Face and ModelScope. It is the small sibling of the 2.4-trillion-parameter Qwen3.8-Max whose weights went up the day before, and on several agentic benchmarks it does not behave like a small model at all: 61.7 on […]
-
Mistral Releases Shieldstral, a 3B Policy-Adaptive Safety Classifier
On August 4, 2026, Mistral AI released Shieldstral 1.0 — a 3-billion-parameter open-weight safety classifier that judges both text and images against moderation policies written in plain language at inference time. Instead of shipping a fixed taxonomy of harm categories baked in during training, Shieldstral asks whatever question you hand it. Mistral says the model […]
-
Thinking Machines Releases Inkling, Its First Open-Weight Model
On July 15, 2026, Thinking Machines Lab released Inkling — its first model trained from scratch and, notably, its first open-weight release. Founded in February 2025 by former OpenAI CTO Mira Murati, the lab is best known for the Tinker fine-tuning platform; Inkling is a 975-billion-parameter Mixture-of-Experts model (41B active) published under the permissive Apache […]
-
Tencent Releases Hy3: 295B Open MoE Model Under Apache 2.0
Tencent has released Hy3, the full production version of its Hunyuan reasoning-and-agent model, following up on the Hy3 Preview that launched in late April 2026. Hy3 is a 295-billion-parameter Mixture-of-Experts (MoE) model with 21 billion active parameters, and it ships fully open-source under the Apache 2.0 license — weights, quantized variants, and inference recipes included. […]
-
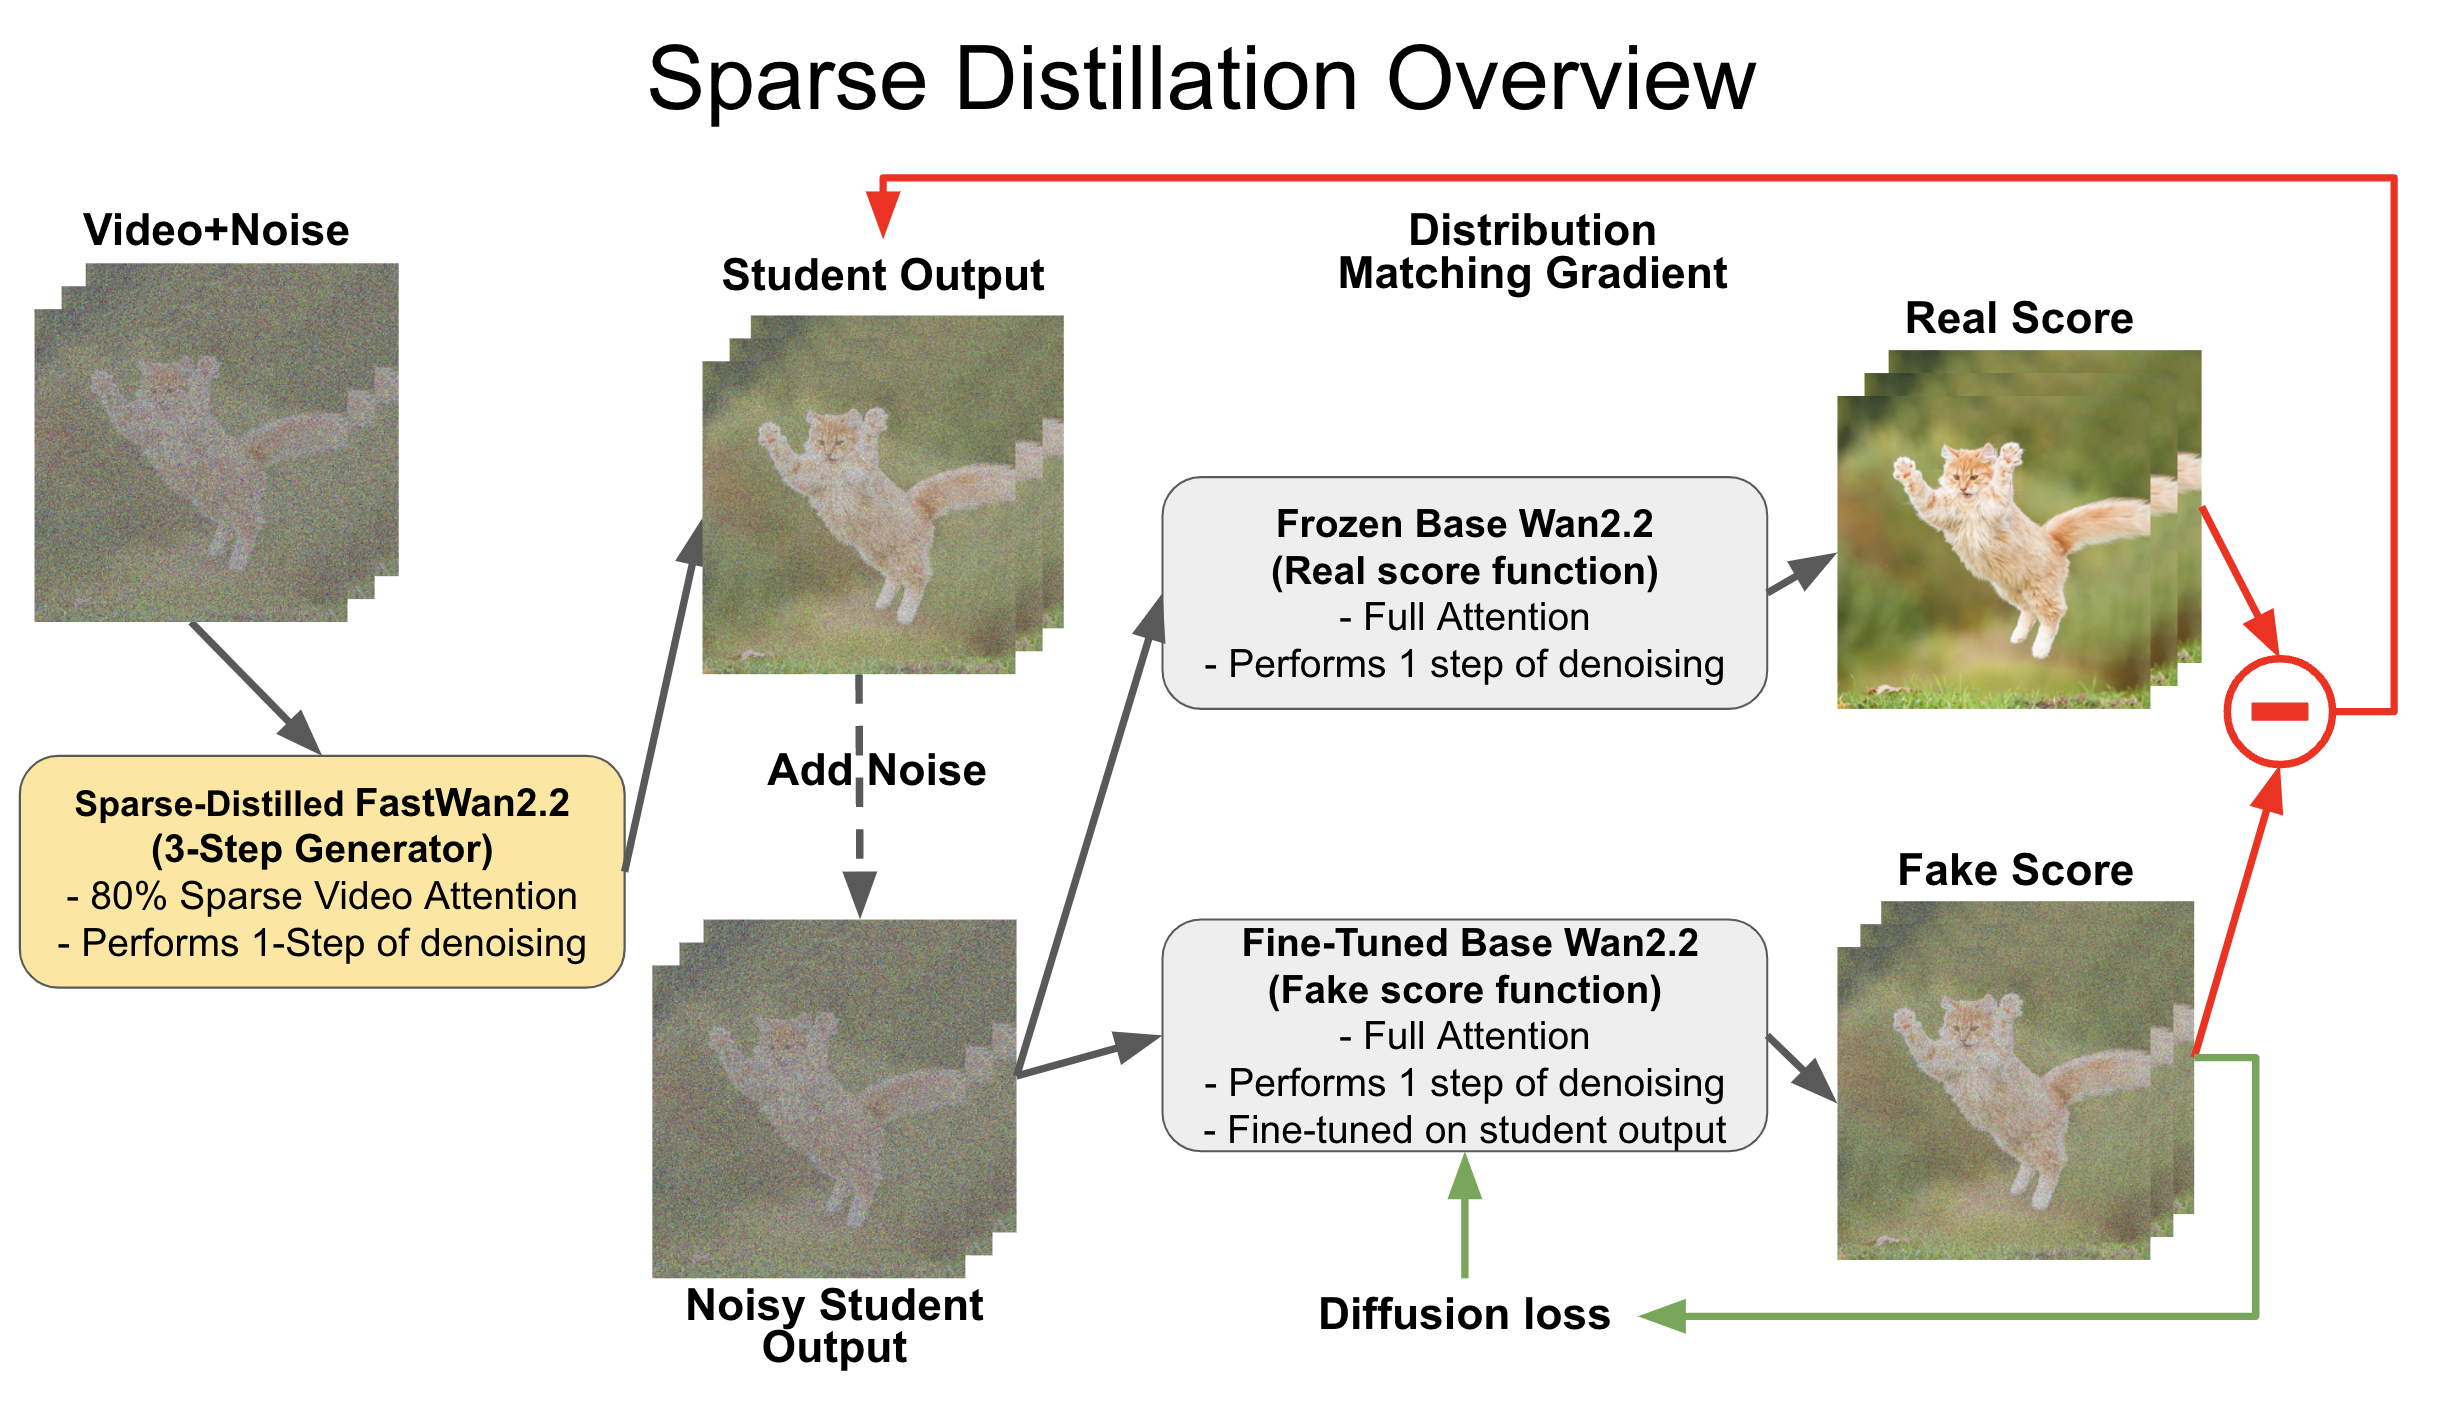
FastWan Generates a 5-Second Video in 5 Seconds via Sparse Distillation
FastWan generates a 5-second video in about 5 seconds on a single GPU — and the team at UC San Diego’s Hao AI Lab did it by training the model to be fast rather than patching speed on at inference time. Released under Apache-2.0 with full weights, training recipes, and datasets, FastWan introduces Sparse Distillation: […]
-
SupraLabs Ships a 30M-Parameter Any-to-Any Model
SupraLabs has released Supra-A2A-Nano-Exp, an experimental ~30-million-parameter “any-to-any” model that handles text, images, and video in a single autoregressive transformer — small enough to run on a laptop CPU. Released under Apache 2.0 by the independent research group behind a string of trending ultra-small models, it is framed not as a capable generator but as […]
-
Google Ships Gemma 4 QAT Models: 72% Less VRAM, Same Quality
Lead — On June 5, 2026, Google DeepMind released quantization-aware training (QAT) checkpoints for the entire Gemma 4 family, cutting memory requirements by roughly 72% while keeping output quality nearly identical to the full-precision models. The release spans every size — from the sub-1 GB E2B edge model to the 31B dense flagship — and […]
-
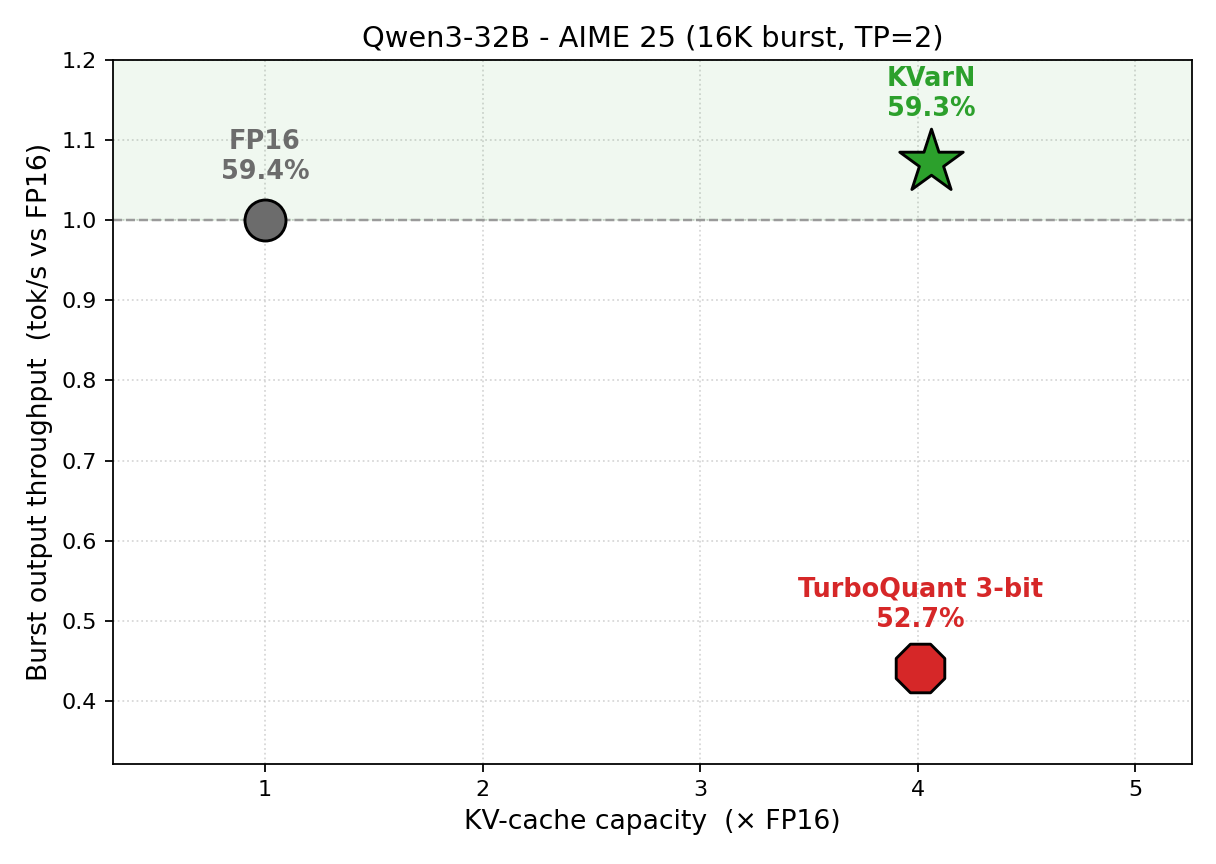
Huawei’s KVarN Hits 5x KV-Cache Capacity at FP16 Accuracy and Throughput
On June 2, 2026, Huawei researchers released KVarN — a variance-normalized KV-cache quantization backend for vLLM that breaks the long-standing tradeoff between cache compression and inference speed. KVarN delivers 3–5× more context capacity at 2-bit precision while keeping FP16-level accuracy and beating FP16 throughput, all behind a single vLLM flag with no calibration. It ships […]
-
Google Releases Gemma 4 12B: Frontier Multimodal AI on a Laptop
Lead — On June 3, 2026, Google DeepMind released Gemma 4 12B, a unified, encoder-free multimodal model that brings frontier-class intelligence to a single 16 GB laptop. The 11.95-billion-parameter model handles text, images, and audio in one decoder-only transformer, supports a 256K-token context across 140+ languages, and ships under a fully permissive Apache 2.0 license. Google […]