Tag: benchmark
-
SK Telecom Opens A.X K2: 688B Parameters and One Telling Benchmark
SK Telecom released A.X K2 on July 29, 2026 — a 688-billion-parameter Mixture-of-Experts model published on Hugging Face under Apache 2.0, and the largest model yet to come out of Korea’s government-backed sovereign AI program. The headline numbers are strong: 97.1 on AIME26, 80.5 on KMMLU-Pro, and a wall of perfect 100s on needle-in-a-haystack retrieval […]
-
Kimi K3 Open Weights Ship: 2.8T Parameters, 1.4 TB to Run
Moonshot AI released the full Kimi K3 weights on July 27, 2026, hitting the date it promised when the model debuted eleven days earlier. K3 is a 2.8-trillion-parameter Mixture-of-Experts model with a 1-million-token context window and native vision — the first open 3T-class model ever published. The download is 1.56 TB across 118 files, and […]
-
Google’s Gemini 3.6 Flash Cuts Agent Token Costs by up to 65%
On July 21, 2026, Google DeepMind released Gemini 3.6 Flash, Gemini 3.5 Flash-Lite, and Gemini 3.5 Flash Cyber — a refresh of the entire Flash tier aimed squarely at teams running AI agents at scale. The headline claim is not a higher intelligence ceiling but a lower bill: 3.6 Flash uses 17% fewer output tokens […]
-
Kimi K3 Hits Third on Artificial Analysis; Open Weights Due July 27
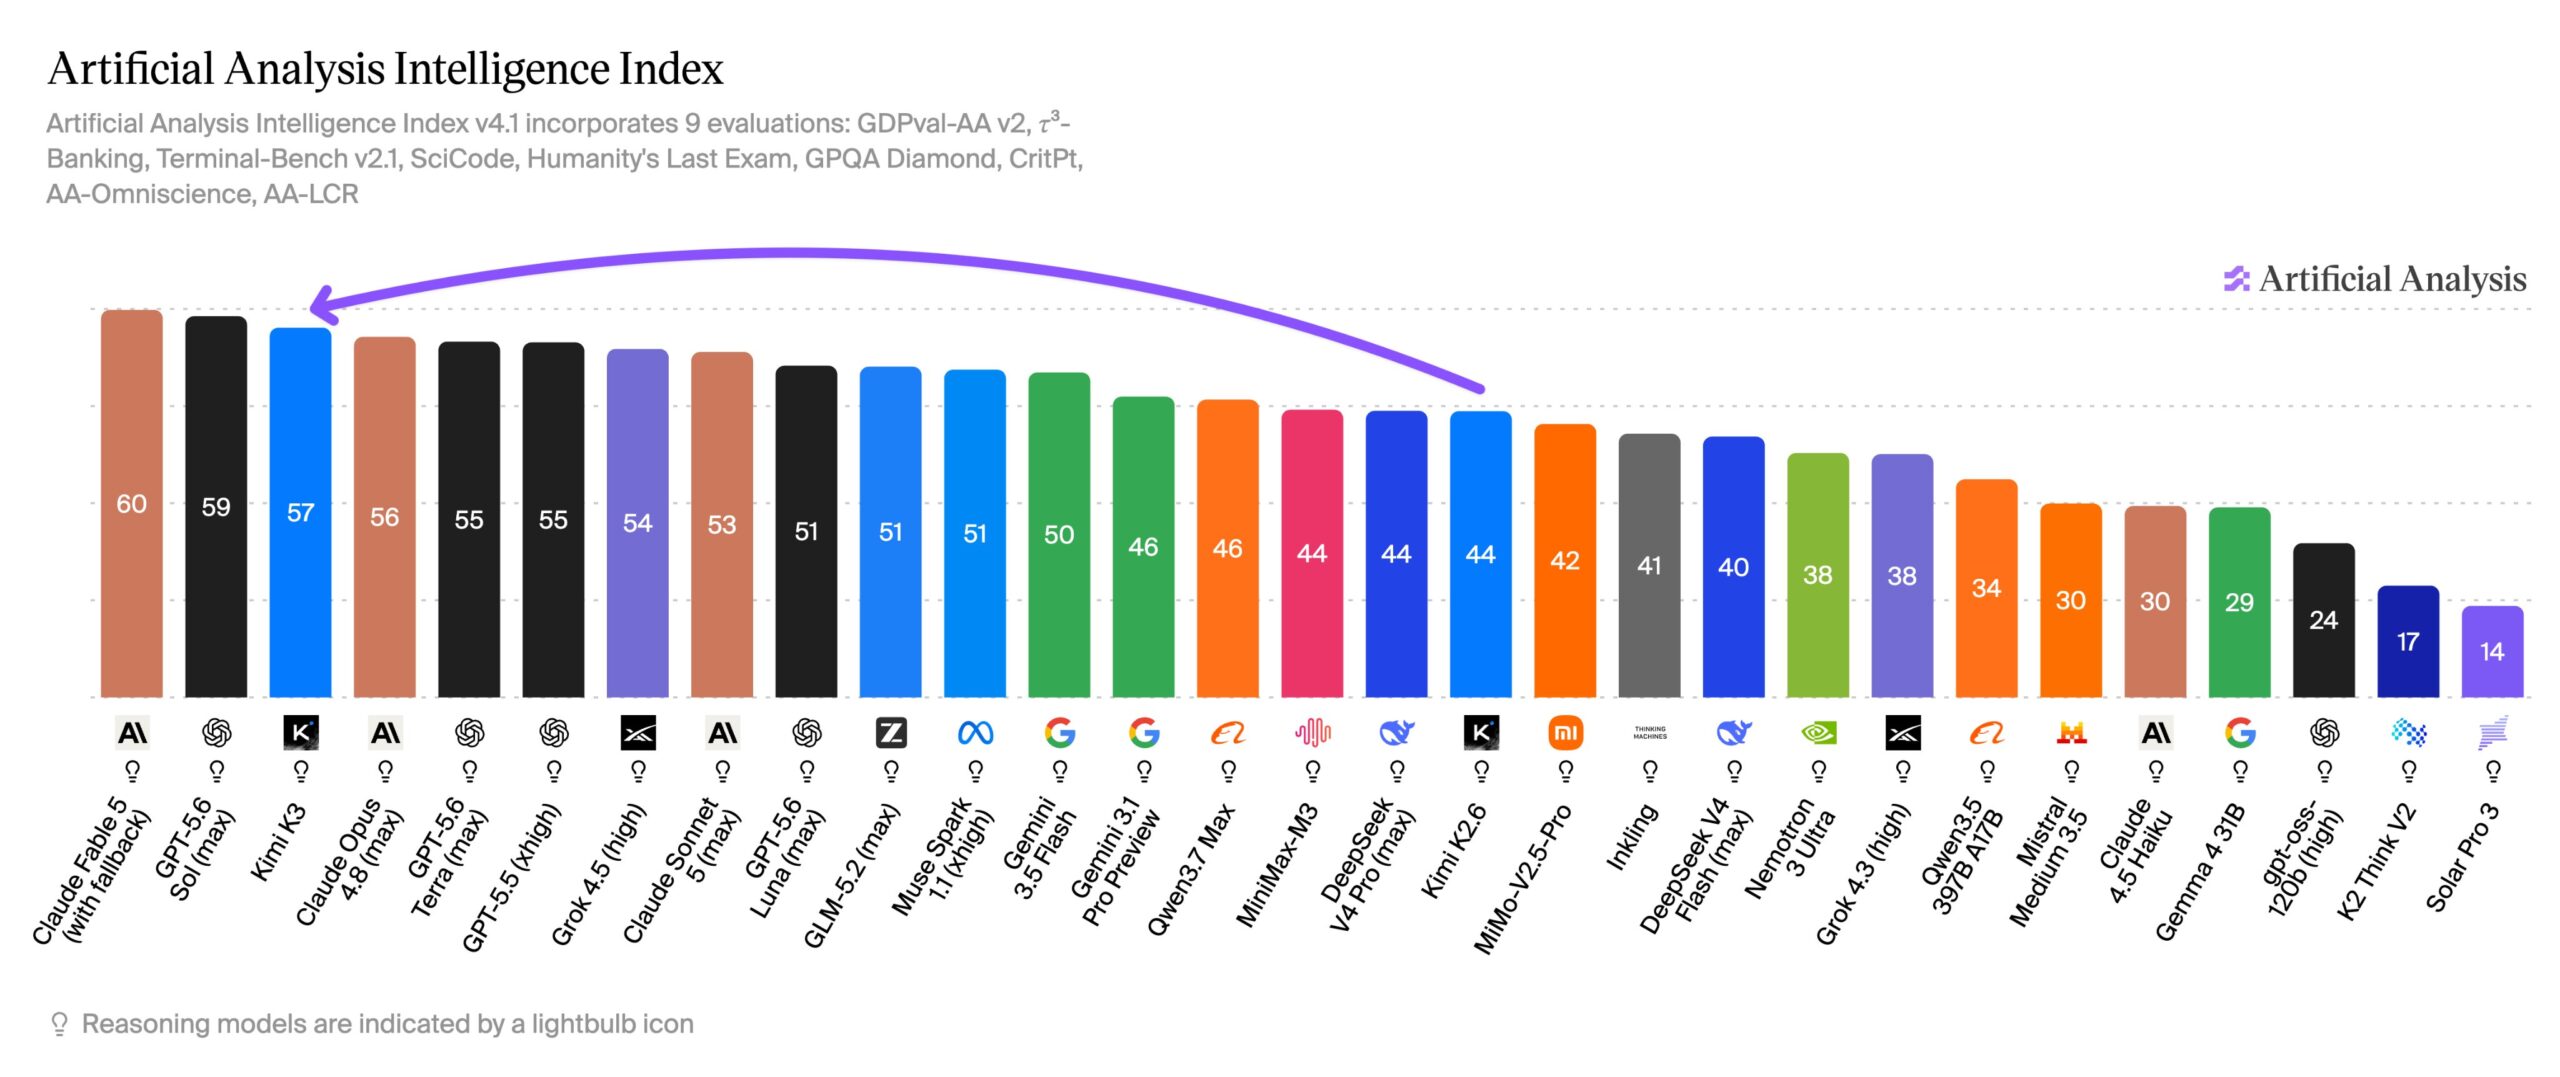
Moonshot AI launched Kimi K3 on July 16, 2026 — a 2.8-trillion-parameter Mixture-of-Experts model with a 1-million-token context window that now sits third on the Artificial Analysis Intelligence Index, ahead of Claude Opus 4.8 and behind only Claude Fable 5 and GPT-5.6 Sol. The full weights are promised by July 27, which would make K3 […]
-
OpenAI Launches GPT-5.6 Family: Sol, Terra, and Luna Reach General Availability
OpenAI launched the GPT-5.6 family for general availability on July 9, 2026 — Sol (flagship), Terra (balanced), and Luna (fast and affordable) — following a two-week limited preview that began June 26 under a government safety review. The models post state-of-the-art results in coding, cybersecurity, and long-horizon knowledge work while using markedly fewer tokens than […]
-
NVIDIA Star Elastic: One Checkpoint, Three Reasoning Models, Zero-Shot Slicing
On May 7, 2026, NVIDIA released Star Elastic — a single 30-billion-parameter reasoning checkpoint that contains two smaller production-ready models, 23B and 12B, embedded in its weights. Developers can extract the smaller variants with a one-shot slicing script, no fine-tuning required. The release introduces a “many-in-one” approach to LLM packaging that NVIDIA reports cuts post-training […]
-
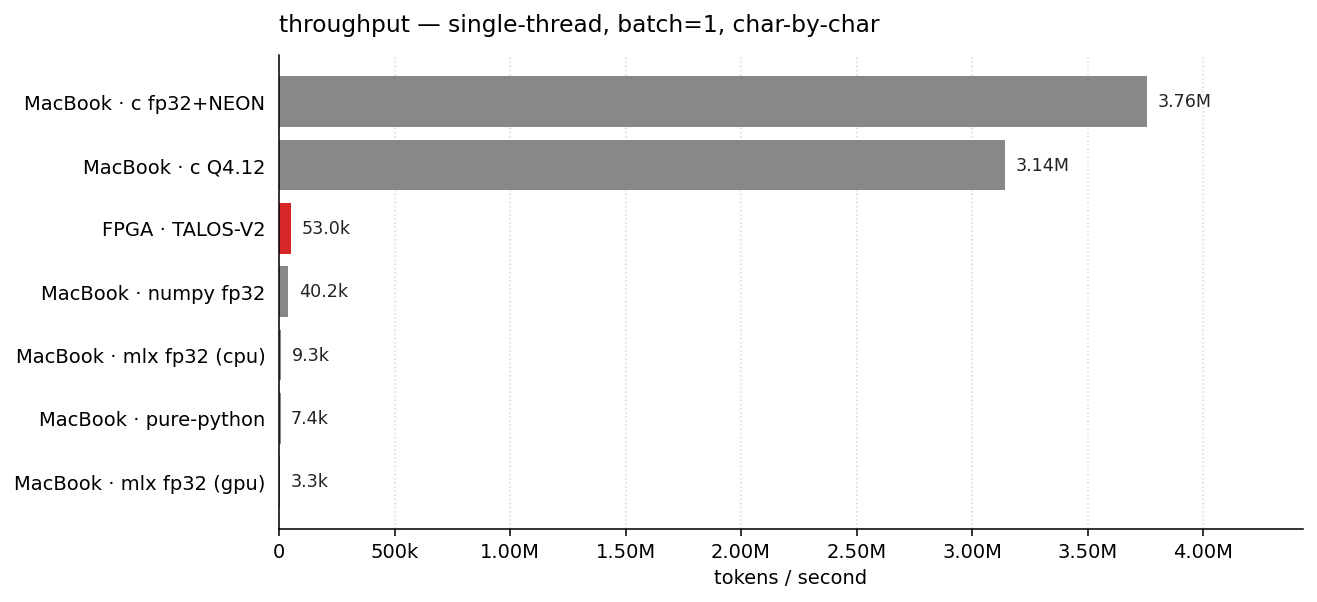
Karpathy’s microGPT on FPGA Loses to a Single MacBook Core by 71x
A custom FPGA implementation of Andrej Karpathy’s microGPT was clocked at 53,000 tokens per second — and then promptly out-run by a single M4 Max MacBook P-core doing roughly 71× the throughput in plain C. The benchmark, published on May 2, 2026 by Alex Cheema, has reignited a long-running debate in the local-AI community: when […]
-
Arcee AI Releases Trinity-Large-Thinking: A 400B Open Reasoning Agent
Arcee AI released Trinity-Large-Thinking on April 1, 2026 — an open-source frontier reasoning model built for complex, long-horizon AI agents. Weighing in at 398 billion total parameters (with ~13B active per token), it is one of the largest open-source models ever released by a U.S. startup, and it puts a credible challenge to proprietary alternatives […]
-
Qwen 3.5 Small Models: 9B Parameters That Beat 120B
Key points On March 2, 2026, Alibaba’s Qwen team completed the Qwen 3.5 family with four small dense models of 0.8B, 2B, 4B, and 9B parameters for on-device and edge deployment. All four models are open-weight under Apache 2.0 and available on Hugging Face and ModelScope. Qwen3.5-9B outperforms models 3-13 times its size across language, […]
-
Qwen 3.5 Medium Series: Frontier AI That Fits on Your GPU
Key points On February 24, 2026, Alibaba’s Qwen team expanded the Qwen 3.5 family with three Apache 2.0 open-weight models — Qwen3.5-27B, Qwen3.5-35B-A3B, and Qwen3.5-122B-A10B — available on Hugging Face. Qwen3.5-27B is a dense model with all 27 billion parameters active at inference, optimized for coding and instruction-following, and uses a 3:1 hybrid ratio of […]