Tag: coding
-
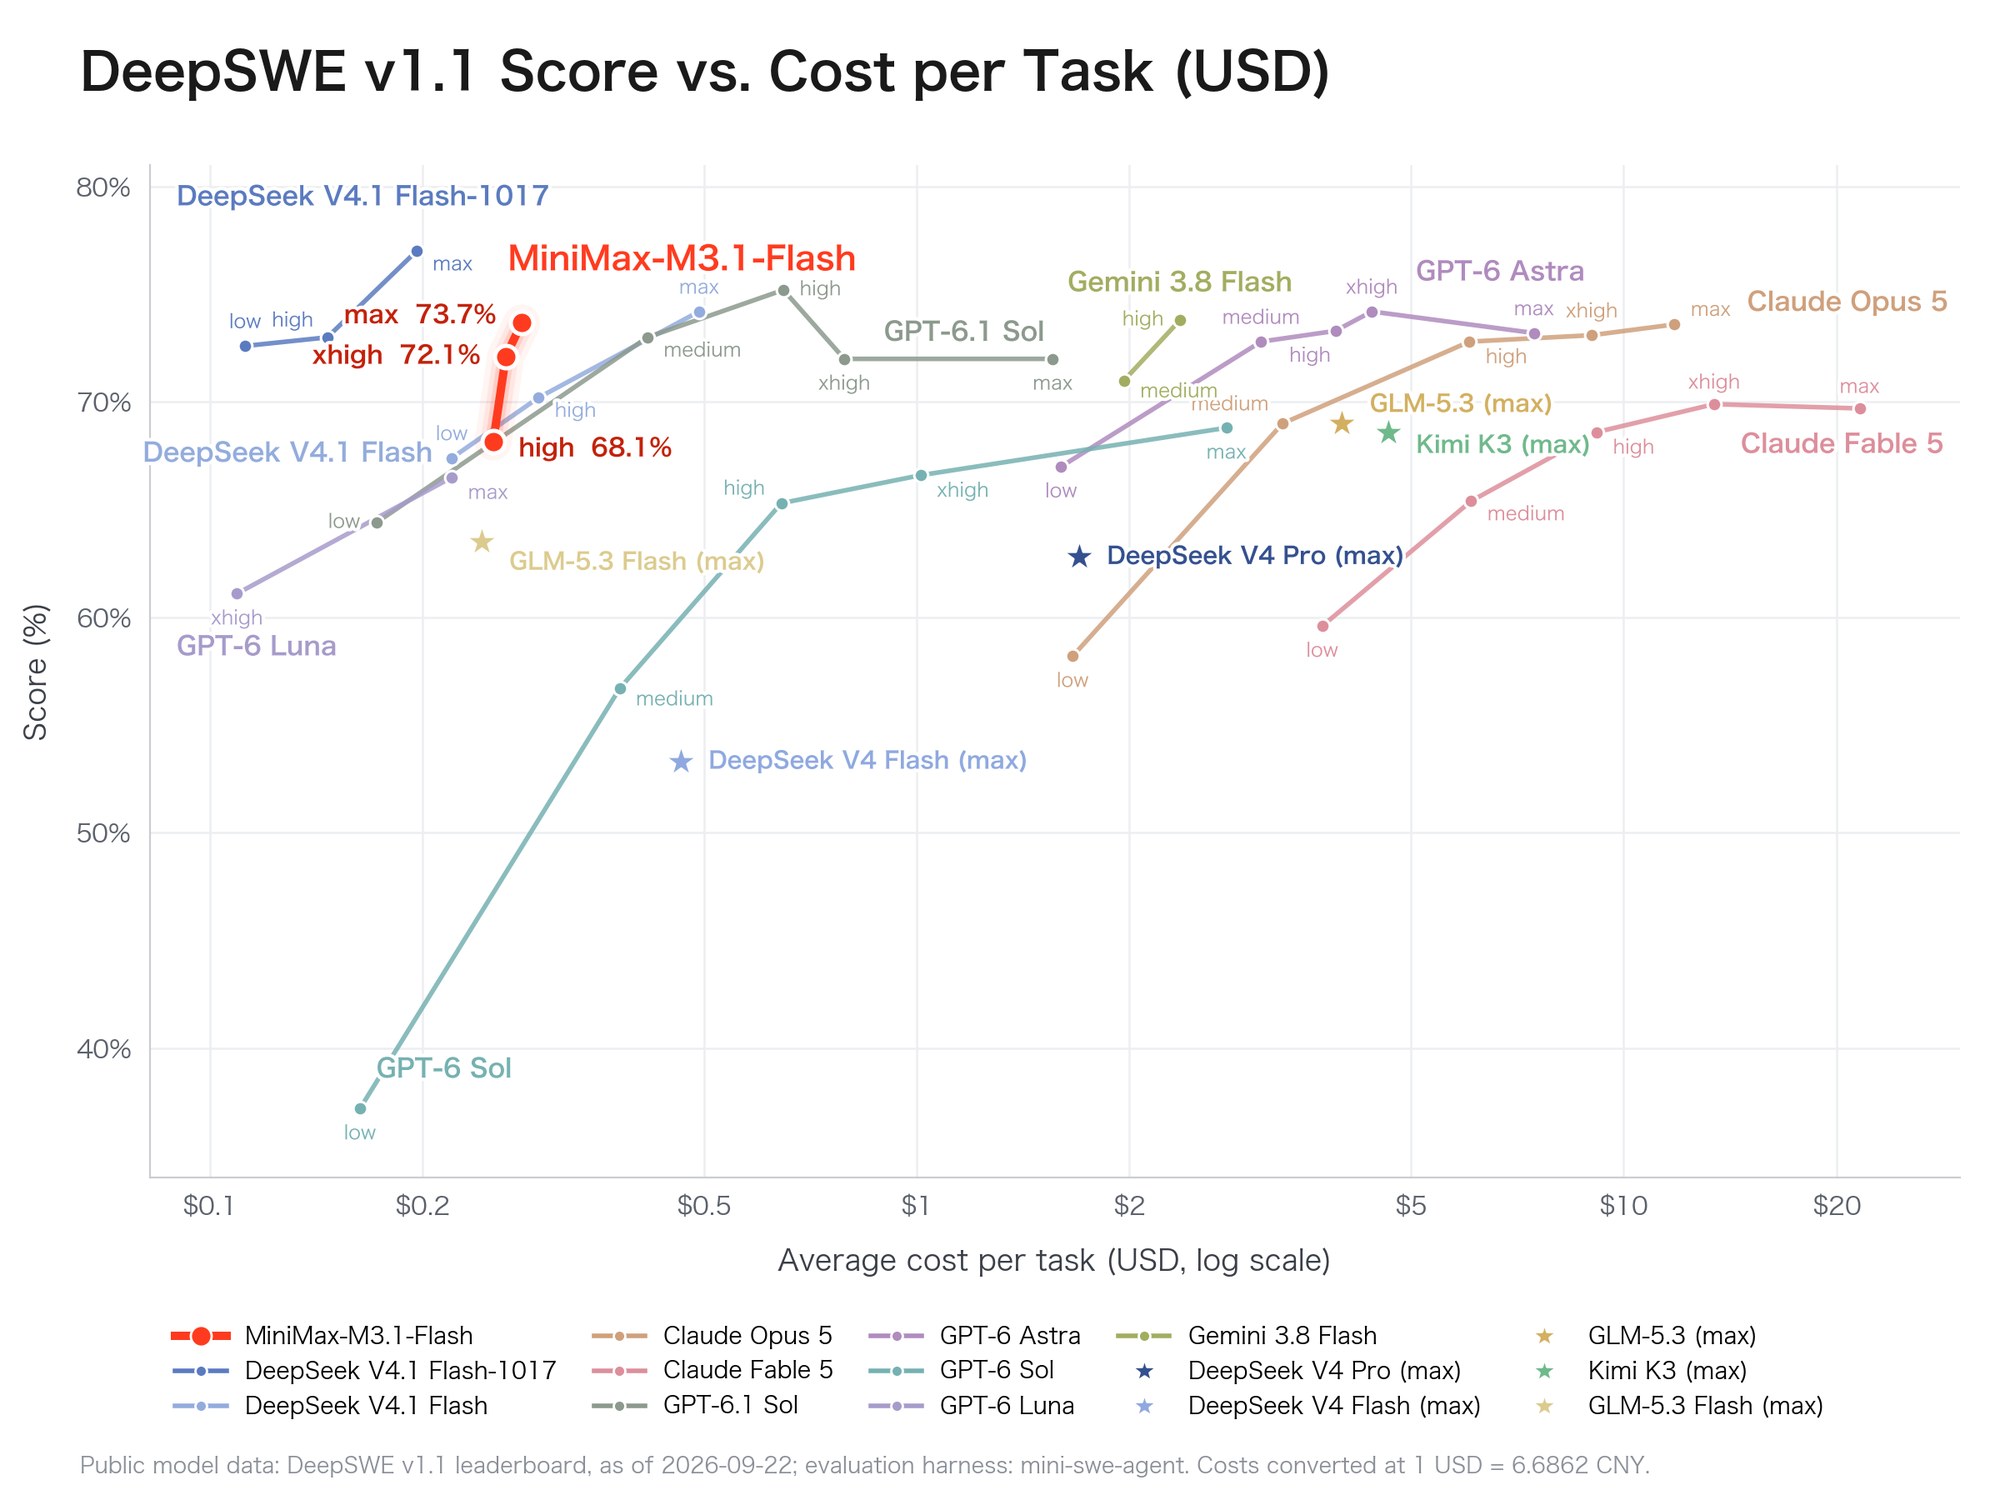
MiniMax Ships M3.1 Flash: API Now, Weights Due October 23
On October 19, 2026, MiniMax released M3.1 Flash, a faster and cheaper successor to June’s M3, and put it on its API the same day — but the weights are not out yet. MiniMax’s launch post says only that the weights “will be released later”. The Decoder and SiliconANGLE both report October 23. Until a […]
-
OpenAI Releases GPT-6 Sol and Luna at Half the Price
OpenAI released GPT‑6 Sol and GPT‑6 Luna on September 22, 2026, three weeks after it launched the flagship GPT‑6 Astra. Sol is the mid-tier model and Luna the low-cost one. Both cost half as much in the API as the GPT‑5.6 models they replace: Sol is $2 per million input tokens and $10 per million […]
-
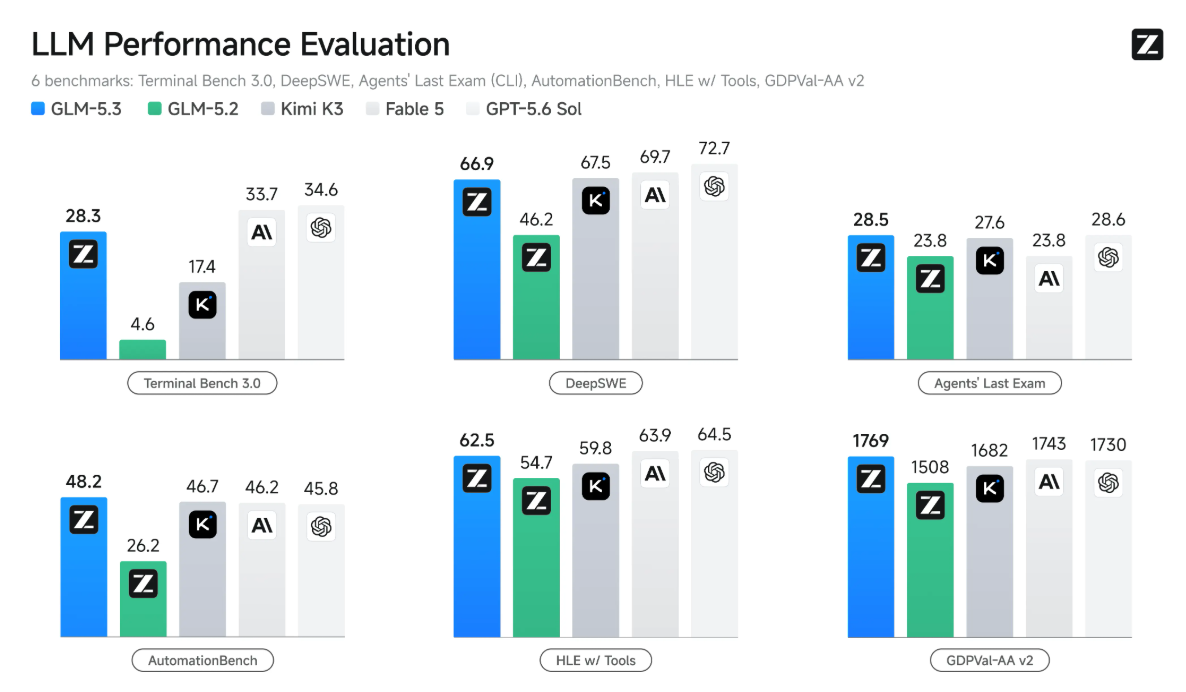
GLM-5.3: Z.ai Scales Post-Training, Holds the Weights Back
On August 14, 2026, Z.ai (formerly Zhipu AI) released GLM-5.3 — and, unusually, without a new base model. GLM-5.3 sits on the same 743-billion-parameter Mixture-of-Experts base as June’s GLM-5.2, and every reported gain comes from extended post-training alone. The model is live now through Z.ai’s API, its GLM Coding Plan, and the ZCode client, but […]
-
Poolside Releases Laguna S 2.1, a 118B Open-Weight Coding Model
On July 21, 2026, San Francisco-based Poolside released Laguna S 2.1 — a 118-billion-parameter Mixture-of-Experts model built for agentic coding that activates only 8 billion parameters per token. It tops the SWE-Bench Multilingual table at 78.5%, holds its own against models ten to twenty times its size on long-horizon coding benchmarks, and fits on a […]
-
GLM-5.2: Z.ai’s Open-Weights Coder Beats GPT-5.5 at 1/6 the Cost
On June 13, 2026, Z.ai (formerly Zhipu AI) released GLM-5.2 — a 753-billion-parameter open-weights Mixture-of-Experts model built for long-horizon, autonomous coding. The headline claim is striking: GLM-5.2 edges past OpenAI’s GPT-5.5 on several multi-step engineering benchmarks while costing roughly one-sixth as much to run. The full weights ship under an unrestricted MIT license on Hugging […]
-
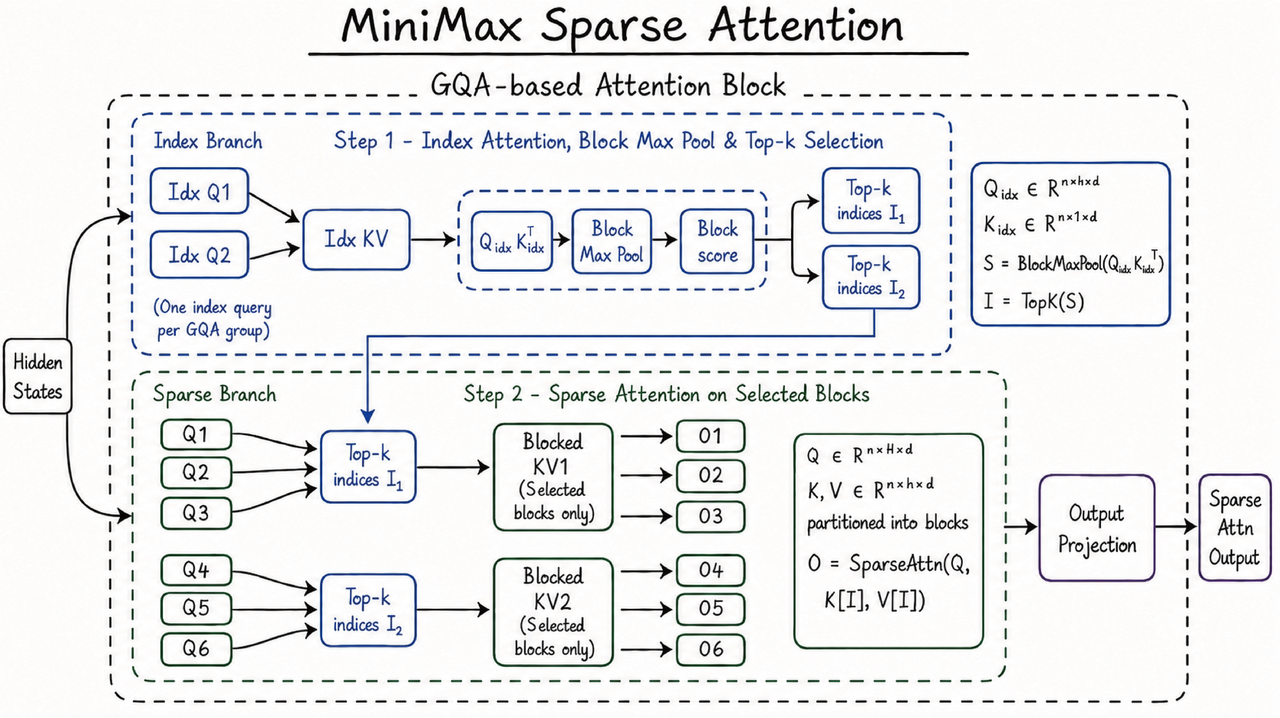
MiniMax M3: Frontier Coding, 1M Context, and Sparse Attention
MiniMax released M3 on June 1, 2026, claiming the first open-weight model to combine frontier coding, a 1-million-token context window, and native multimodality in a single architecture. The headline is not just the benchmark sheet — it is the engine underneath: a new sparse-attention mechanism (MSA) that the company says cuts per-token compute at 1M […]
-
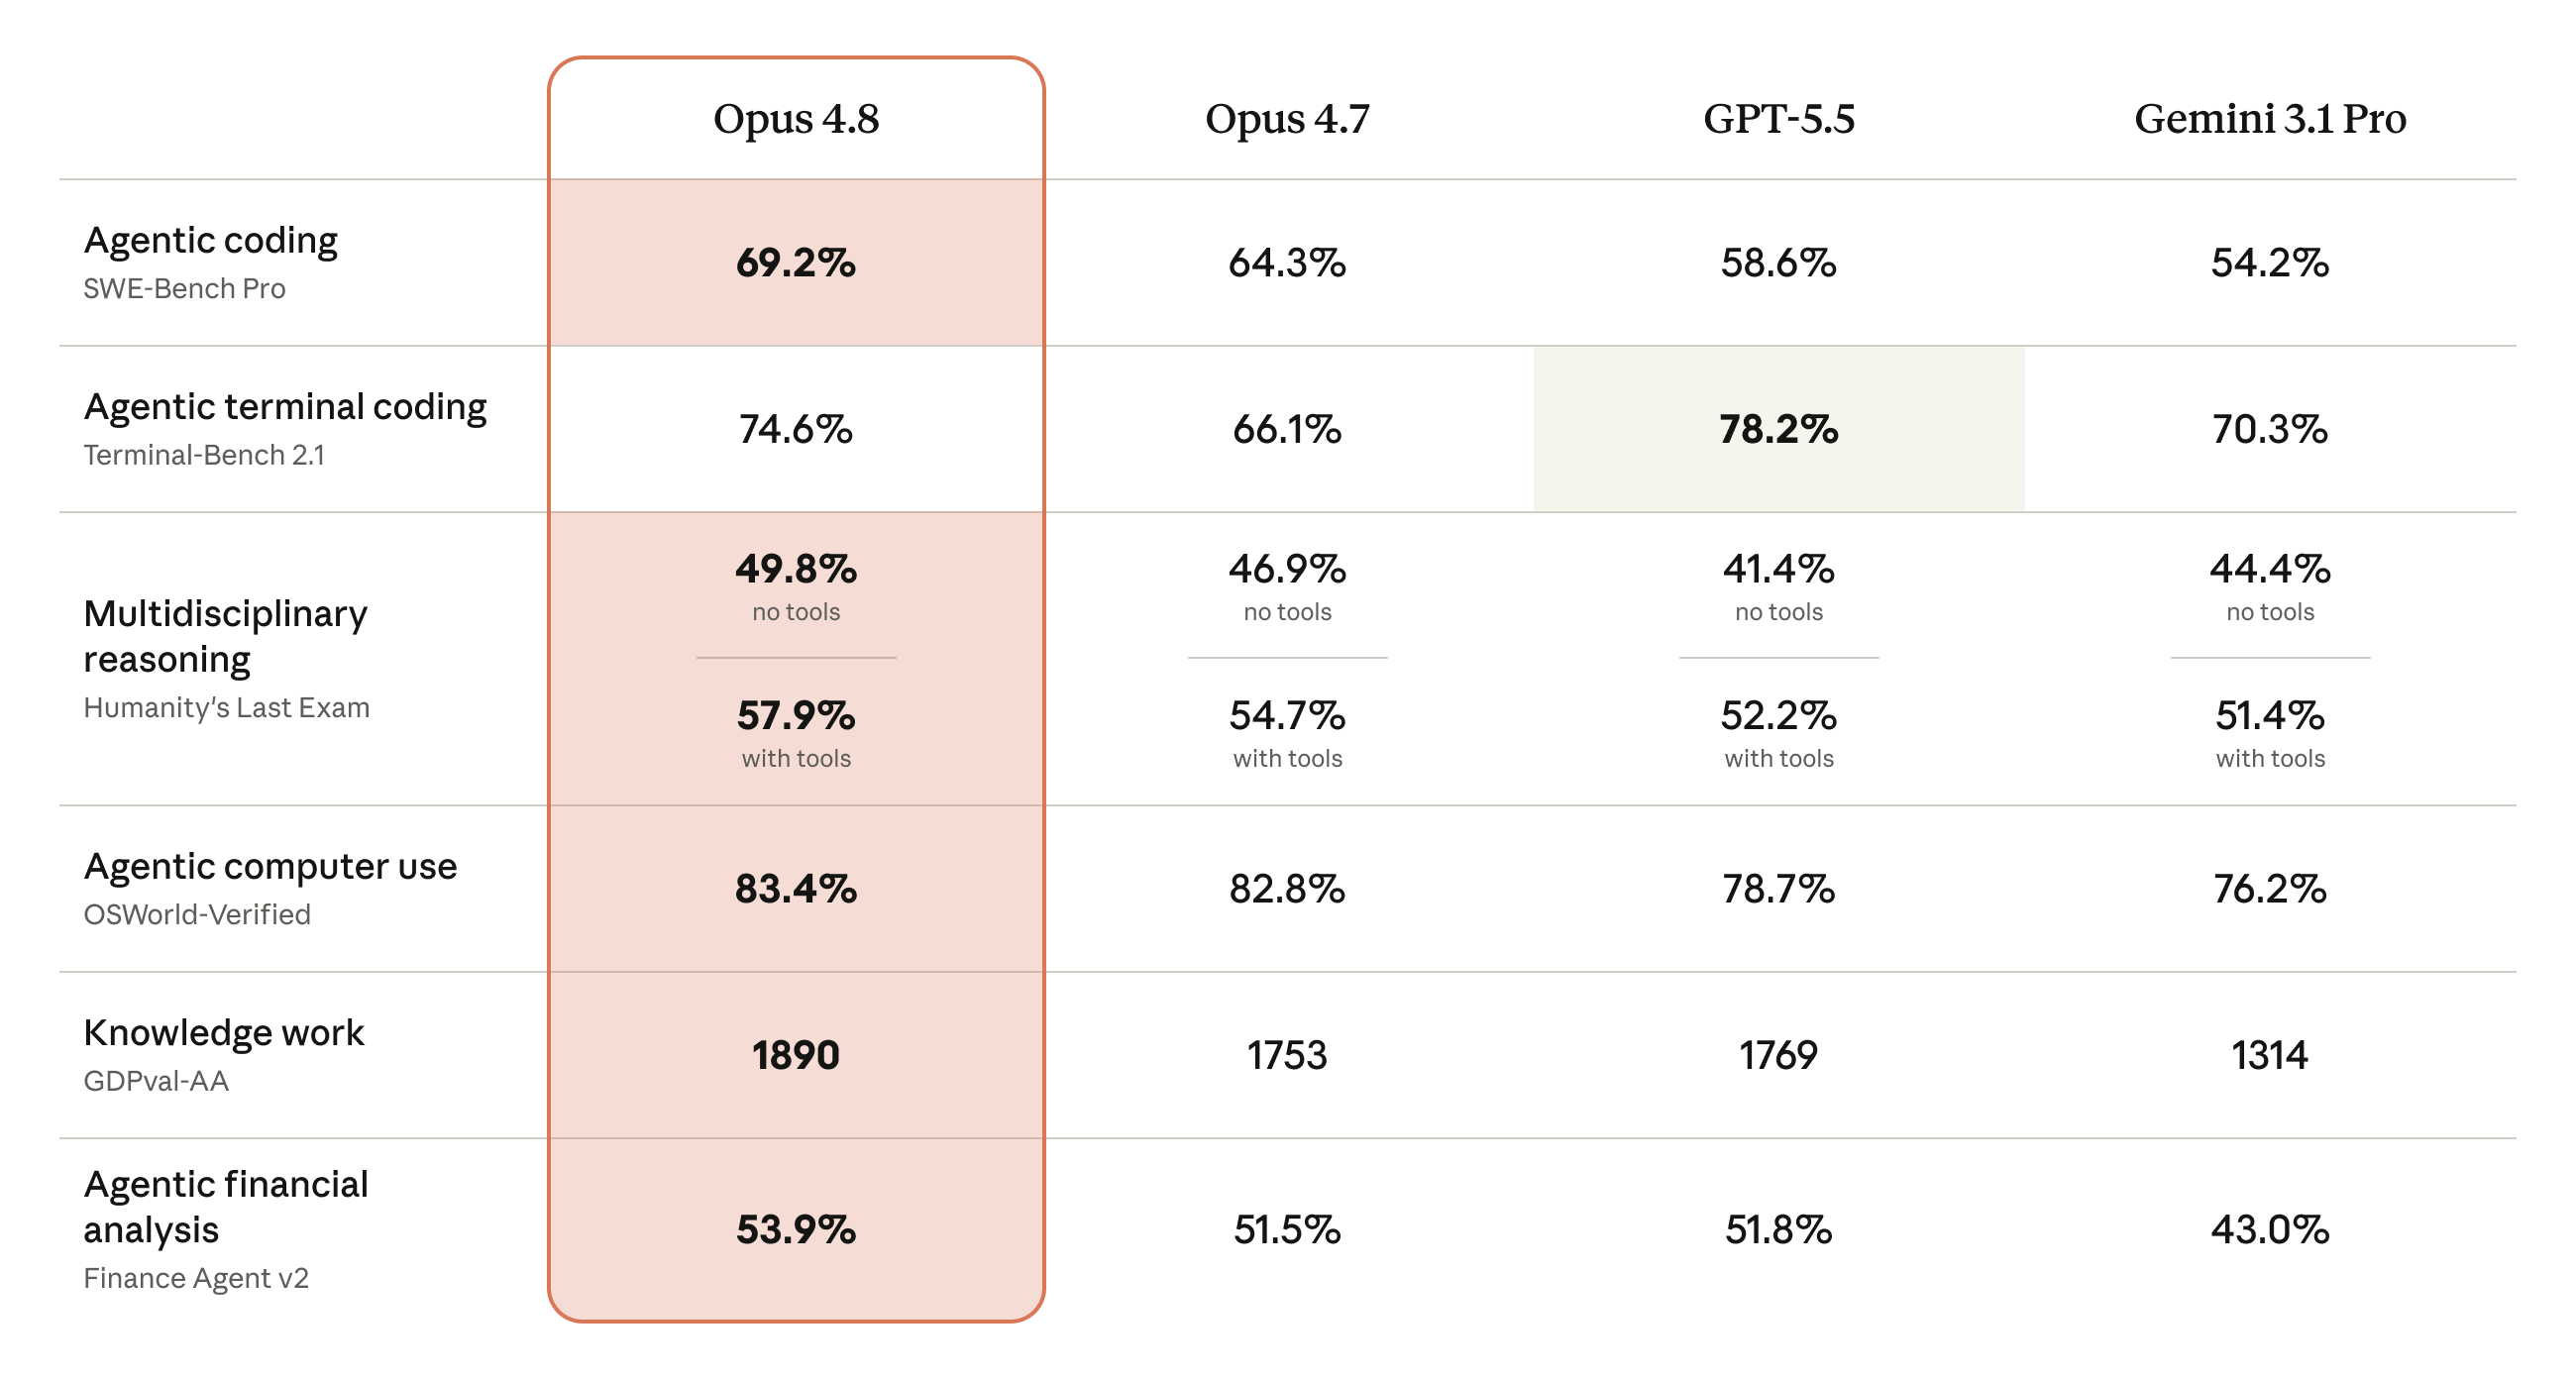
Anthropic Releases Claude Opus 4.8 for Longer Agentic Coding
Anthropic released Claude Opus 4.8 on May 28, 2026, upgrading its flagship generally available model for long-horizon coding agents, professional knowledge work, and enterprise workflows. The release is not a radical architecture reveal; its significance is more practical: better benchmark results, a cheaper fast mode, stronger self-checking behavior, and new Claude Code workflows that let […]
-
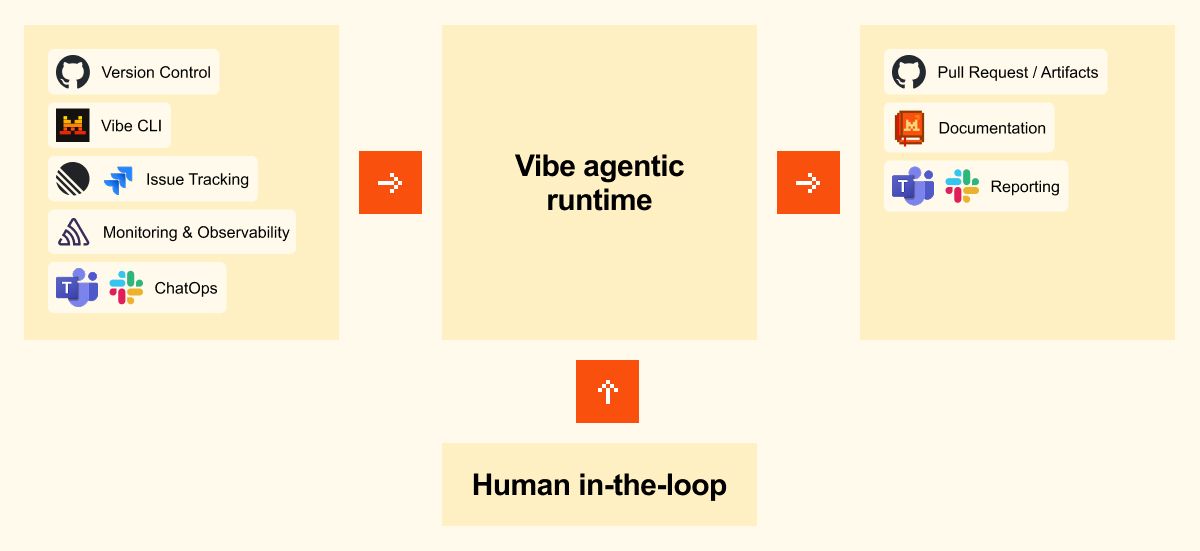
Mistral Medium 3.5 Launches with Vibe Remote Coding Agents
On April 29, 2026, Mistral AI launched Mistral Medium 3.5 — a 128-billion-parameter dense multimodal model with a 256k context window — alongside Vibe remote agents, a cloud-based system that runs coding sessions asynchronously and in parallel. The model unifies instruction following, reasoning, and coding into a single set of weights, replaces Devstral 2 in […]
-
OpenAI Releases GPT-5.5: Agentic Coding Ceiling Tops 14 Benchmarks
OpenAI released GPT-5.5 on April 23, 2026, just six weeks after GPT-5.4, positioning the model as a major step toward agentic computing. The company claims state-of-the-art results across 14 benchmarks, including 82.7% on Terminal-Bench 2.0 and 58.6% on SWE-Bench Pro, with the model now rolling out to Plus, Pro, Business, and Enterprise tiers of ChatGPT […]
-
Qwen3.6-27B: A Dense 27B Model That Beats a 397B MoE on Coding
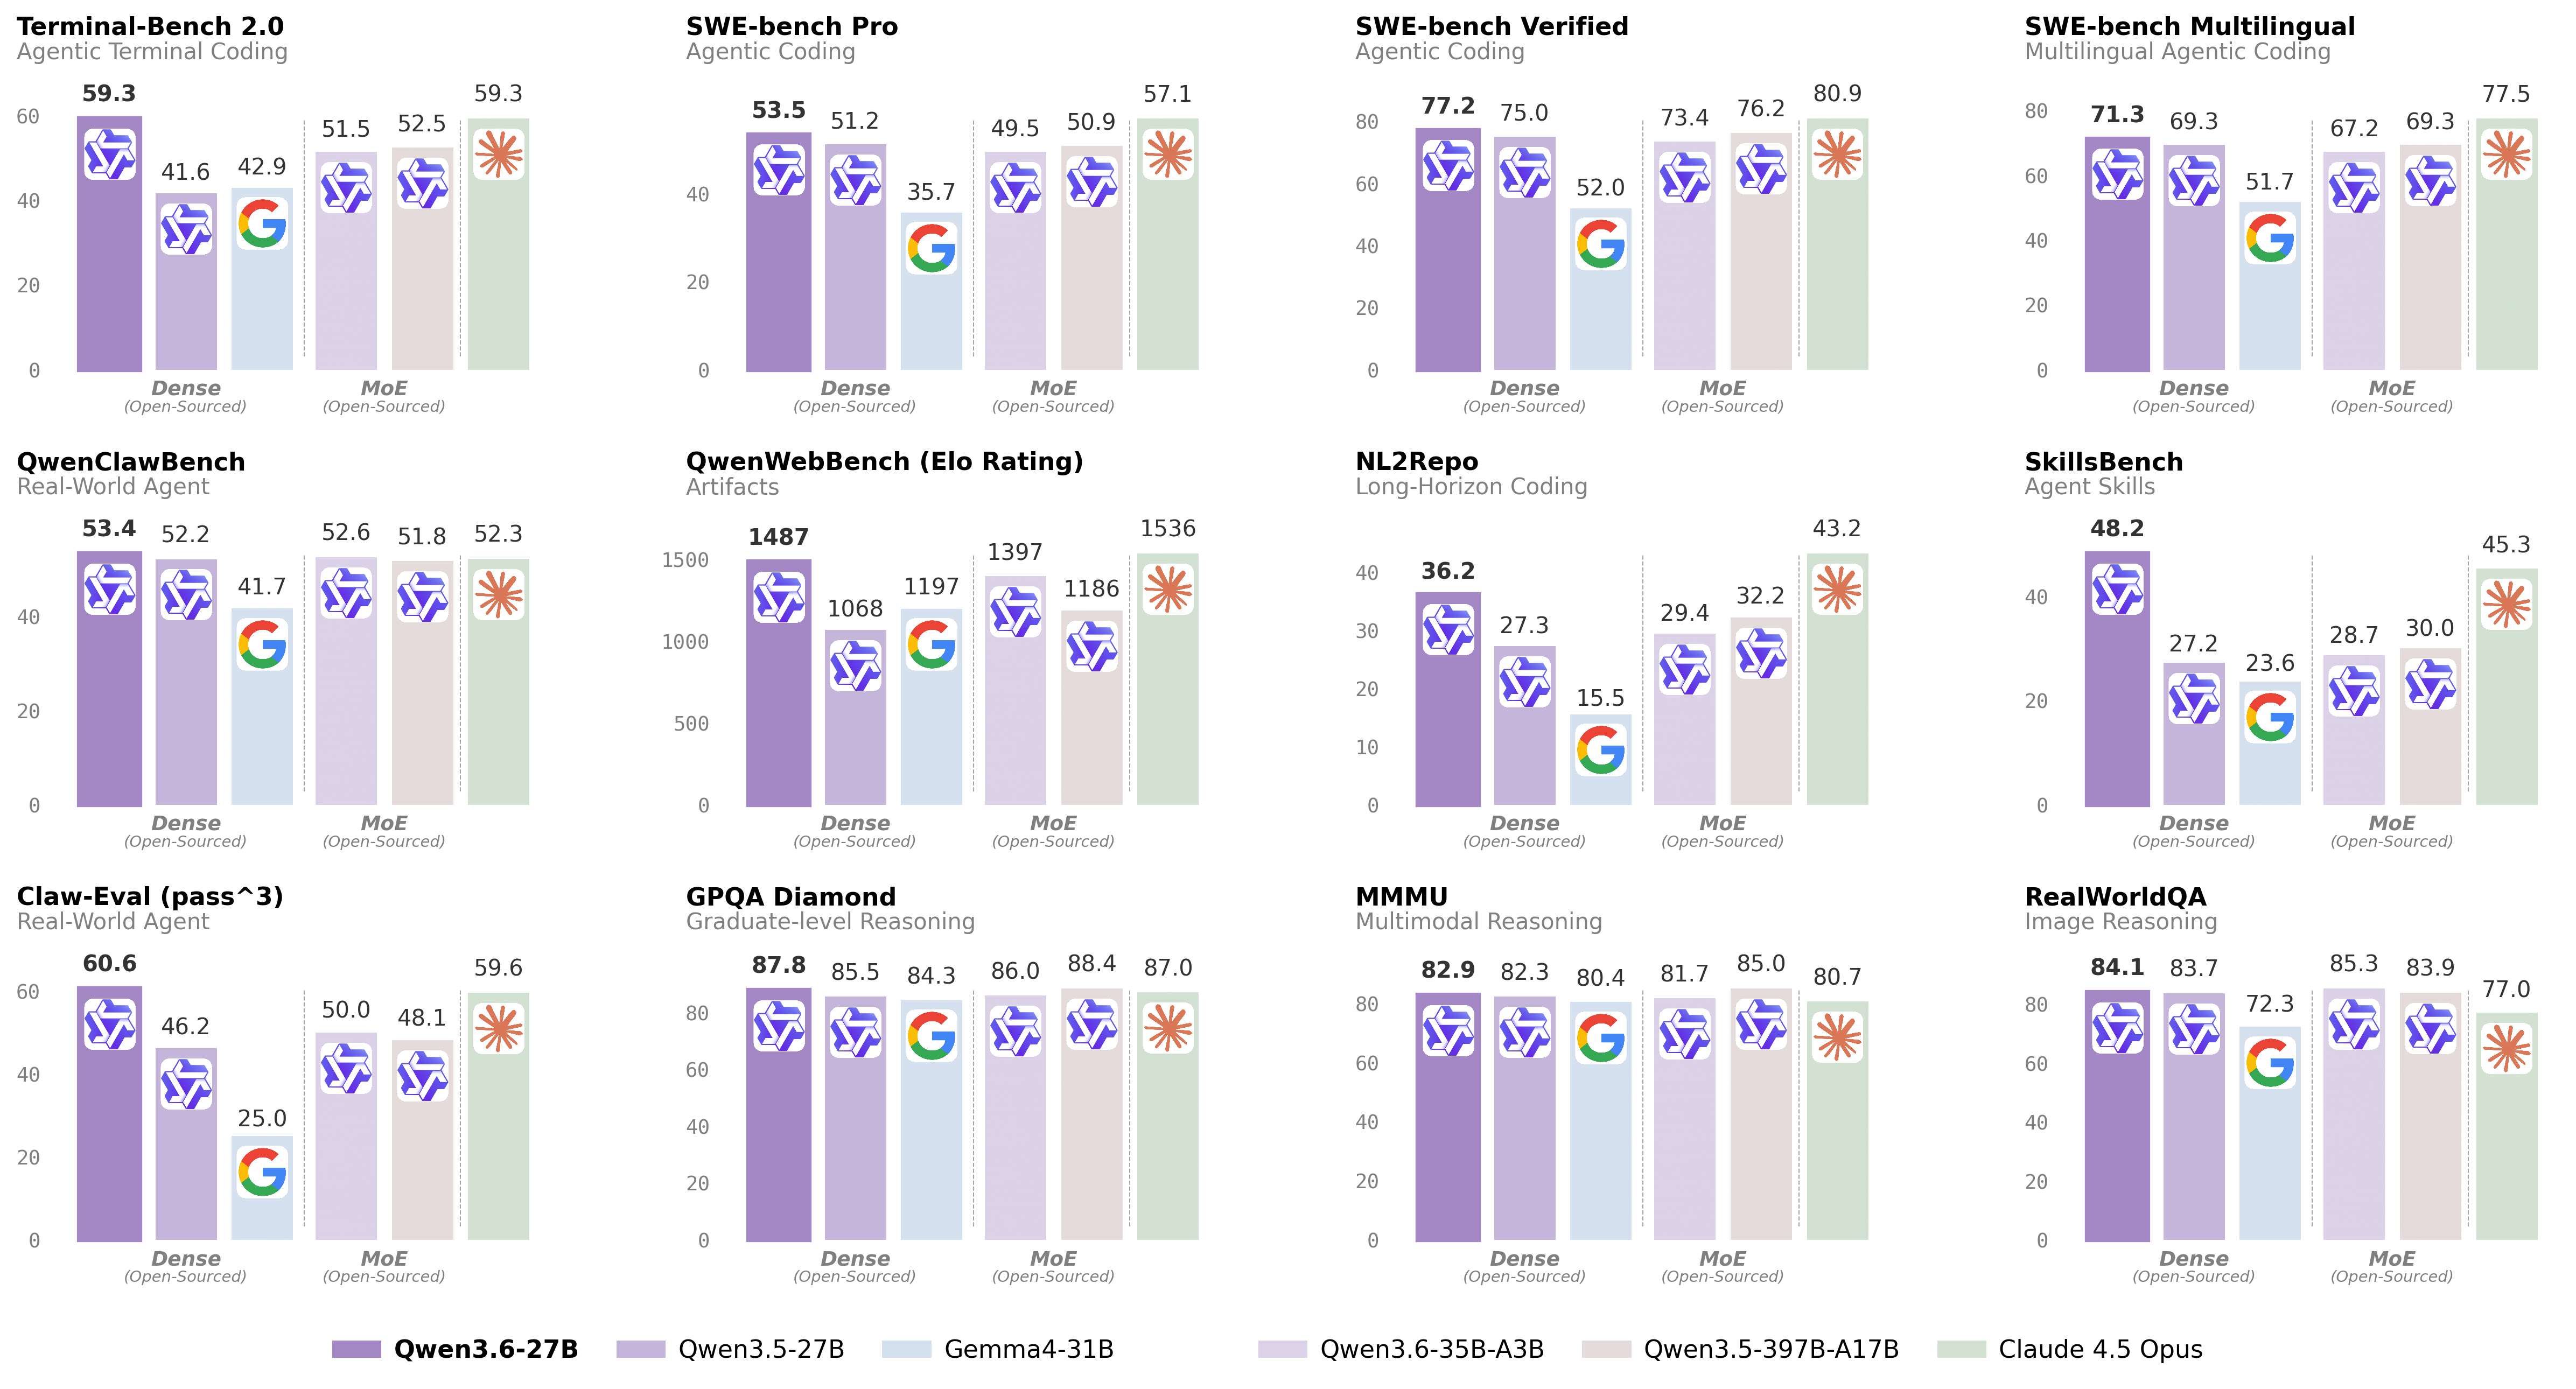
On April 22, 2026, Alibaba’s Qwen team released Qwen3.6-27B — the first dense open-weight model in the Qwen3.6 generation. Released under Apache 2.0 on Hugging Face, the 27-billion-parameter multimodal model posts flagship-level agentic coding scores that beat the team’s previous-generation 397B Mixture-of-Experts flagship across multiple benchmarks, while fitting into a 16.8 GB Q4_K_M quantization that runs […]