Tag: document understanding
-
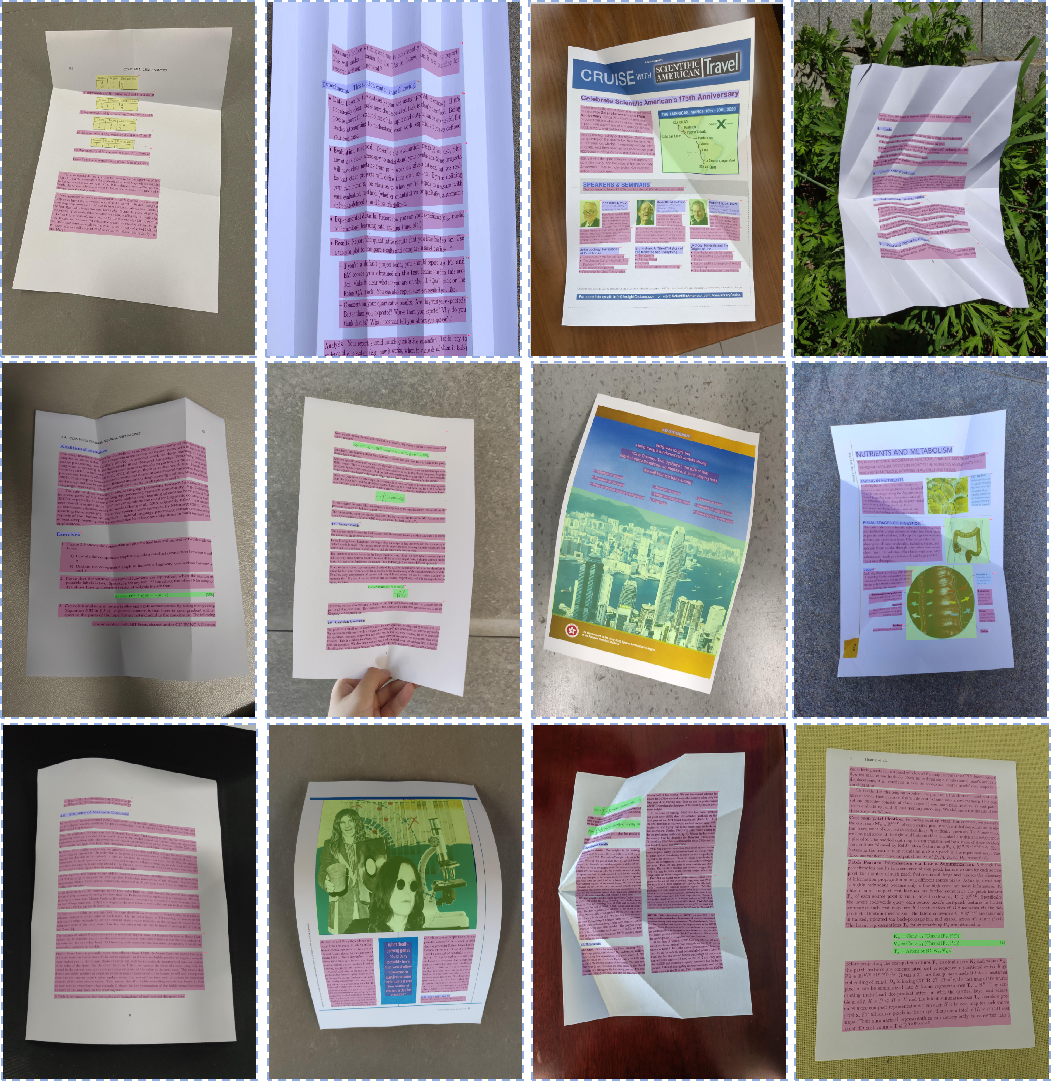
TeleOCR Parses Crumpled, Photographed Pages Without Dewarping
A research team at China Telecom’s AI subsidiary (TeleAI) has released TeleOCR, a 1.2-billion-parameter vision-language model that parses both clean digital documents and photographed ones — folded, curled, or crumpled — with no separate dewarping step. The weights first went up on Hugging Face on August 17, 2026 under the name NaviDC-OCR. The team renamed […]
-
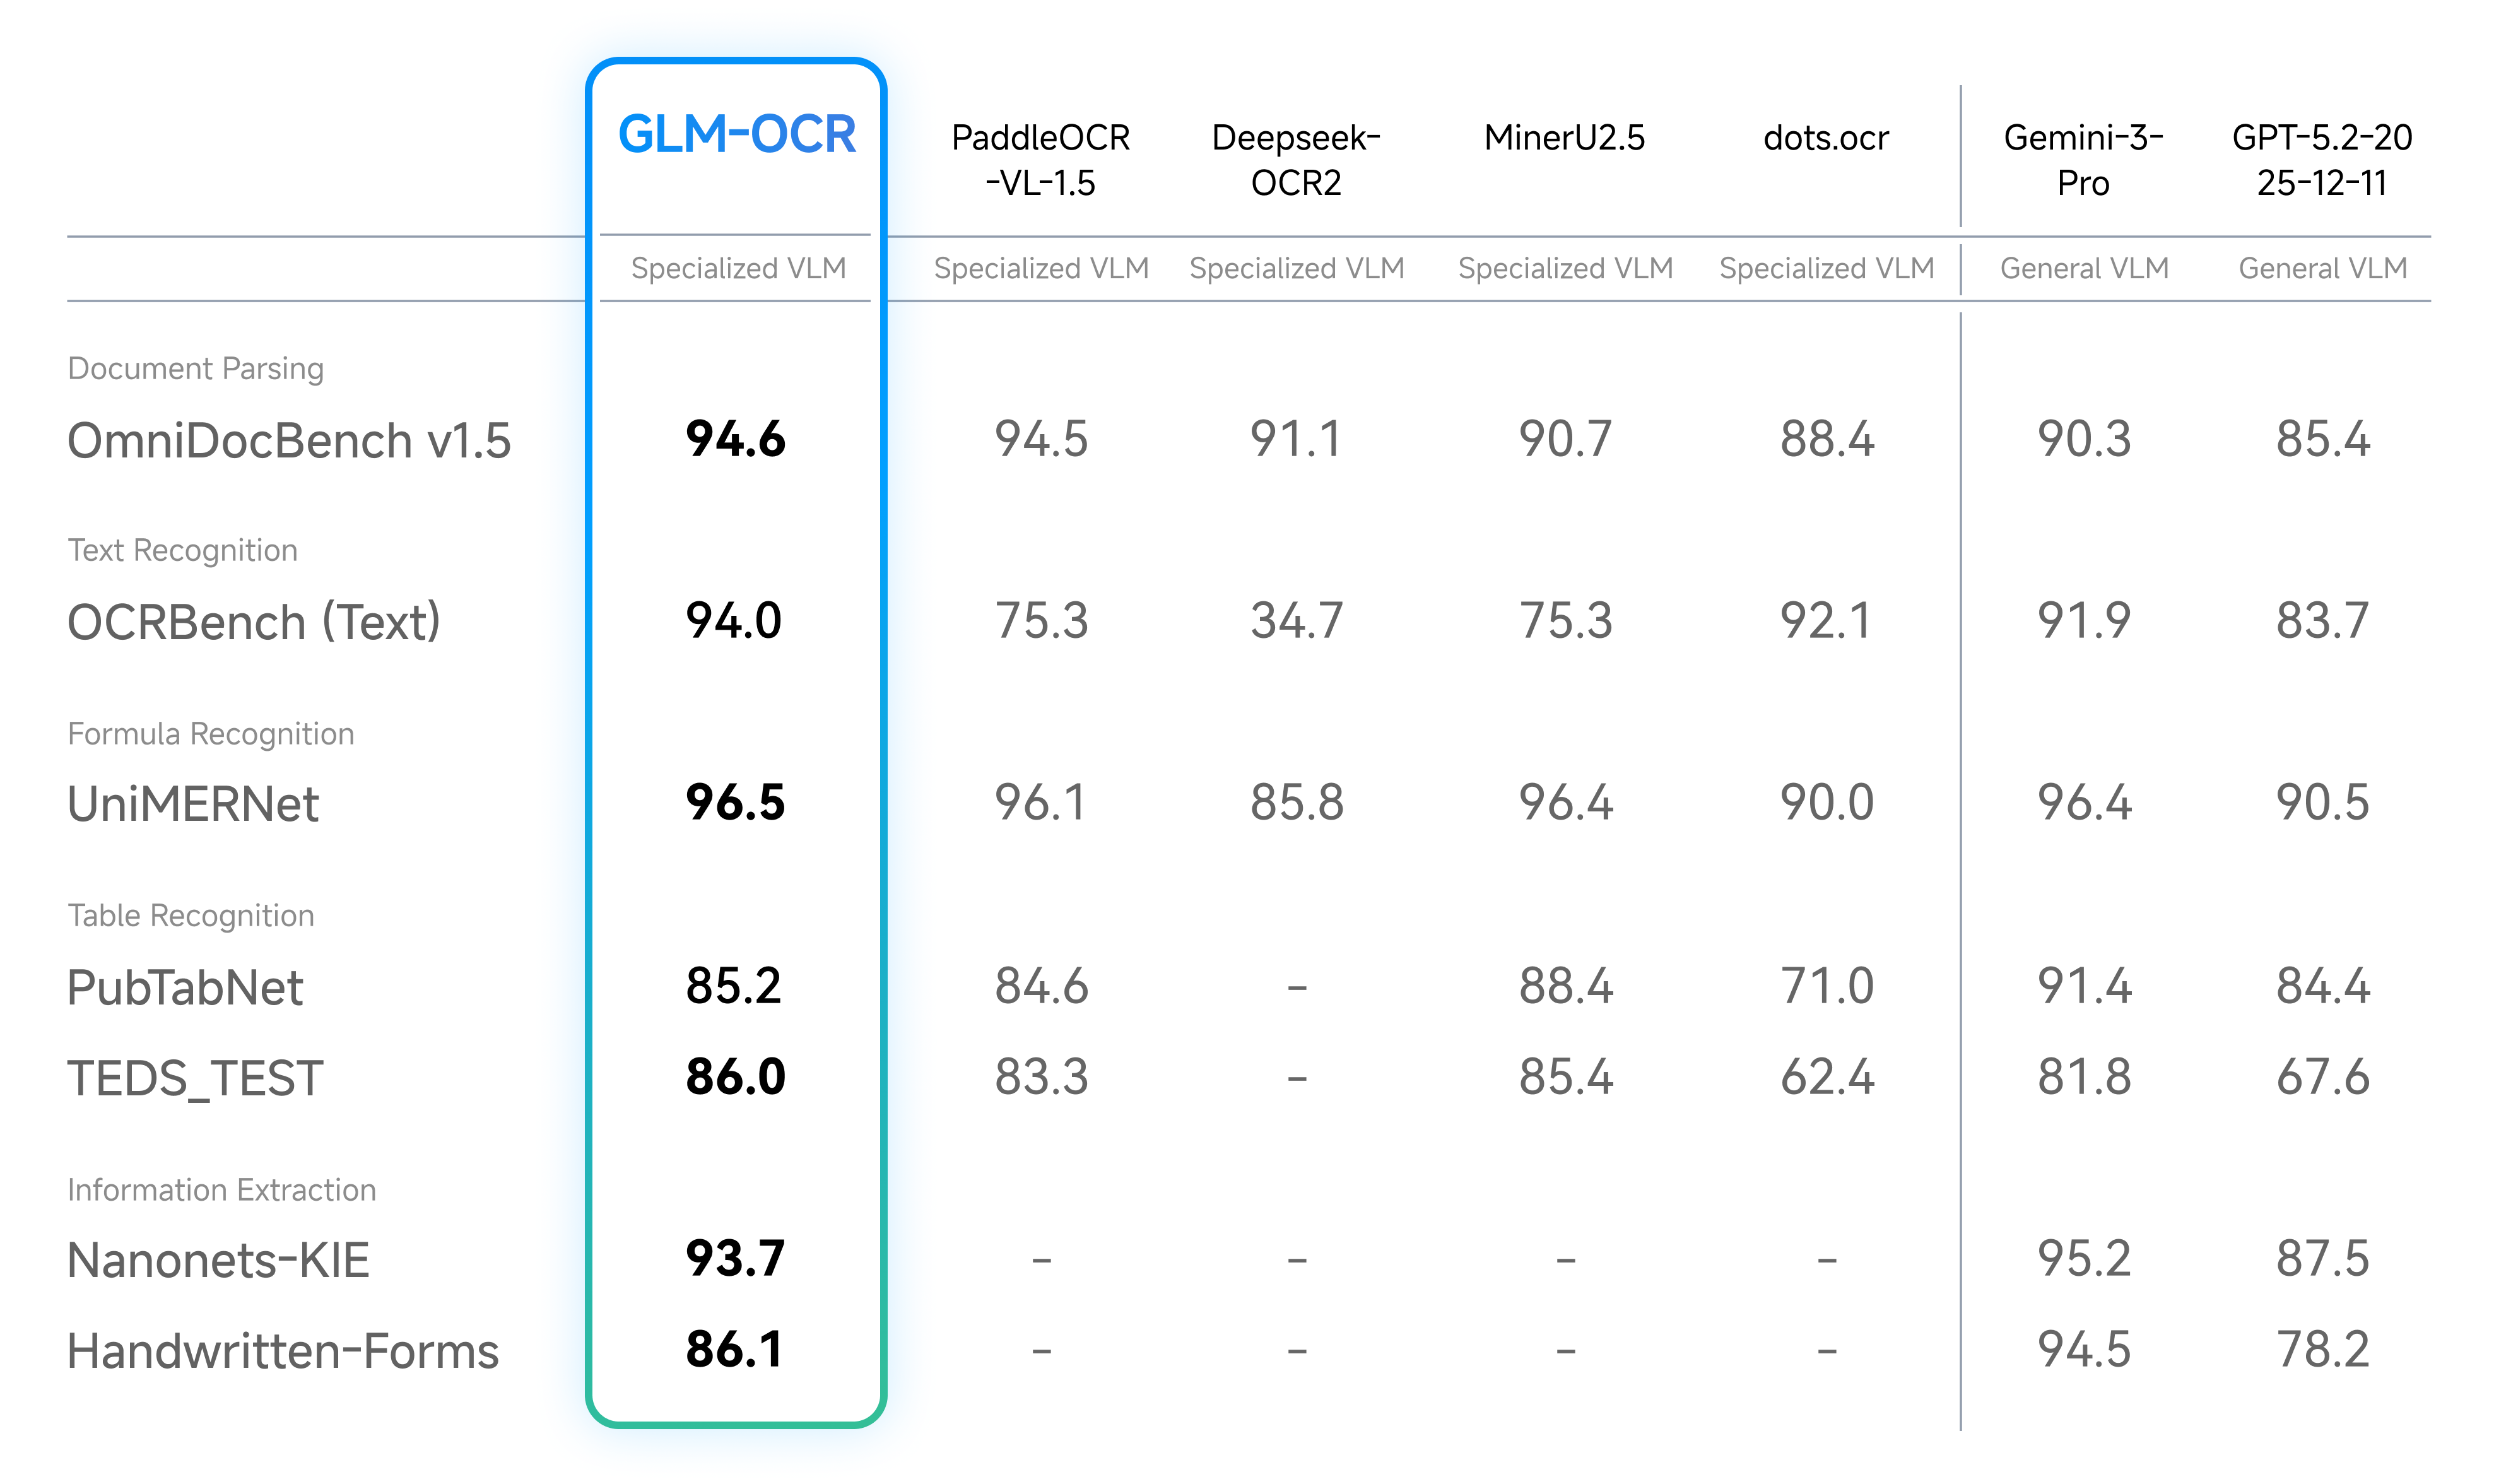
GLM-OCR: Z.ai’s 0.9B Model Takes the Top Spot on Document Understanding Benchmarks
Key points Z.ai has open-sourced GLM-OCR, a compact multimodal model with 0.9 billion parameters that ranks first on OmniDocBench V1.5 with a score of 94.62. GLM-OCR is a multimodal optical character recognition model developed by Z.ai, the commercial arm of ZhipuAI, and designed specifically for complex document understanding. It supports three core recognition modes: general […]