Tag: Hao AI Lab
-
JetSpec: Causal Parallel Tree Drafting Hits 9.64x Faster LLM Inference
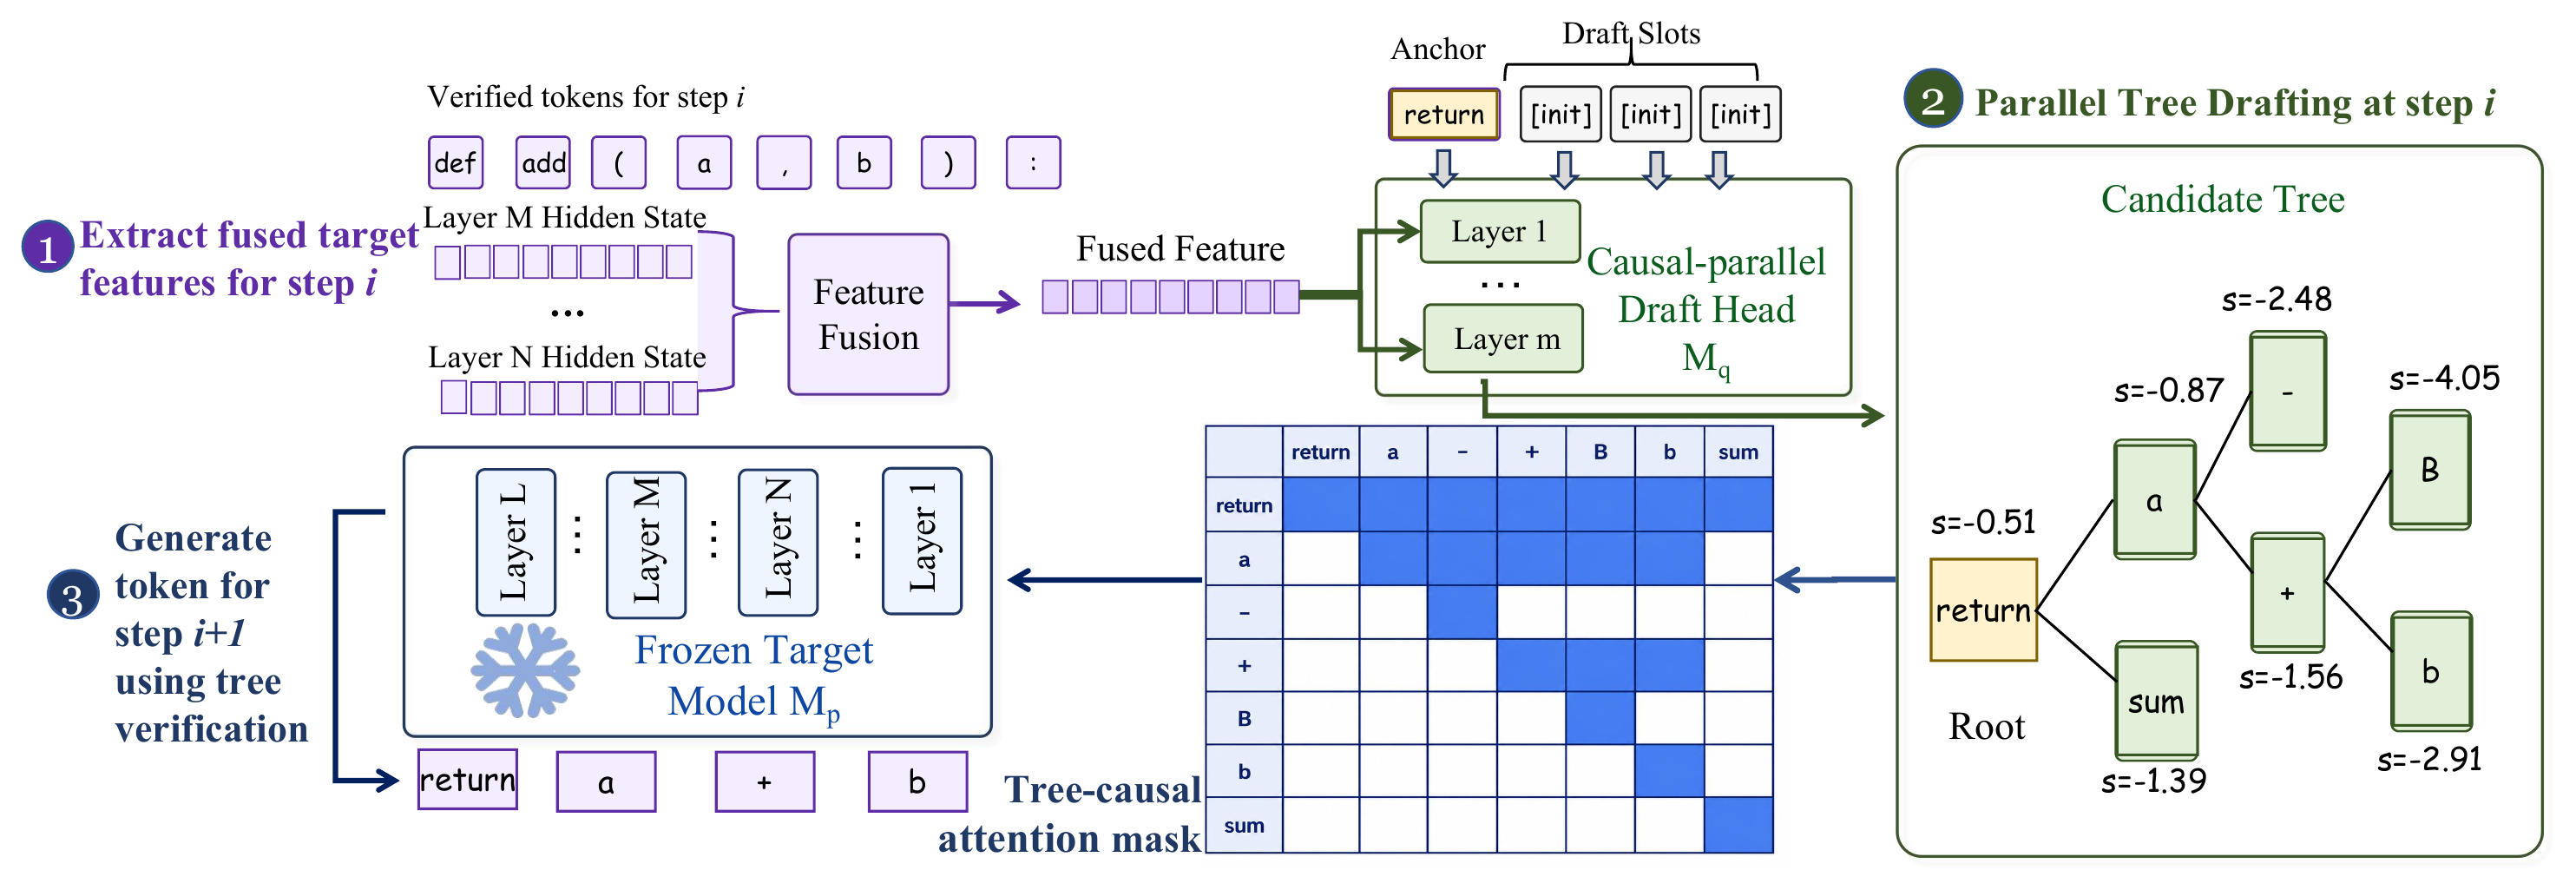
On June 26, 2026, researchers at UC San Diego’s Hao AI Lab released JetSpec — a speculative decoding method that accelerates large language model inference by up to 9.64× while leaving the model’s outputs unchanged. JetSpec trains a small “causal parallel draft head” on top of a frozen target model, generating a scored tree of […]