Tag: kernels
-
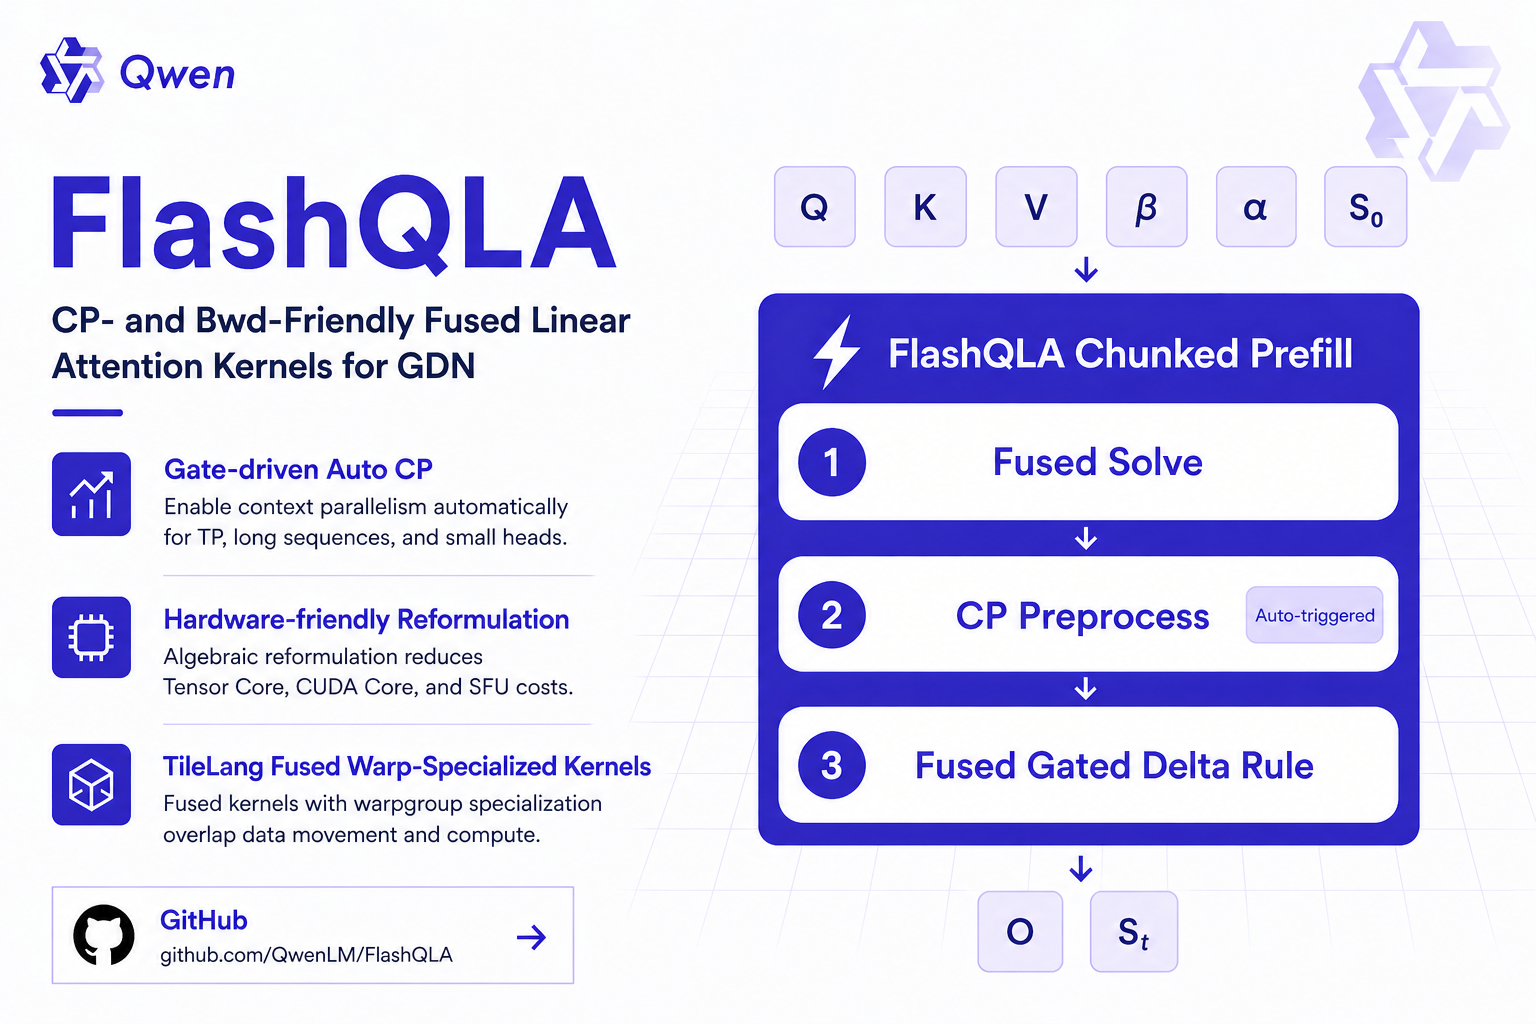
Qwen Releases FlashQLA: 2-3x Faster Linear Attention Kernels on Hopper
Qwen has open-sourced FlashQLA, a high-performance linear attention kernel library built on TileLang that targets the GDN (Gated Delta Network) Chunked Prefill workload. Released in late April 2026 under the MIT License, FlashQLA reports a 2–3× forward-pass speedup and roughly 2× backward-pass speedup over the FLA Triton kernels, and roughly 2× over FlashInfer 0.6.9 on […]