Tag: Level: Intermediate
-
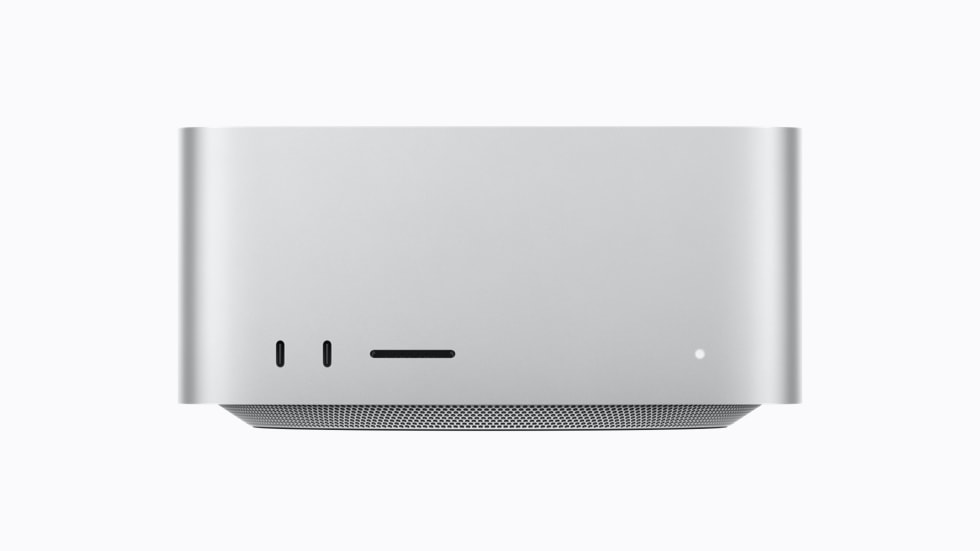
Apple’s M5 Ultra Mac Studio: 512GB of Unified Memory for Local AI
On August 25, 2026, Apple announced a new Mac Studio built around the M5 Max and the quad-die M5 Ultra — a desktop configurable with up to 512GB of unified memory and 1.2TB/s of memory bandwidth. Apple is pitching it explicitly at people running large language models locally: the company says the M5 Ultra configuration […]
-
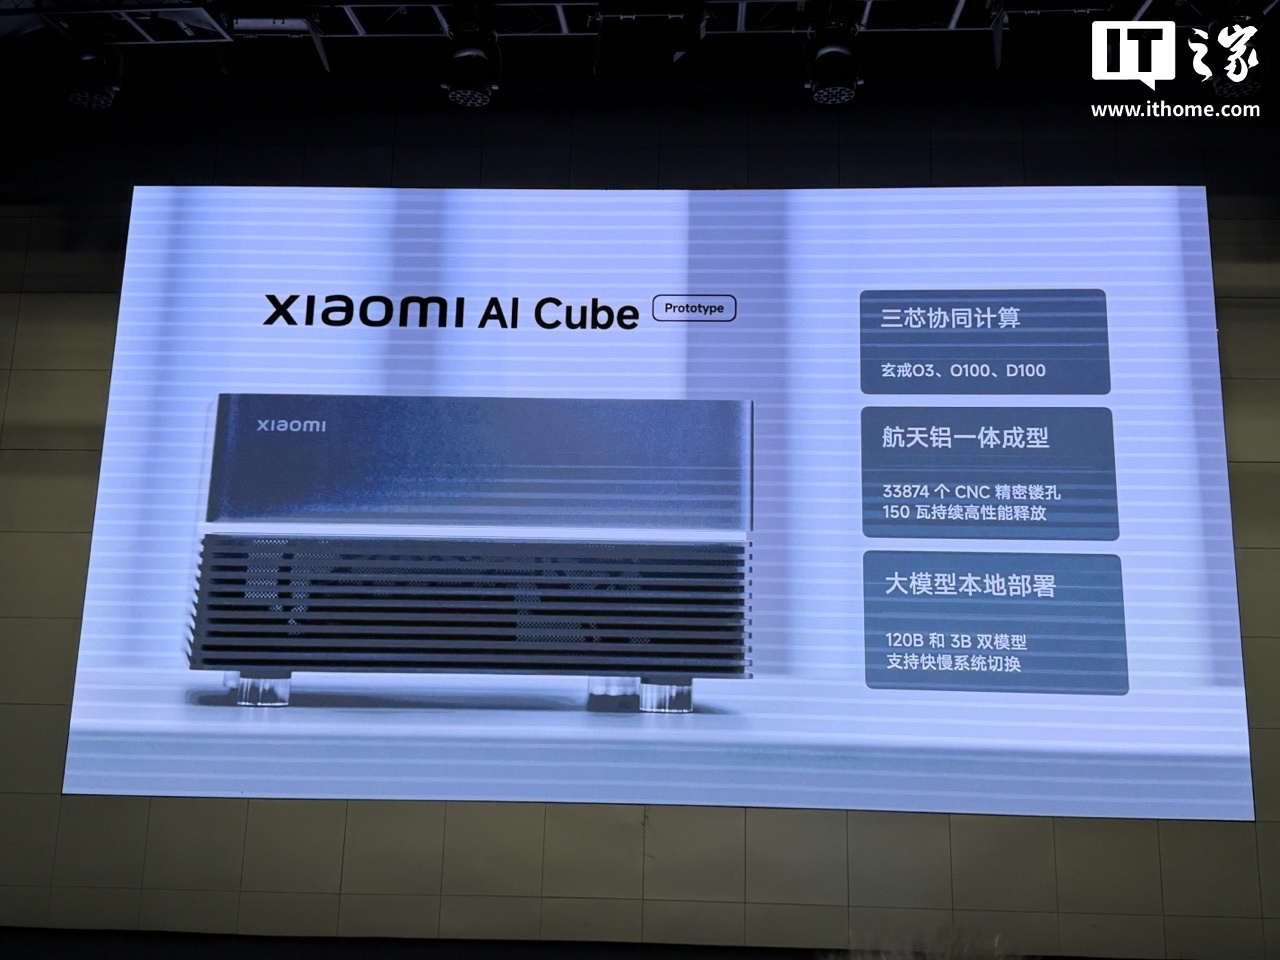
Xiaomi Shows AI Cube Prototype: Three Chips, 1.22TB/s
Xiaomi unveiled the AI Cube Prototype at its Xuanjie chip technical briefing on August 24, 2026 — an engineering-sample mini PC built around three of the company’s own chips at once, aimed squarely at running large language models locally. The headline number is the 1.22 TB/s bandwidth of the new Xuanjie O100 accelerator, but the […]
-
Gemini 3.7 Flash: A Big Coding Jump in a Three-Week Point Release
On August 13, 2026, Google DeepMind released Gemini 3.7 Flash — just 23 days after Gemini 3.6 Flash, and built on the same architecture and training data. The model card is explicit that this is not a new pretraining run but “algorithmic improvements to its core reasoning foundation.” The gains are concentrated almost entirely in […]
-
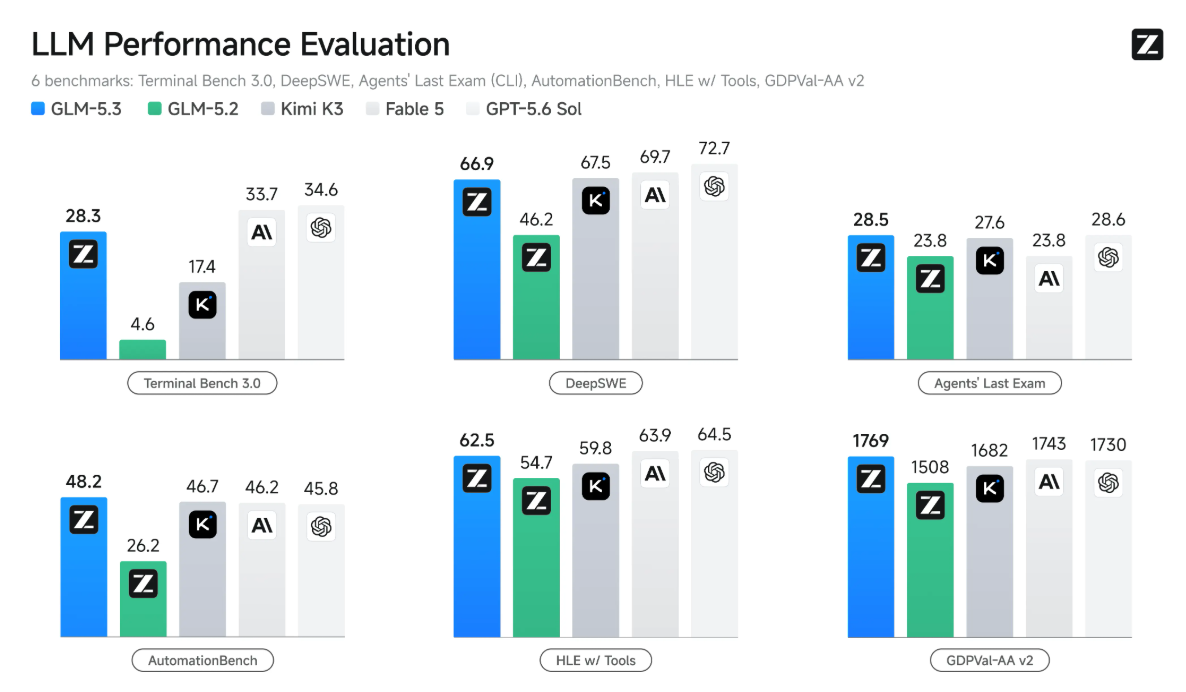
GLM-5.3: Z.ai Scales Post-Training, Holds the Weights Back
On August 14, 2026, Z.ai (formerly Zhipu AI) released GLM-5.3 — and, unusually, without a new base model. GLM-5.3 sits on the same 743-billion-parameter Mixture-of-Experts base as June’s GLM-5.2, and every reported gain comes from extended post-training alone. The model is live now through Z.ai’s API, its GLM Coding Plan, and the ZCode client, but […]
-
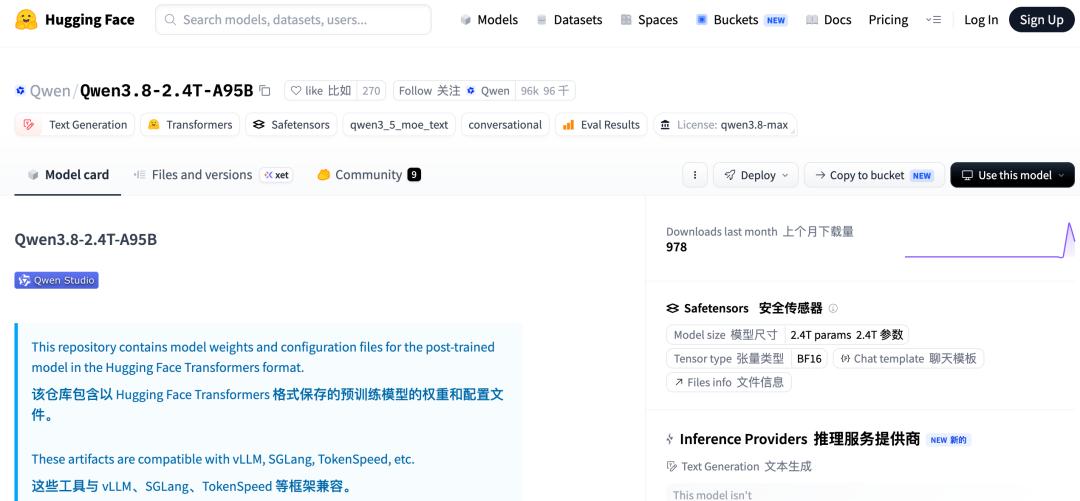
Qwen3.8-2.4T-A95B: Alibaba Open-Weights Its Max-Tier Flagship
Alibaba published the weights for Qwen3.8-2.4T-A95B on August 13, 2026 — the open-weight release of Qwen3.8-Max, the 2.4-trillion-parameter Mixture-of-Experts model it launched as an API product ten days earlier. It is the first time Alibaba has released a Max-tier model’s weights, and at 2.4T total parameters it is the largest open-weight language model published to […]
-
LTX-2.5 Adds Native Multi-Shot Video and a Diffusion Decoder
LTX released LTX-2.5 on August 11, 2026 — an update to its 22-billion-parameter open-weights audio-video model that replaces the VAE reconstruction stage with a diffusion video decoder, adds native multi-shot generation in a single pass, and ships with day-one ComfyUI support. The Israeli company behind Lightricks says the model generates a 10-second clip in 6.8 […]
-
AIUC-1, the AI Agent Certification, Turns to Coding Agents
On July 15, 2026, the Artificial Intelligence Underwriting Company shipped the Q3-2026 revision of AIUC-1 — the AI agent certification standard it launched a year earlier — and pointed it squarely at coding agents. The release changed 8 requirements and 41 controls, adding two mandatory requirements that exist because an agent writing code is not […]
-
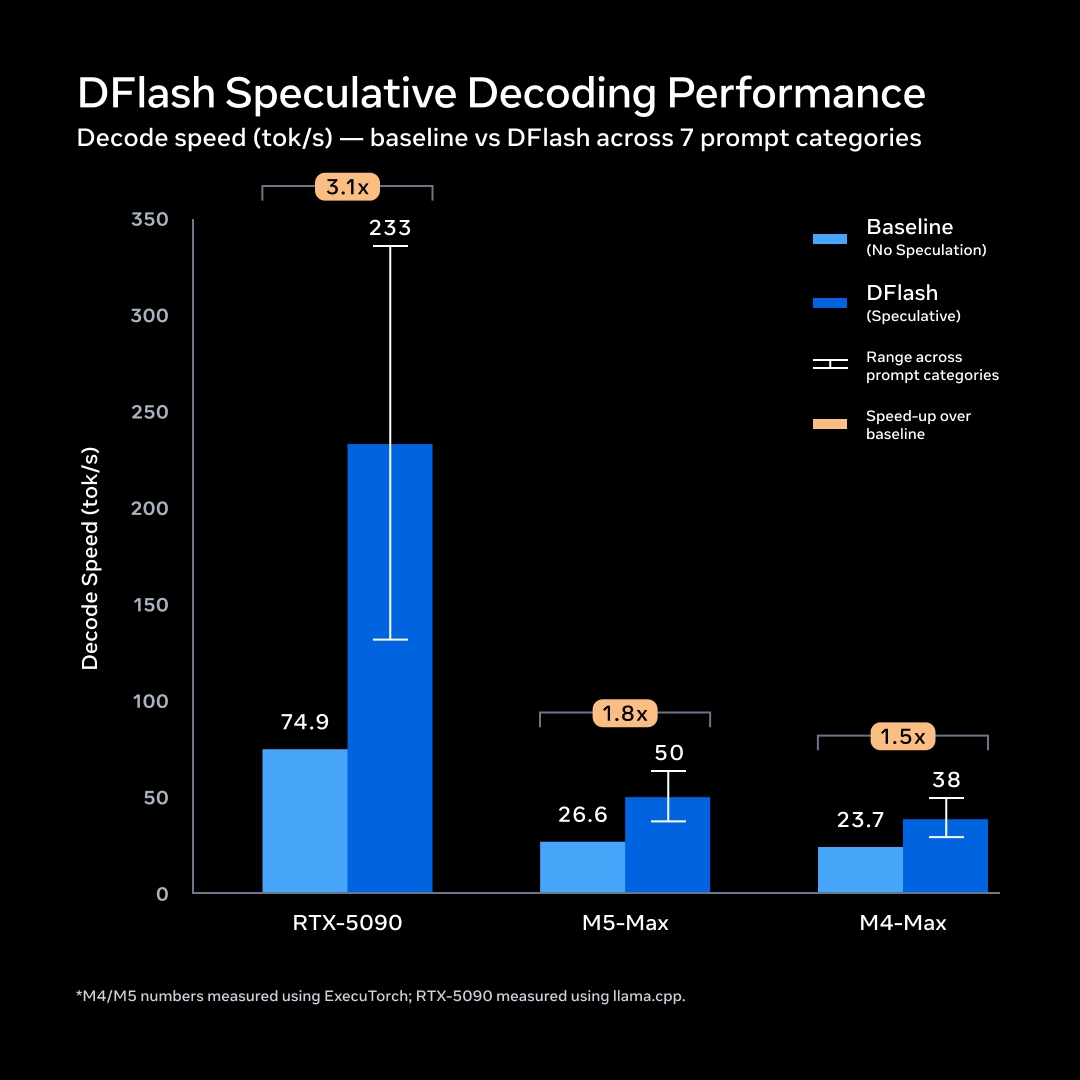
Meta Releases Muse Glimmer, a 30B Agent Model for a Single GPU
On August 10, 2026, Meta released Muse Glimmer — a 30-billion-parameter open-weight model, licensed Apache 2.0, built specifically to run agent workflows locally on a single consumer GPU. It is distilled from Muse Spark, the closed frontier model Meta Superintelligence Labs launched in April, and it is the clearest statement yet of where Meta draws […]
-
AMD Acquires Taalas, the Startup Etching LLMs Into Silicon
On August 6, 2026, AMD announced a definitive agreement to acquire Taalas — the Toronto startup whose chips abandon the idea of loading a model from memory altogether, and instead etch its weights permanently into the transistors themselves. Financial terms were not disclosed. The deal is subject to regulatory approval and is expected to close […]
-
Google Open-Sources WeatherNext: Cyclone Forecasts Gain a Day
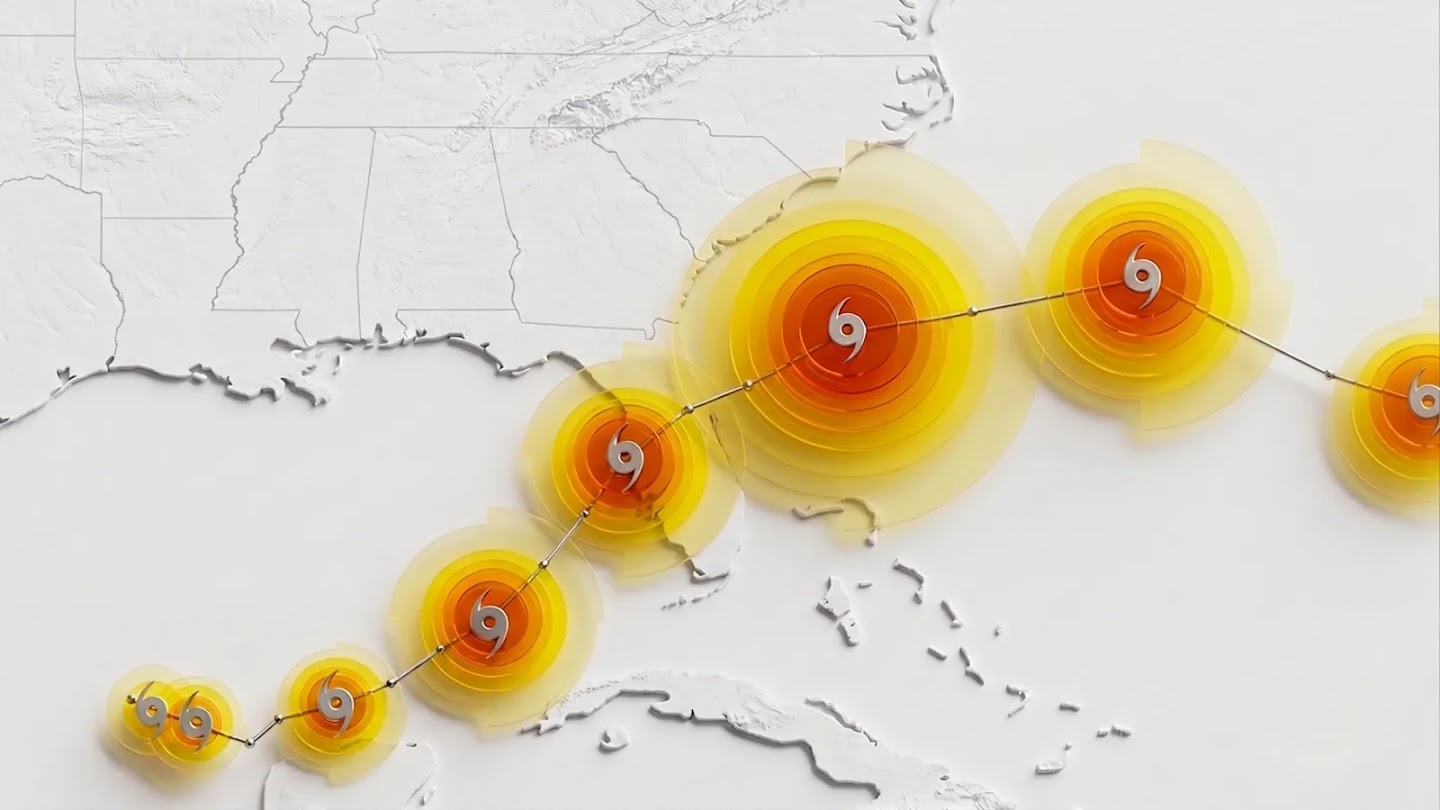
On August 6, 2026, Google DeepMind released the code and model weights for its WeatherNext forecasting family on GitHub, alongside a Nature paper reporting that its cyclone model gives forecasters roughly an extra day of warning on tropical storm track, intensity, and size. The release covers three variants — WeatherNext Cyclones, the general-purpose WeatherNext 2, […]