Tag: llm
-
Vending-Bench 2: AI Models Put to the Test Running a Business for a Year
Key points Andon Labs released Vending-Bench 2, a long-horizon benchmark that gives each model a $500 starting balance to run a simulated vending machine business across 365 simulated days. Claude Opus 4.6 tops the leaderboard at $8,017.59 in final account balance, ahead of Claude Sonnet 4.6 at $7,204.14 and Gemini 3 Pro at $5,478.16. Andon […]
-
Qwen 3.5: Alibaba’s Native Multimodal Agent Model Arrives
Key points Alibaba’s Qwen team released Qwen 3.5 on February 16, 2026, with a flagship 397B-parameter mixture-of-experts model built for the agentic AI era. The flagship Qwen3.5-397B-A17B activates only 17 billion parameters per forward pass despite having 397 billion total parameters. Listed specifications include a 256K-token native context window, 1M tokens on the hosted Qwen3.5-Plus, […]
-
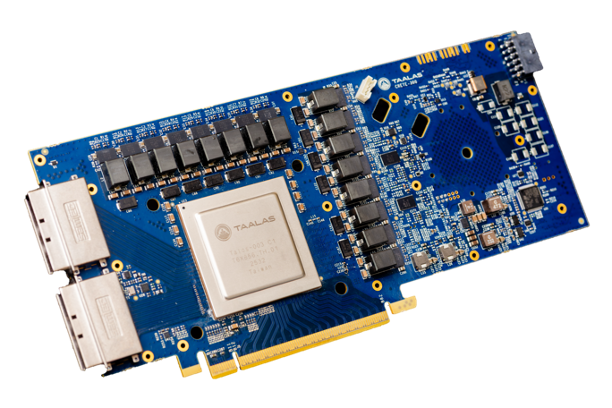
Taalas HC1: Hardwiring Llama 3.1 Into Silicon for 17,000 Tokens/Second
Key points On February 21, 2026, Toronto-based startup Taalas unveiled the HC1, a custom ASIC that hard-codes Meta’s Llama 3.1 8B language model directly into silicon. Taalas says the HC1 delivers up to 17,000 tokens per second per user, roughly ten times faster than today’s best GPU-based solutions, at a fraction of the cost and […]
-
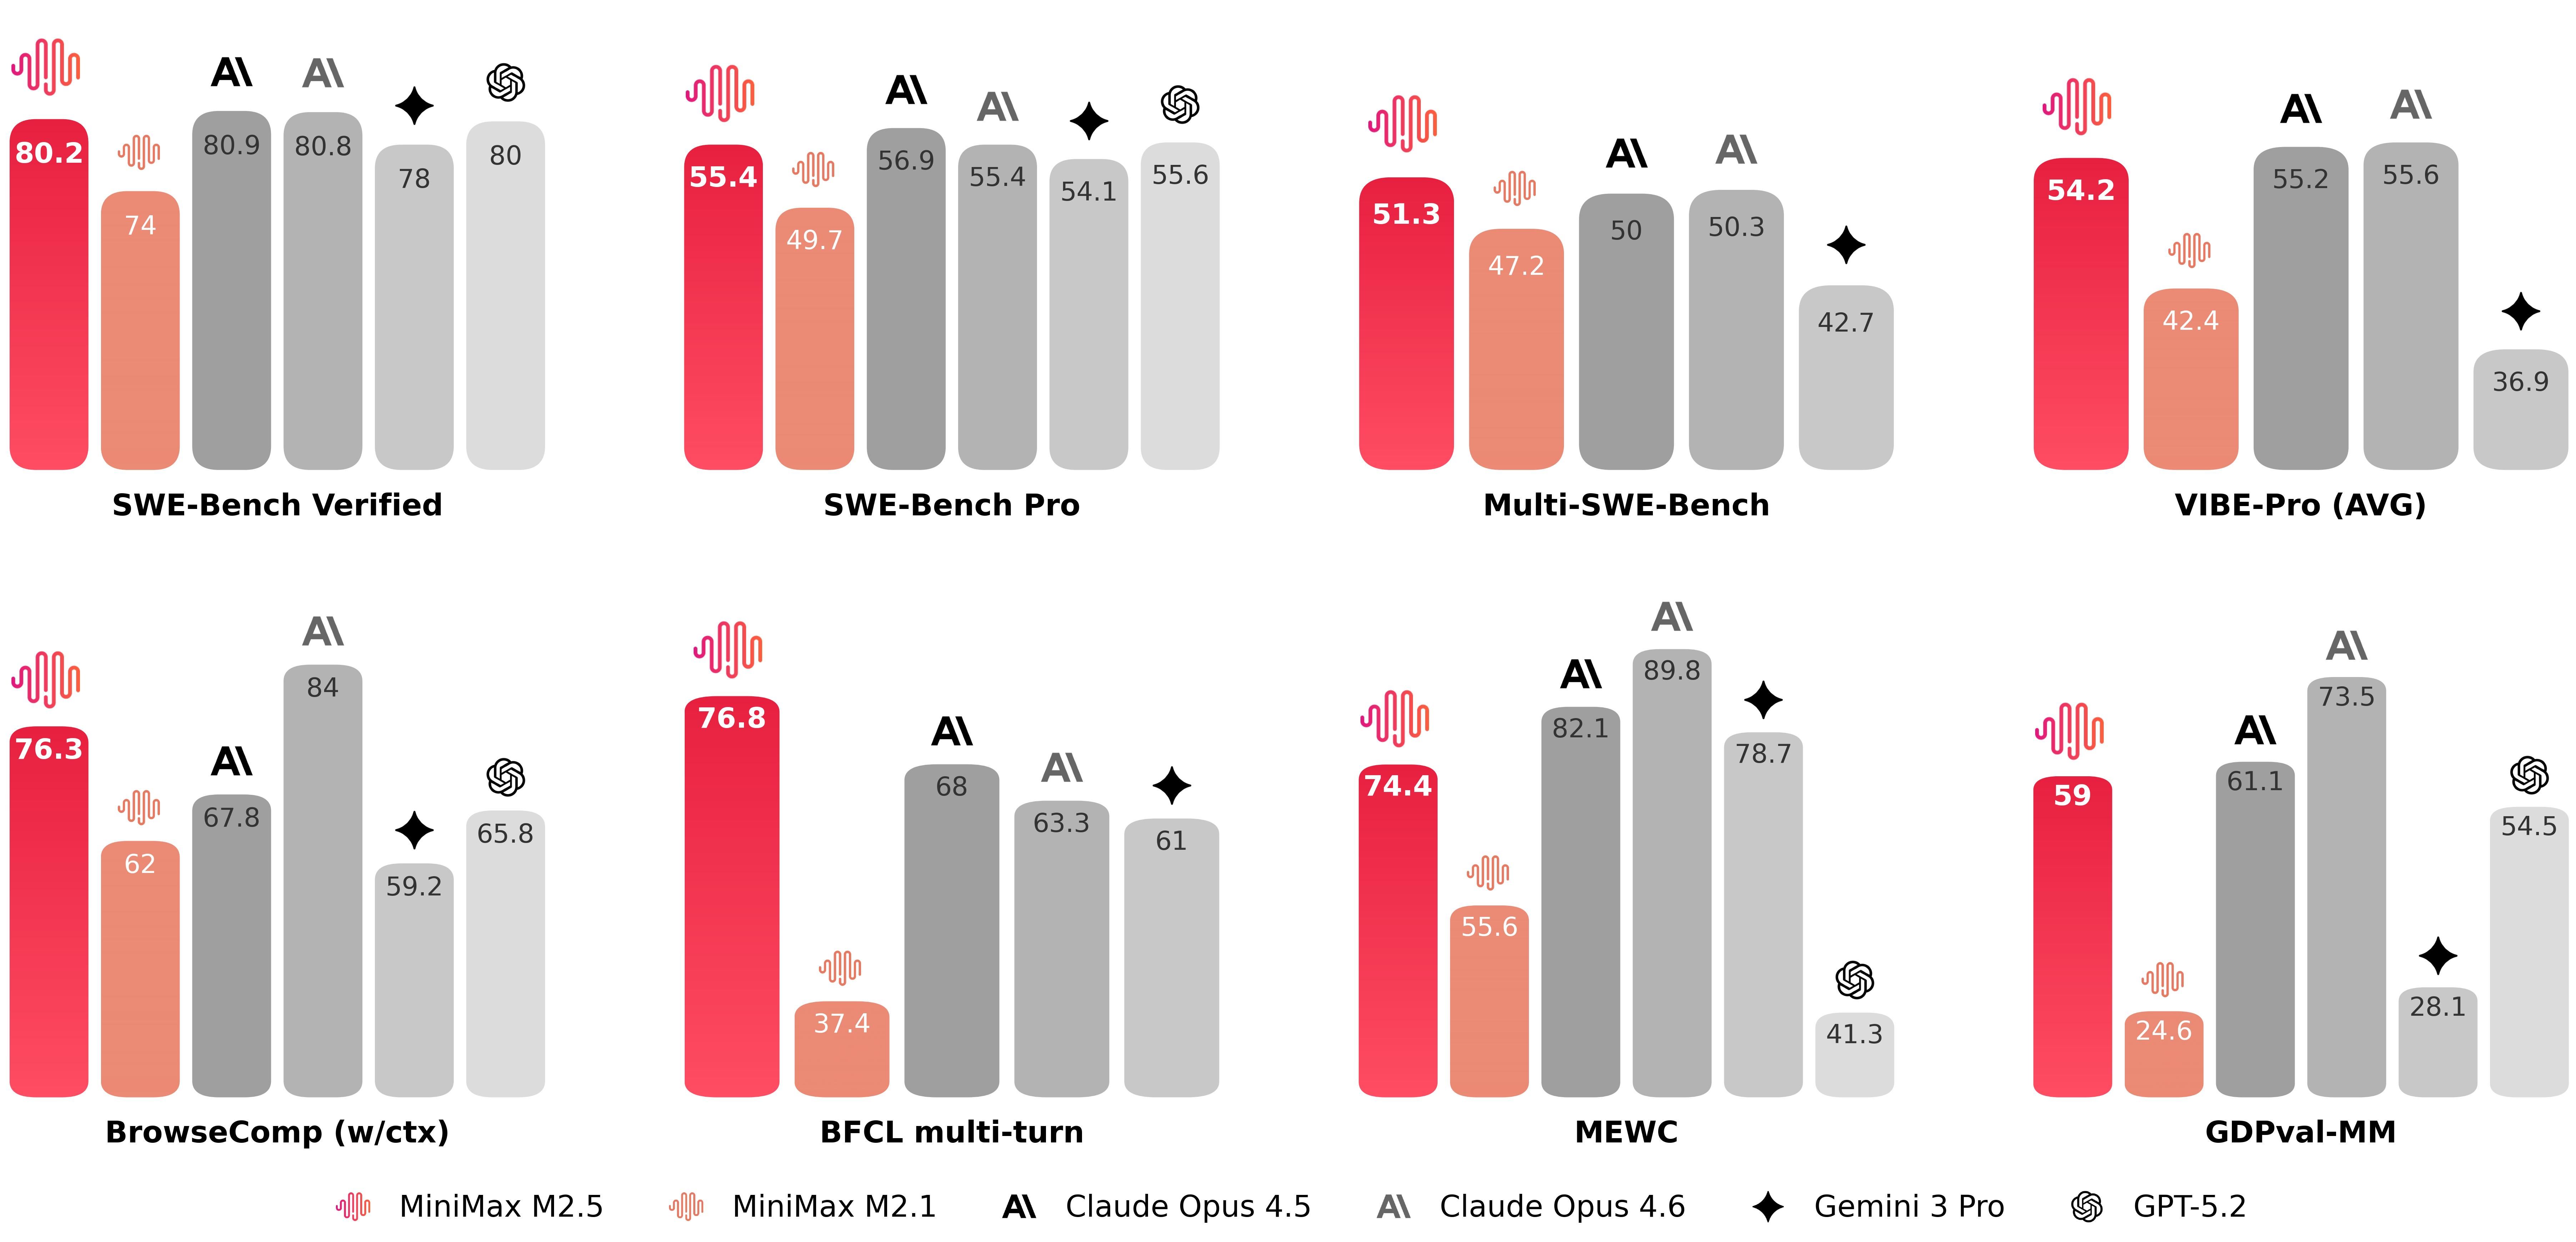
MiniMax M2.5: Frontier AI Performance at a Fraction of the Cost
Key points Announced on February 12, 2026, MiniMax’s M2.5 ships as open weights under a modified MIT license and, according to the company, matches leading proprietary systems at one-tenth to one-twentieth of their cost. M2.5 is a mixture-of-experts model with 229 billion total parameters, 10 billion active parameters and a 200,000-token context window, designed for […]
-
GLM-5: Zhipu AI Ships a 744B Open-Weight Frontier Model
Key points On February 11, 2026, Zhipu AI released GLM-5 through its Z.ai platform with 744 billion total parameters and a Mixture-of-Experts architecture. GLM-5 has 744B total parameters with 40B active per token, spanning 80 layers and 256 experts of which 8 are active at inference, a sparsity rate of about 5.9%. GLM-5 scored 50 […]
-
GLM-4.7-Flash: Z.ai’s Efficient 30B MoE Model for Coding and Agents
Key points Z.ai released GLM-4.7-Flash on January 20, 2026, a fully open-source model under the MIT license that is available for free via the Z.ai API platform. Despite its 30B label, the model uses a Mixture-of-Experts architecture with 31.2 billion total parameters but only approximately 3 billion active parameters during any given inference pass. It […]
-
Anthropic Releases Claude Opus 4.6 with 1M Token Context Window
Key points Anthropic released Claude Opus 4.6 on February 5, 2026, upgrading its flagship model with a 1 million token context window in beta at unchanged pricing. The 1M token window is a fivefold expansion over Opus 4.5’s previous 200k token context window. On MRCR v2, a needle-in-a-haystack retrieval test that buries facts inside large […]
-
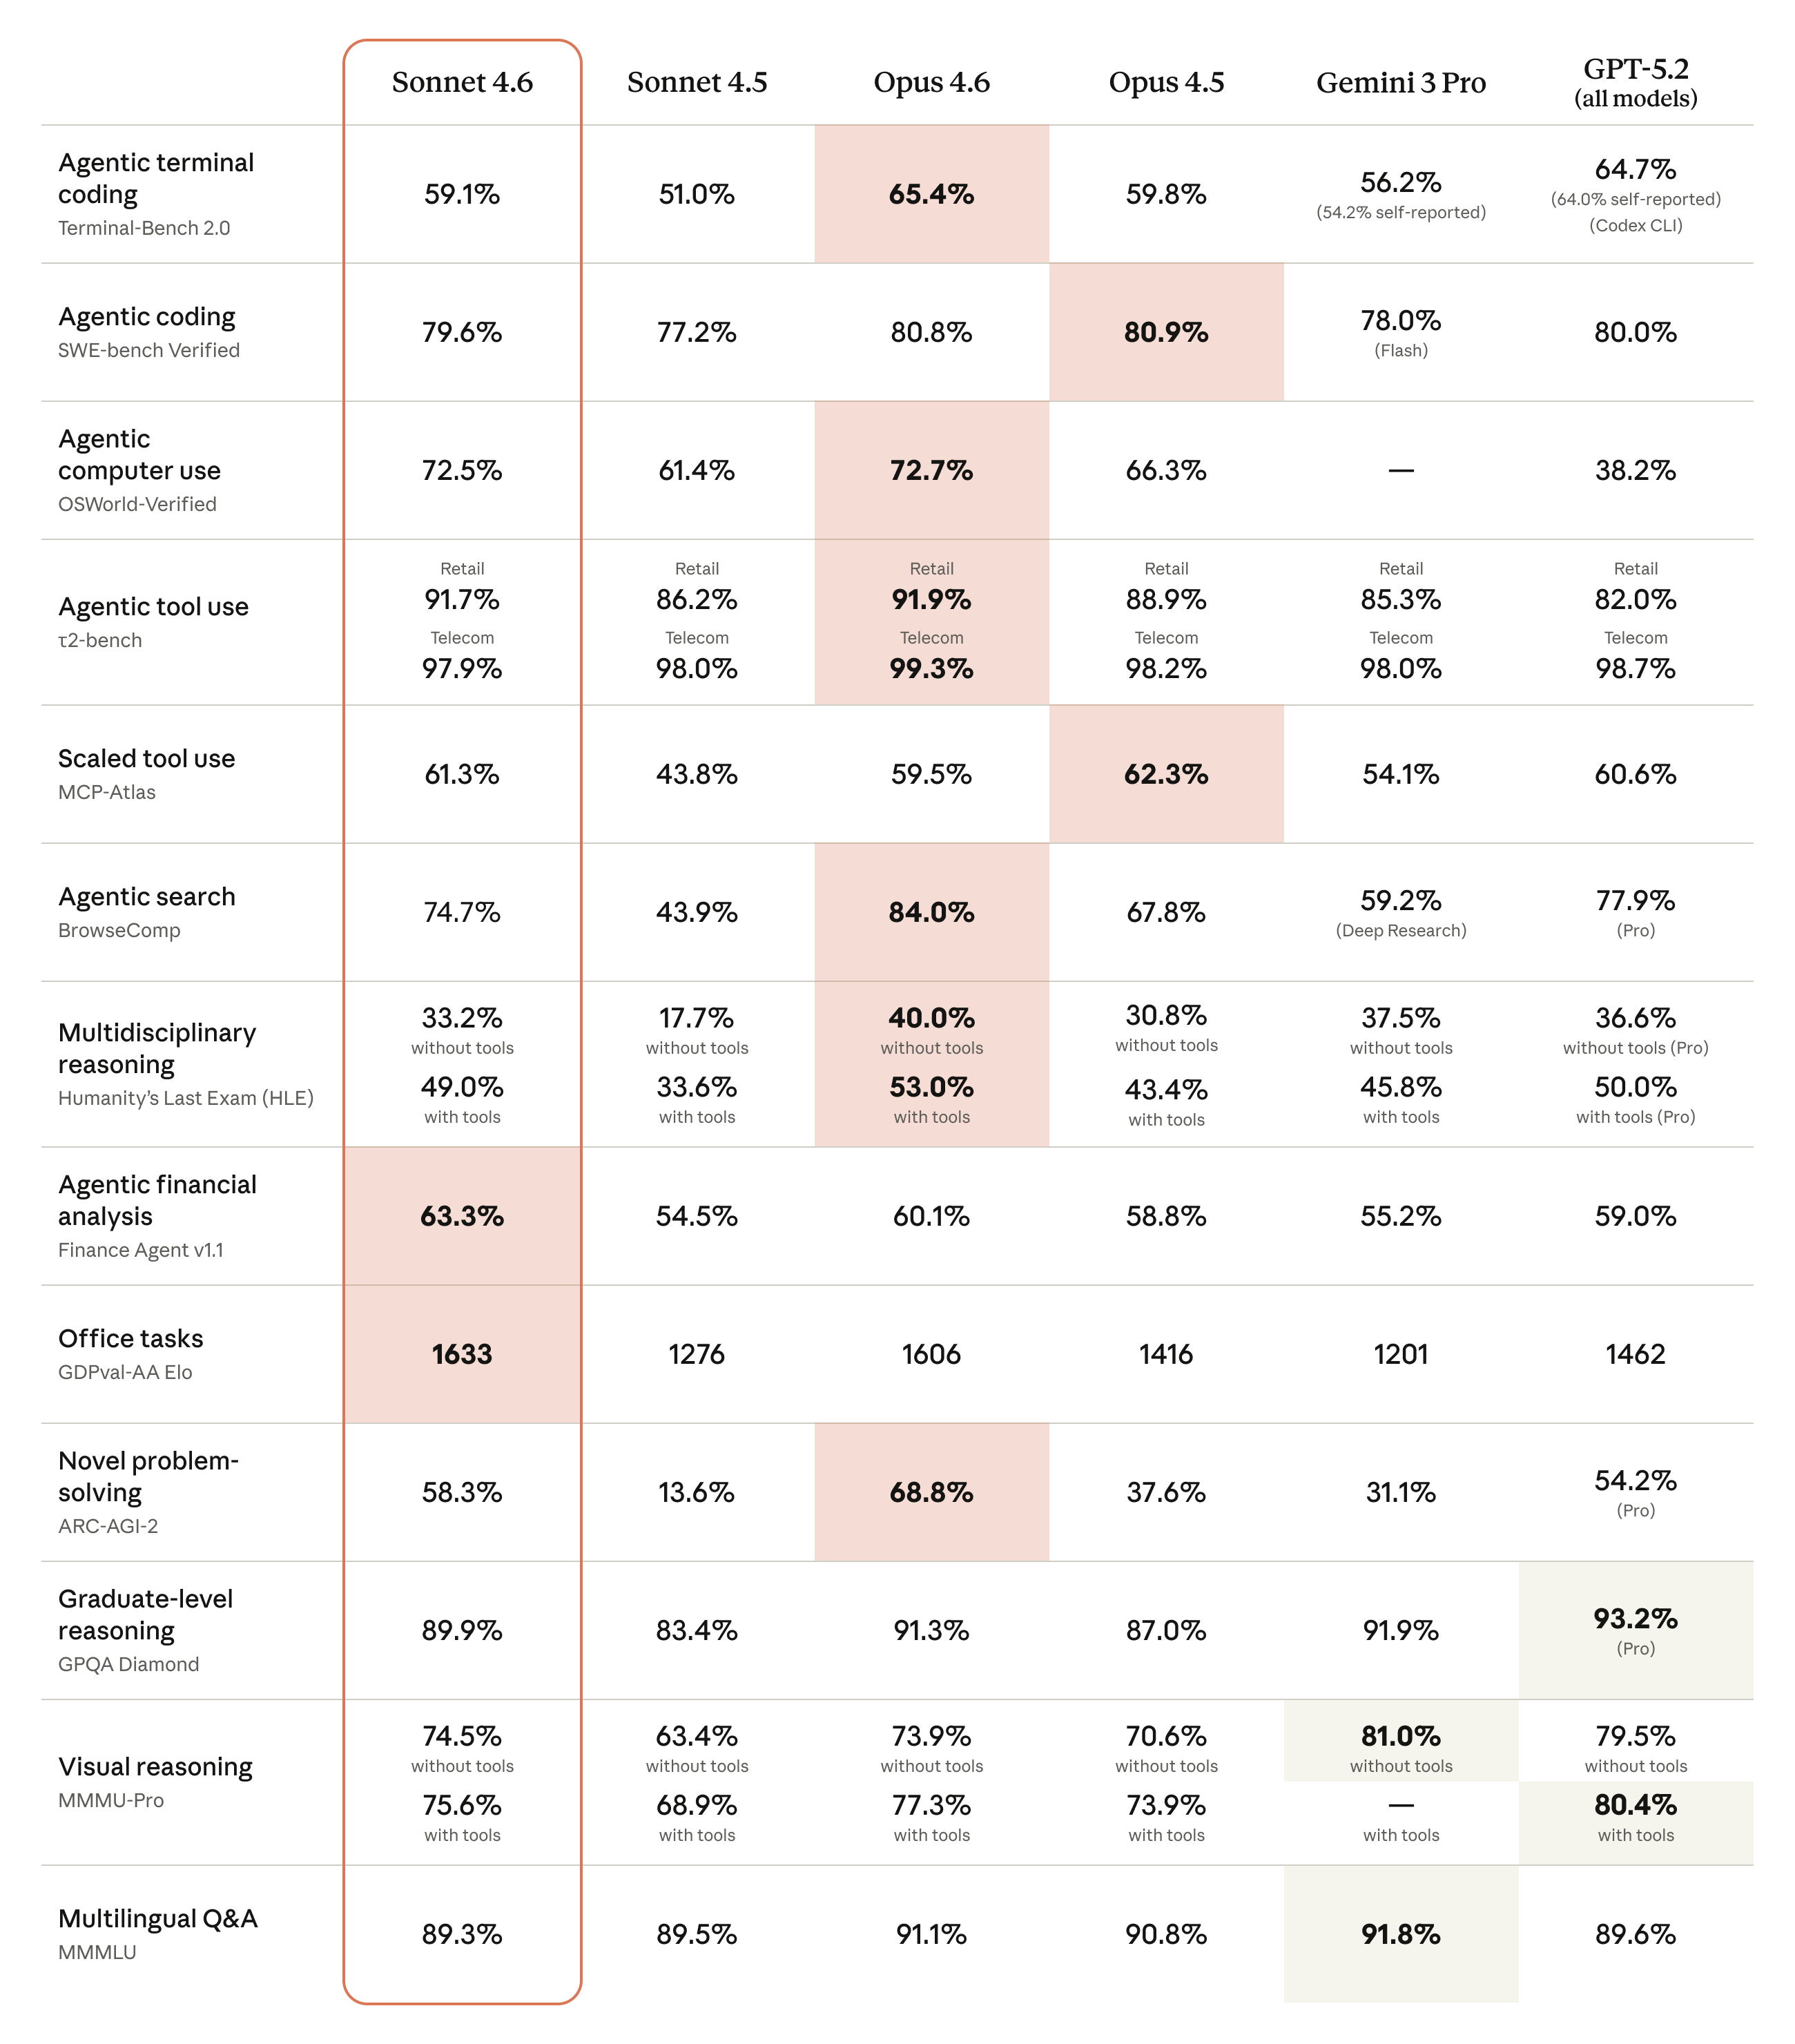
Introducing Claude Sonnet 4.6: Flagship Performance at Mid-Tier Cost
Key points Anthropic released Claude Sonnet 4.6 on February 17, 2026, and says it matches Claude Opus 4.6 on many benchmarks while costing five times less. Sonnet 4.6 has a 1 million token context window in beta, described as the first Sonnet-class model able to process entire codebases, lengthy legal contracts or dozens of research […]
-
Microsoft’s Fara7b: A Breakthrough in Efficient Agentic AI Models
Key points The article describes Microsoft’s Fara7b as an efficient agentic model and claims its approach optimizes performance while reducing computational overhead. The article says Fara7b balances accuracy and efficiency by refining parameter optimization and leveraging distributed computing, which it presents as making the model suited to edge devices or scenarios with limited computational power. […]
-
Gemini 3: A New Era of Intelligence from Google
On November 18 2025, Gemini 3 was officially introduced by Google DeepMind and Google LLC. (blog.google) This marks what they call “a new era of intelligence” — with Gemini 3 being described as their most advanced model yet. (blog.google) Key points On November 18 2025, Gemini 3 was officially introduced by Google DeepMind and Google […]