Tag: local inference
-
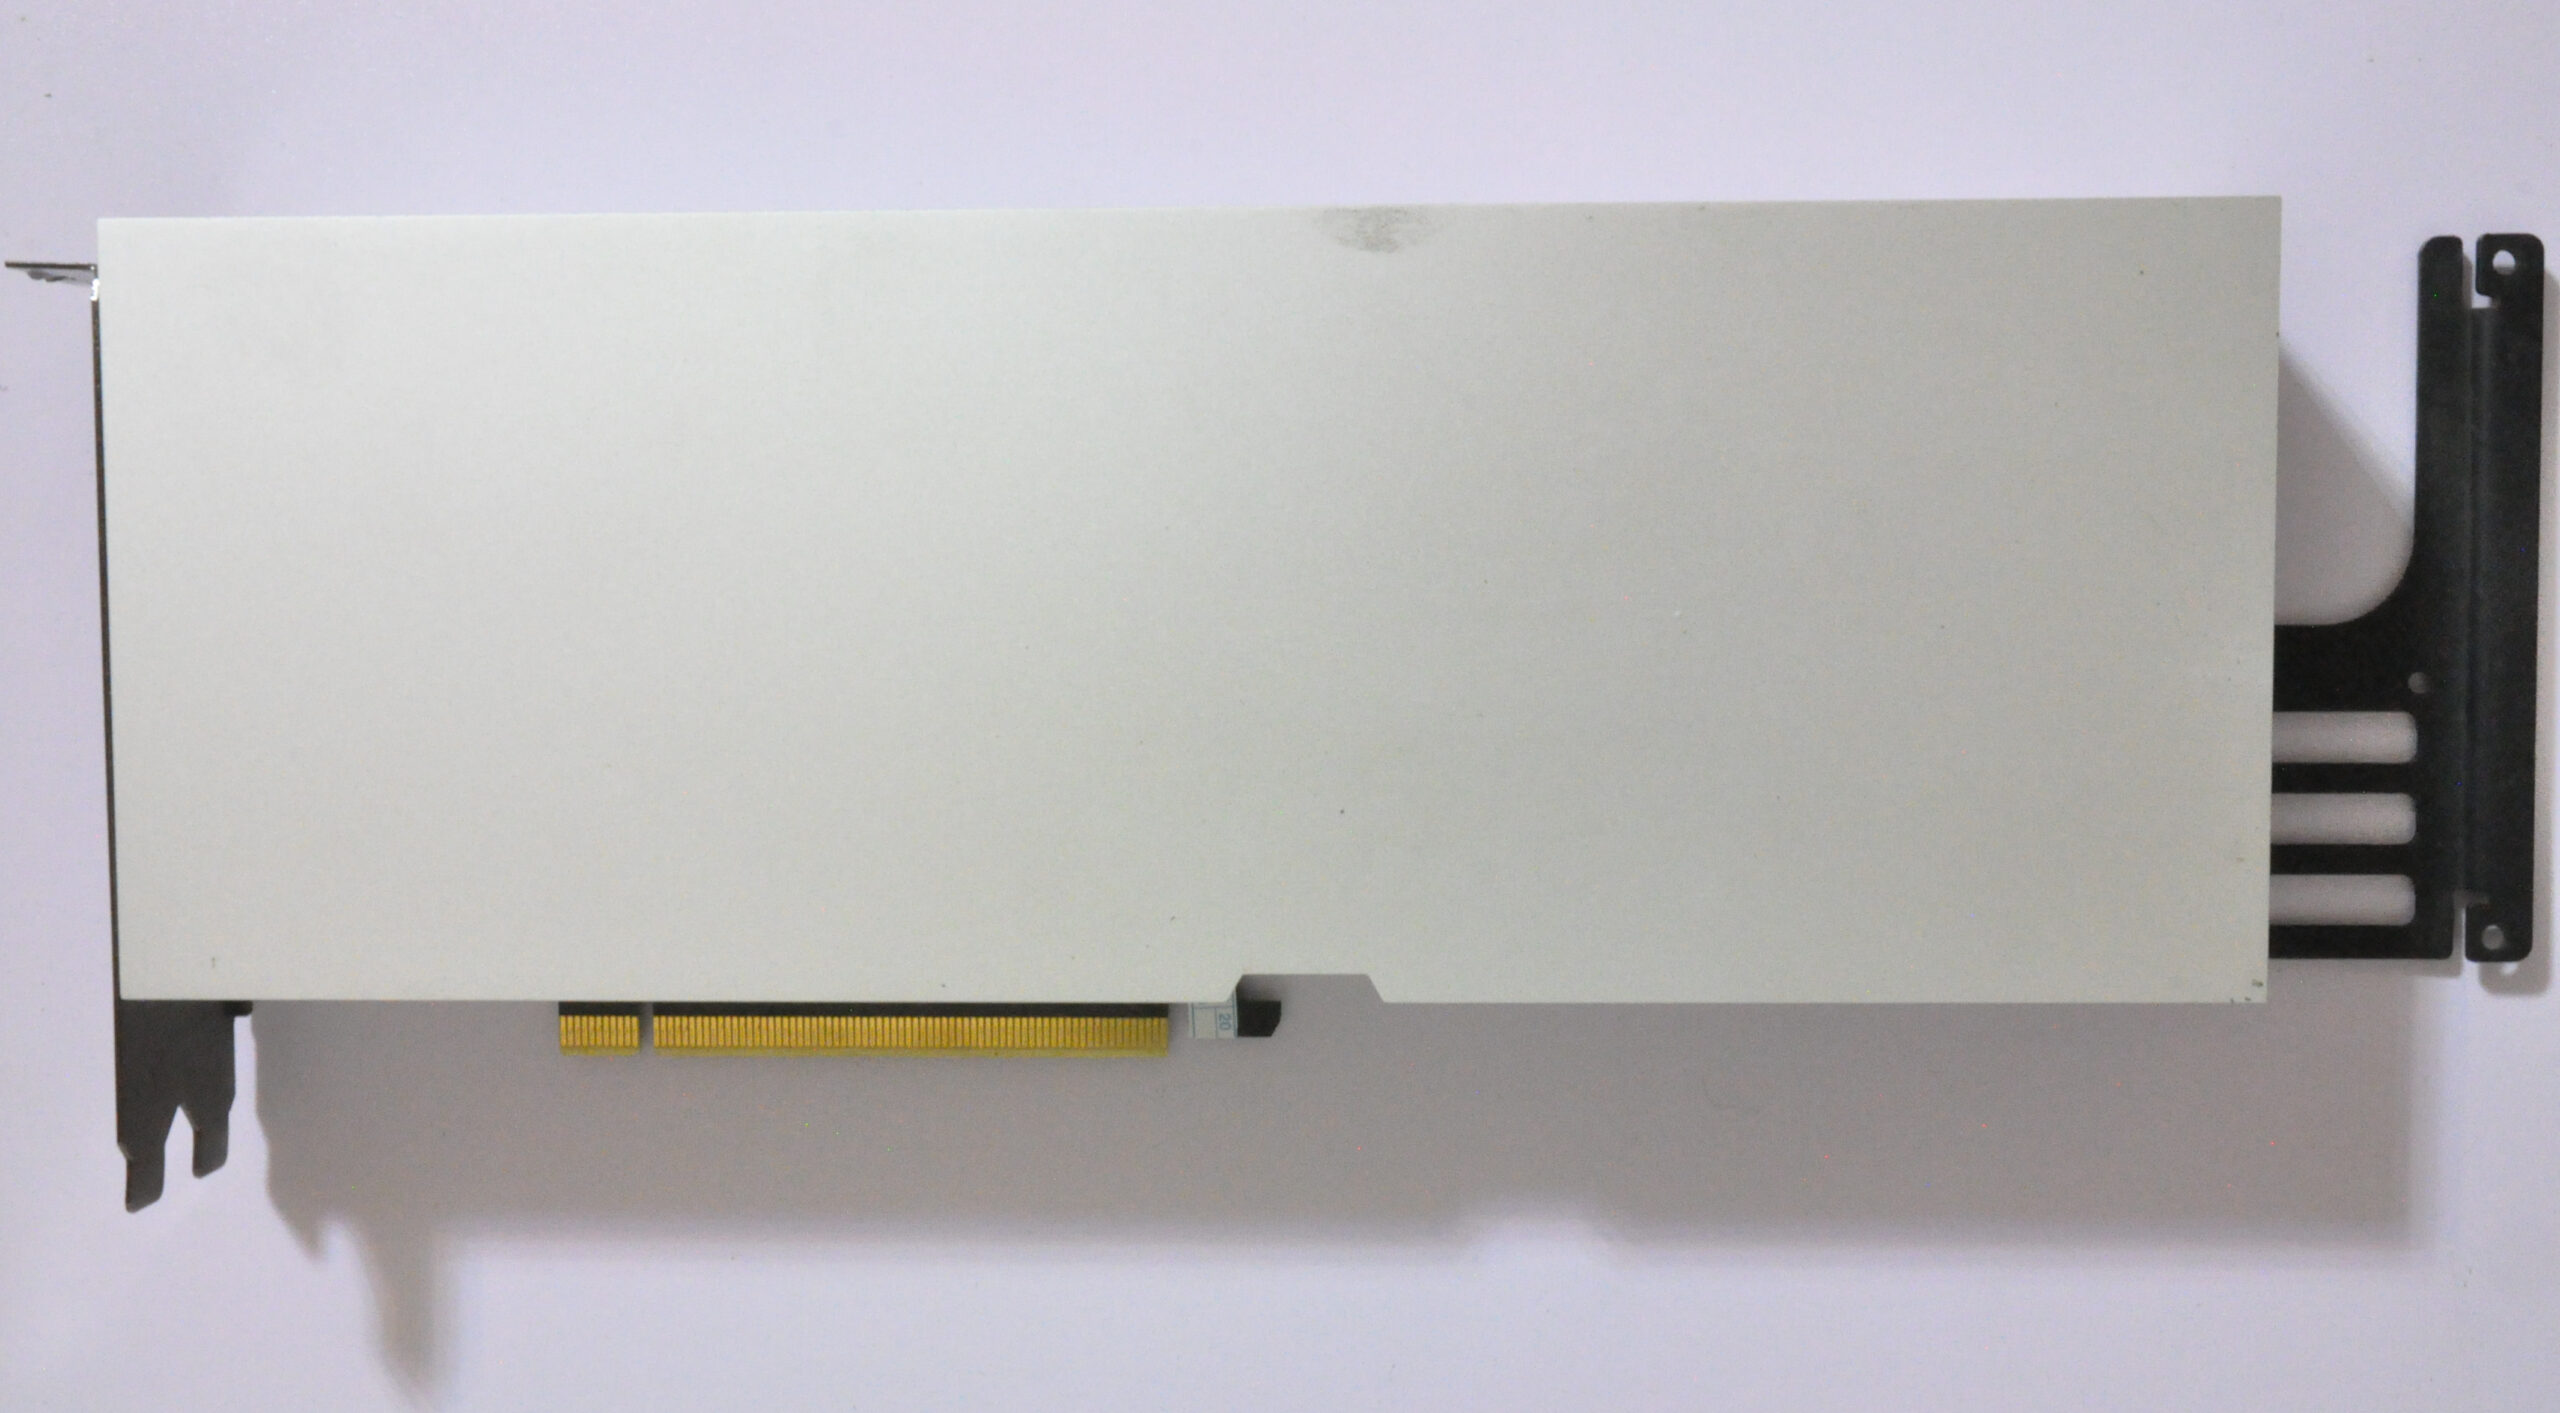
The 8 GB Accelerator That Becomes 64 GB: cmpunlocker v0.5
On 5 October 2026, the open-source project cmpunlocker released version 0.5, adding error-correcting code (ECC) on both DRAM and SRAM, and four more streaming multiprocessors (SMs), to a card it has spent more than a year re-enabling: the NVIDIA CMP 170HX. The board is a GA100 accelerator — the same Ampere die that sits in […]
-
macOS 27 Ships a Foundation Model at the Command Line
macOS 27 “Golden Gate” shipped on September 14, 2026, and with it a system binary at /usr/bin/fm — a command-line interface to Apple’s on-device foundation model, pre-installed, always available, and free of API keys, accounts, and per-token costs. Apple has shipped on-device models since 2024 and opened the Foundation Models framework to developers in 2025, […]
-
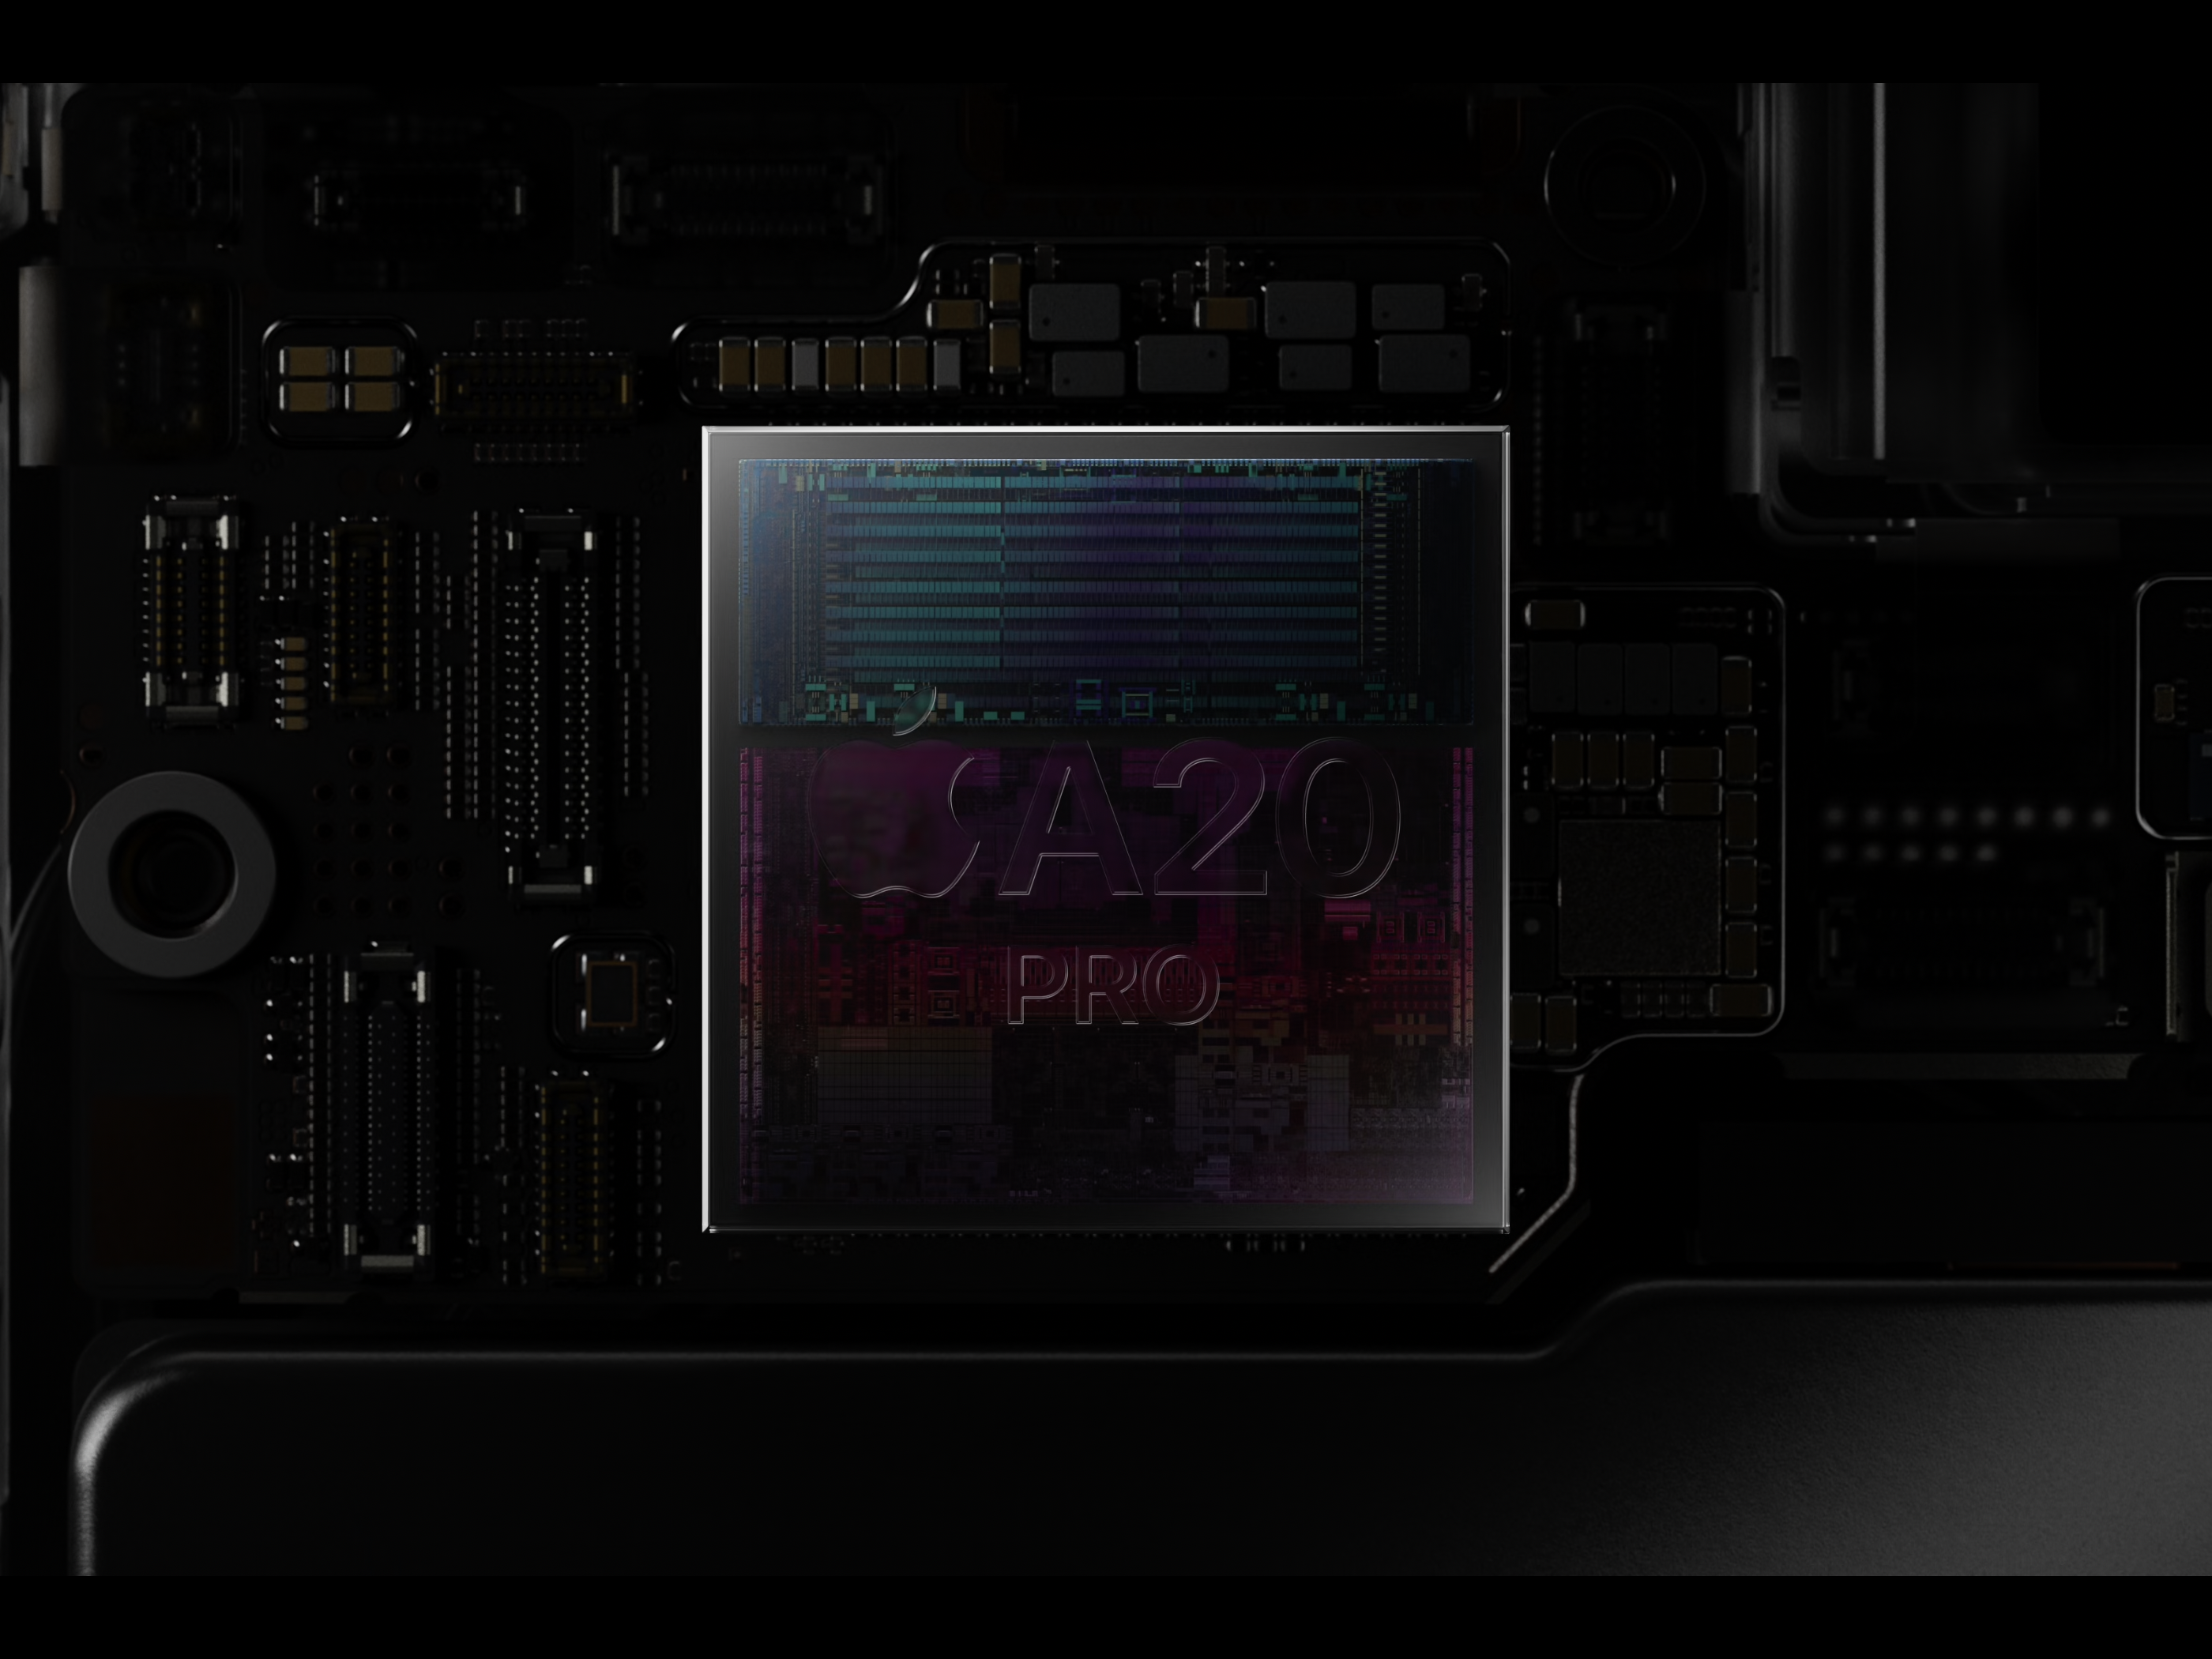
Apple’s A20 Pro Doubles the Neural Engine to 32 Cores
On September 9, 2026, Apple announced the A20 Pro — the first smartphone SoC built on a 2-nanometer process, and the first A-series chip to ship a 32-core Neural Engine. Apple describes the design as a “Dual 16-core Neural Engine” delivering double the AI processing power of the A19 Pro, paired with a 50 percent […]
-
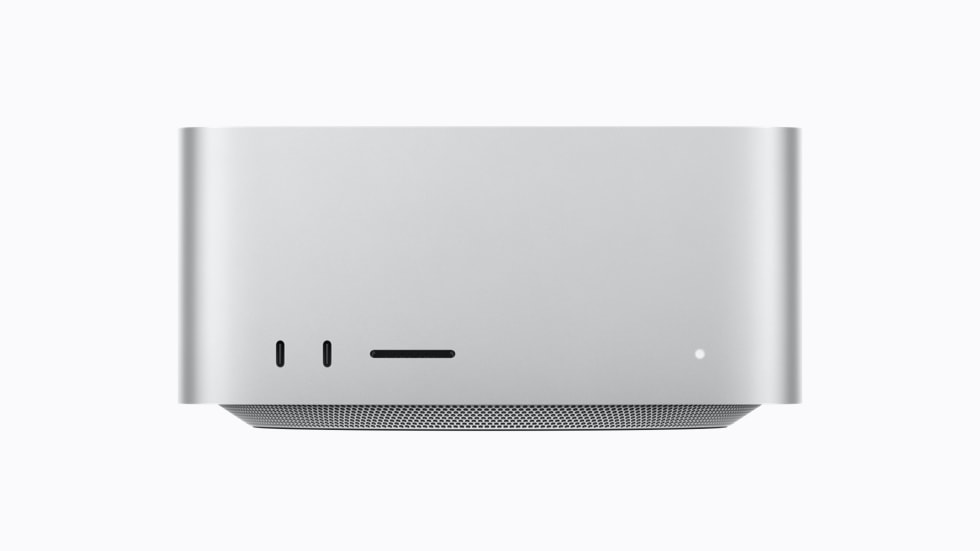
Apple’s M5 Ultra Mac Studio: 512GB of Unified Memory for Local AI
On August 25, 2026, Apple announced a new Mac Studio built around the M5 Max and the quad-die M5 Ultra — a desktop configurable with up to 512GB of unified memory and 1.2TB/s of memory bandwidth. Apple is pitching it explicitly at people running large language models locally: the company says the M5 Ultra configuration […]
-
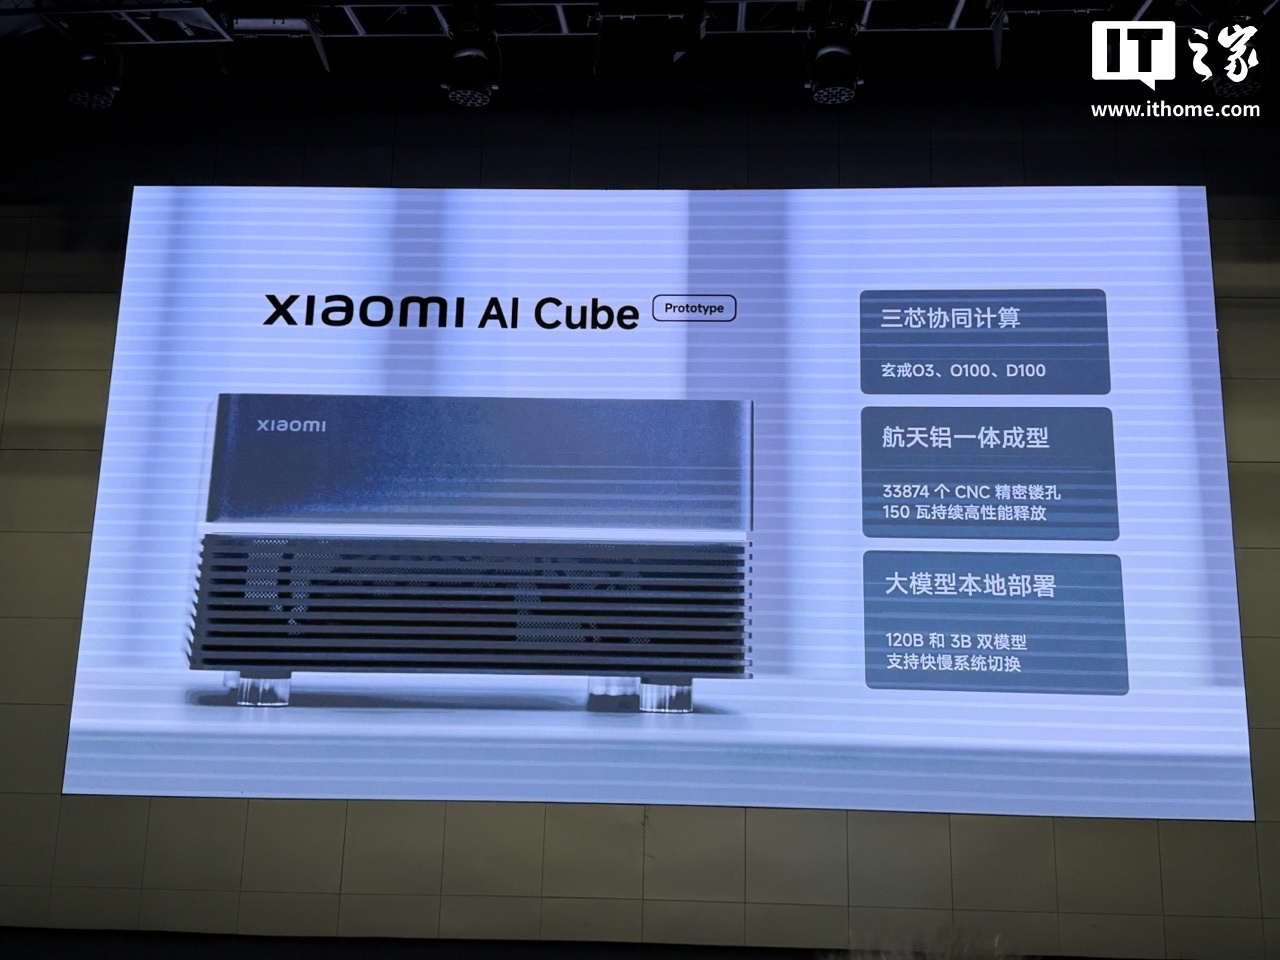
Xiaomi Shows AI Cube Prototype: Three Chips, 1.22TB/s
Xiaomi unveiled the AI Cube Prototype at its Xuanjie chip technical briefing on August 24, 2026 — an engineering-sample mini PC built around three of the company’s own chips at once, aimed squarely at running large language models locally. The headline number is the 1.22 TB/s bandwidth of the new Xuanjie O100 accelerator, but the […]