Tag: moe
-
OpenBMB Releases MiniCPM-V 4.7, Its First MoE Multimodal Model
OpenBMB released MiniCPM-V 4.7 on October 12, 2026 — the latest entry in its MiniCPM-V vision-language series and the first in that line to use a mixture-of-experts (MoE) architecture. The release ships two open-weight models under Apache 2.0: MiniCPM-V 4.7 35B-A3B and MiniCPM-V 4.7 1B. The headline claim is an efficiency one. OpenBMB describes the […]
-
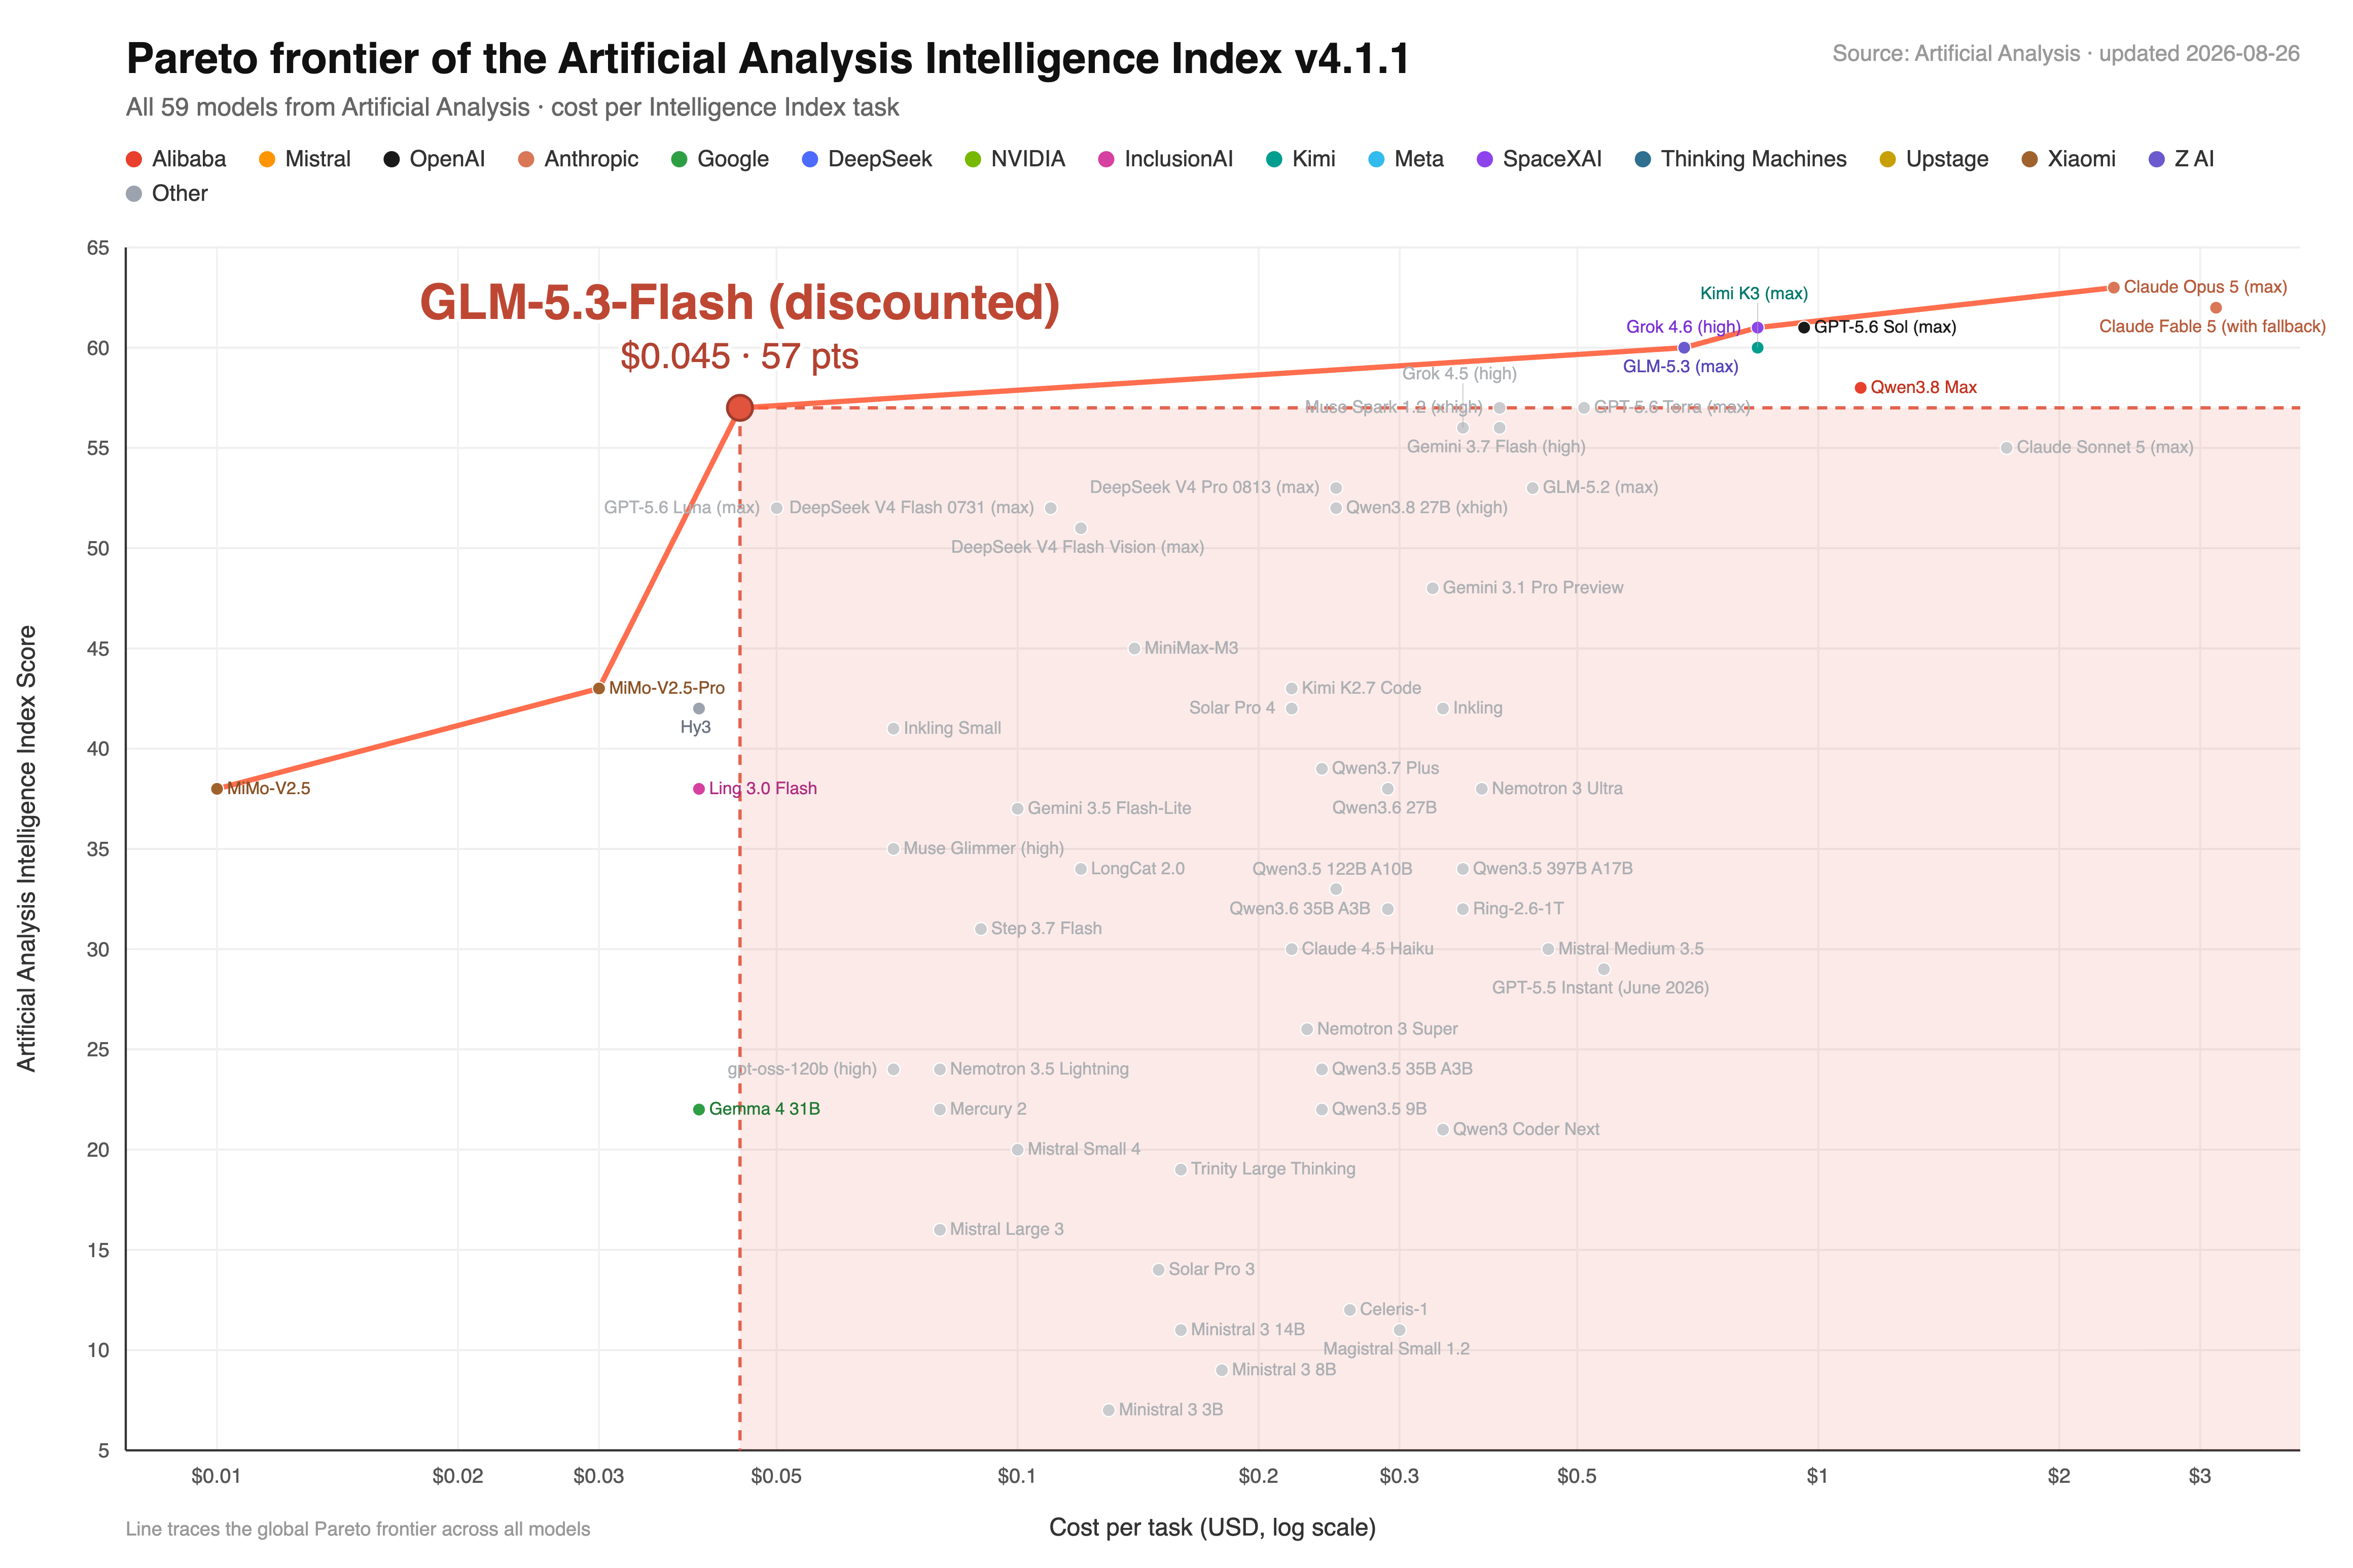
GLM-5.3-Flash: 320B Multimodal MoE, Weights on Day One
On August 26, 2026, Z.ai released GLM-5.3-Flash — a 320-billion-parameter Mixture-of-Experts model that activates just 18 billion parameters per token, and the first natively multimodal model in the GLM-5 series. It is also the release that inverts the pattern set twelve days earlier: GLM-5.3 shipped on August 14 with its weights held back for a […]
-
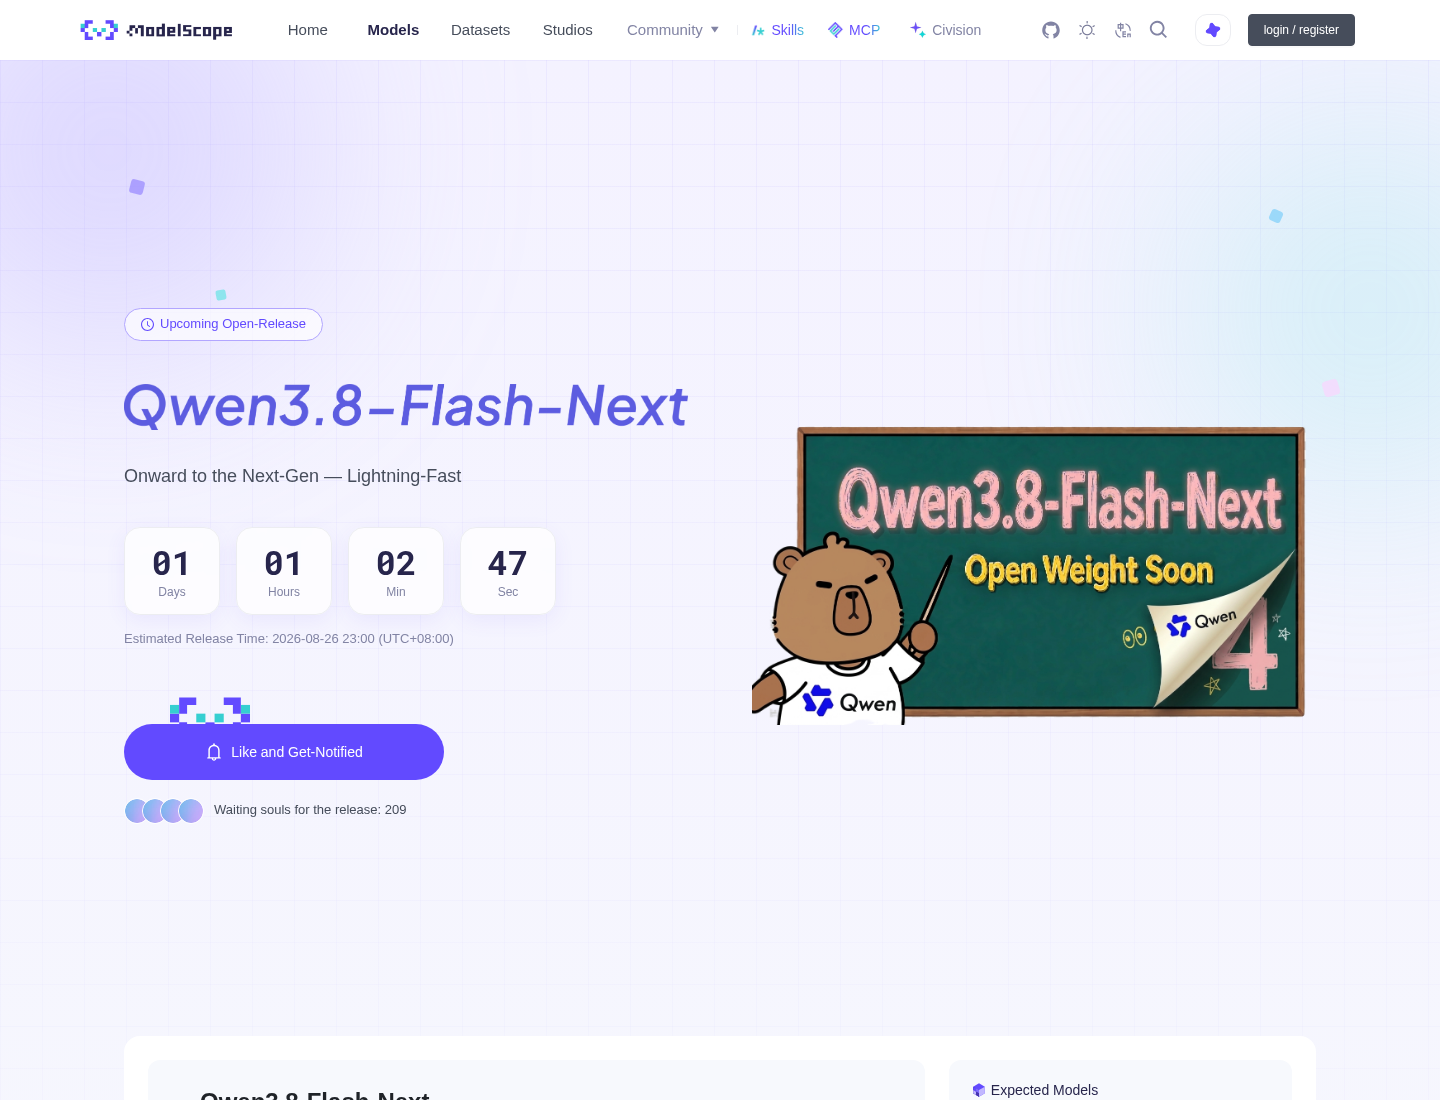
Qwen3.8-Flash-Next: Alibaba Previews the Qwen4 Architecture
Alibaba’s Qwen team has scheduled an open-weight release of Qwen3.8-Flash-Next for 23:00 on August 26, 2026 (UTC+08:00), describing it on ModelScope as “a multimodal MoE model built on the next-generation Qwen4 architecture.” The weights were not yet public at the time of writing. What has circulated instead is a specification block that appeared briefly on […]
-
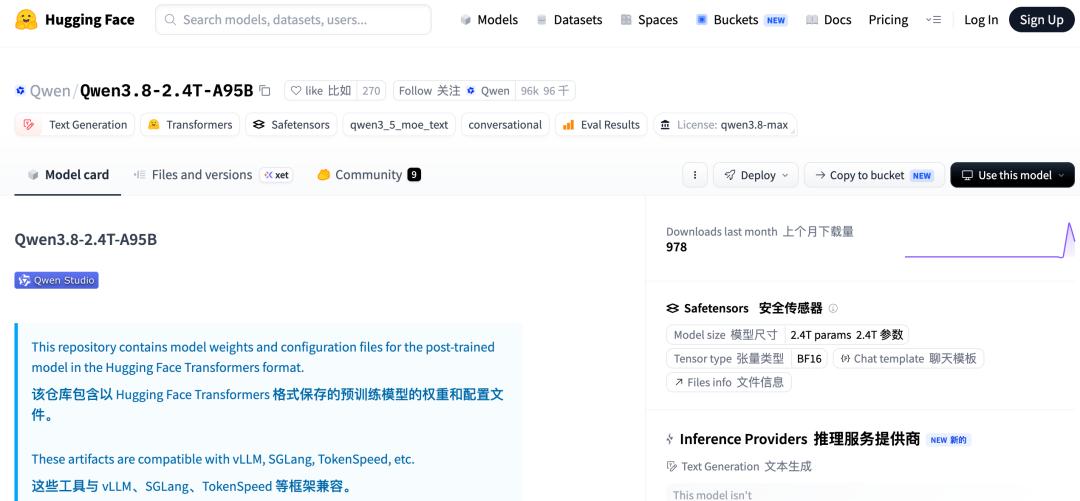
Qwen3.8-2.4T-A95B: Alibaba Open-Weights Its Max-Tier Flagship
Alibaba published the weights for Qwen3.8-2.4T-A95B on August 13, 2026 — the open-weight release of Qwen3.8-Max, the 2.4-trillion-parameter Mixture-of-Experts model it launched as an API product ten days earlier. It is the first time Alibaba has released a Max-tier model’s weights, and at 2.4T total parameters it is the largest open-weight language model published to […]
-
Qwen3.8-Max Draws Level With the Frontier on Agentic Benchmarks
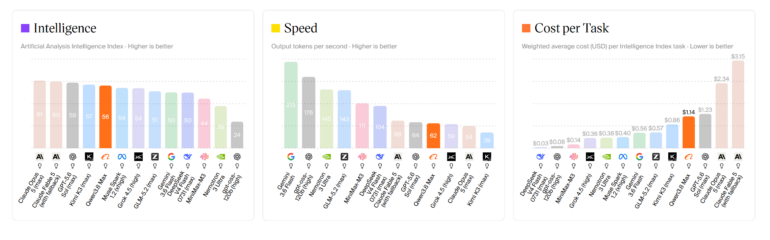
Alibaba released Qwen3.8-Max on August 3, 2026, and within days independent evaluation put it level with the frontier on agentic work. On Artificial Analysis’ Agentic Index, the 2.4-trillion-parameter model scores 58 — tied with Claude Opus 5 running at xhigh effort, and one point behind Opus 5 at max effort, which still holds the top […]
-
Qwen3.8-Max Preview: Alibaba’s 2.4T-Parameter Bid for the Frontier
Alibaba’s Qwen team announced Qwen3.8-Max-Preview on July 19, 2026 — a 2.4 trillion-parameter multimodal model the team calls its most capable system yet, claiming performance “second only to Fable 5” among the models it evaluated. The preview landed just two days after Moonshot AI’s 2.8 trillion-parameter Kimi K3 open-weight release, underscoring how quickly China’s frontier […]
-
Qwen3.6-35B-A3B: Alibaba Open-Sources a Frontier-Class Agentic Coder
On April 2, 2026, Alibaba’s Qwen team open-sourced Qwen3.6-35B-A3B — the first open-weight variant of the Qwen3.6 generation. Released under Apache 2.0 on Hugging Face alongside the proprietary Qwen3.6-Plus API model, the 35-billion-parameter Mixture-of-Experts model activates just 3B parameters per token while posting frontier-level scores on agentic coding and reasoning benchmarks, including 73.4 on SWE-bench […]
-
Qwen 3.5 Medium Series: Frontier AI That Fits on Your GPU
Key points On February 24, 2026, Alibaba’s Qwen team expanded the Qwen 3.5 family with three Apache 2.0 open-weight models — Qwen3.5-27B, Qwen3.5-35B-A3B, and Qwen3.5-122B-A10B — available on Hugging Face. Qwen3.5-27B is a dense model with all 27 billion parameters active at inference, optimized for coding and instruction-following, and uses a 3:1 hybrid ratio of […]
-
Qwen3-Coder-Next: Alibaba’s Ultra-Sparse 80B Coding Agent
Key points Alibaba’s Qwen team released Qwen3-Coder-Next in February 2026 under the Apache 2.0 license, an open-weight coding model that activates only 3 billion of its 80 billion total parameters per forward pass. On SWE-Bench Verified with the SWE-Agent scaffold the model scores 70.6%, and it also scores 62.8% on SWE-Bench Multilingual and 44.3% on […]
-
GLM-4.7-Flash: Z.ai’s Efficient 30B MoE Model for Coding and Agents
Key points Z.ai released GLM-4.7-Flash on January 20, 2026, a fully open-source model under the MIT license that is available for free via the Z.ai API platform. Despite its 30B label, the model uses a Mixture-of-Experts architecture with 31.2 billion total parameters but only approximately 3 billion active parameters during any given inference pass. It […]