Tag: PrismML
-
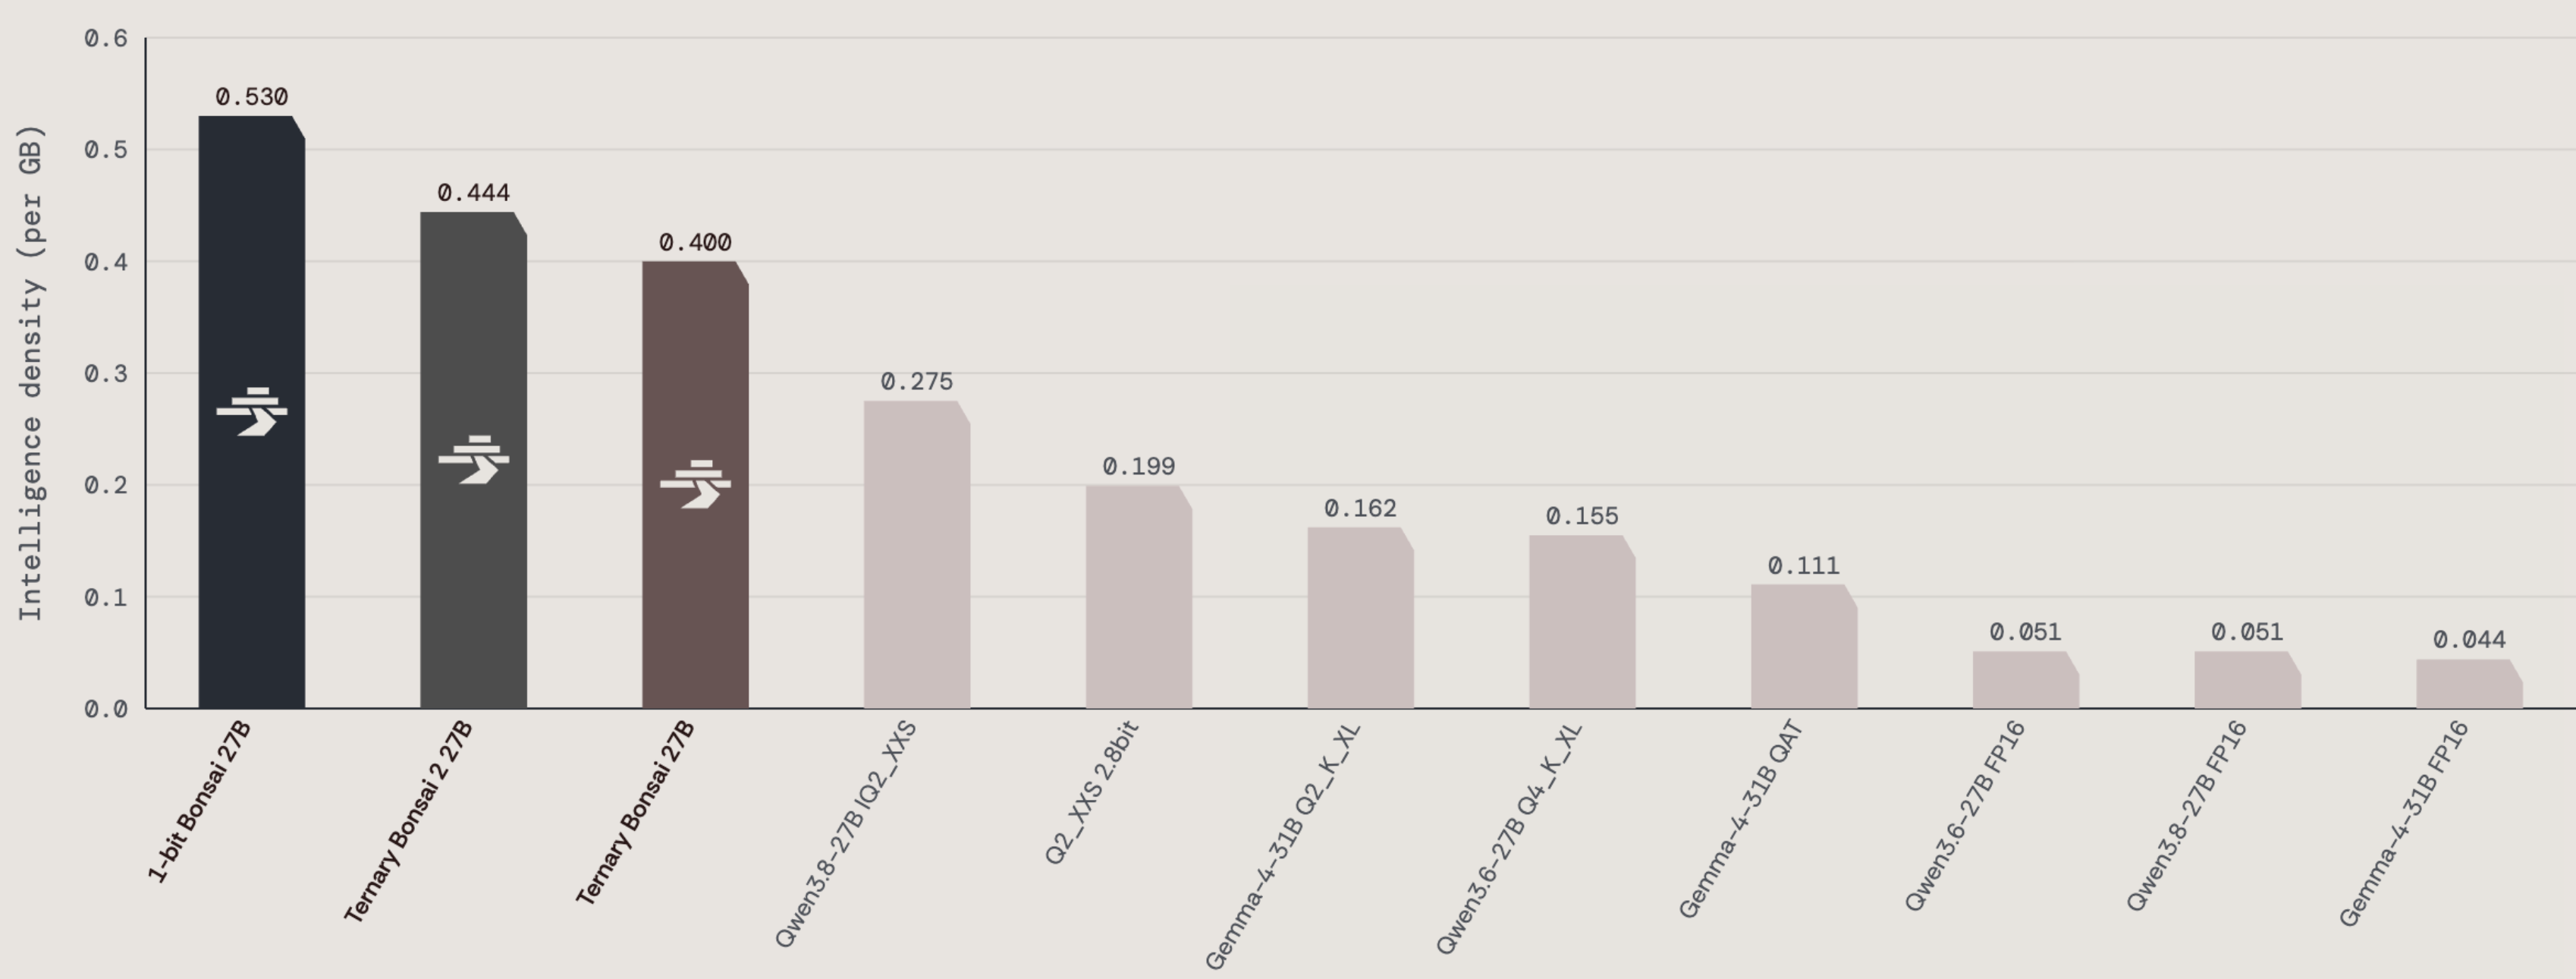
Bonsai 2 27B: Qwen3.8 in 5.9 GB at 98% of Full Precision
On September 17, 2026, PrismML released Ternary Bonsai 2 27B — a 1.76-bit-per-weight build of Alibaba’s Qwen3.8-27B that fits in 5.93 GB and, on the company’s 20-benchmark suite, keeps 98.2% of the full-precision model’s score. July’s Ternary Bonsai 27B, built on the older Qwen3.6 base, retained about 95%. The new build ships under Apache 2.0 […]
-
Bonsai 27B: A 27B-Class AI Model That Runs on a Phone
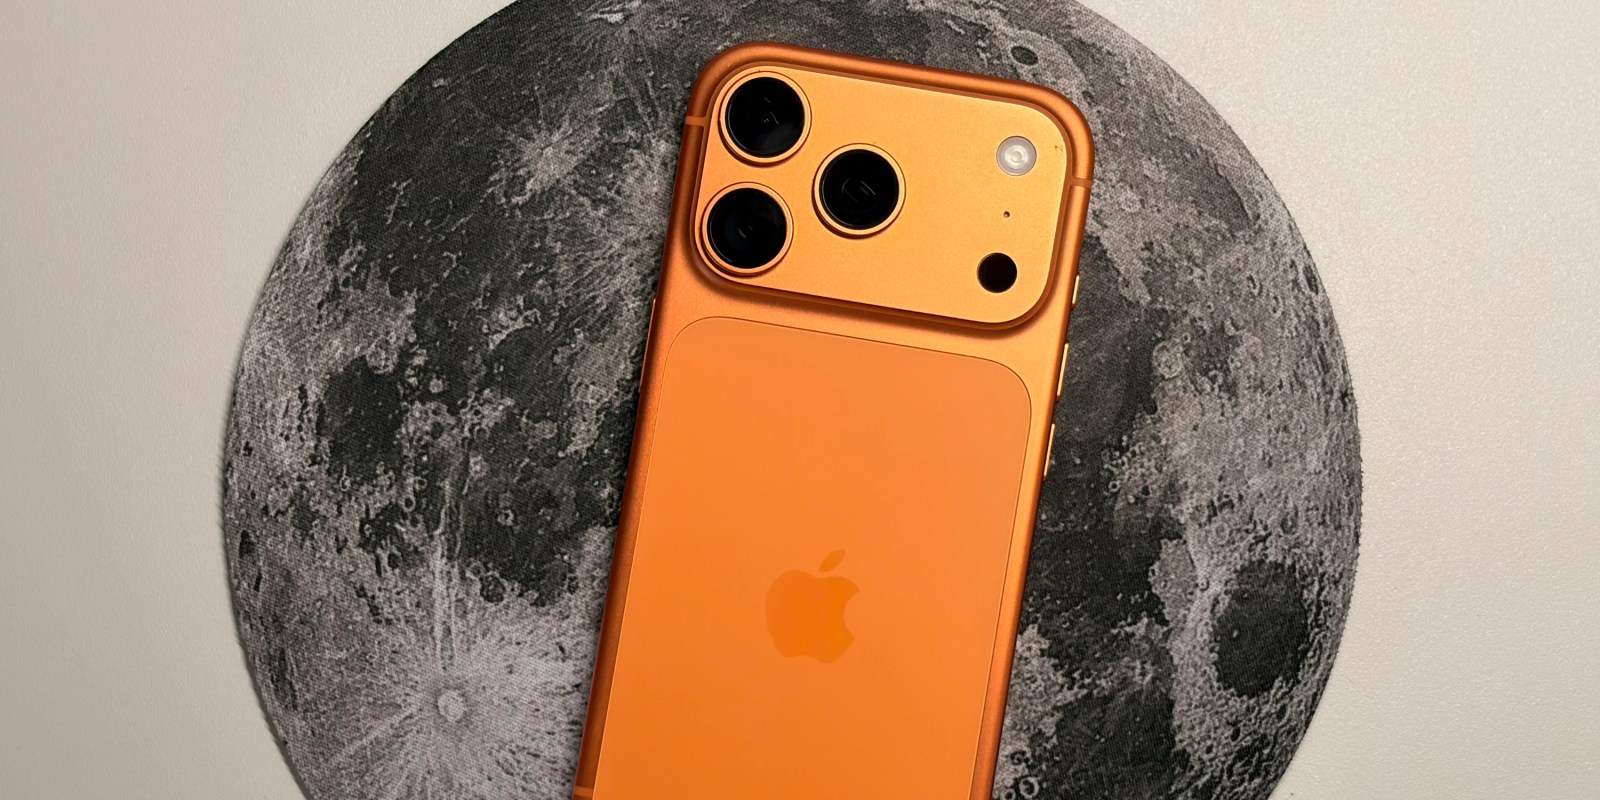
On July 14, 2026, PrismML released Bonsai 27B — a pair of extreme-quantization builds of Alibaba’s Qwen3.6-27B that the company calls the first 27B-class model capable of running on a phone. The 1-bit variant fits in 3.9 GB and runs on an iPhone 17 Pro, while a higher-quality ternary variant fits in 5.9 GB for […]
-
PrismML Releases 1-Bit Bonsai Image 4B for Local Generation
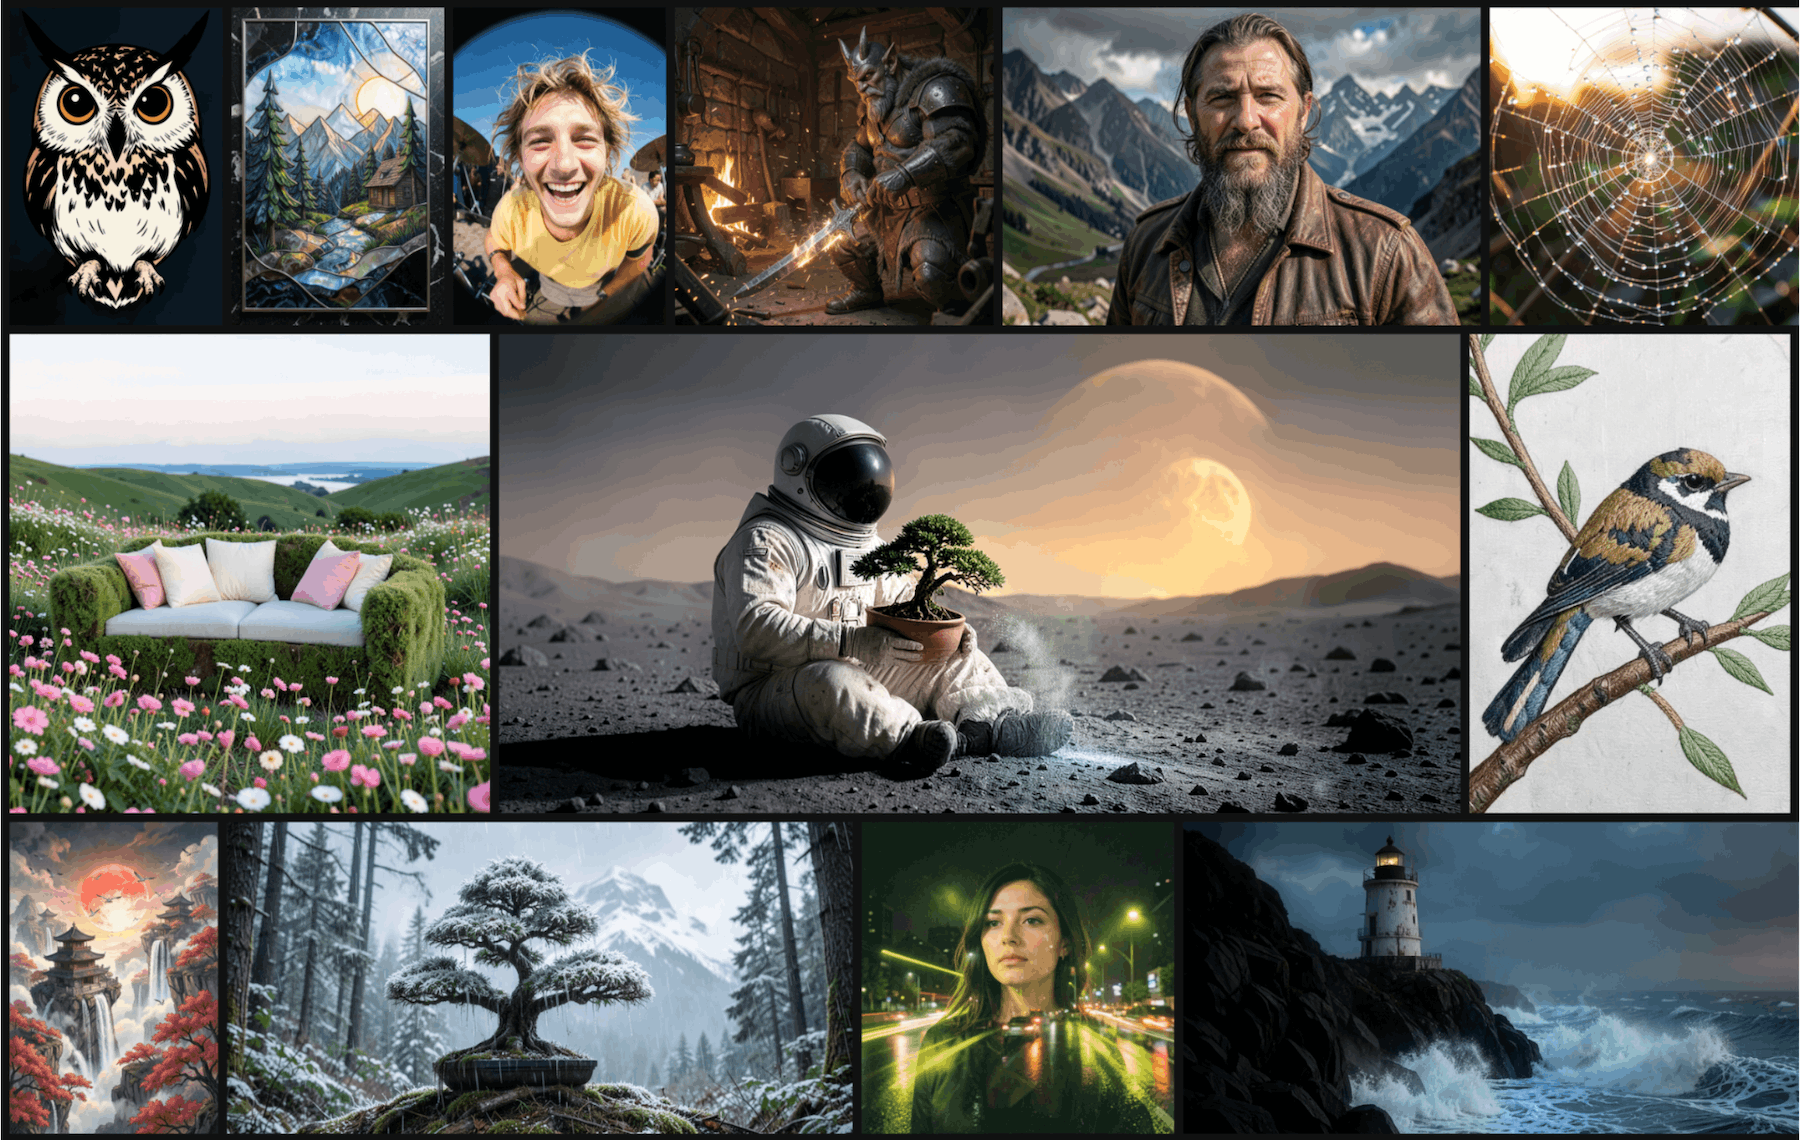
PrismML released Bonsai Image 4B, a 1-bit and ternary text-to-image diffusion transformer family, extending the company’s Bonsai quantization push from language models into image generation. The notable claim is local accessibility: PrismML says the models are small enough to run fully in a browser through WebGPU while still producing competitive text-to-image outputs. Intermediate Key points […]