Tag: quantization
-
Meta Opens Muse Spark Weights: 816B MoE, 1M Context
On October 15, 2026, Meta Superintelligence Labs released the weights for Muse Spark Open — an 816-billion-parameter sparse mixture-of-experts model that activates 42 billion parameters per token, with a 1,048,576-token context window. Meta calls it “the most capable US open-weight model to date,” and the release is as much a hardware story as a benchmark […]
-
LittleBit-2: Samsung’s Sub-1-Bit LLMs via Latent Geometry Alignment
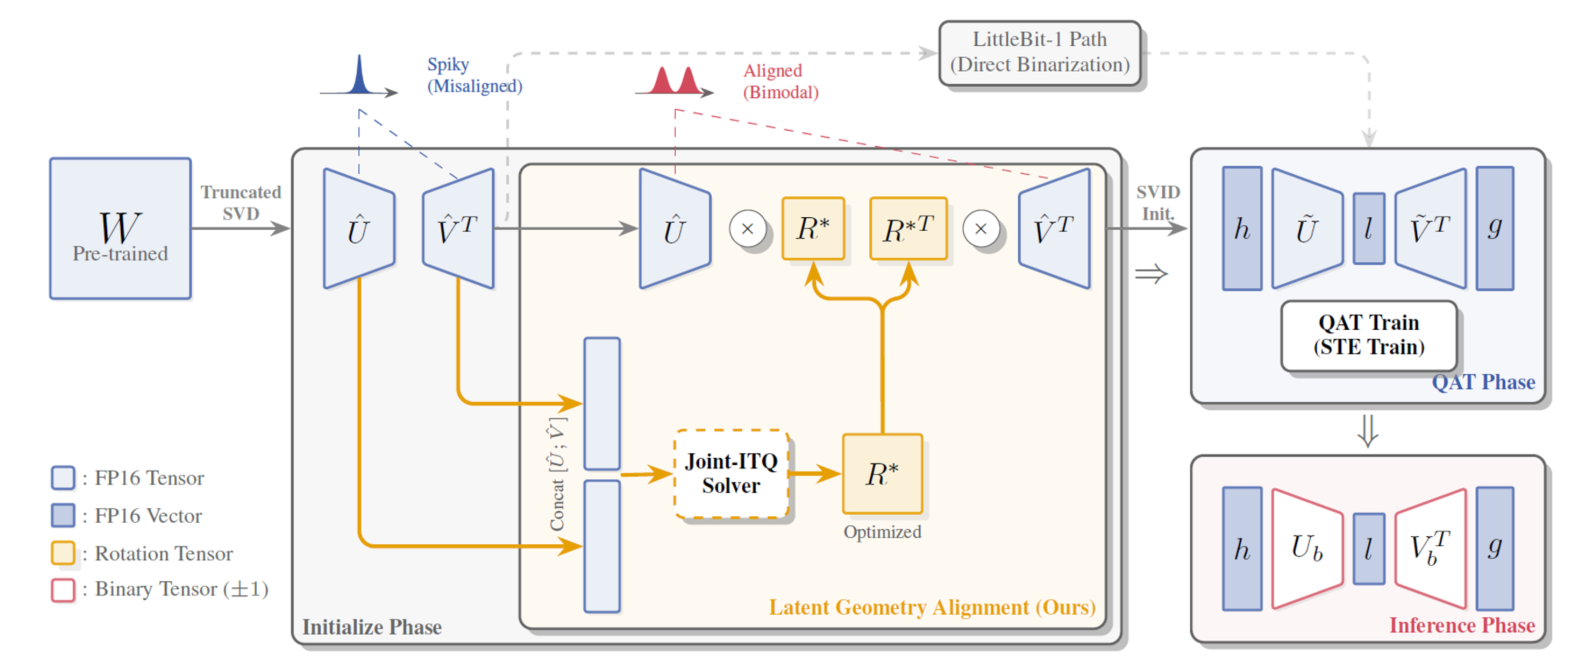
Lead — On July 23, 2026, Samsung Research published LittleBit-2, the successor to a compression method that pushes large language models below one bit per weight. Presented at ICML 2026, LittleBit-2 keeps the original LittleBit architecture from NeurIPS 2025 but changes one thing: how the compressed weights are initialized. That single change takes the method […]
-
Bonsai 2 27B: Qwen3.8 in 5.9 GB at 98% of Full Precision
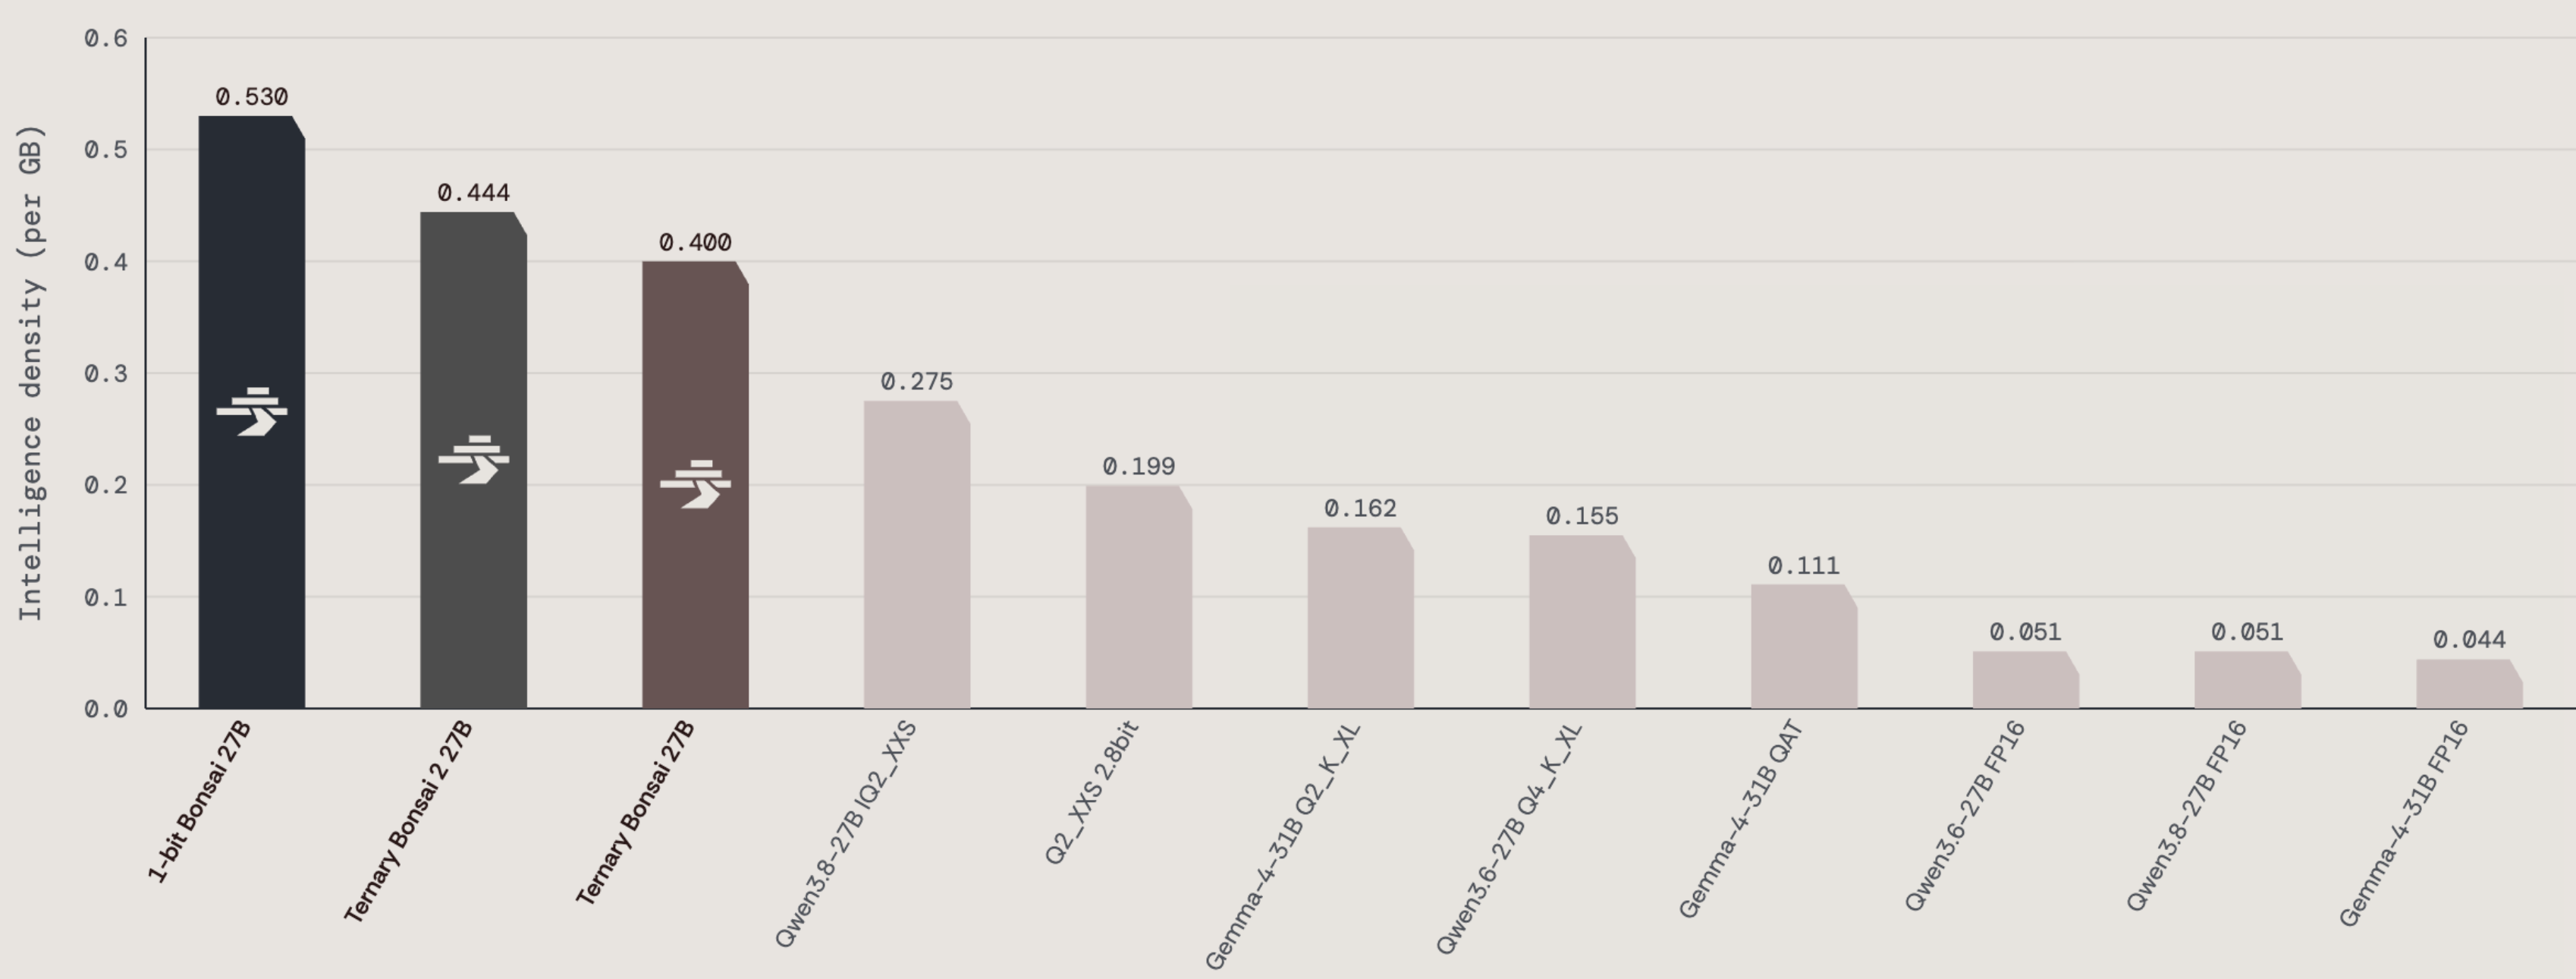
On September 17, 2026, PrismML released Ternary Bonsai 2 27B — a 1.76-bit-per-weight build of Alibaba’s Qwen3.8-27B that fits in 5.93 GB and, on the company’s 20-benchmark suite, keeps 98.2% of the full-precision model’s score. July’s Ternary Bonsai 27B, built on the older Qwen3.6 base, retained about 95%. The new build ships under Apache 2.0 […]
-
MiniMax Ships H3 Weights — With the US and EU Excluded
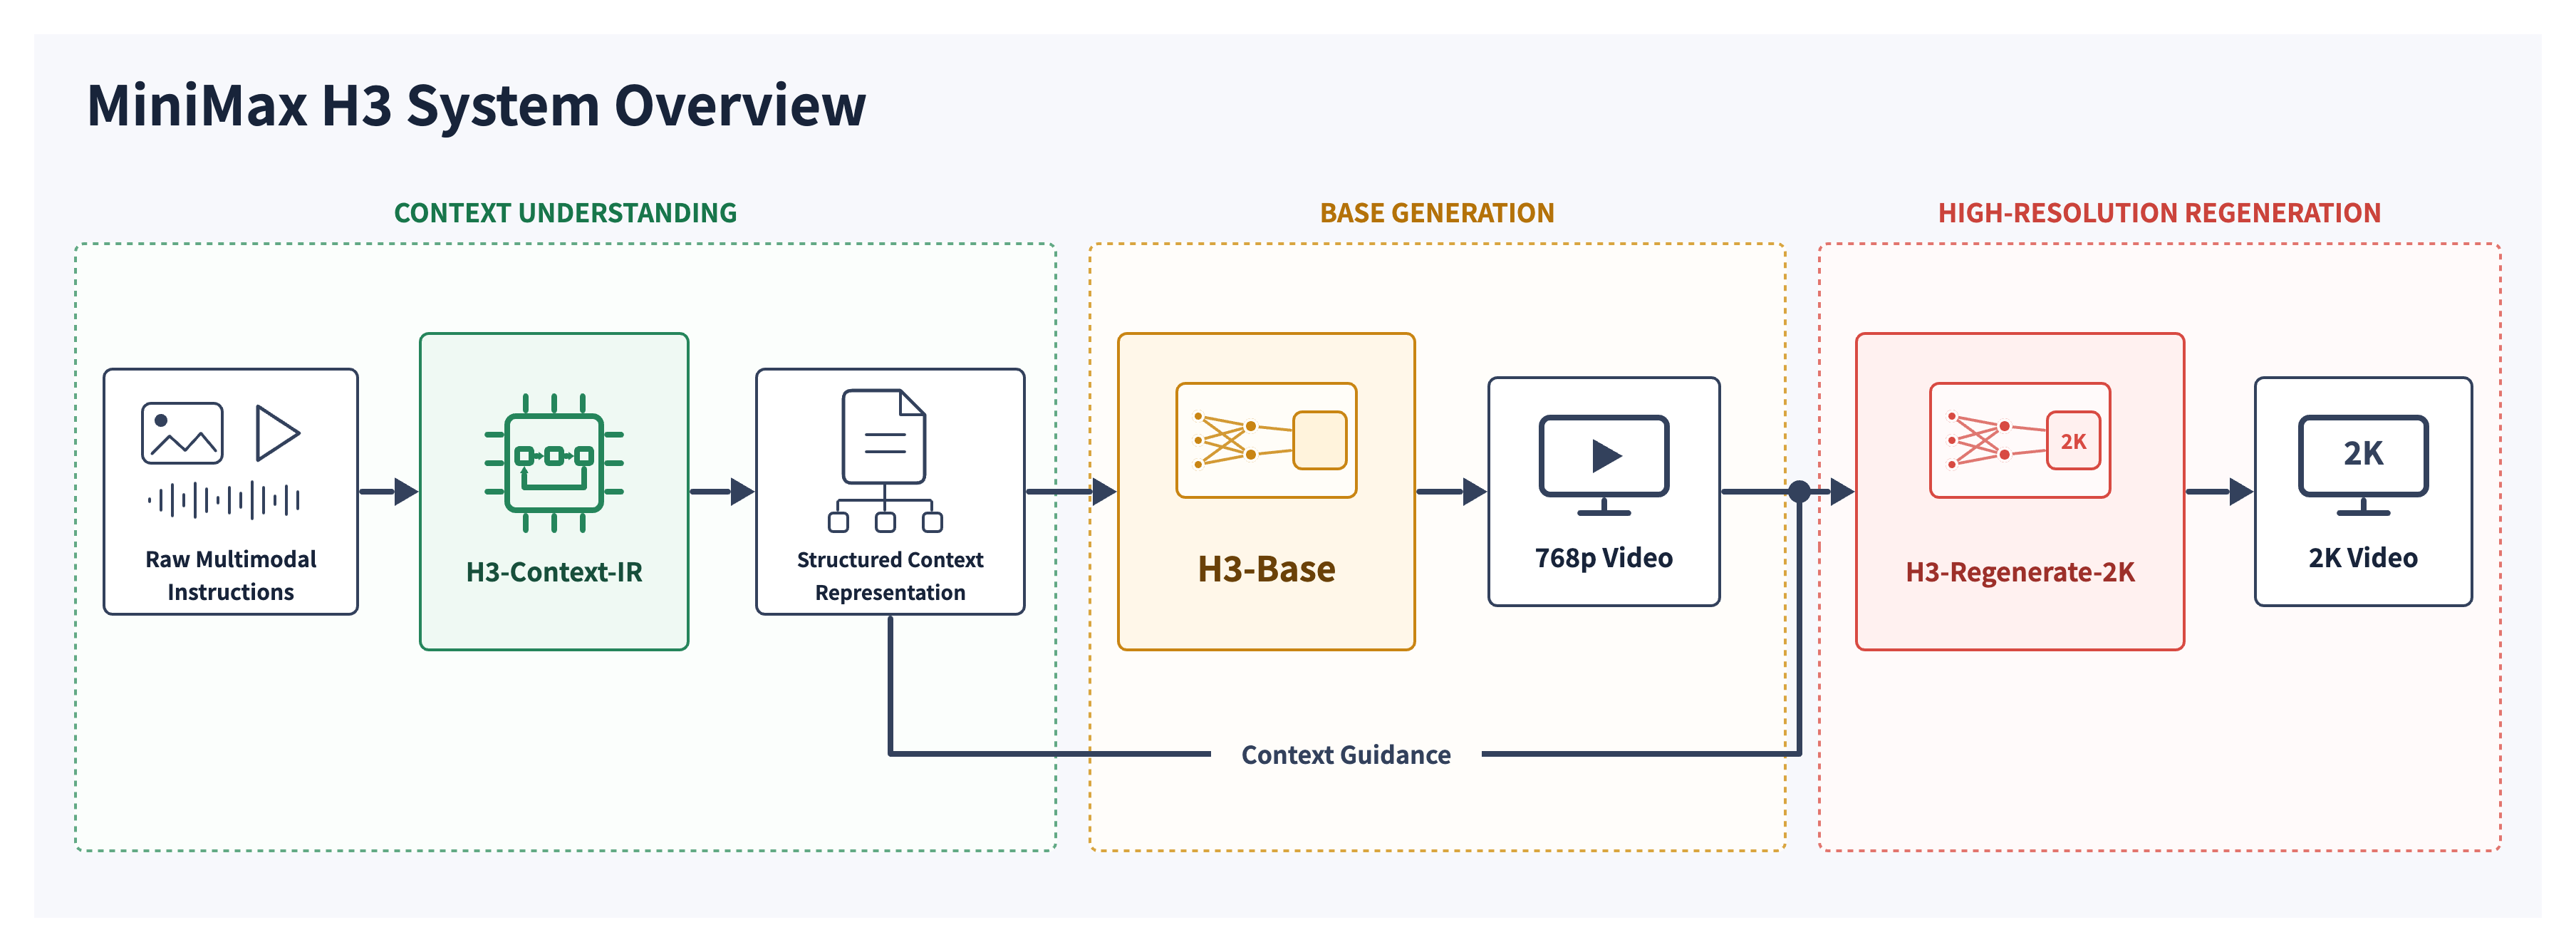
MiniMax published the MiniMax-H3 weights to Hugging Face on August 3, 2026 — three days after announcing the omni-modal video model and promising an open release “in the coming days.” The checkpoints are real, the quantized build is small enough to matter, and ComfyUI shipped day-0 support. But the accompanying MiniMax H3 Community License carves […]
-
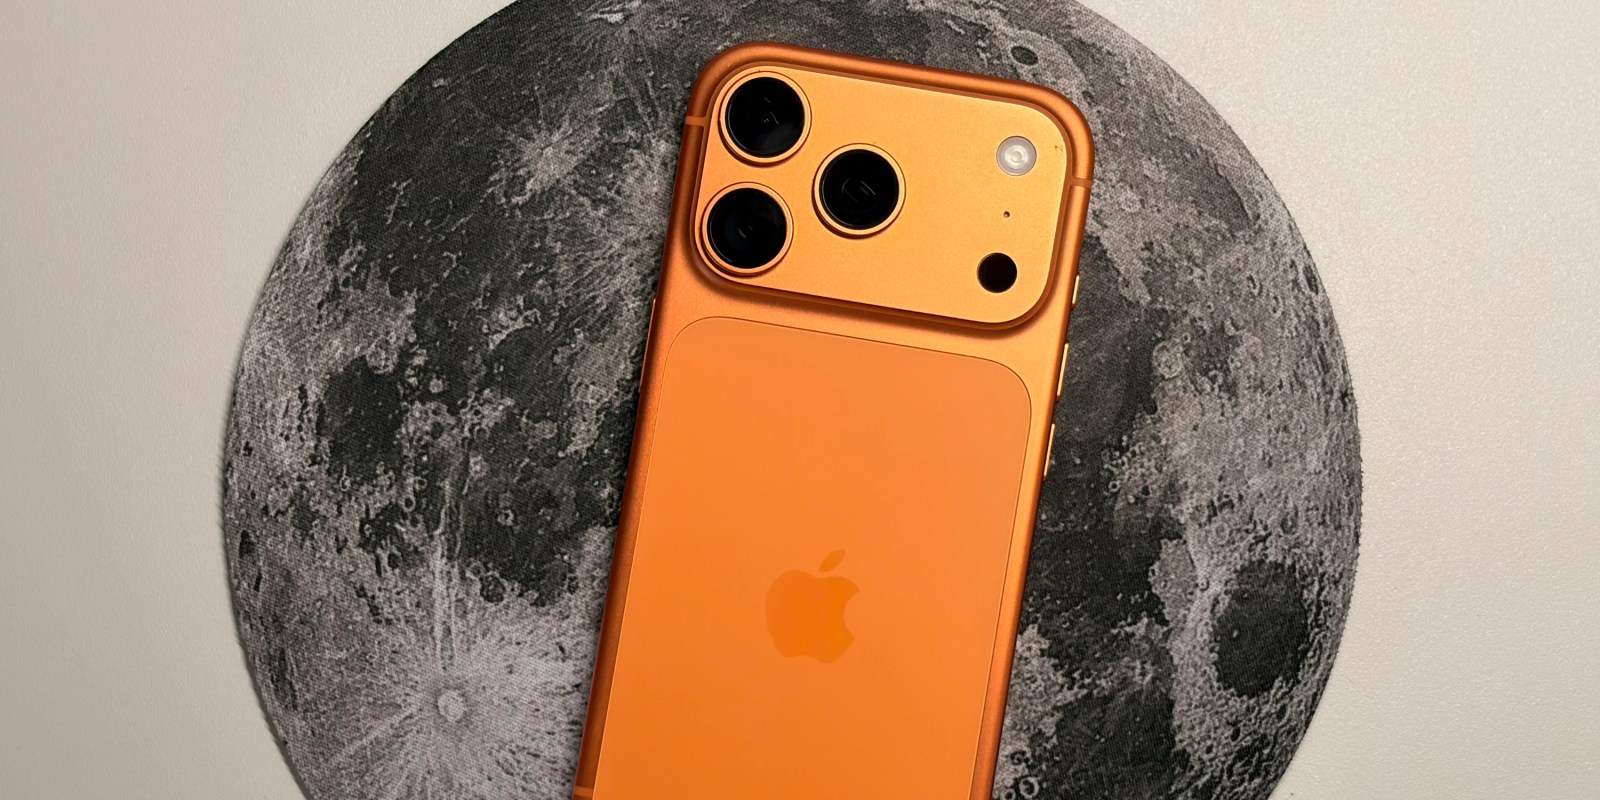
Bonsai 27B: A 27B-Class AI Model That Runs on a Phone
On July 14, 2026, PrismML released Bonsai 27B — a pair of extreme-quantization builds of Alibaba’s Qwen3.6-27B that the company calls the first 27B-class model capable of running on a phone. The 1-bit variant fits in 3.9 GB and runs on an iPhone 17 Pro, while a higher-quality ternary variant fits in 5.9 GB for […]
-
Google Ships Gemma 4 QAT Models: 72% Less VRAM, Same Quality
Lead — On June 5, 2026, Google DeepMind released quantization-aware training (QAT) checkpoints for the entire Gemma 4 family, cutting memory requirements by roughly 72% while keeping output quality nearly identical to the full-precision models. The release spans every size — from the sub-1 GB E2B edge model to the 31B dense flagship — and […]
-
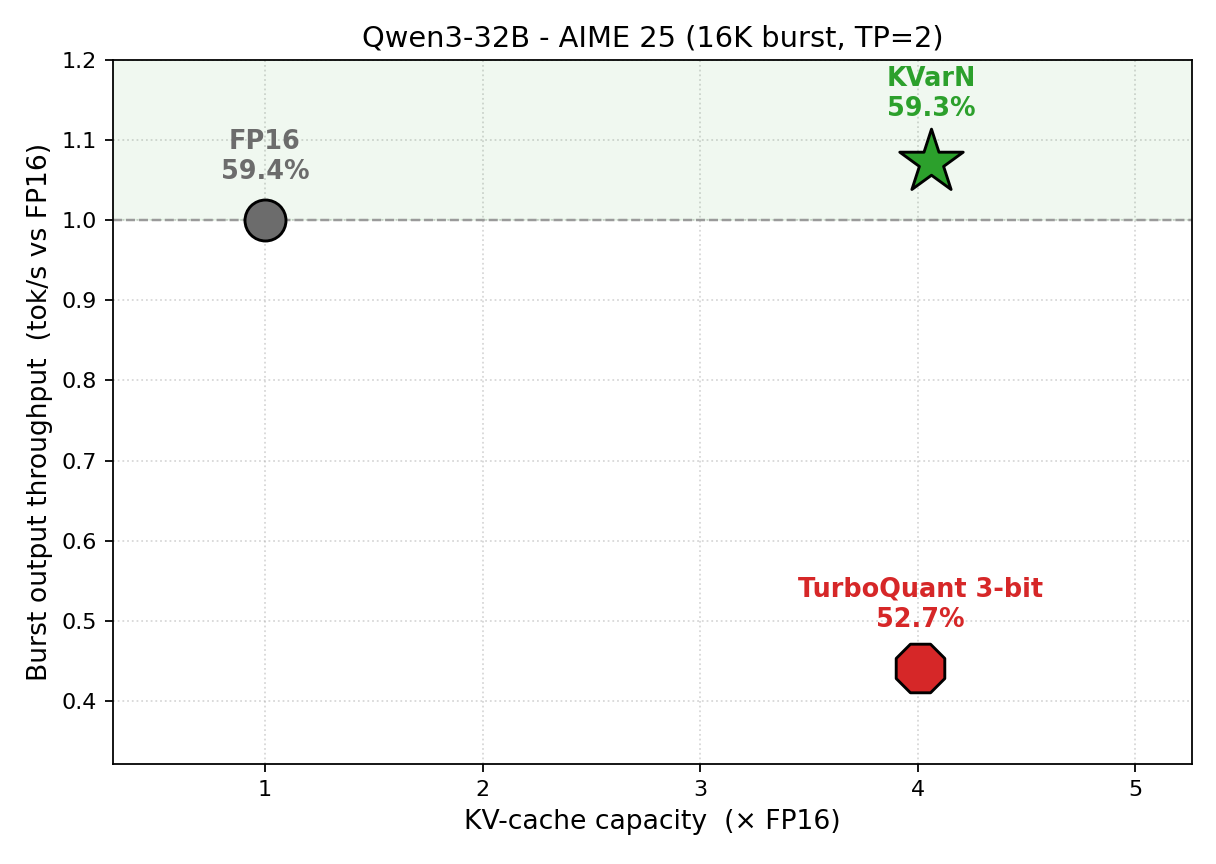
Huawei’s KVarN Hits 5x KV-Cache Capacity at FP16 Accuracy and Throughput
On June 2, 2026, Huawei researchers released KVarN — a variance-normalized KV-cache quantization backend for vLLM that breaks the long-standing tradeoff between cache compression and inference speed. KVarN delivers 3–5× more context capacity at 2-bit precision while keeping FP16-level accuracy and beating FP16 throughput, all behind a single vLLM flag with no calibration. It ships […]
-
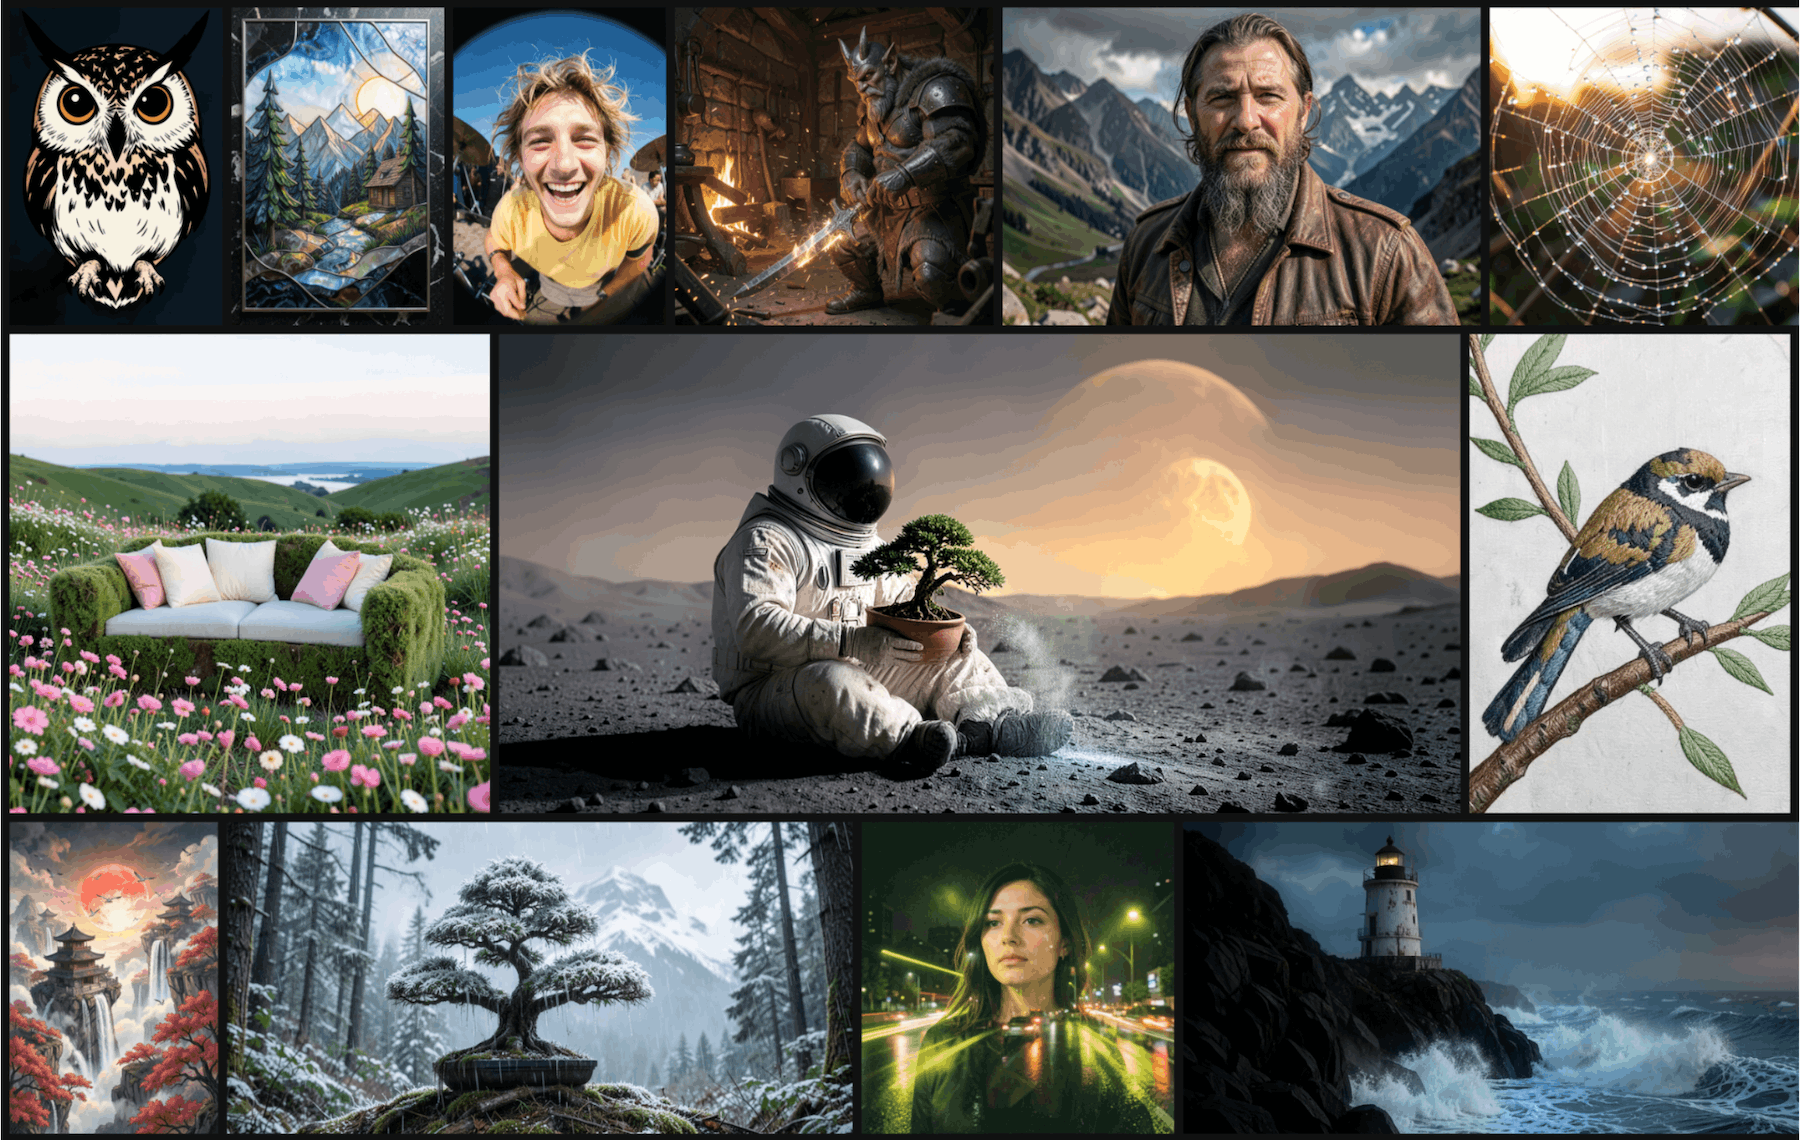
PrismML Releases 1-Bit Bonsai Image 4B for Local Generation
PrismML released Bonsai Image 4B, a 1-bit and ternary text-to-image diffusion transformer family, extending the company’s Bonsai quantization push from language models into image generation. The notable claim is local accessibility: PrismML says the models are small enough to run fully in a browser through WebGPU while still producing competitive text-to-image outputs. Intermediate Key points […]
-
Bankai: Kilobyte-Scale Patches for 1-Bit LLMs via XOR Adaptation
Bankai is the first post-training adaptation method for true 1-bit large language models. Released on April 2, 2026, it uses bitwise XOR operations on binary weights to create kilobyte-scale patches that modify model behavior with zero inference overhead. Where LoRA adapters weigh ~100 MB each, a Bankai patch compresses to roughly 1 KB — and […]
-
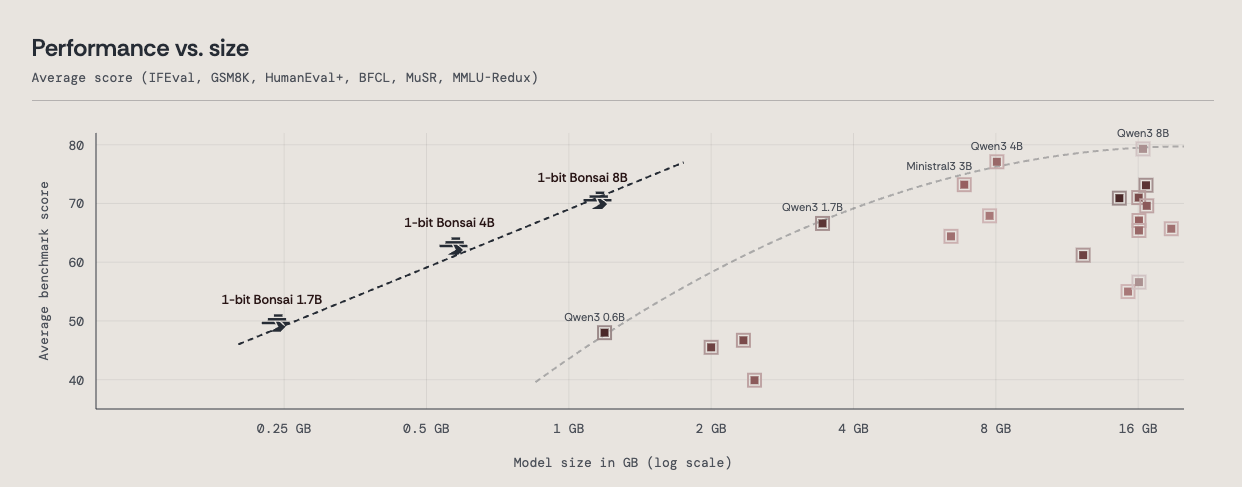
PrismML’s 1-Bit Bonsai LLMs: 8B Model in 1.15 GB
On March 31, 2026, PrismML emerged from stealth to announce 1-bit Bonsai — a family of open-weight language models the company calls the first commercially viable 1-bit LLMs. The 8B flagship fits in just 1.15 GB of memory, runs 8× faster than a standard FP16 8B model, and matches its benchmark performance. Backed by $16.25M […]