Tag: qwen
-
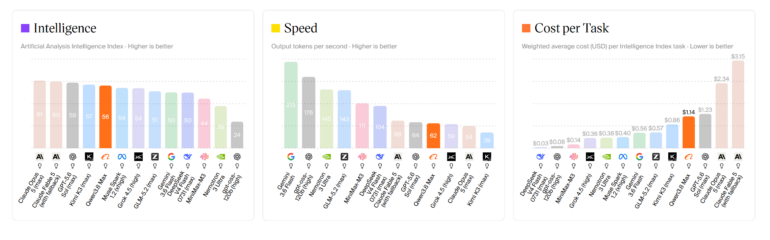
Qwen3.8-Max Draws Level With the Frontier on Agentic Benchmarks
Alibaba released Qwen3.8-Max on August 3, 2026, and within days independent evaluation put it level with the frontier on agentic work. On Artificial Analysis’ Agentic Index, the 2.4-trillion-parameter model scores 58 — tied with Claude Opus 5 running at xhigh effort, and one point behind Opus 5 at max effort, which still holds the top […]
-
NInfer: 700 tok/s on One RTX 5090, With a Rare Honest Audit
NInfer is a from-scratch C++/CUDA inference engine that runs exactly two model checkpoints on exactly one GPU. Published under Apache 2.0 and first committed on June 26, 2026, the project by developer Neroued supports only Qwen3.6-27B and Qwen3.6-35B-A3B, only on an NVIDIA GeForce RTX 5090, and only one request at a time. In return for […]
-
Qwen-Image-3.0: 4.5k-Token Prompts, No Benchmarks, No Weights
Alibaba’s Qwen team launched Qwen-Image-3.0 on July 21, 2026 — the third generation of its image-generation model, built around a single claim: that generated images can now be useful, not just good-looking. The headline capability is a jump to 4.5k-token prompts, roughly 4.5× the instruction length its predecessors accepted, which the team says lets the […]
-
Qwen3.8-Max Preview: Alibaba’s 2.4T-Parameter Bid for the Frontier
Alibaba’s Qwen team announced Qwen3.8-Max-Preview on July 19, 2026 — a 2.4 trillion-parameter multimodal model the team calls its most capable system yet, claiming performance “second only to Fable 5” among the models it evaluated. The preview landed just two days after Moonshot AI’s 2.8 trillion-parameter Kimi K3 open-weight release, underscoring how quickly China’s frontier […]
-
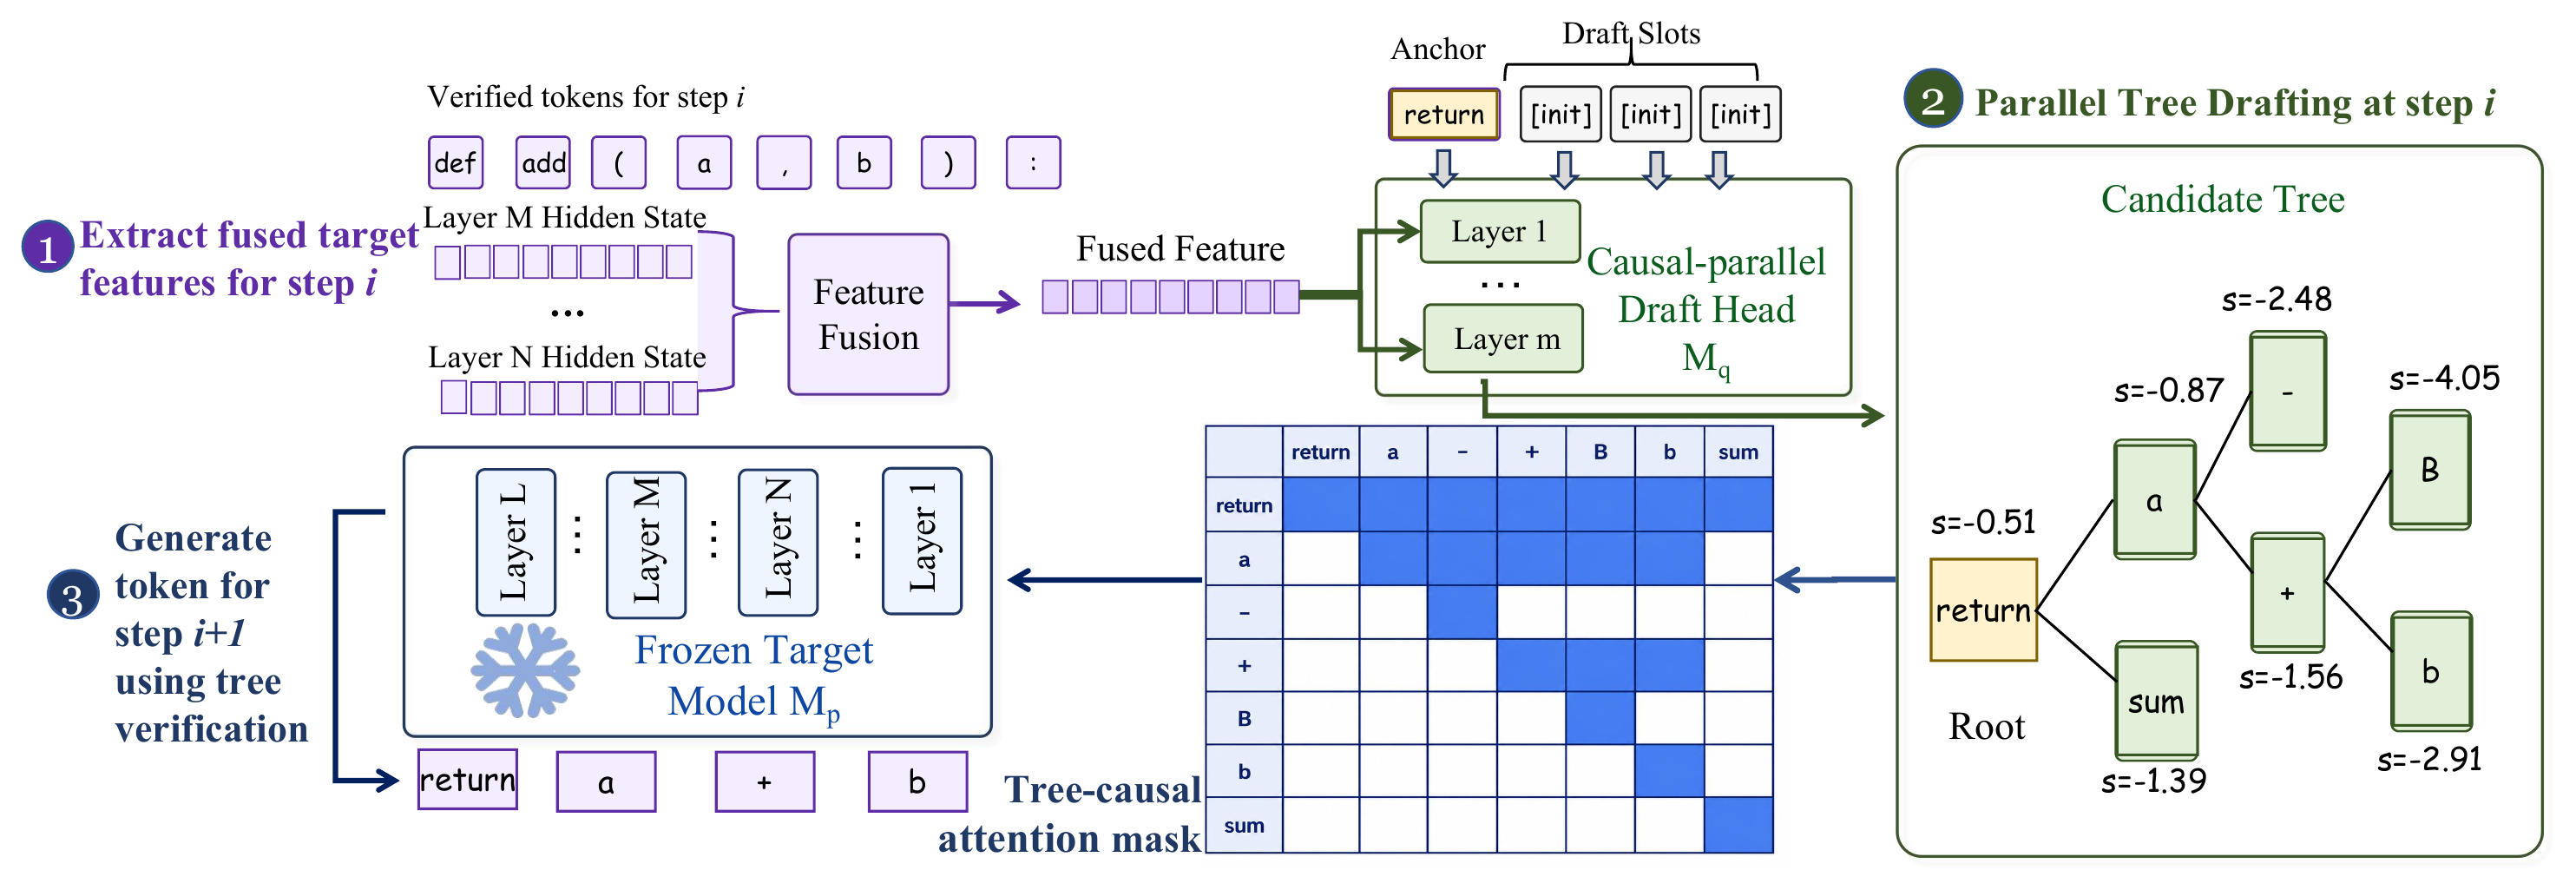
JetSpec: Causal Parallel Tree Drafting Hits 9.64x Faster LLM Inference
On June 26, 2026, researchers at UC San Diego’s Hao AI Lab released JetSpec — a speculative decoding method that accelerates large language model inference by up to 9.64× while leaving the model’s outputs unchanged. JetSpec trains a small “causal parallel draft head” on top of a frozen target model, generating a scored tree of […]
-
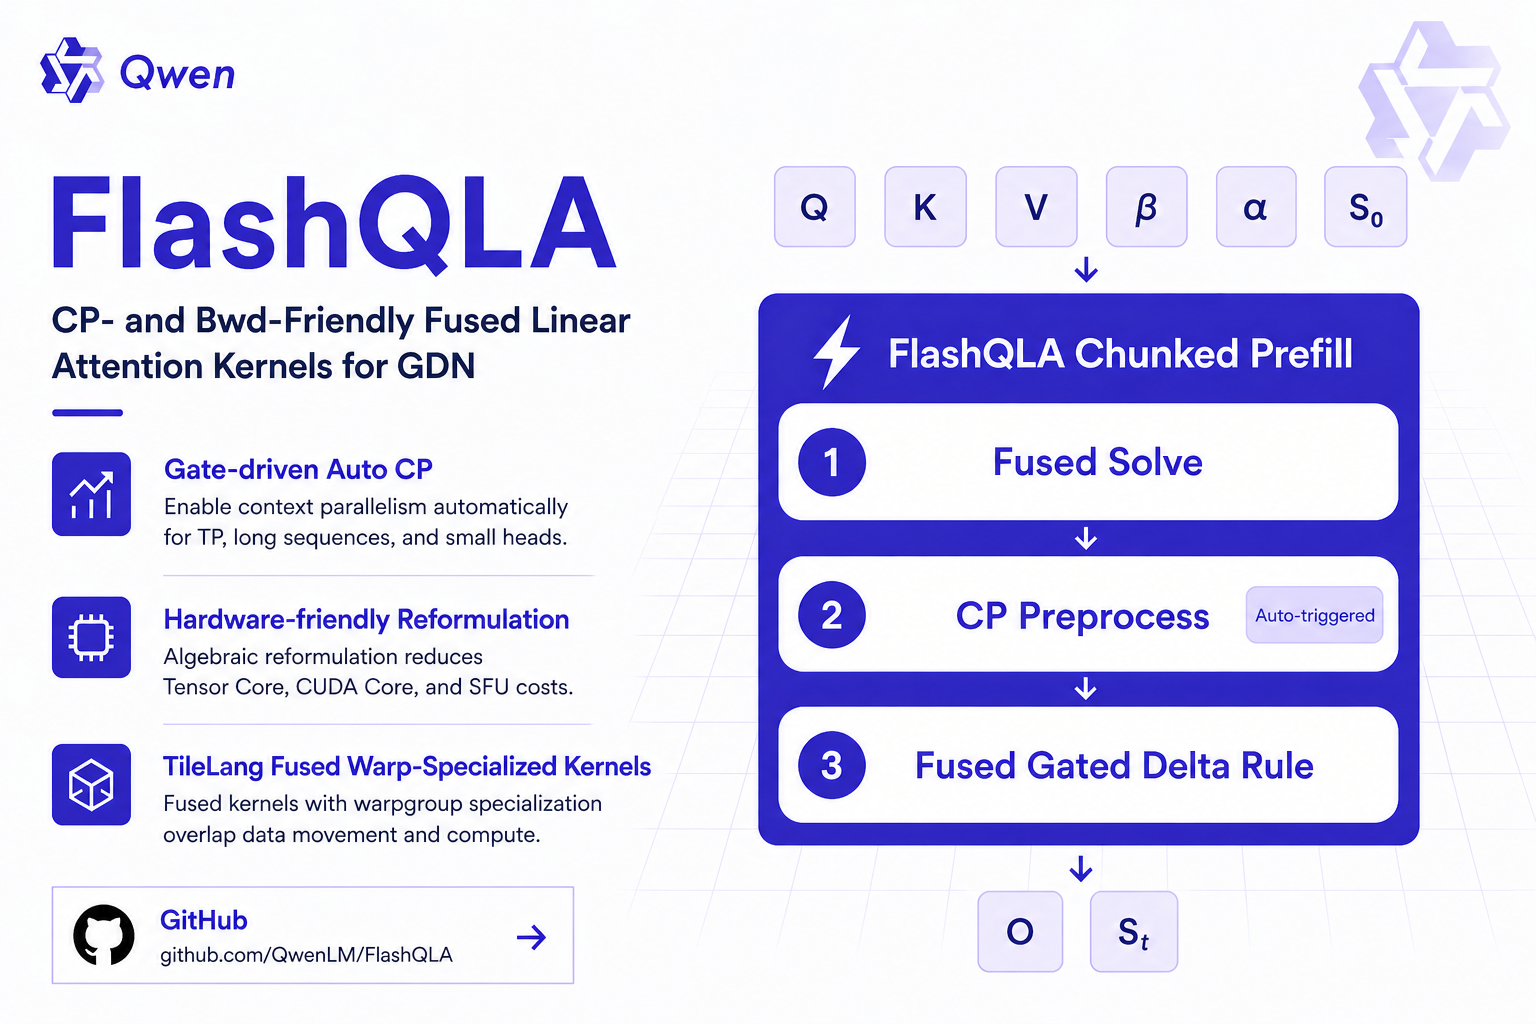
Qwen Releases FlashQLA: 2-3x Faster Linear Attention Kernels on Hopper
Qwen has open-sourced FlashQLA, a high-performance linear attention kernel library built on TileLang that targets the GDN (Gated Delta Network) Chunked Prefill workload. Released in late April 2026 under the MIT License, FlashQLA reports a 2–3× forward-pass speedup and roughly 2× backward-pass speedup over the FLA Triton kernels, and roughly 2× over FlashInfer 0.6.9 on […]
-
Luce DFlash Brings 2x Speculative Decoding to Qwen3.6-27B on a Single RTX 3090
Luce DFlash now runs Qwen3.6-27B on a single RTX 3090, delivering up to 2× throughput over autoregressive decoding. The Lucebox Hub project, which hand-tunes LLM inference for specific consumer GPUs, ported its DFlash speculative decoding stack to Qwen3.6-27B in late April 2026. Because Qwen3.6-27B reuses the Qwen3.5 architecture string with identical layer and head dimensions, […]
-
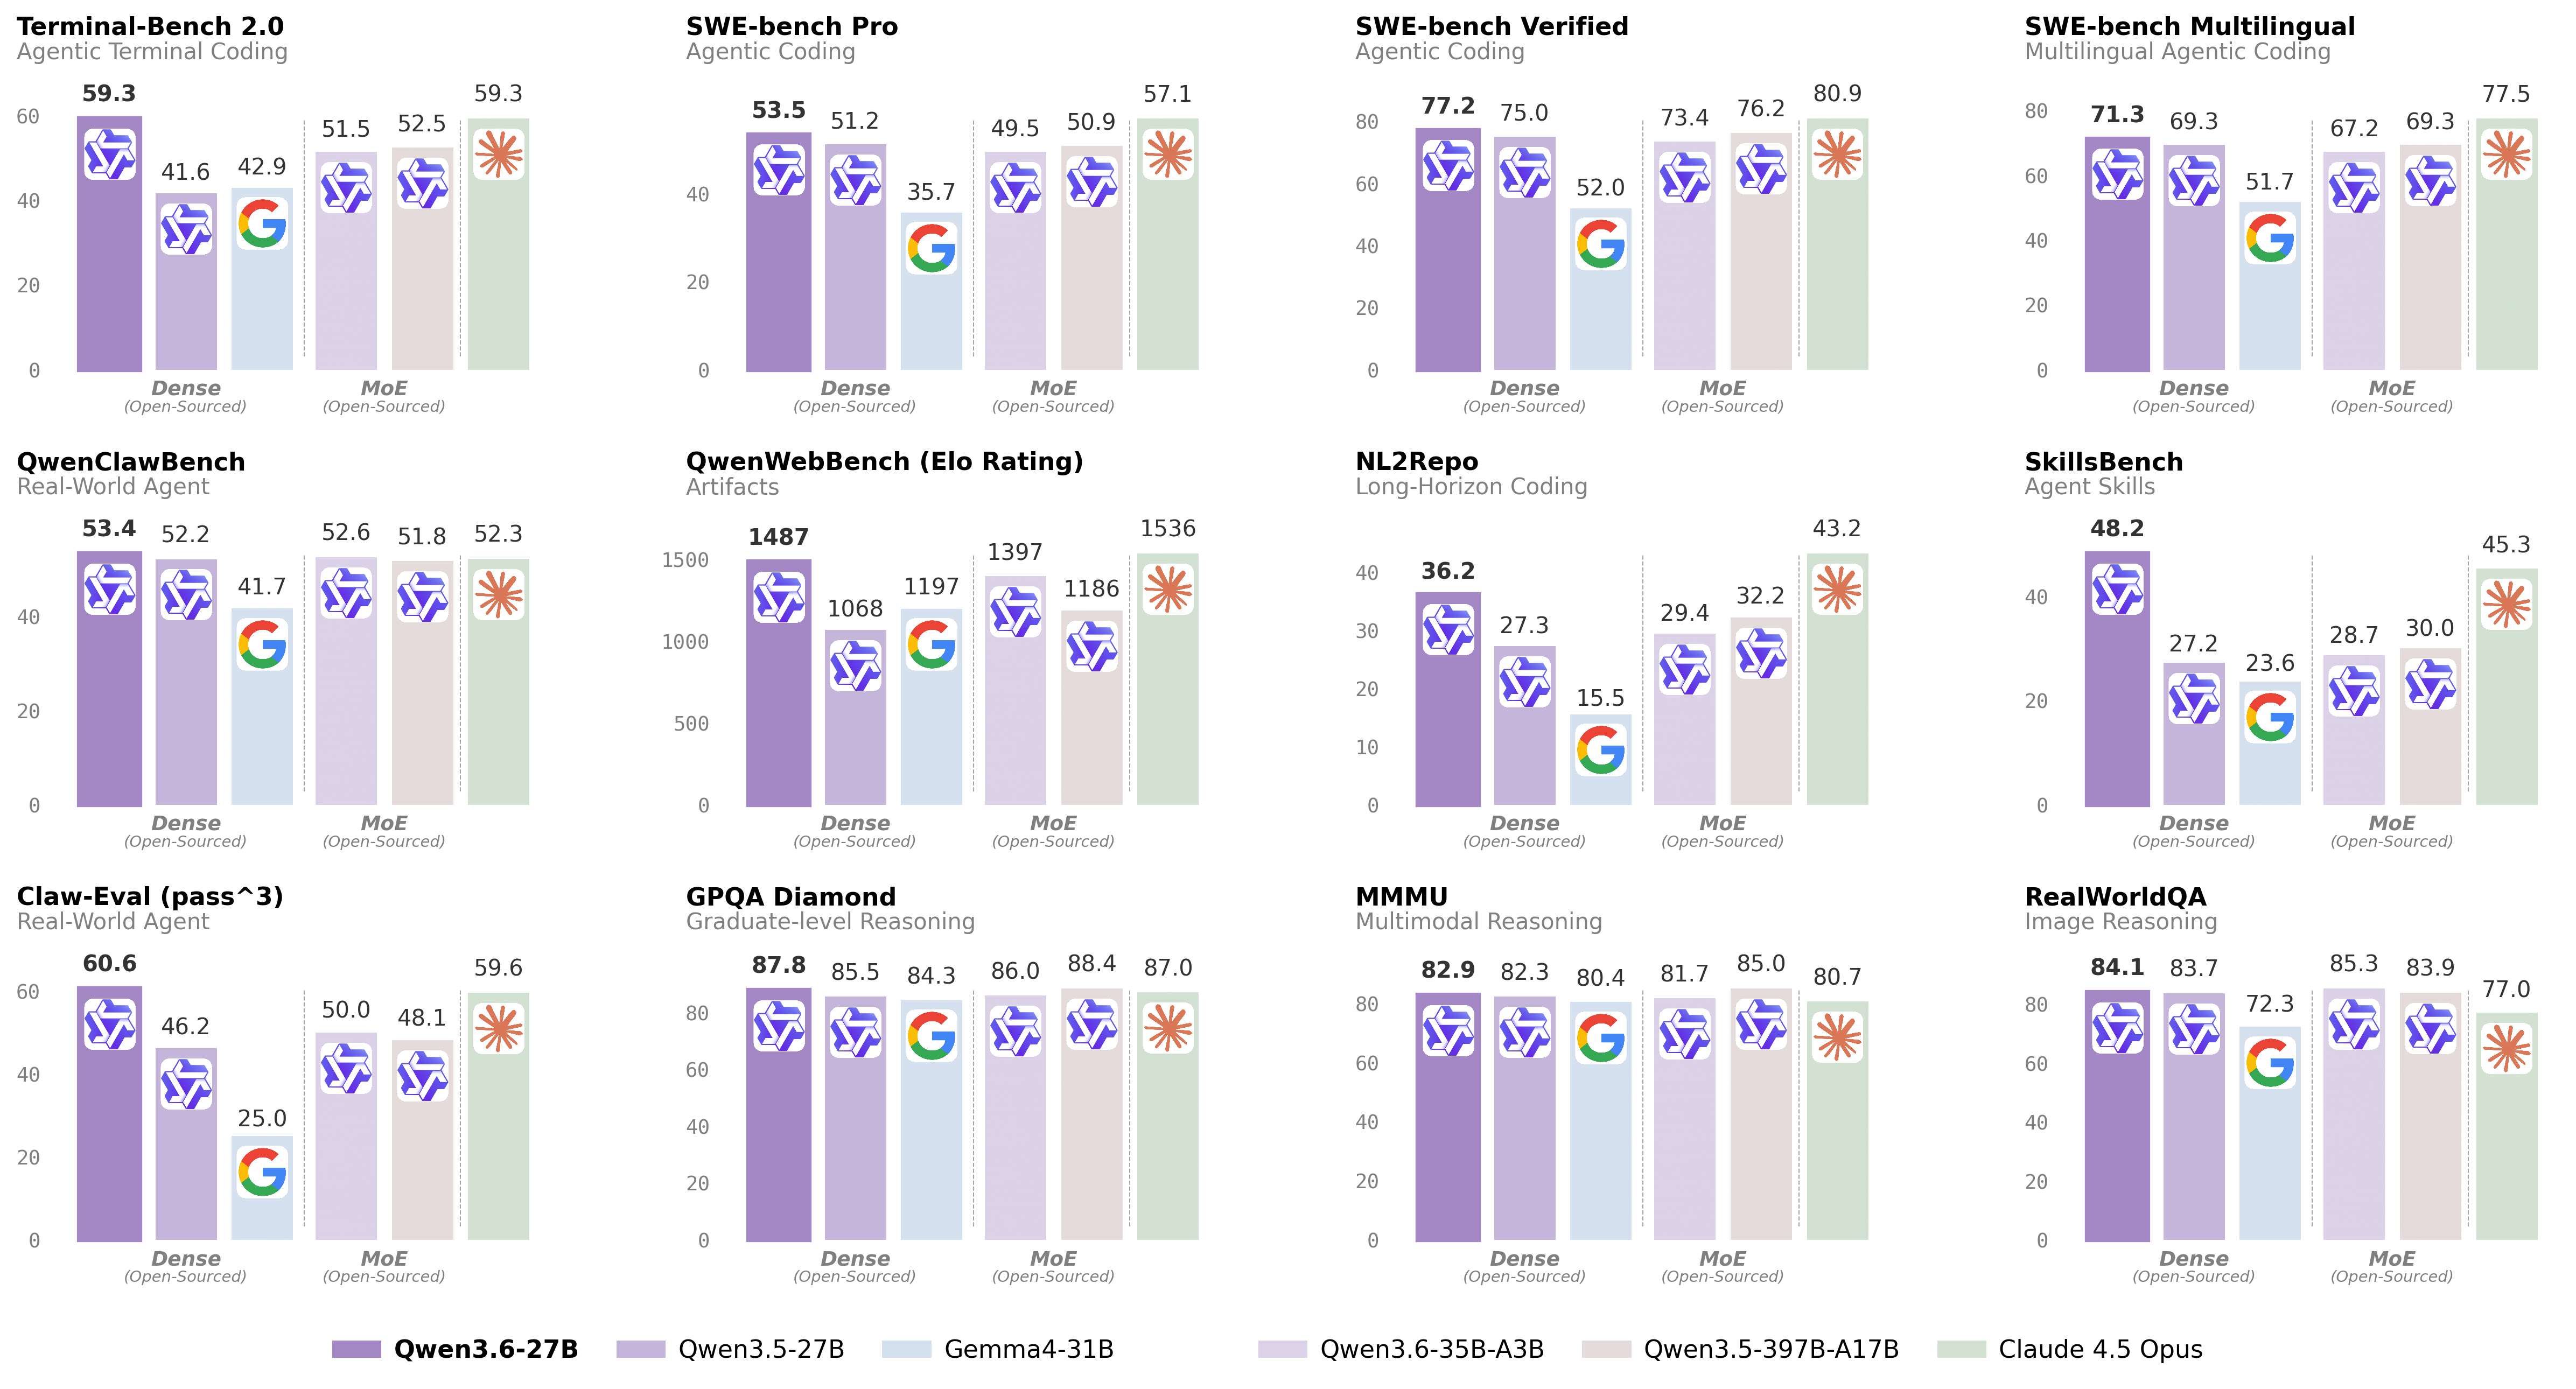
Qwen3.6-27B: A Dense 27B Model That Beats a 397B MoE on Coding
On April 22, 2026, Alibaba’s Qwen team released Qwen3.6-27B — the first dense open-weight model in the Qwen3.6 generation. Released under Apache 2.0 on Hugging Face, the 27-billion-parameter multimodal model posts flagship-level agentic coding scores that beat the team’s previous-generation 397B Mixture-of-Experts flagship across multiple benchmarks, while fitting into a 16.8 GB Q4_K_M quantization that runs […]
-
Qwen3.6-35B-A3B: Alibaba Open-Sources a Frontier-Class Agentic Coder
On April 2, 2026, Alibaba’s Qwen team open-sourced Qwen3.6-35B-A3B — the first open-weight variant of the Qwen3.6 generation. Released under Apache 2.0 on Hugging Face alongside the proprietary Qwen3.6-Plus API model, the 35-billion-parameter Mixture-of-Experts model activates just 3B parameters per token while posting frontier-level scores on agentic coding and reasoning benchmarks, including 73.4 on SWE-bench […]
-
CoPaw-Flash-9B: Alibaba’s Agentic Fine-Tune of Qwen3.5-9B
On March 30, 2026, Alibaba’s AgentScope team formally released CoPaw v1.0.0 — a personal AI agent workstation built around CoPaw-Flash-9B, an agentic fine-tune of Qwen3.5-9B. The model and the broader CoPaw framework are fully open-sourced under the AgentScope organization on Hugging Face and GitHub, positioning CoPaw as a lightweight, locally-runnable alternative to cloud-only AI agent […]