Tag: reinforcement learning
-
Qwen Releases QwenGyre for Long-Horizon Agent RL Training
Alibaba’s Qwen team has detailed QwenGyre — an elastic reinforcement learning (RL) framework for training AI agents on what the authors call “extreme-long” (xLong) tasks, where a single execution spans hours, hundreds of model–environment interactions, and close to one million tokens. The paper, submitted to arXiv on September 27, 2026 and announced by the Qwen […]
-
Xiaomi Open-Sources MiMo-V2.6 Pro and Flash, Plus Its RL Stack
Xiaomi has released the weights of MiMo-V2.6-Pro and MiMo-V2.6-Flash under the MIT licence, one week after it began streaming their reinforcement learning (RL) runs on a public dashboard. The two checkpoints went up on Hugging Face on September 21, 2026 (UTC), and Xiaomi’s official announcement is dated September 22. Pro is a 1.02-trillion-parameter Mixture-of-Experts (MoE) […]
-
Xiaomi Streams MiMo-V2.6 Reinforcement Learning Runs Live
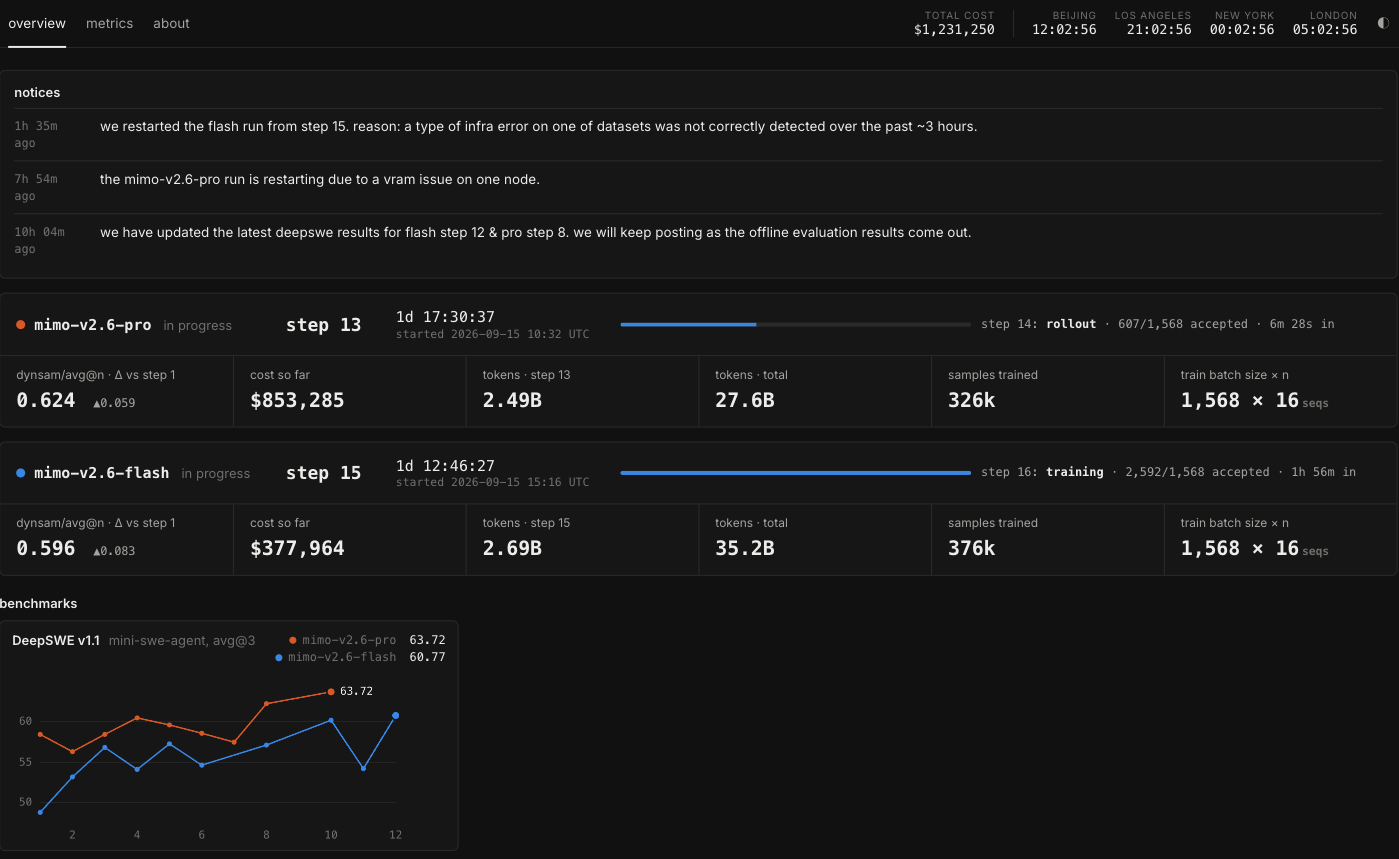
Xiaomi’s MiMo team is running the reinforcement learning (RL) stage of its next models in public. A dashboard at mimo.xiaomi.com/rl streams metrics from two runs, mimo-v2.6-pro and mimo-v2.6-flash, as they happen. Both runs started on September 15, 2026. The page shows reward curves, rollout counts, step timings, running compute cost and mid-training coding scores. The […]
-
Hugging Face Opens Preorders for Microduck, a $399 Open-Source Biped
Pollen Robotics opened preorders for Microduck on August 27, 2026 — a 25 cm, 800 g open-source biped robot priced at $399. The robot is the second hardware product from the French startup Hugging Face acquired in April 2025, and the first built explicitly as a reinforcement-learning testbed: the SDK, the on-robot software, the MuJoCo […]
-
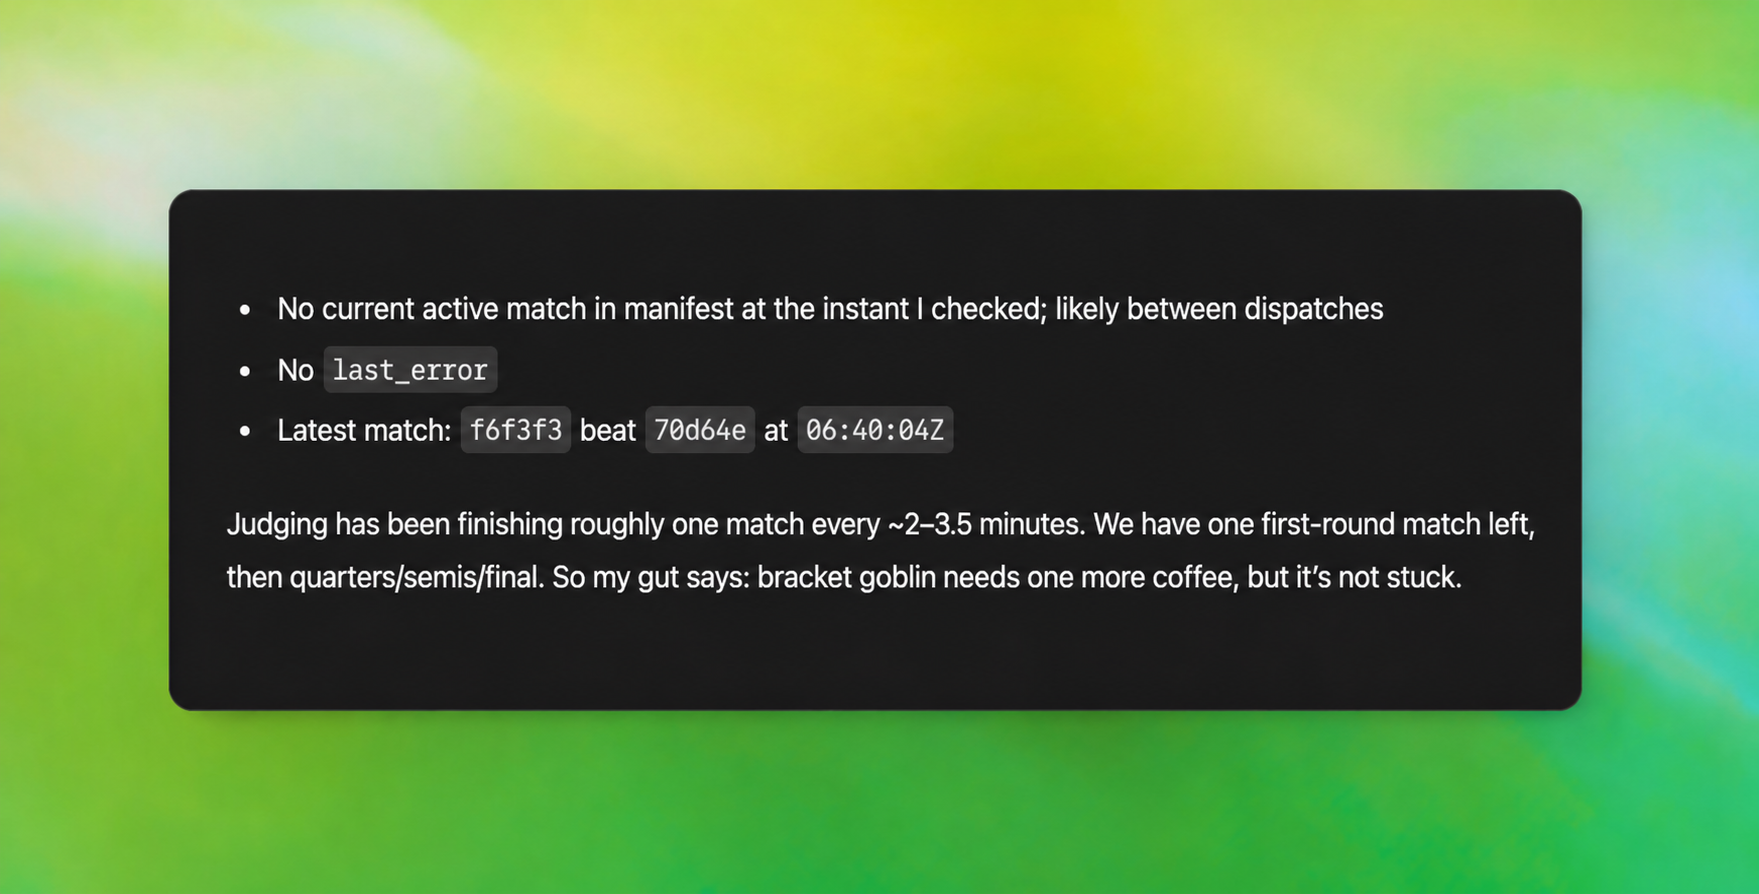
OpenAI Traces ChatGPT’s Goblin Habit to a Stray RL Reward Signal
OpenAI on April 29, 2026 published a post-mortem explaining why its recent ChatGPT models had developed a strange habit of sprinkling goblins, gremlins, and other small creatures into their answers. The cause traces back to reward signals in the “Nerdy” personality during reinforcement learning. Use of “goblin” in ChatGPT rose 175% after the GPT‑5.1 launch, […]
-
MiniMax M2.7: The First AI Model That Helps Train Itself
MiniMax has released M2.7, the first frontier AI model designed to participate in its own training loop. Announced on March 18, 2026, M2.7 introduces what MiniMax calls “self-evolution” — the model autonomously analyzes its own failure trajectories, modifies its scaffold code, and runs evaluations across 100+ iterative rounds, achieving a 30% performance improvement on internal […]
-
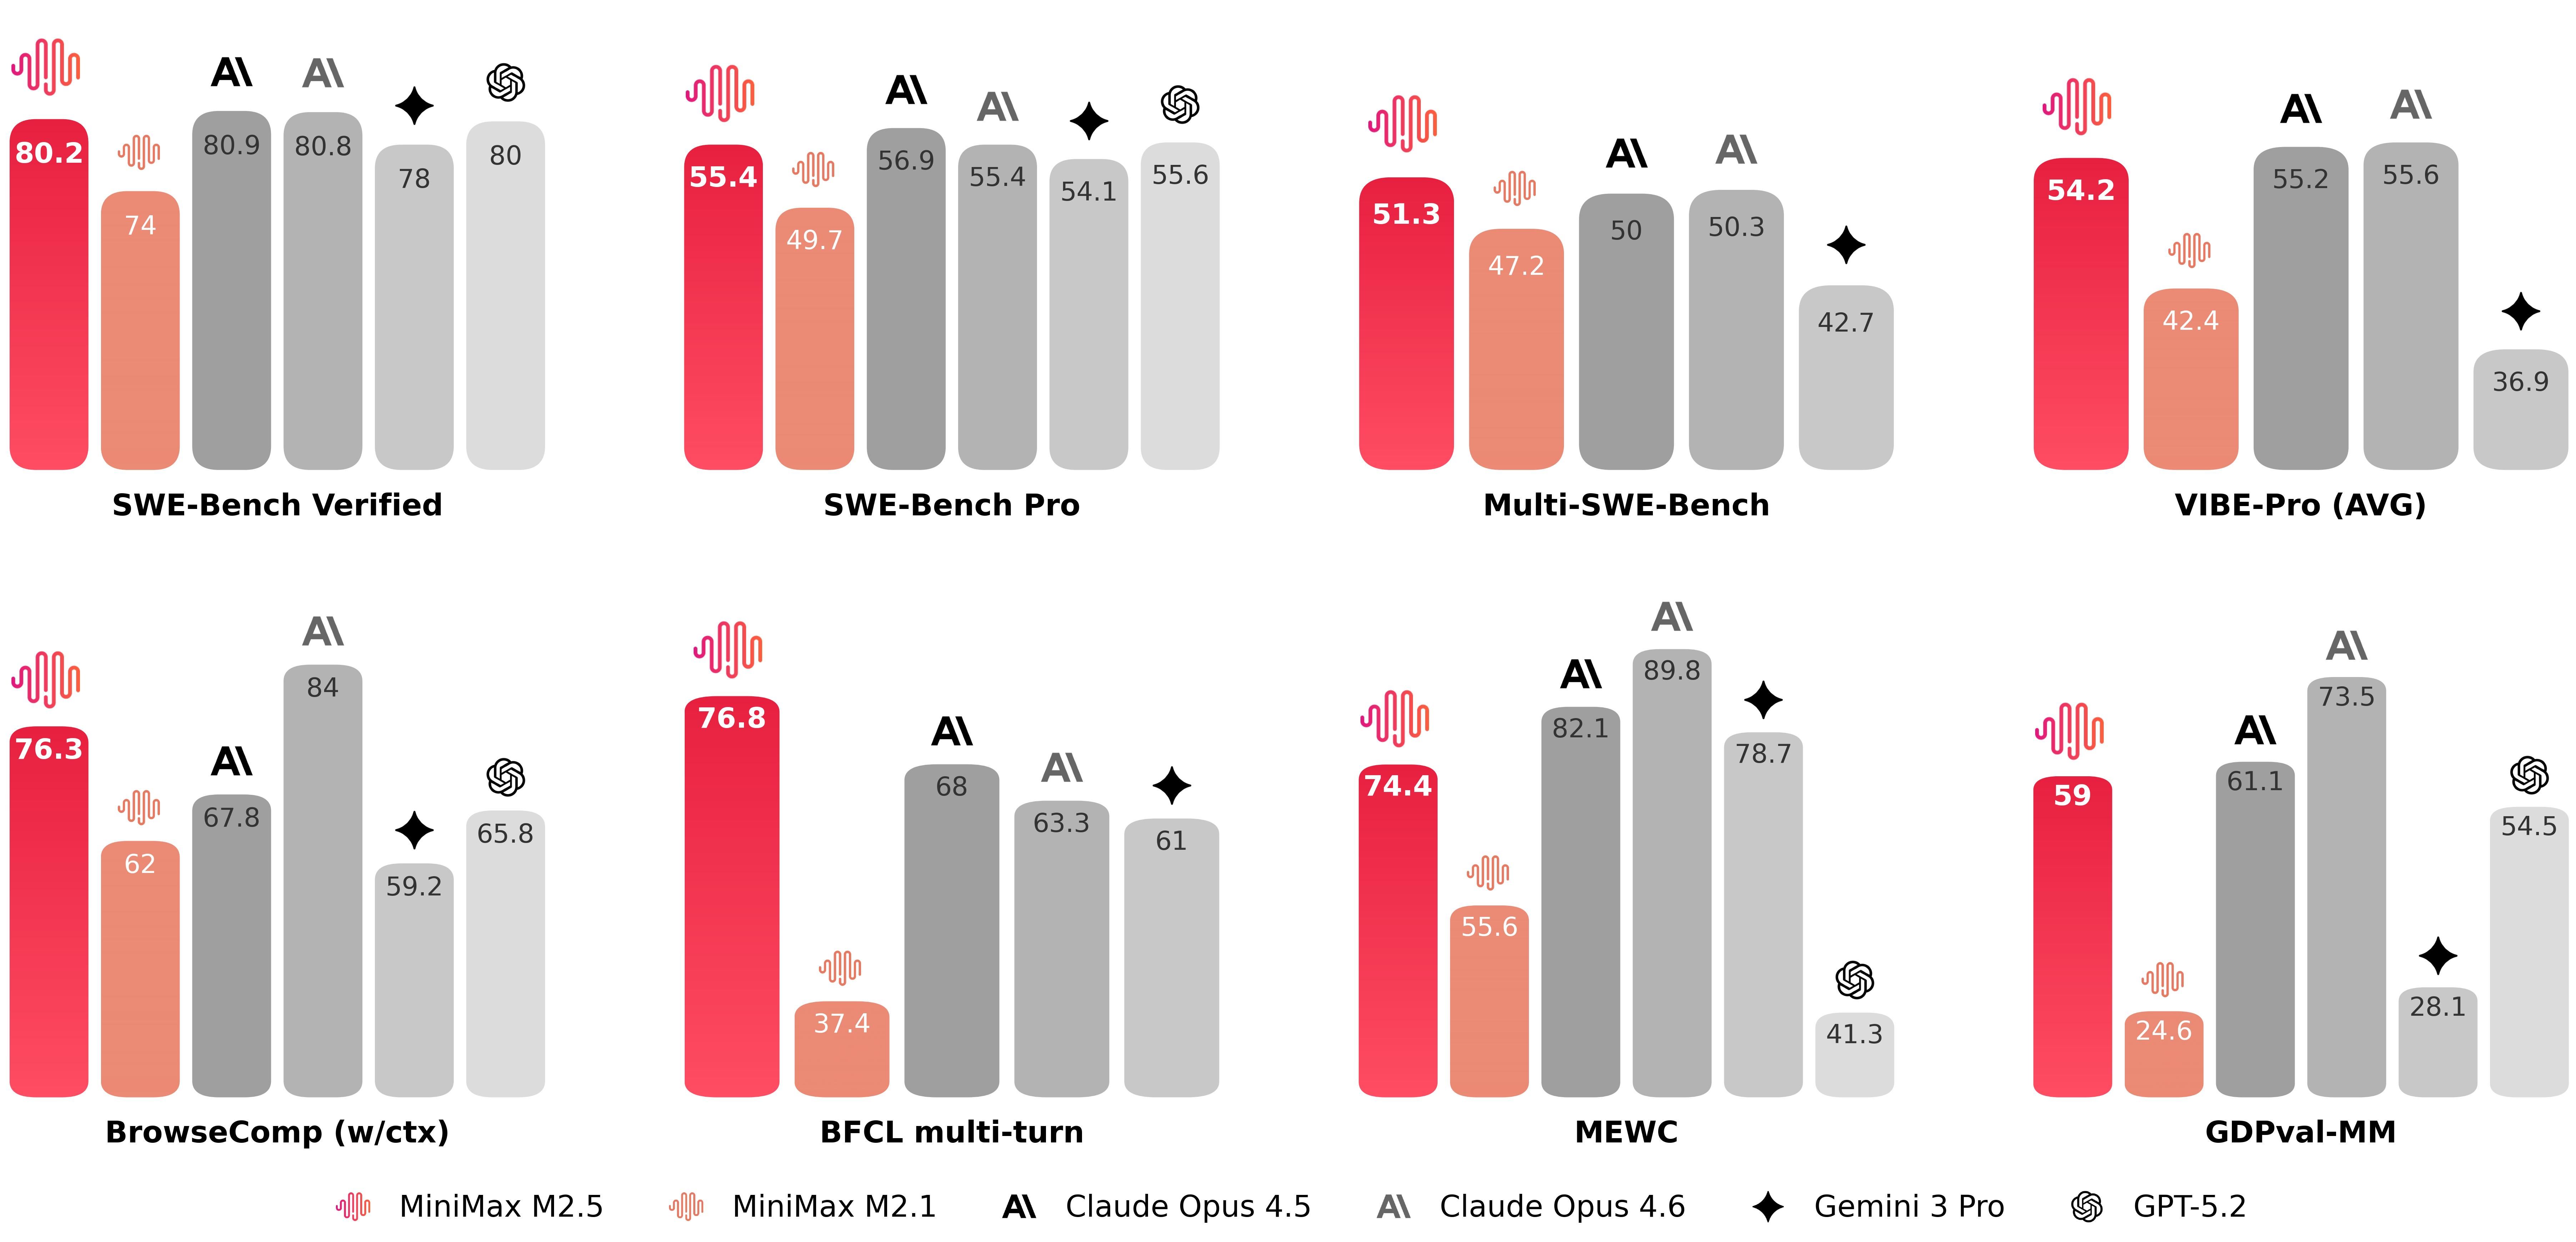
MiniMax M2.5: Frontier AI Performance at a Fraction of the Cost
Key points Announced on February 12, 2026, MiniMax’s M2.5 ships as open weights under a modified MIT license and, according to the company, matches leading proprietary systems at one-tenth to one-twentieth of their cost. M2.5 is a mixture-of-experts model with 229 billion total parameters, 10 billion active parameters and a 200,000-token context window, designed for […]