Tag: speculative decoding
-
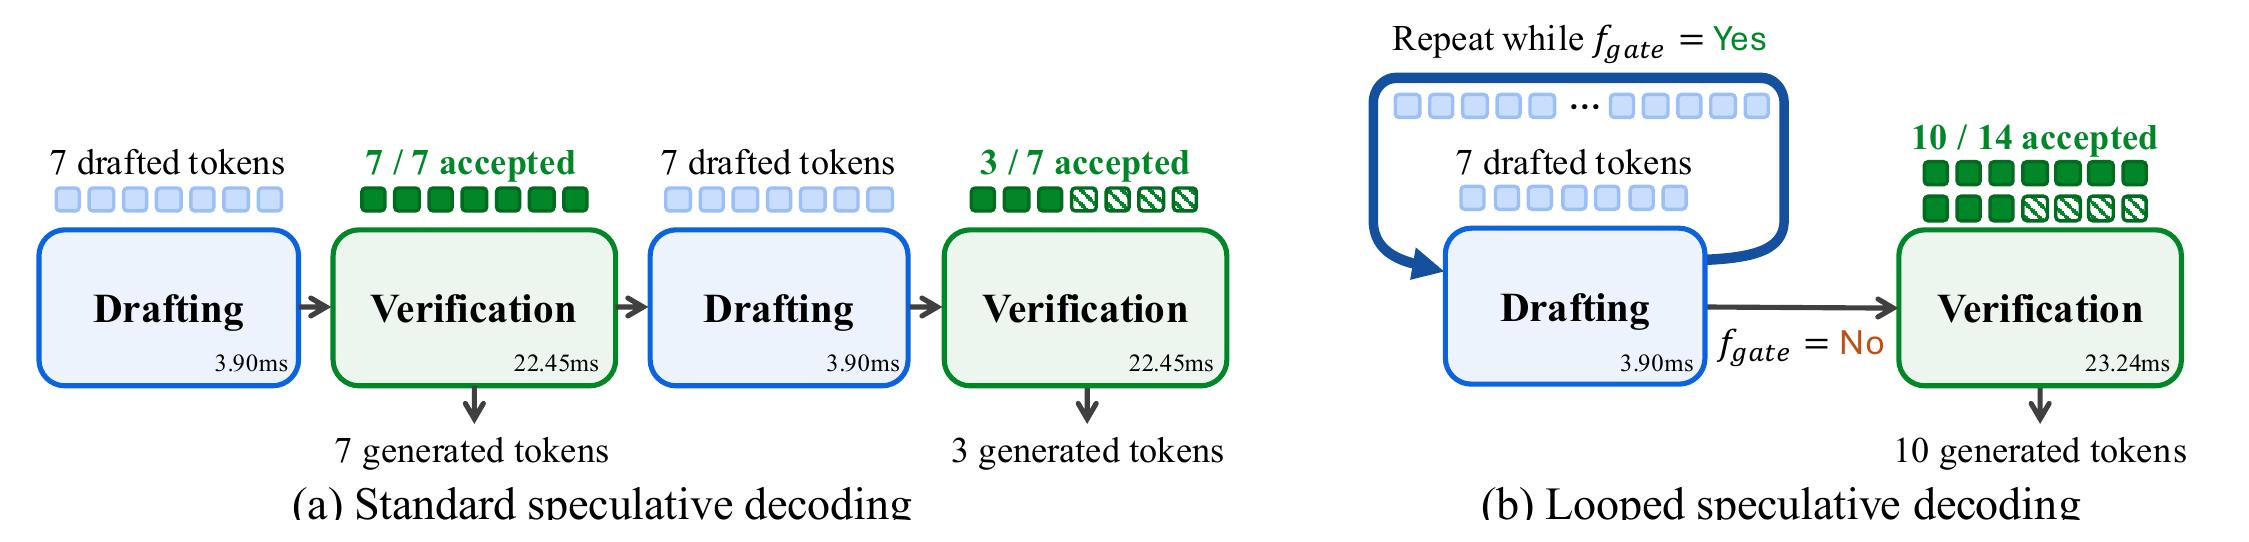
DLoop: Looped Speculative Decoding Cuts Target-Model Passes
NAVER AI Lab has proposed DLoop, a change to speculative decoding that lets a single verification pass cover several rounds of drafting instead of just one. In a preprint posted to arXiv on October 6, 2026, the team reports wall-clock speedups 5 to 41 percent higher than the draft models it builds on — EAGLE-3, […]
-
NInfer: 700 tok/s on One RTX 5090, With a Rare Honest Audit
NInfer is a from-scratch C++/CUDA inference engine that runs exactly two model checkpoints on exactly one GPU. Published under Apache 2.0 and first committed on June 26, 2026, the project by developer Neroued supports only Qwen3.6-27B and Qwen3.6-35B-A3B, only on an NVIDIA GeForce RTX 5090, and only one request at a time. In return for […]
-
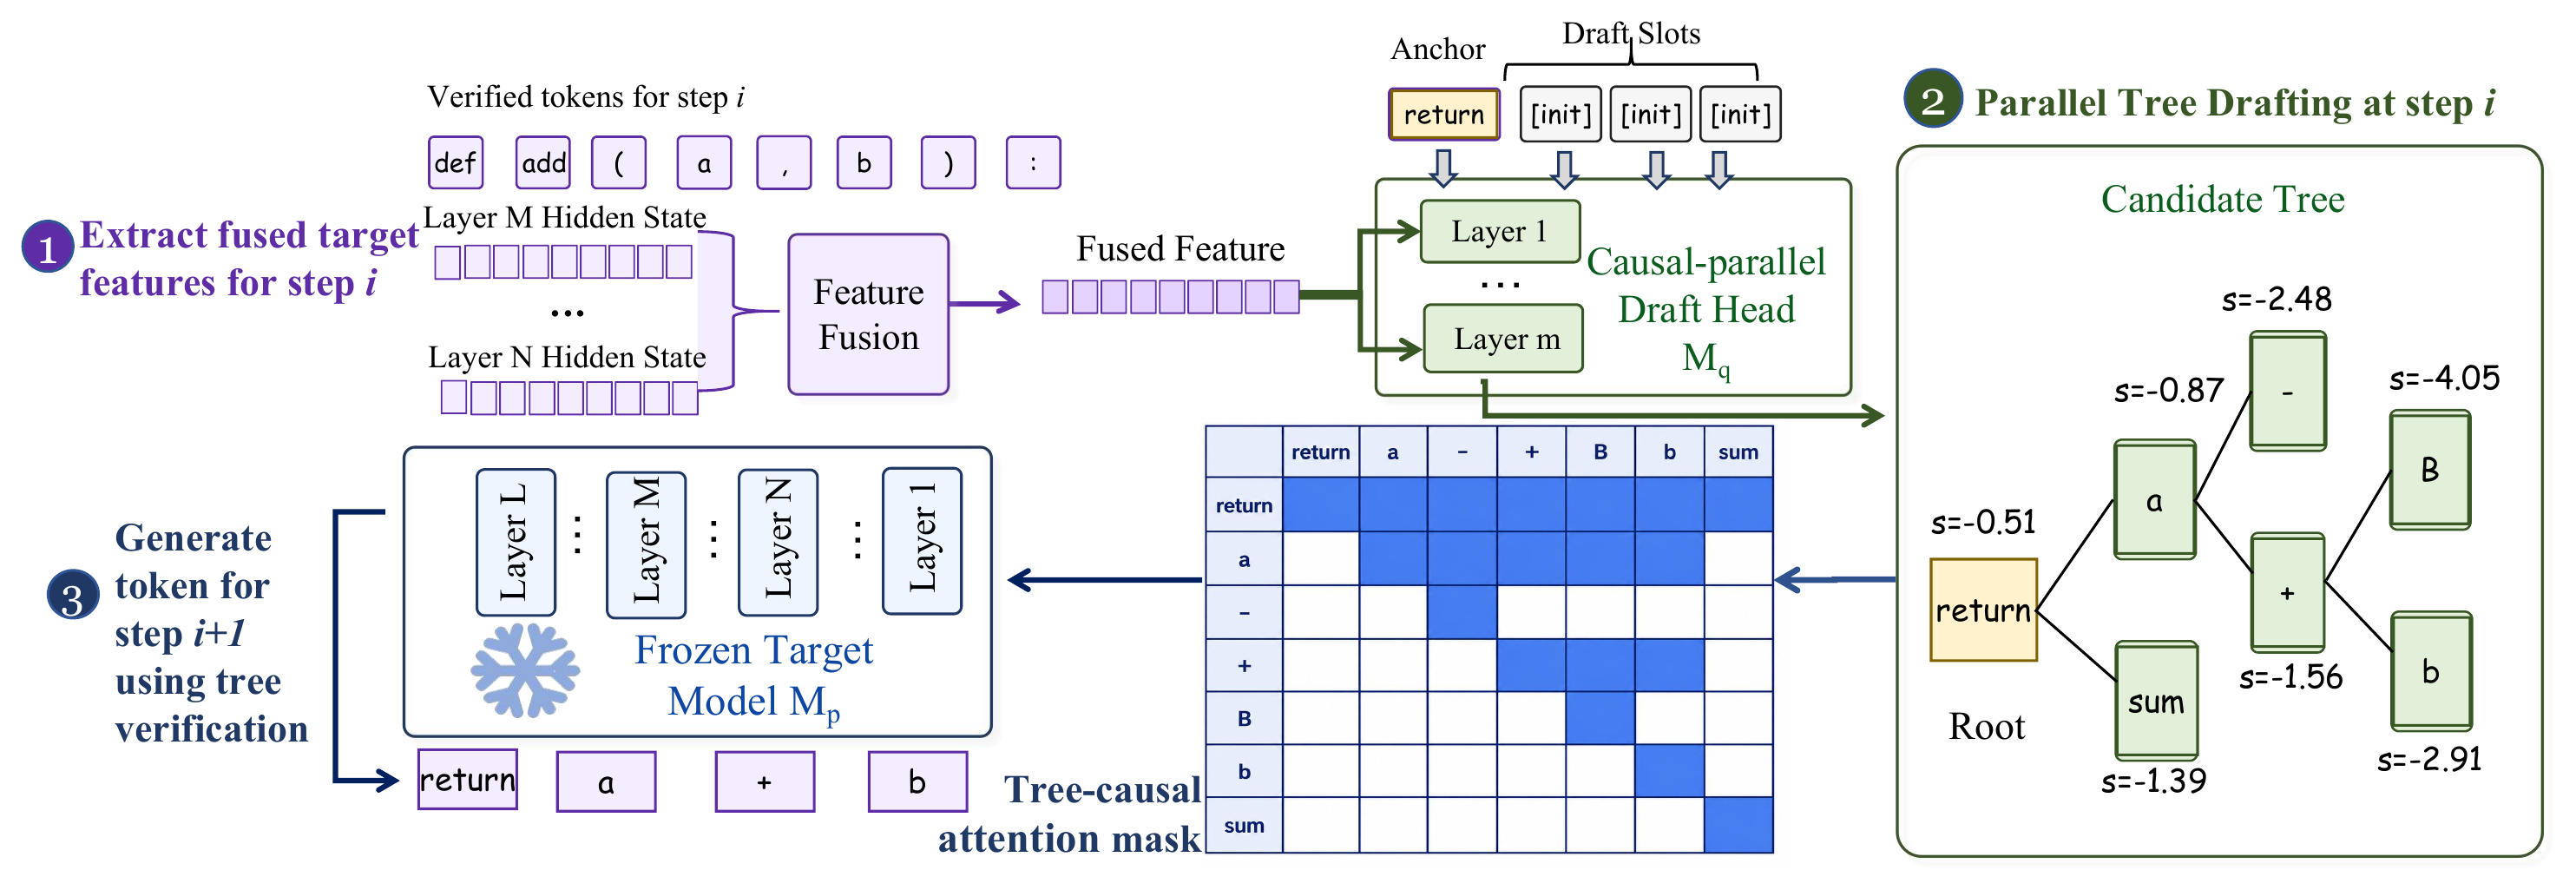
JetSpec: Causal Parallel Tree Drafting Hits 9.64x Faster LLM Inference
On June 26, 2026, researchers at UC San Diego’s Hao AI Lab released JetSpec — a speculative decoding method that accelerates large language model inference by up to 9.64× while leaving the model’s outputs unchanged. JetSpec trains a small “causal parallel draft head” on top of a frozen target model, generating a scored tree of […]
-
Gemma 4 Gets Multi-Token Prediction Drafters: 3x Faster Inference, Same Outputs
Lead — On May 5, 2026, Google released Multi-Token Prediction (MTP) drafters for the Gemma 4 family of open models. The drafters use speculative decoding to deliver up to a 3x speedup in inference latency without changing model outputs, and they ship under the same Apache 2.0 license as the underlying models. Advanced Key points […]
-
Luce DFlash Brings 2x Speculative Decoding to Qwen3.6-27B on a Single RTX 3090
Luce DFlash now runs Qwen3.6-27B on a single RTX 3090, delivering up to 2× throughput over autoregressive decoding. The Lucebox Hub project, which hand-tunes LLM inference for specific consumer GPUs, ported its DFlash speculative decoding stack to Qwen3.6-27B in late April 2026. Because Qwen3.6-27B reuses the Qwen3.5 architecture string with identical layer and head dimensions, […]
-
DFlash: Block Diffusion Delivers 6x Faster LLM Inference
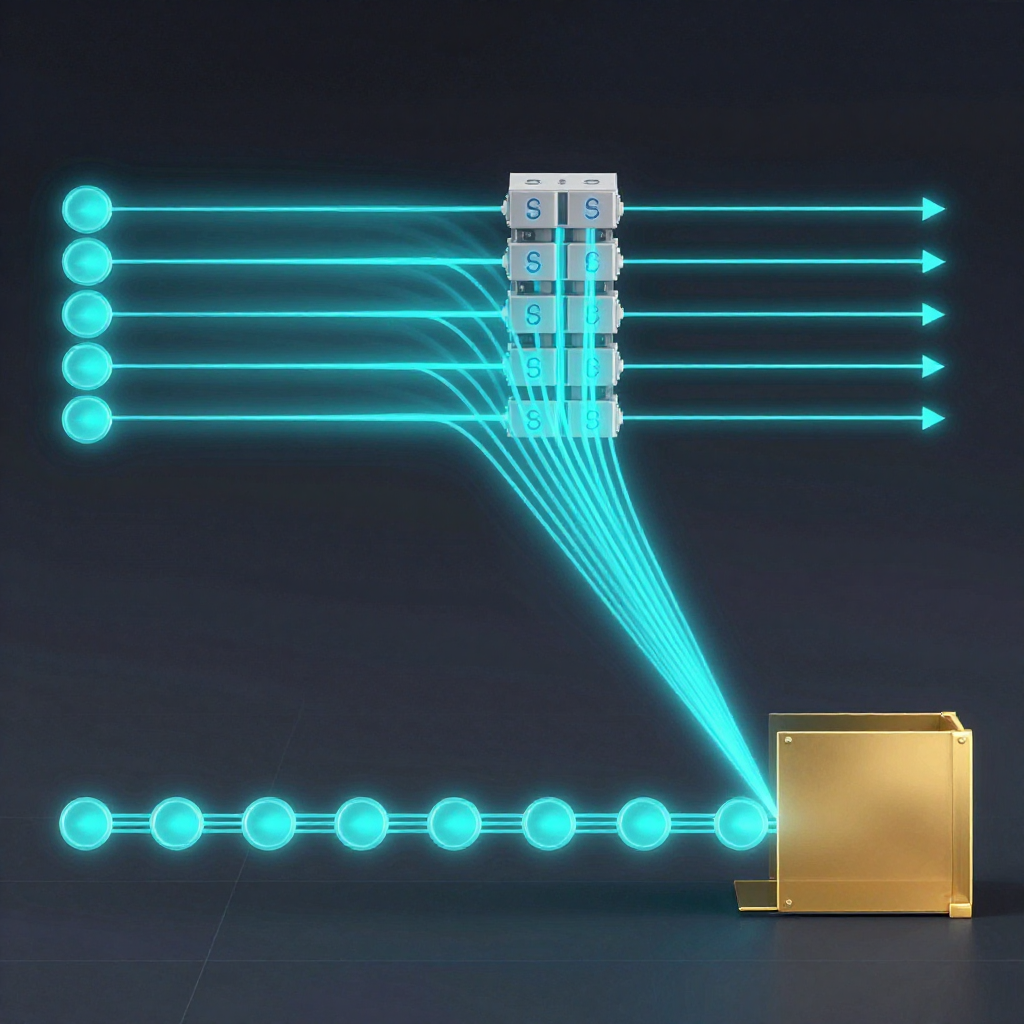
DFlash is a new speculative decoding framework that uses block diffusion models to generate draft tokens in parallel rather than sequentially, achieving over 6× lossless acceleration on large language models — up to 2.5× faster than the previous state-of-the-art method EAGLE-3. The paper was published in February 2026 by Jian Chen, Yesheng Liang, and Zhijian […]