Tag: speech-to-text
-
OpenAI Launches GPT-Realtime-2 with GPT-5-Class Voice Reasoning
OpenAI on May 7, 2026 introduced three new realtime voice models in its API — GPT‑Realtime‑2, GPT‑Realtime‑Translate, and GPT‑Realtime‑Whisper. The flagship GPT‑Realtime‑2 brings GPT‑5‑class reasoning to live voice, expands the context window from 32K to 128K tokens, and adds adjustable reasoning effort, parallel tool calls, and audible “preambles” so agents can carry conversations forward while […]
-
Cohere Transcribe: 2B Open-Source ASR Model Takes #1 on Leaderboard
On March 26, 2026, Cohere released Cohere Transcribe — a 2-billion-parameter open-source automatic speech recognition (ASR) model that claims the #1 spot on the Hugging Face Open ASR Leaderboard. Licensed under Apache 2.0 and designed to run on consumer-grade GPUs, Transcribe marks Cohere’s first entry into voice AI and signals growing competition in the open-source […]
-
Voxtral Transcribe 2: Mistral’s Open Real-Time Speech-to-Text
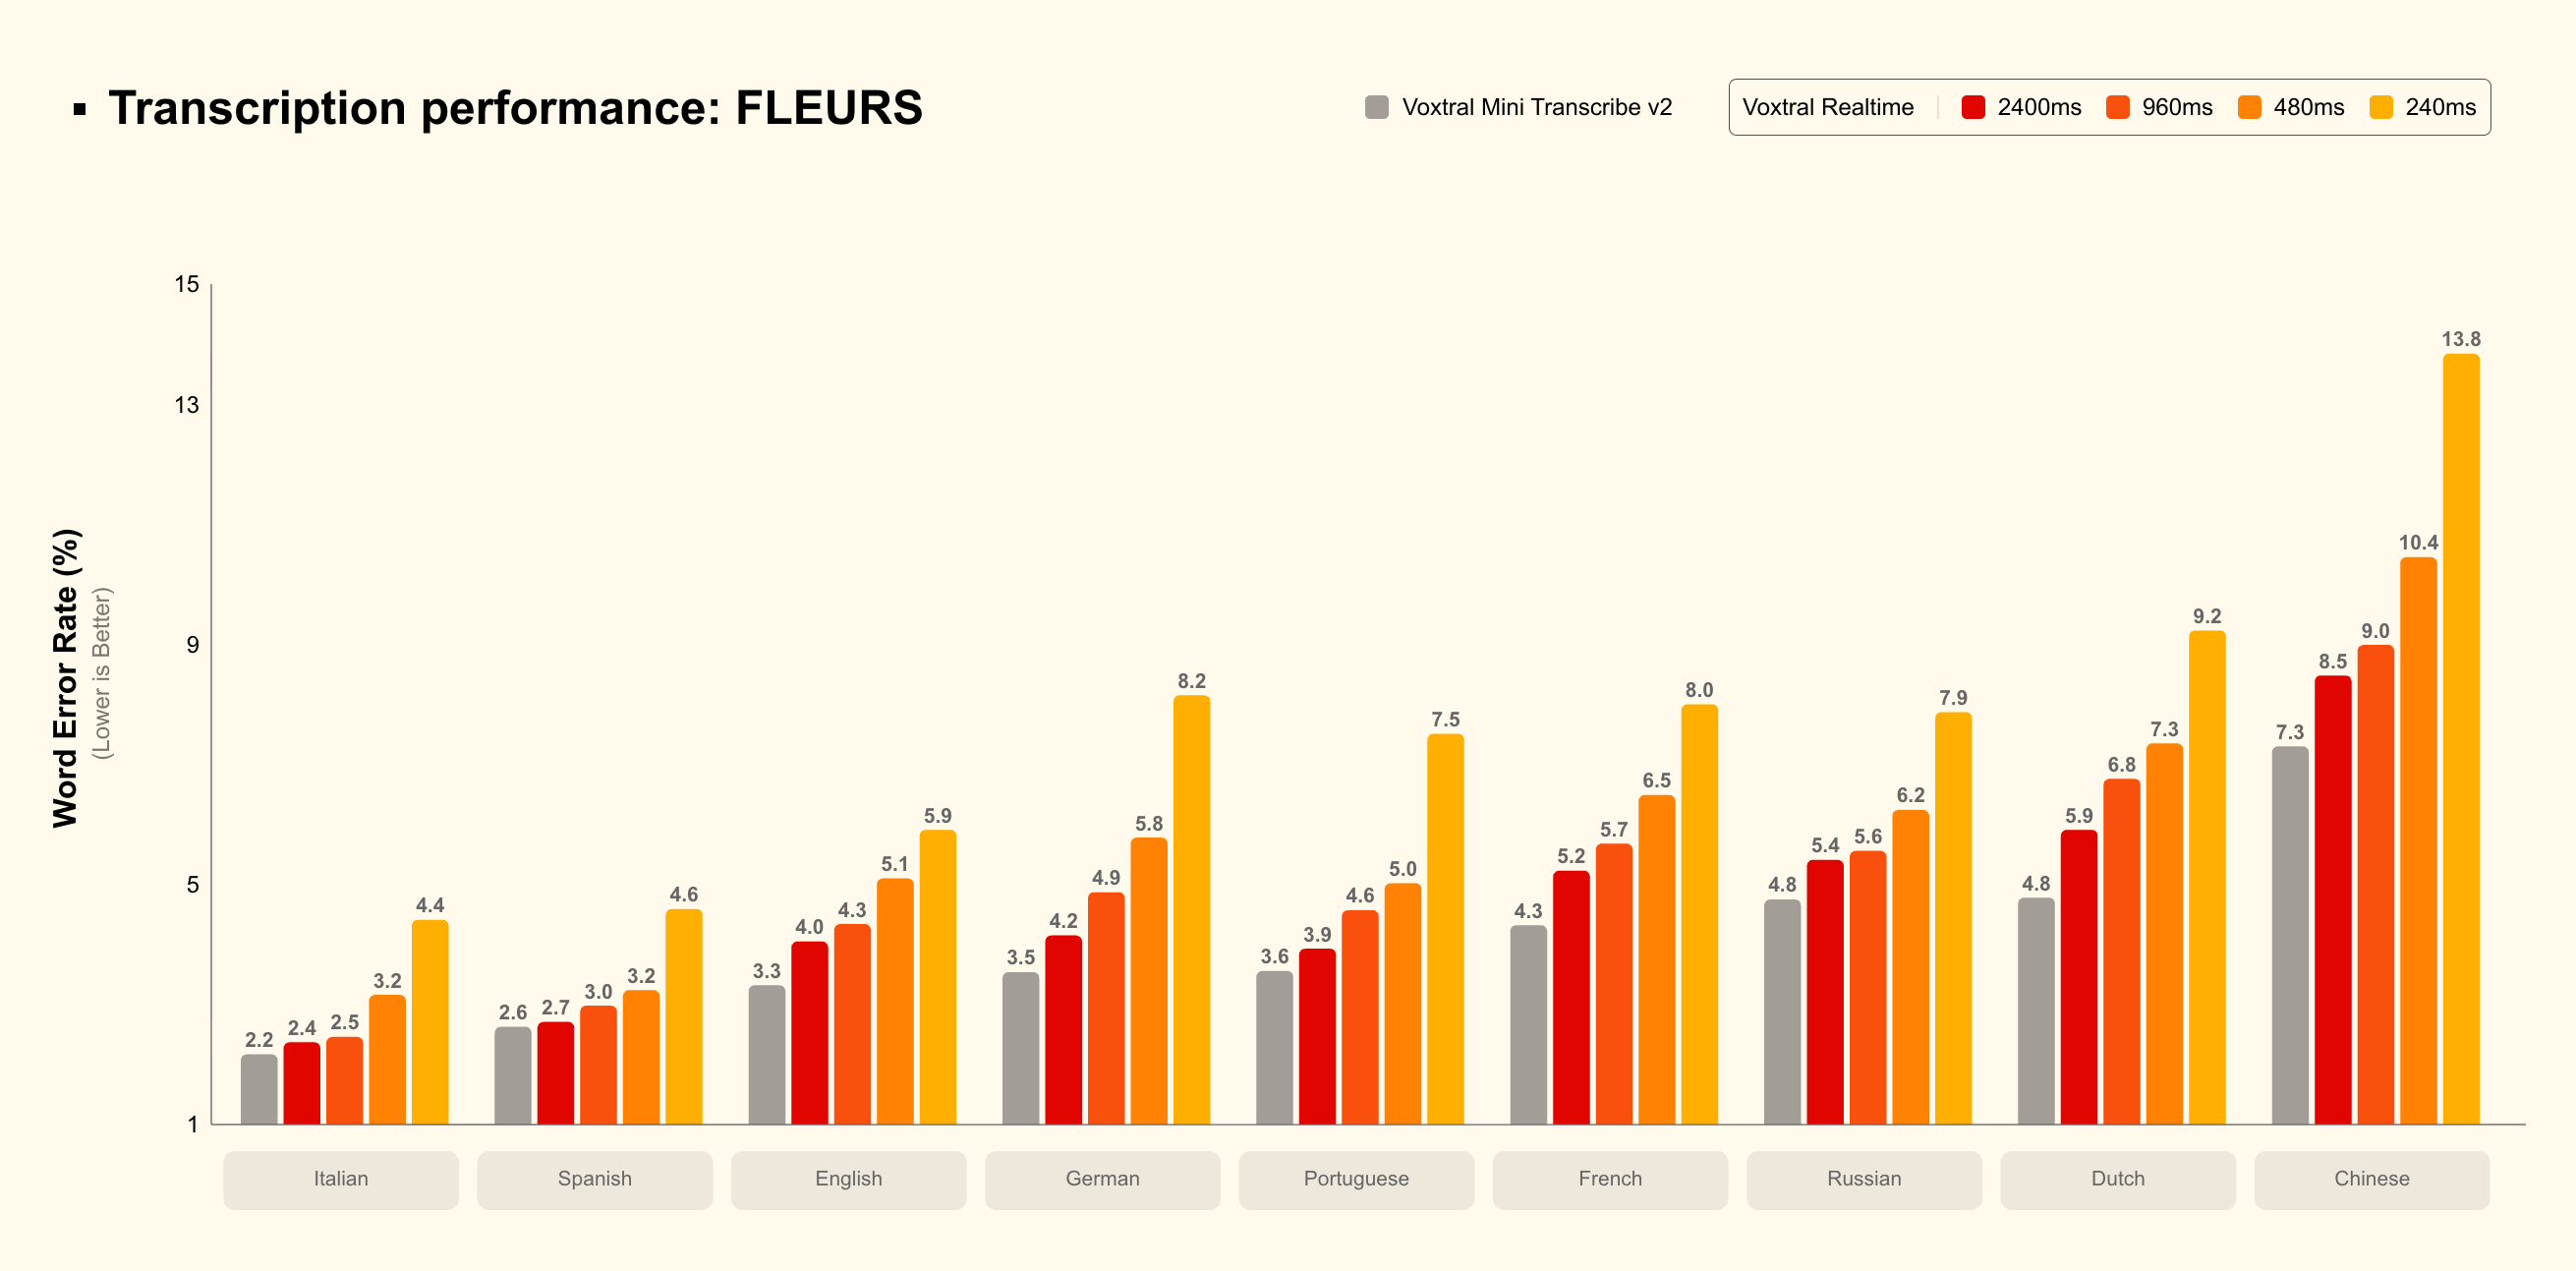
Key points On February 4, 2026, Mistral AI launched Voxtral Transcribe 2, a dual-model family with a high-accuracy batch transcription model and an open-weights real-time model. Mistral’s batch transcription model, Voxtral Mini Transcribe V2, achieves approximately 4% word error rate on the FLEURS benchmark, outperforming GPT-4o mini, Gemini 2.5 Flash, AssemblyAI Universal and Deepgram Nova […]
-
📢 Major Announcement: Qwen3‑ASR & Qwen3‑ForcedAligner Open Sourced
Alibaba’s Qwen3‑ASR family — a new advanced set of automatic speech recognition (ASR) models — has been officially open sourced, alongside a novel non‑autoregressive forced alignment model, Qwen3‑ForcedAligner. These models are designed as production‑ready, all‑in‑one speech intelligence systems that work across a wide range of languages and real‑world audio conditions. (Qwen) Key points The announcement […]
-
Voxtral Mini 3B & Small 24B — Frontier Open‑Source Speech Understanding by Mistral AI
Introduction On July 15, 2025, Mistral AI launched Voxtral, a new family of speech understanding models offering state-of-the-art, multilingual, and open-source voice AI. Available in two sizes—a compact Mini 3B for local or edge use and a larger Small (24B) for production environments—both are offered under an Apache 2.0 license and accessible via Hugging Face and […]