Tag: tts
-
inclusionAI Open-Sources Ming-3.0-audio, a 126B Audio LLM
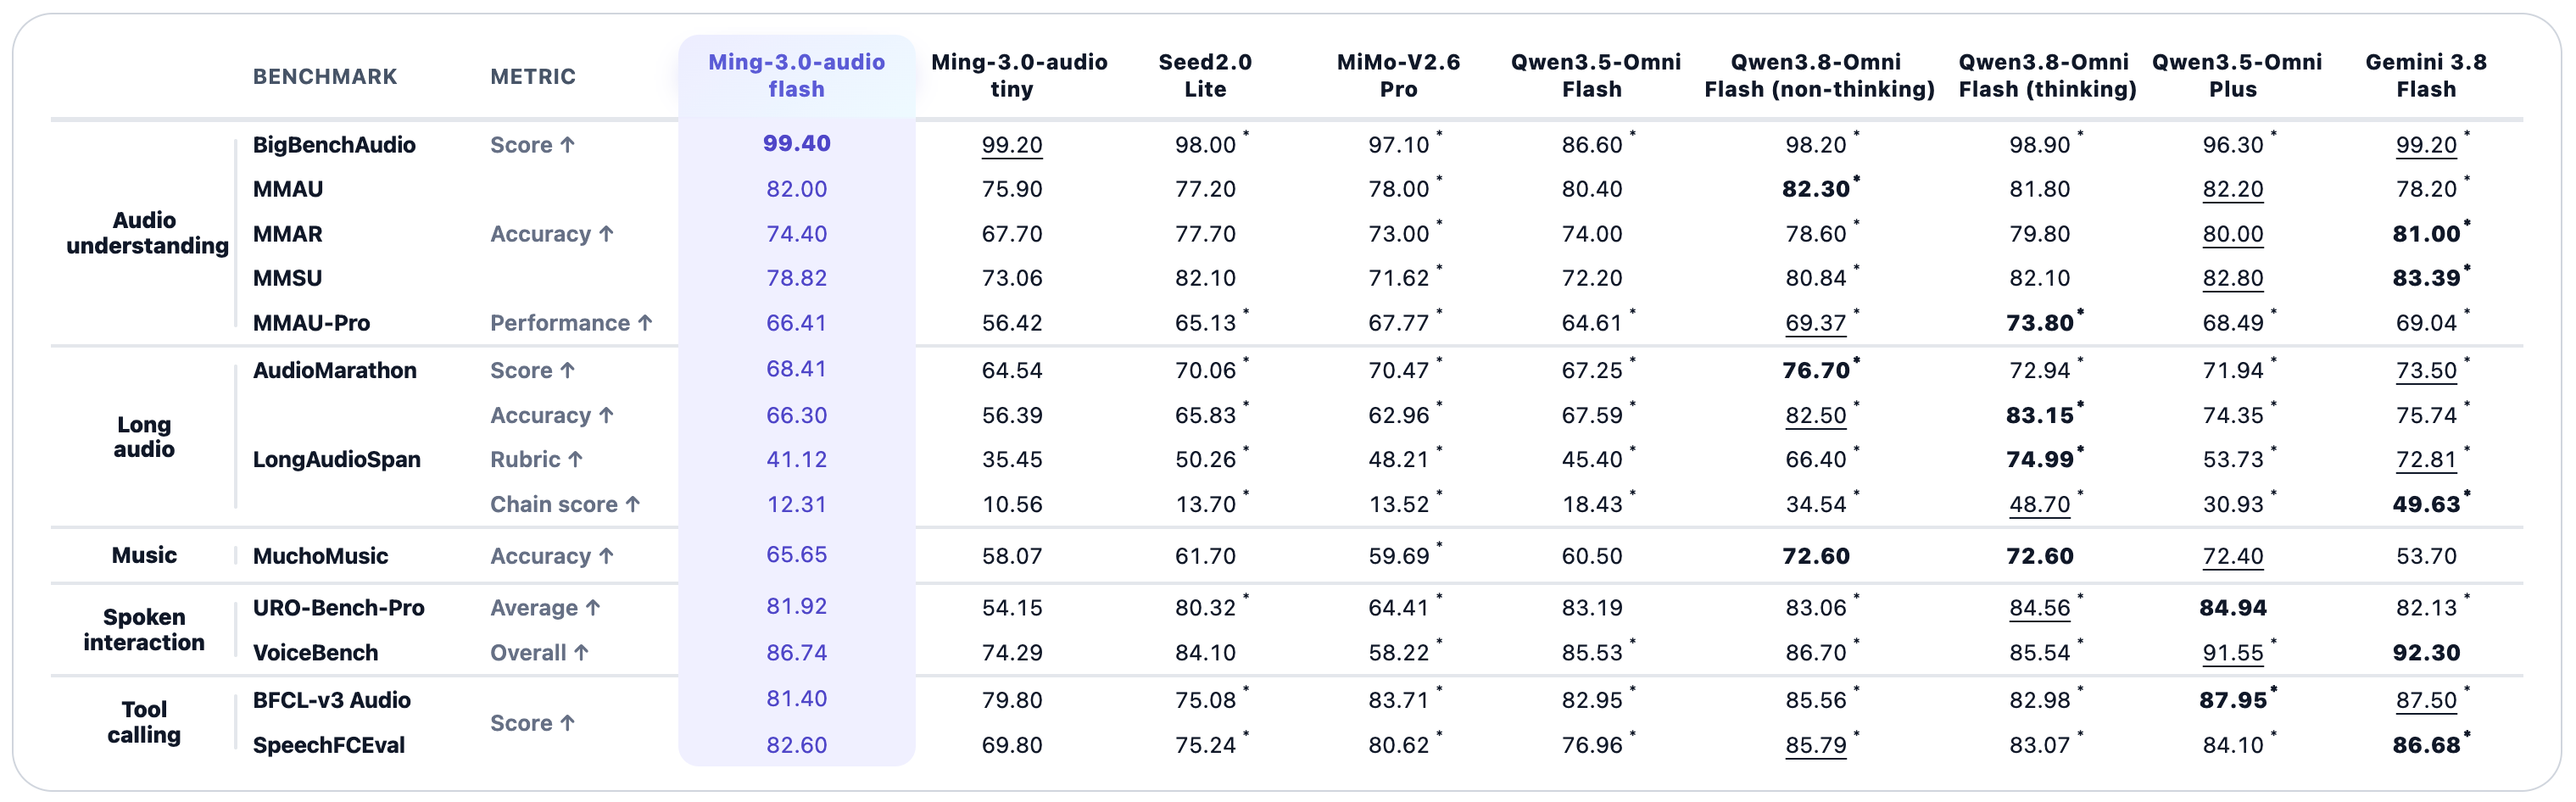
On October 19, 2026, Ant Group’s inclusionAI lab released Ming-3.0-audio-flash, a 126-billion-parameter audio-language model that activates 6.5 billion parameters per token and answers either in text or in synthesized speech. The weights and inference code went up on Hugging Face, ModelScope and GitHub under the MIT licence, together with a compact 9.3-billion-parameter sibling, Ming-3.0-audio-tiny. It […]
-
Fish Audio Releases Drama 3, a 35B Open-Weight Directable TTS Model
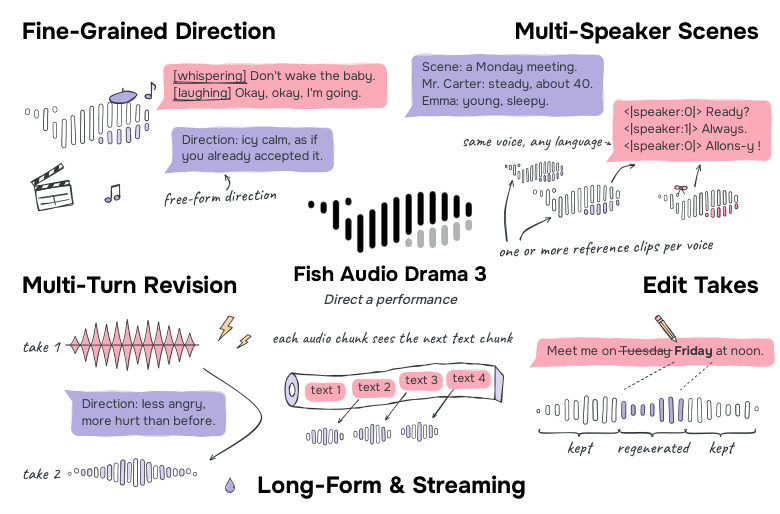
Lead — On October 13, 2026, Fish Audio released Drama 3, a 35-billion-parameter open-weight text-to-speech model that follows plain-language acting directions instead of selecting from a fixed menu of emotion presets. The weights are published on Hugging Face and GitHub under the Fish Audio Community License v1.0, and the model is served from launch day […]
-
Google Releases Gemini 3.1 Flash TTS with 200+ Audio Tags
On April 15, 2026, Google DeepMind released Gemini 3.1 Flash TTS — a text-to-speech model that introduces more than 200 granular audio tags for steering vocal style, tone, pacing, and accent, and tops the Artificial Analysis TTS leaderboard with an Elo score of 1,211. The preview is available through the Gemini API, Google AI Studio, […]
-
Voxtral TTS: Mistral’s Open-Weight Text-to-Speech Model Rivals ElevenLabs
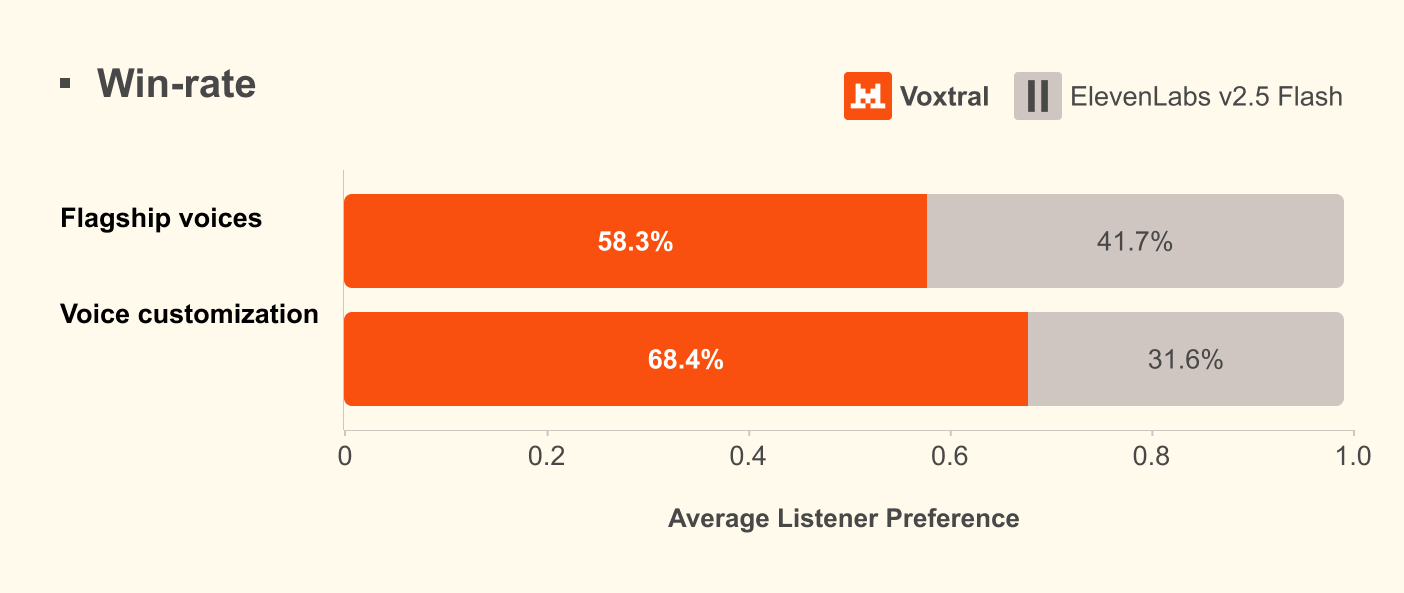
On March 26, 2026, Mistral AI released Voxtral TTS — a 4-billion-parameter open-weight text-to-speech model that the company says outperforms ElevenLabs Flash v2.5 in human preference tests while matching ElevenLabs v3 in lifelike interactions. Built on Ministral 3B, Voxtral TTS supports nine languages, clones voices from just three seconds of audio, and achieves 70ms latency […]
-
KittenTTS: State-of-the-Art Voice Synthesis in Under 25 MB
Key points KittenTTS was released on February 19, 2026 by KittenML as an open-source text-to-speech model that fits in under 25 MB. Its smallest configuration uses 14–15 million parameters and runs entirely on CPUs without any GPU requirement. It ships in three variants: Nano at 14–15M parameters and about 25 MB INT8, Micro at 40M […]
-
📢 Qwen3‑TTS — Open‑Source Text‑to‑Speech (TTS) Family
Qwen3‑TTS is a new open‑source suite of advanced text‑to‑speech models released by Alibaba’s Qwen team. It brings cutting‑edge speech synthesis capabilities — including voice cloning, voice design, and multilingual generation — to developers, researchers, and creators. (qwen.ai) Key points Qwen3-TTS is a new open-source suite of advanced text-to-speech models released by Alibaba’s Qwen team, bringing […]
-
Pocket TTS
Pocket TTS is a 100-million-parameter open-source text-to-speech (TTS) model developed by Kyutai that runs efficiently on CPUs in real time and supports high-quality voice cloning. (eWeek) Key points Pocket TTS is a 100-million-parameter open-source text-to-speech model developed by Kyutai. It achieves faster-than-real-time performance, with about 6× real-time throughput on standard hardware such as a MacBook […]
-
🎙️ GLM‑TTS – High‑Quality Text‑to‑Speech Model
GLM‑TTS is an open‑source text‑to‑speech (TTS) synthesis system built using large language models (LLMs). It’s designed to produce expressive, high‑quality speech from text and includes features like zero‑shot voice cloning and emotion control. (Hugging Face) Key points GLM-TTS is an open-source text-to-speech synthesis system built using large language models, designed to produce expressive, high-quality speech […]
-
What is Live Avatar
Key Capabilities & Technical Details What You Can Do with It Because of its real‑time streaming + infinite length + high visual fidelity, Live Avatar enables use cases like: Key points Live Avatar is described as an AI-driven framework for real-time, streaming, infinite-length avatar video generation. It reportedly achieves 20 FPS when run on 5 […]
-
Introducing VoxCPM 1.5 — the latest milestone in open‑source speech synthesis
The team behind the VoxCPM project recently released VoxCPM 1.5 — a major update to their open‑source, tokenizer‑free Text-to-Speech (TTS) system. This new version brings substantial improvements in audio quality and efficiency compared to prior versions. (Hugging Face) Key points VoxCPM 1.5 was released on December 5, 2025 as a major update to the project’s open-source, […]