Tag: vllm
-
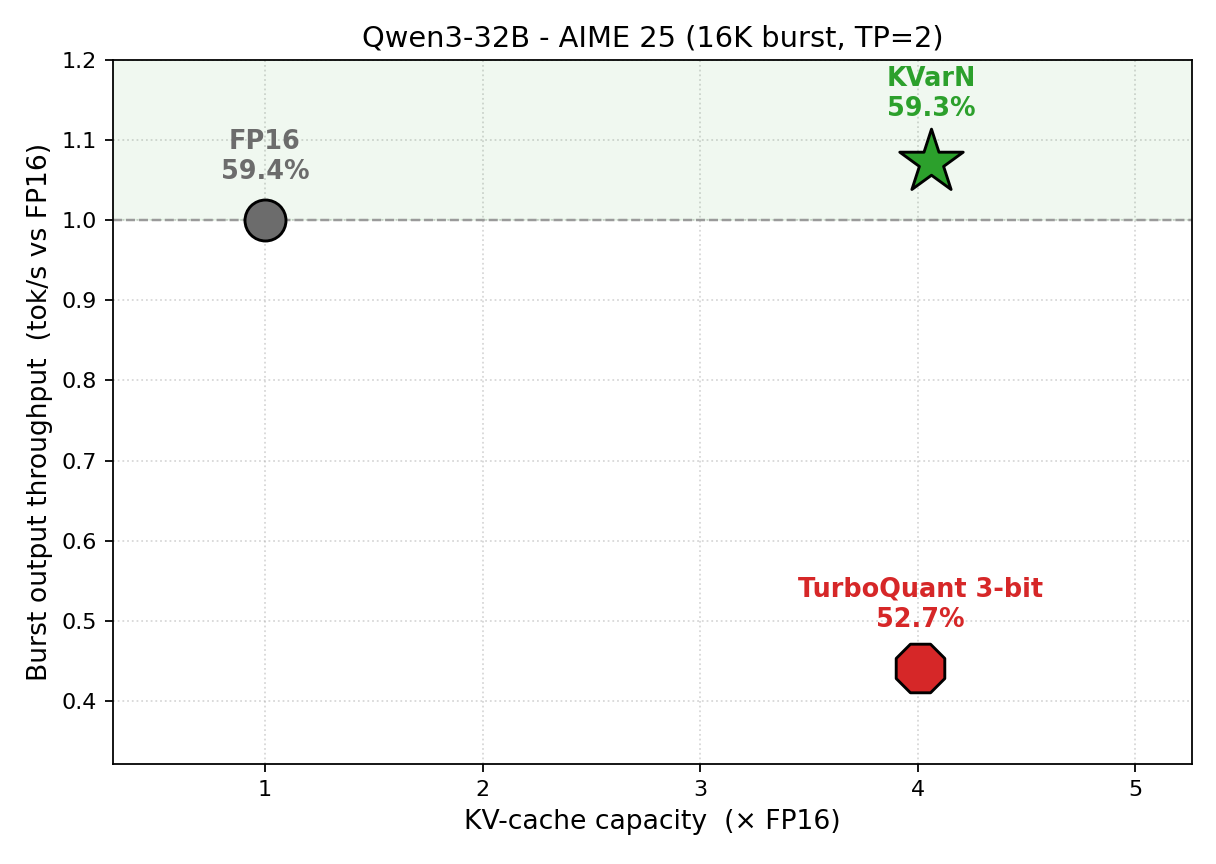
Huawei’s KVarN Hits 5x KV-Cache Capacity at FP16 Accuracy and Throughput
On June 2, 2026, Huawei researchers released KVarN — a variance-normalized KV-cache quantization backend for vLLM that breaks the long-standing tradeoff between cache compression and inference speed. KVarN delivers 3–5× more context capacity at 2-bit precision while keeping FP16-level accuracy and beating FP16 throughput, all behind a single vLLM flag with no calibration. It ships […]
-
BadHost Starlette Bug Puts AI Agent Infrastructure on Alert
A critical Starlette vulnerability known as BadHost is drawing attention from AI infrastructure teams because Starlette is widely used in Python web services, including stacks around vLLM, MCP servers, and agent tooling. The issue, tracked as CVE-2026-48710, involves improper handling of untrusted Host headers and can enable cache poisoning, poisoned password reset links, and server-side […]