Tag: voice
-
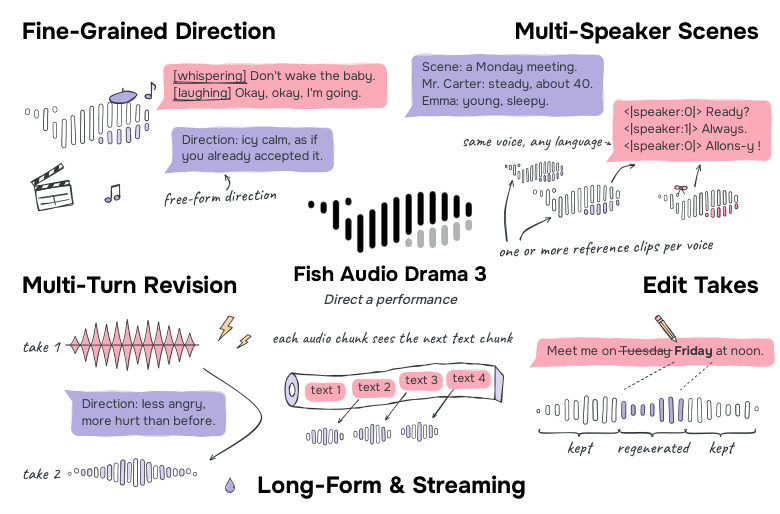
Fish Audio Releases Drama 3, a 35B Open-Weight Directable TTS Model
Lead — On October 13, 2026, Fish Audio released Drama 3, a 35-billion-parameter open-weight text-to-speech model that follows plain-language acting directions instead of selecting from a fixed menu of emotion presets. The weights are published on Hugging Face and GitHub under the Fish Audio Community License v1.0, and the model is served from launch day […]
-
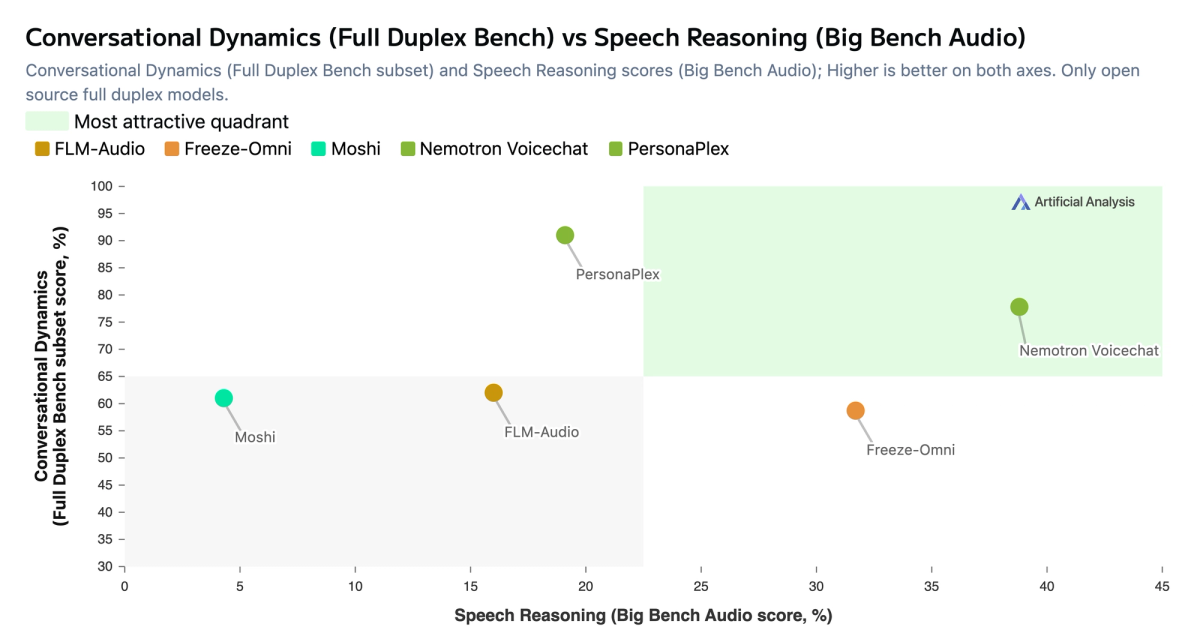
NVIDIA Releases NemotronLabs VoiceChat, an Open Full-Duplex Voice Model
NVIDIA released NemotronLabs VoiceChat on August 3, 2026 — an 11-billion-parameter, end-to-end speech model that listens and speaks at the same time, published with open weights on Hugging Face. It is the first open full-duplex model that can call tools mid-conversation, and independent testing from Artificial Analysis places it as the only open-weights speech model […]
-
OpenAI Launches GPT-Live: Full-Duplex Voice for ChatGPT
OpenAI on July 8, 2026 launched GPT‑Live, a new generation of voice models now powering ChatGPT Voice. Built on a full-duplex architecture that listens and speaks at the same time, GPT‑Live‑1 and GPT‑Live‑1 mini are rolling out globally to ChatGPT users on iOS, Android, and the web starting today. The models replace the turn-based Advanced […]
-
Thinking Machines Unveils Interaction Models for Real-Time Human-AI Collaboration
Thinking Machines Lab announced its first “interaction models” on May 11, 2026, unveiling TML-Interaction-Small — a 276B-parameter mixture-of-experts model (12B active) designed for real-time, multimodal collaboration. Rather than waiting for the user to finish speaking, the model interleaves 200-millisecond chunks of audio and video input with simultaneous output generation, eliminating the turn-taking pause that defines […]
-
OpenAI Launches GPT-Realtime-2 with GPT-5-Class Voice Reasoning
OpenAI on May 7, 2026 introduced three new realtime voice models in its API — GPT‑Realtime‑2, GPT‑Realtime‑Translate, and GPT‑Realtime‑Whisper. The flagship GPT‑Realtime‑2 brings GPT‑5‑class reasoning to live voice, expands the context window from 32K to 128K tokens, and adds adjustable reasoning effort, parallel tool calls, and audible “preambles” so agents can carry conversations forward while […]
-
Google Releases Gemini 3.1 Flash TTS with 200+ Audio Tags
On April 15, 2026, Google DeepMind released Gemini 3.1 Flash TTS — a text-to-speech model that introduces more than 200 granular audio tags for steering vocal style, tone, pacing, and accent, and tops the Artificial Analysis TTS leaderboard with an Elo score of 1,211. The preview is available through the Gemini API, Google AI Studio, […]
-
Qwen3.5-Omni: Alibaba’s Omnimodal AI Speaks 36 Languages and Codes from Voice
On March 30, 2026, Alibaba’s Qwen team released Qwen3.5-Omni — a natively omnimodal AI model that processes text, images, audio, and video while generating real-time speech output. Available in three sizes (Plus, Flash, and Light), the model claims 215 state-of-the-art benchmark results and introduces features like semantic interruption, voice cloning, and an emergent “Audio-Visual Vibe […]
-
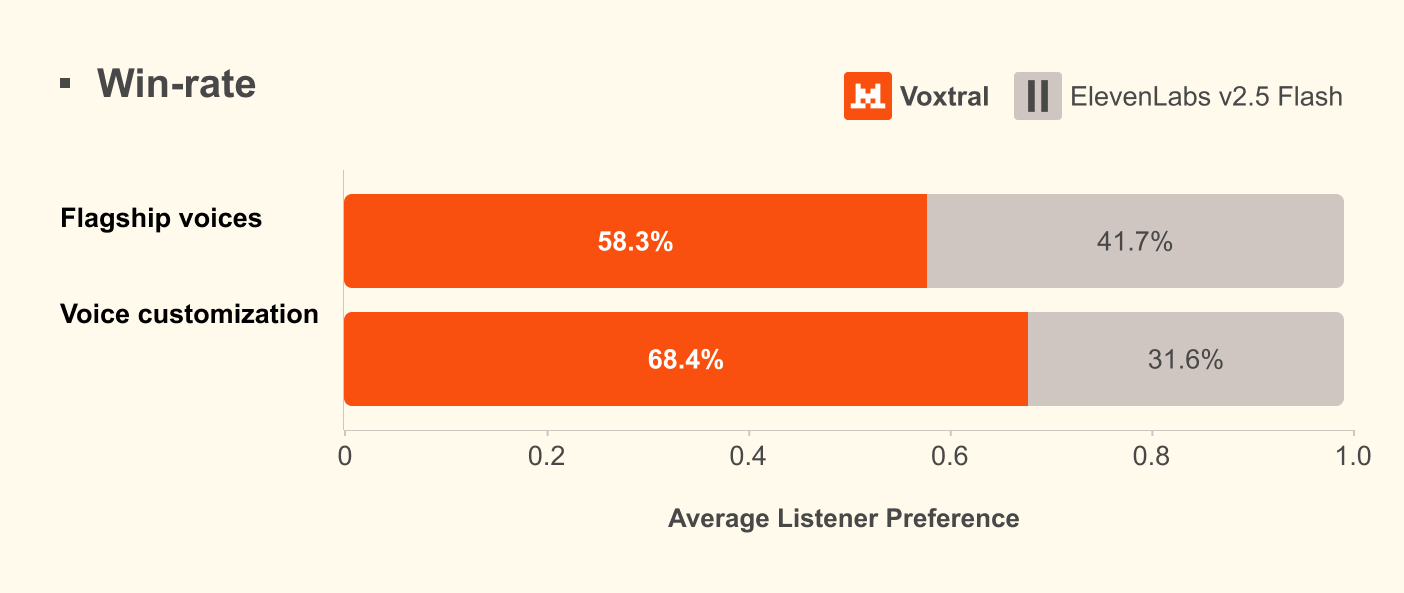
Voxtral TTS: Mistral’s Open-Weight Text-to-Speech Model Rivals ElevenLabs
On March 26, 2026, Mistral AI released Voxtral TTS — a 4-billion-parameter open-weight text-to-speech model that the company says outperforms ElevenLabs Flash v2.5 in human preference tests while matching ElevenLabs v3 in lifelike interactions. Built on Ministral 3B, Voxtral TTS supports nine languages, clones voices from just three seconds of audio, and achieves 70ms latency […]
-
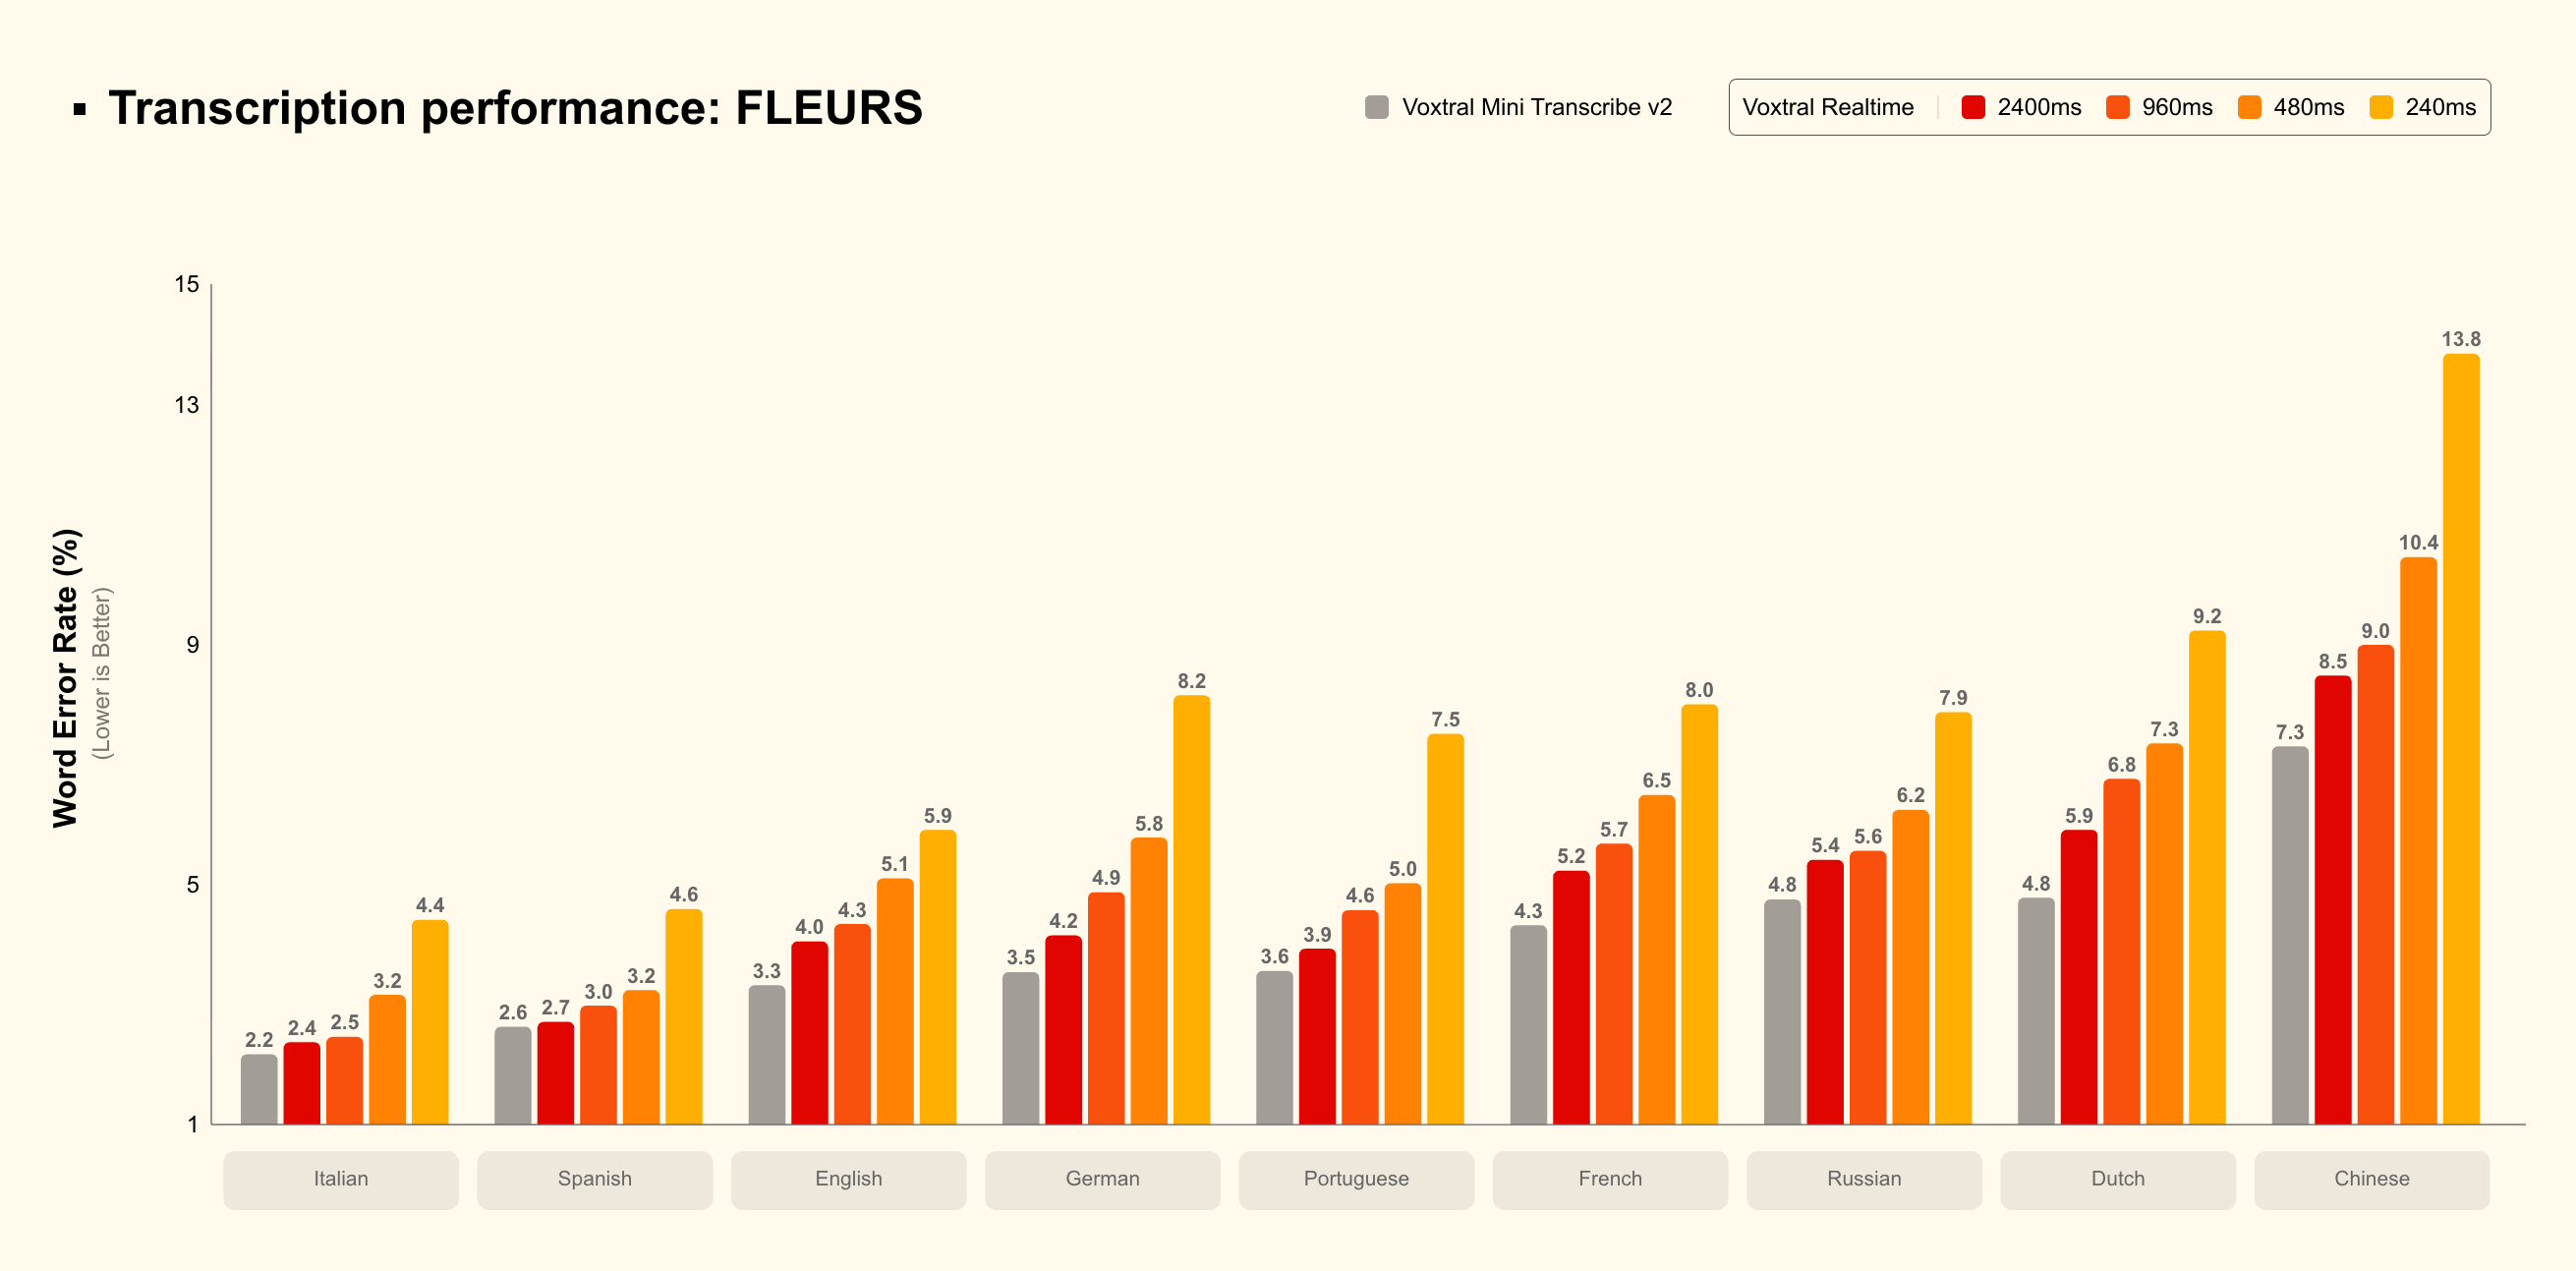
Voxtral Transcribe 2: Mistral’s Open Real-Time Speech-to-Text
Key points On February 4, 2026, Mistral AI launched Voxtral Transcribe 2, a dual-model family with a high-accuracy batch transcription model and an open-weights real-time model. Mistral’s batch transcription model, Voxtral Mini Transcribe V2, achieves approximately 4% word error rate on the FLEURS benchmark, outperforming GPT-4o mini, Gemini 2.5 Flash, AssemblyAI Universal and Deepgram Nova […]
-
🎙️ GLM‑TTS – High‑Quality Text‑to‑Speech Model
GLM‑TTS is an open‑source text‑to‑speech (TTS) synthesis system built using large language models (LLMs). It’s designed to produce expressive, high‑quality speech from text and includes features like zero‑shot voice cloning and emotion control. (Hugging Face) Key points GLM-TTS is an open-source text-to-speech synthesis system built using large language models, designed to produce expressive, high-quality speech […]