Tag: Audio
-
Cohere Transcribe: 2B Open-Source ASR Model Takes #1 on Leaderboard
On March 26, 2026, Cohere released Cohere Transcribe — a 2-billion-parameter open-source automatic speech recognition (ASR) model that claims the #1 spot on the Hugging Face Open ASR Leaderboard. Licensed under Apache 2.0 and designed to run on consumer-grade GPUs, Transcribe marks Cohere’s first entry into voice AI and signals growing competition in the open-source […]
-
Foundation-1: A Producer-Focused AI Model for Structured Music Sample Generation
RoyalCities has released Foundation-1, a specialized text-to-sample AI model built on Stability AI’s Stable Audio Open architecture. Unlike general-purpose music generators that output full songs, Foundation-1 is designed for actual music production workflows — generating tempo-synced, key-aware, bar-structured audio loops with fine-grained control over instrumentation, timbre, effects, and musical phrasing. Intermediate Key points RoyalCities released […]
-
Seedance 2.0: ByteDance’s Multimodal Audio-Video AI Model
Key points ByteDance launched Seedance 2.0 on February 12, 2026, describing it as a unified multimodal audio-video joint generation architecture. Users can feed the model up to 9 images, 3 video clips, 3 audio clips, and natural language instructions at once, 12 files in total. Output videos can run up to 15 seconds at native […]
-
ACE-Step 1.5: Open-Source Music Generation That Rivals Commercial AI
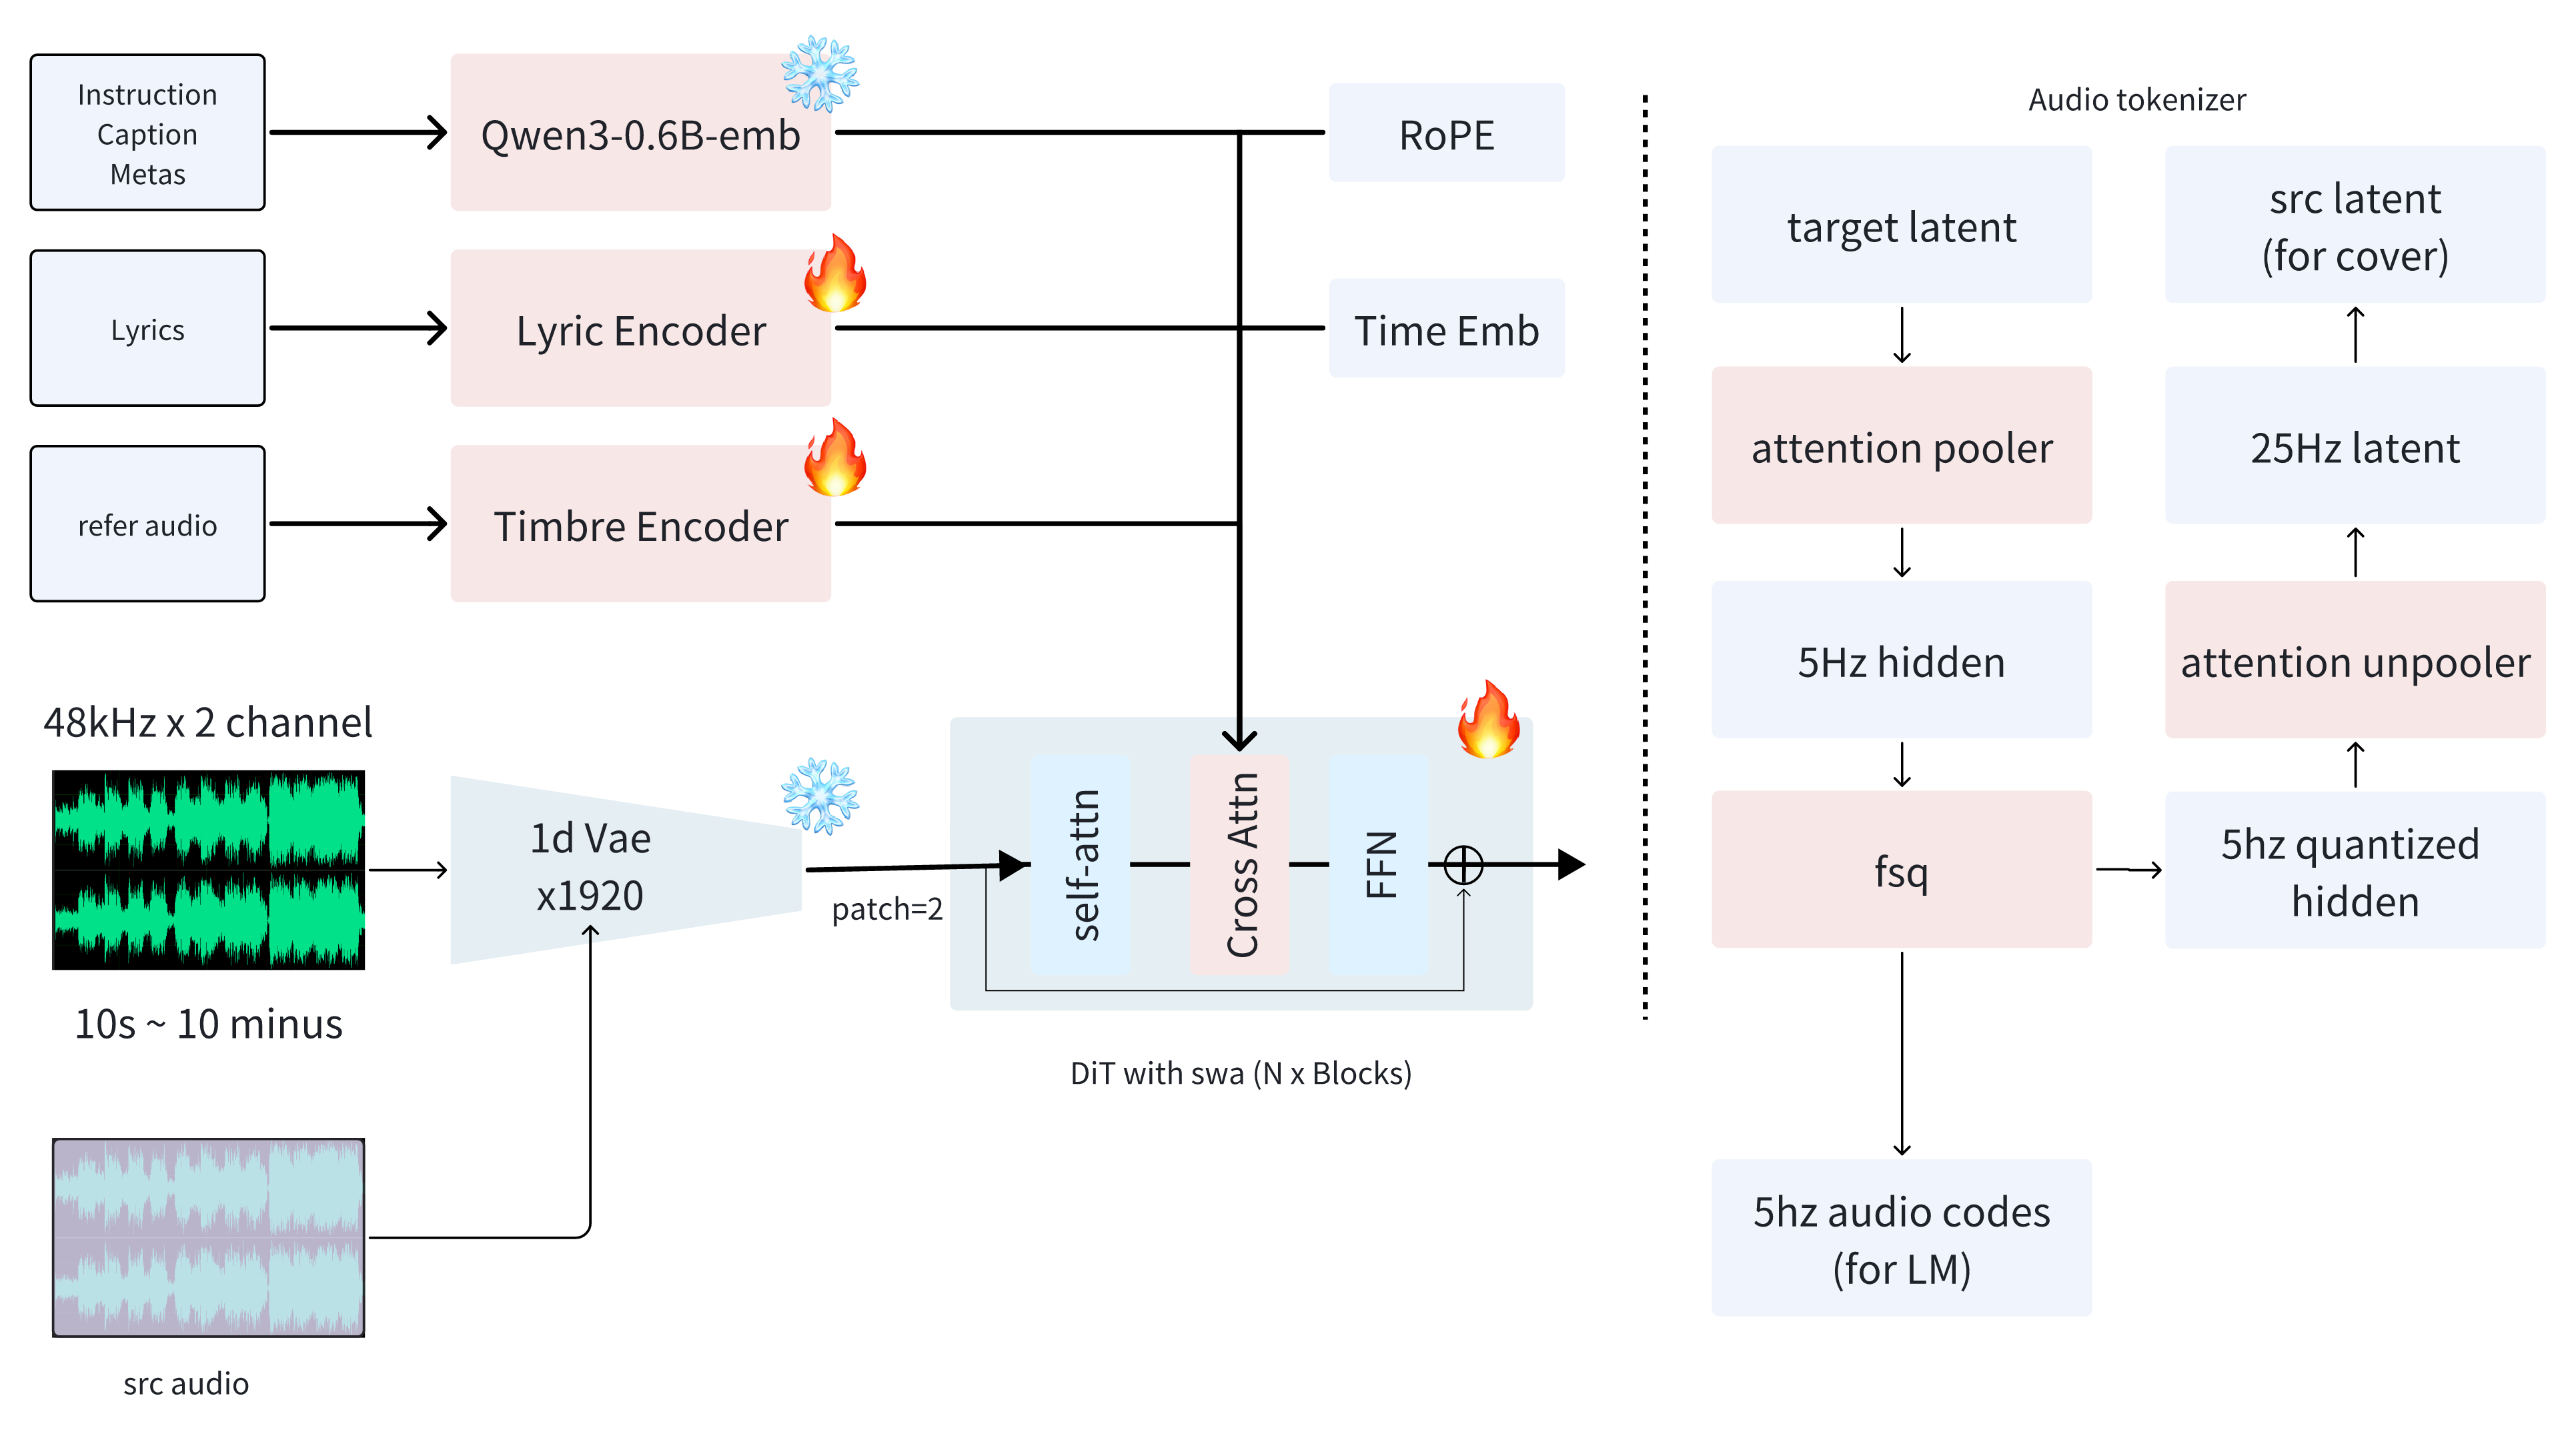
Key points ACE-Step 1.5, released on January 28, 2026, is an open-source music generation model jointly developed by ACE Studio and StepFun. It generates a full song in under 2 seconds on an A100 GPU or under 10 seconds on an RTX 3090 while requiring less than 4GB of VRAM. The model uses a two-stage […]
-
KittenTTS: State-of-the-Art Voice Synthesis in Under 25 MB
Key points KittenTTS was released on February 19, 2026 by KittenML as an open-source text-to-speech model that fits in under 25 MB. Its smallest configuration uses 14–15 million parameters and runs entirely on CPUs without any GPU requirement. It ships in three variants: Nano at 14–15M parameters and about 25 MB INT8, Micro at 40M […]
-
Voxtral Transcribe 2: Mistral’s Open Real-Time Speech-to-Text
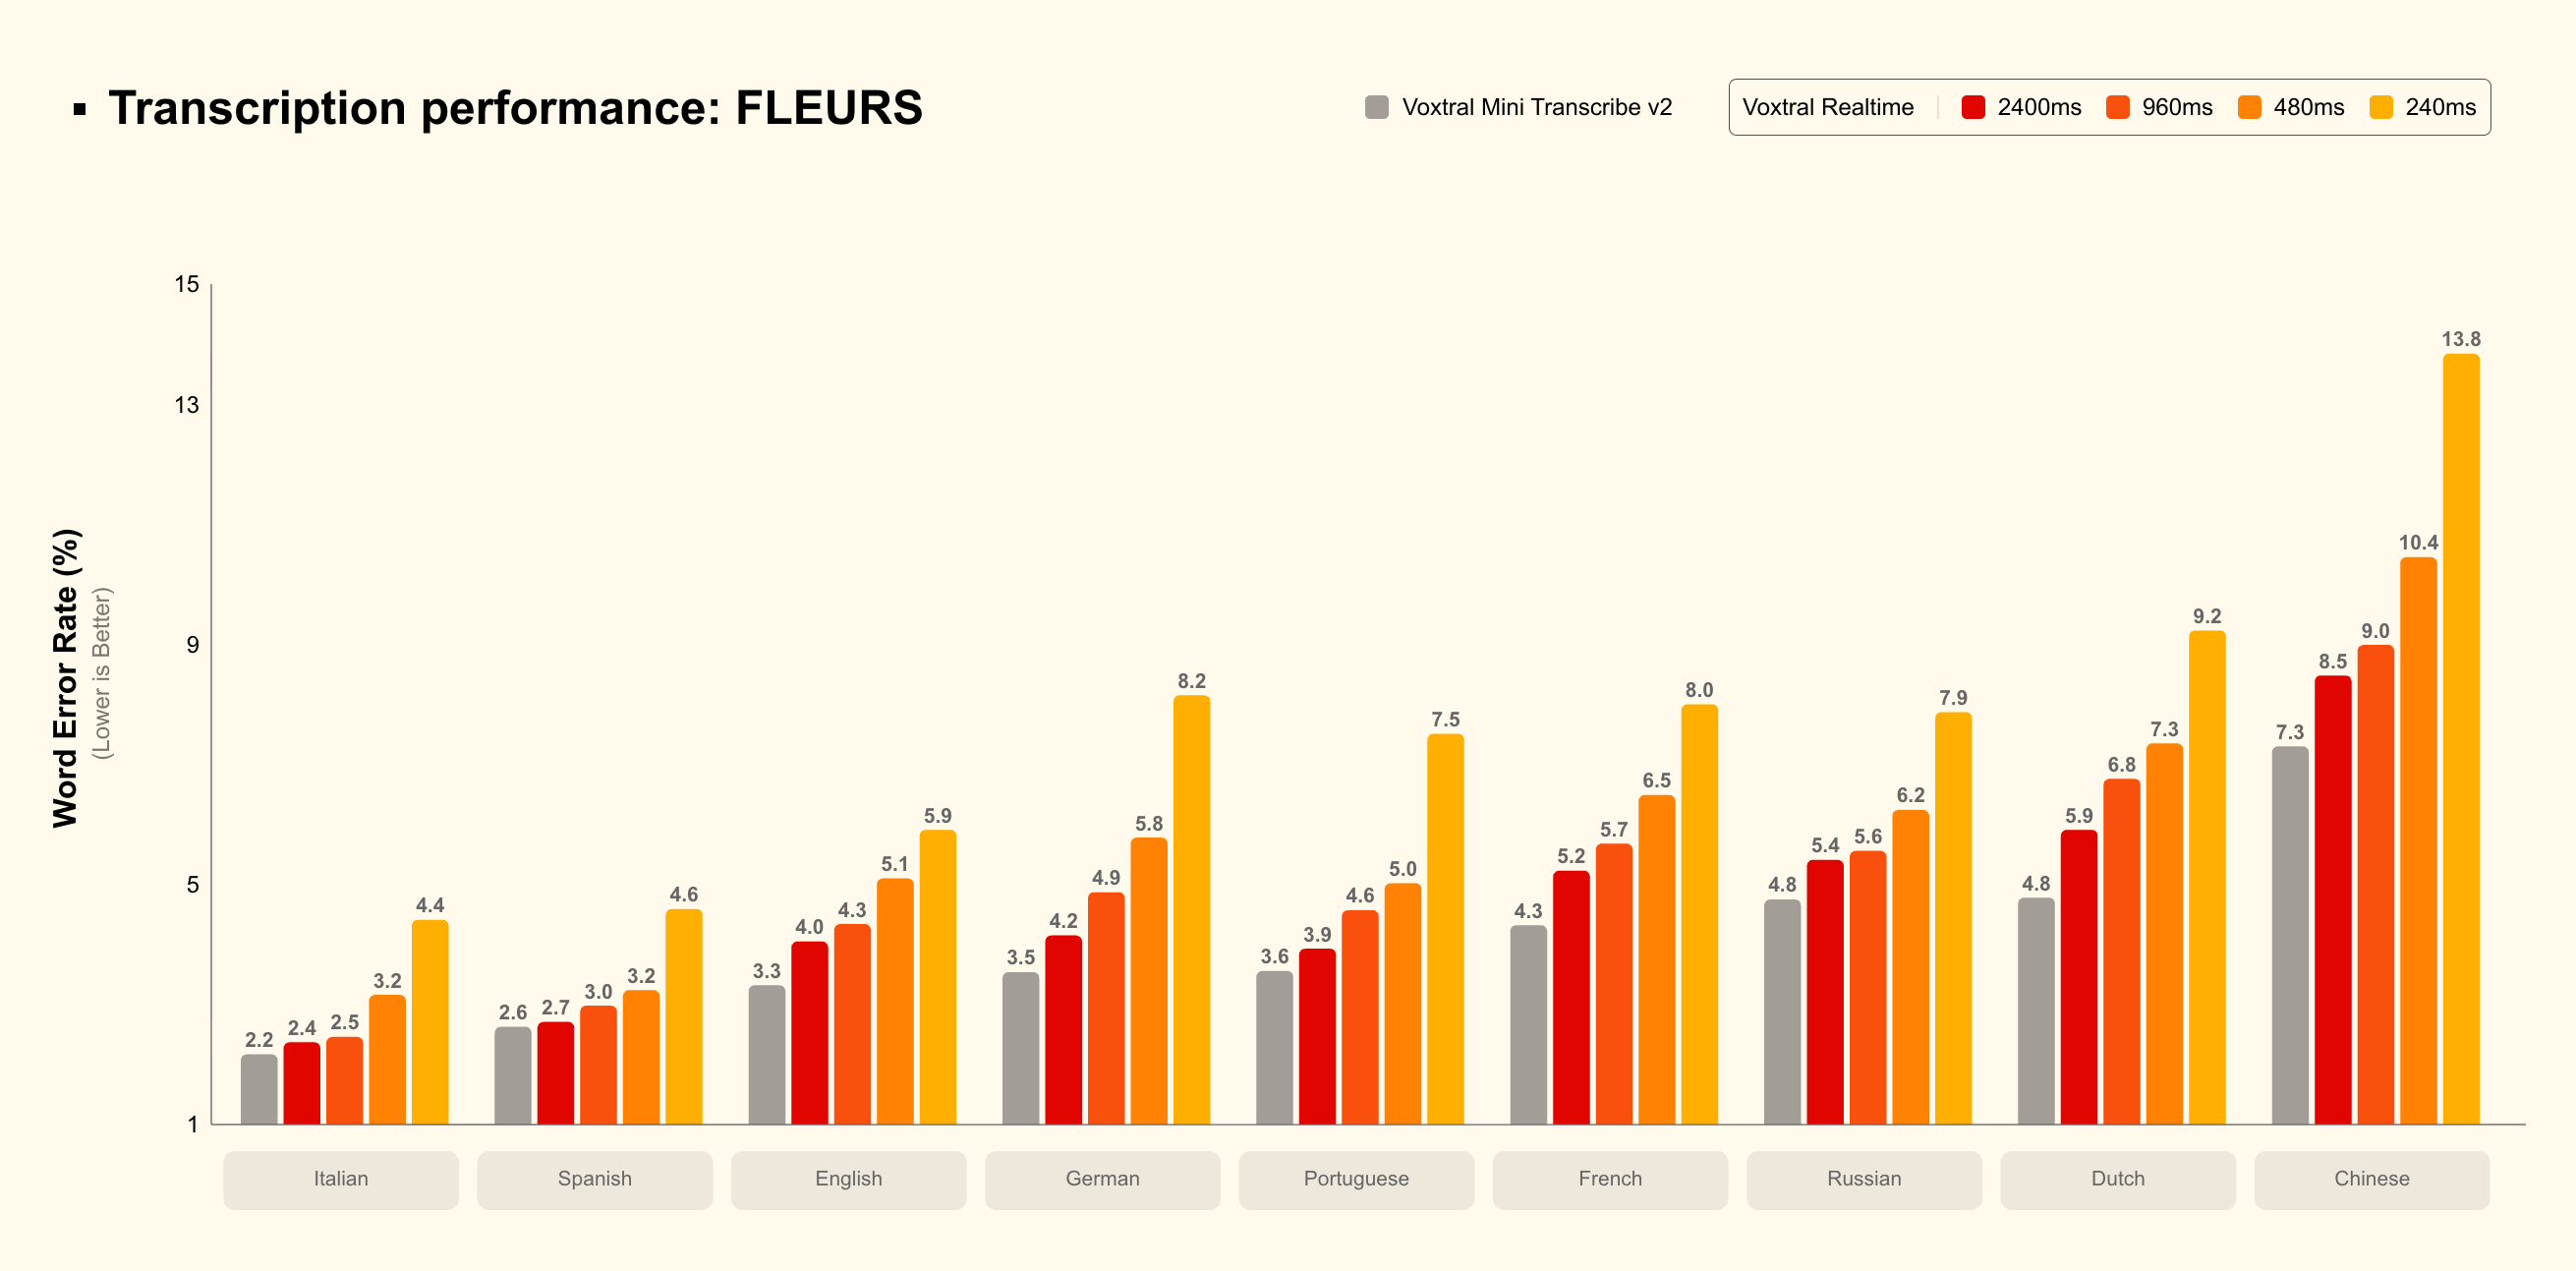
Key points On February 4, 2026, Mistral AI launched Voxtral Transcribe 2, a dual-model family with a high-accuracy batch transcription model and an open-weights real-time model. Mistral’s batch transcription model, Voxtral Mini Transcribe V2, achieves approximately 4% word error rate on the FLEURS benchmark, outperforming GPT-4o mini, Gemini 2.5 Flash, AssemblyAI Universal and Deepgram Nova […]
-
📢 Qwen3‑TTS — Open‑Source Text‑to‑Speech (TTS) Family
Qwen3‑TTS is a new open‑source suite of advanced text‑to‑speech models released by Alibaba’s Qwen team. It brings cutting‑edge speech synthesis capabilities — including voice cloning, voice design, and multilingual generation — to developers, researchers, and creators. (qwen.ai) Key points Qwen3-TTS is a new open-source suite of advanced text-to-speech models released by Alibaba’s Qwen team, bringing […]
-
🎵 HeartMuLa: A Family of Open-Source Music Foundation Models
HeartMuLa is an open-source suite of AI models focused on music understanding and generation. It’s designed to help researchers and creators synthesize high-quality music using rich user prompts such as lyrics, style descriptions, and even reference audio. (HeartMuLa) Key points HeartMuLa is an open-source suite of AI models focused on music understanding and generation. It […]
-
Pocket TTS
Pocket TTS is a 100-million-parameter open-source text-to-speech (TTS) model developed by Kyutai that runs efficiently on CPUs in real time and supports high-quality voice cloning. (eWeek) Key points Pocket TTS is a 100-million-parameter open-source text-to-speech model developed by Kyutai. It achieves faster-than-real-time performance, with about 6× real-time throughput on standard hardware such as a MacBook […]
-
Maya1: Advancements in Text-to-Speech Technology, Faster Models for Enhanced User Experience
Key points The article describes a new text-to-speech model called FasterMaya1TTS that is said to generate 50 seconds of natural-sounding audio in record time. It says the model addresses long-standing challenges in latency and efficiency, making real-time applications more viable. Listed features include reduced processing time without sacrificing quality, high fidelity with human-like intonation and […]