Tag: edge computing
-
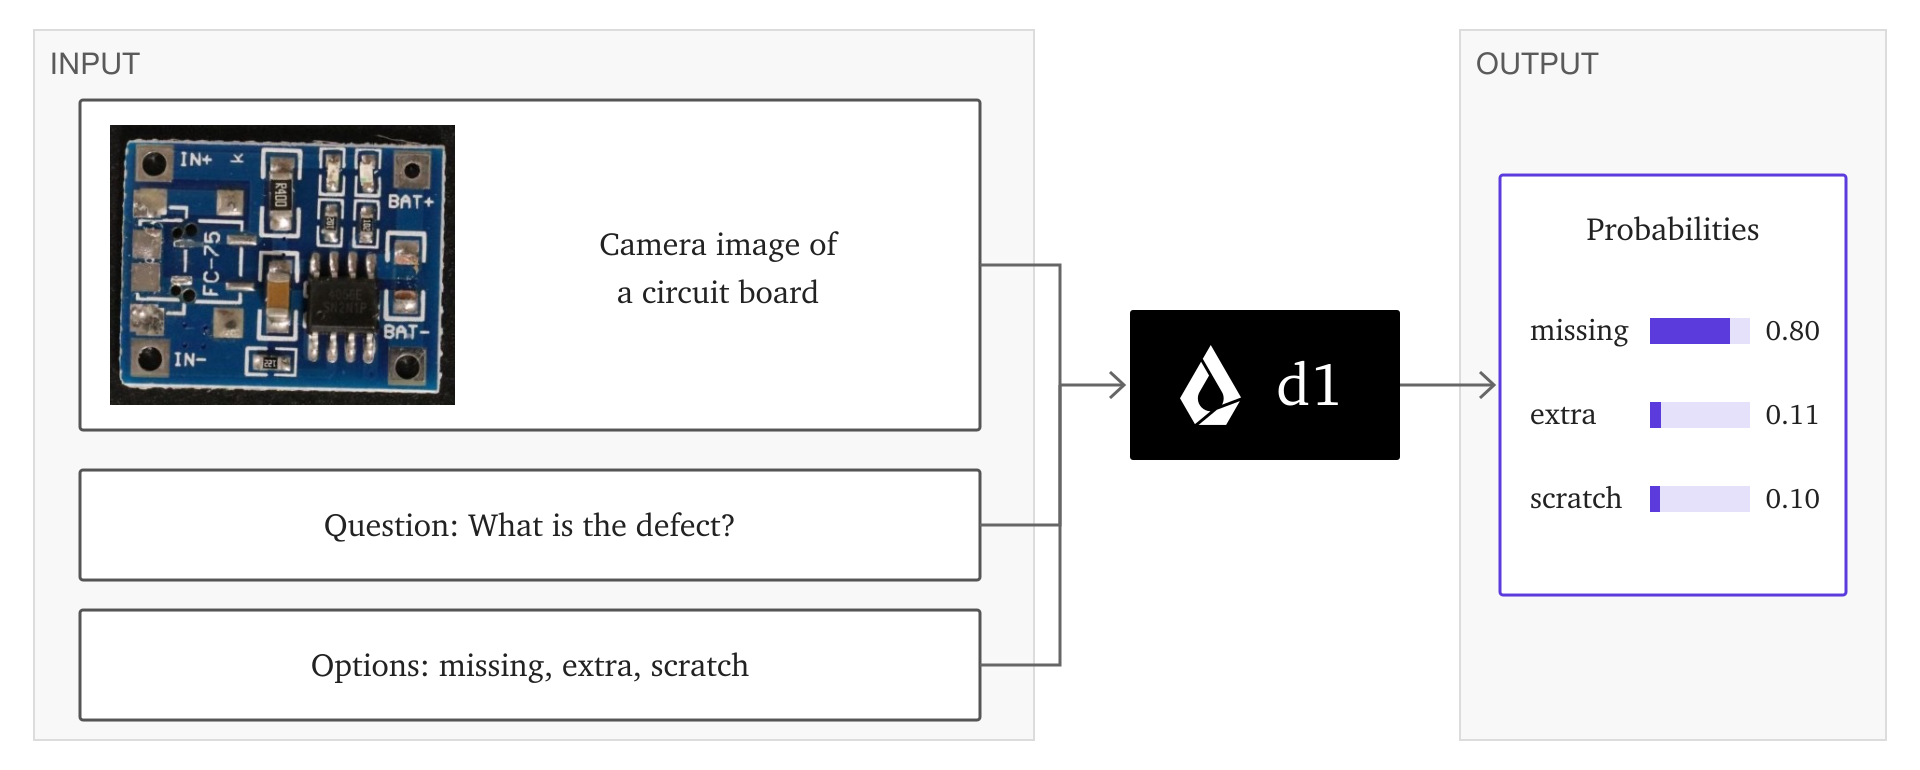
Liquid AI Releases Open-Weight d1 Decision Models for the Edge
On October 7, 2026, Liquid AI released two open-weight “decision models”: d1-3B and d1-omni-600M. Unlike the generative Liquid Foundation Models (LFMs) they are built from, neither writes text. Given a state — text, JSON, one or more images, or, for the smaller model, a voice clip of up to 30 seconds — plus a set […]
-
Liquid AI’s LFM2-VL-450M: Vision-Language AI in Half a Billion Parameters
Liquid AI has released LFM2-VL-450M, a 450-million-parameter vision-language model designed for on-device inference. Built on Liquid’s LFM2-350M language backbone and an 86M-parameter SigLIP2 NaFlex vision encoder, the model delivers 2× faster inference than comparable VLMs on GPUs while processing images at native resolution — all under an Apache 2.0 license. Intermediate Key points Liquid AI […]
-
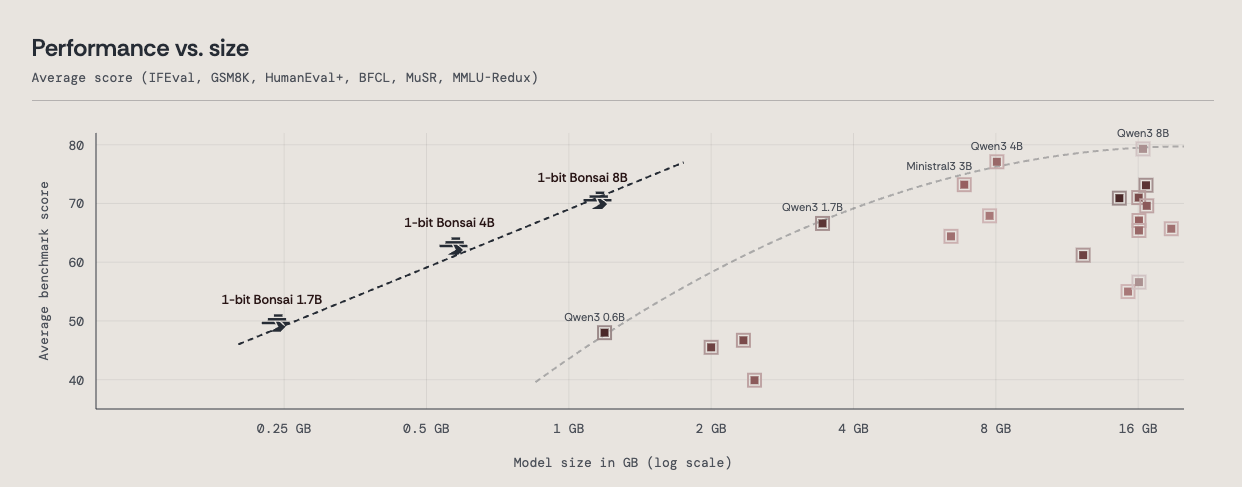
PrismML’s 1-Bit Bonsai LLMs: 8B Model in 1.15 GB
On March 31, 2026, PrismML emerged from stealth to announce 1-bit Bonsai — a family of open-weight language models the company calls the first commercially viable 1-bit LLMs. The 8B flagship fits in just 1.15 GB of memory, runs 8× faster than a standard FP16 8B model, and matches its benchmark performance. Backed by $16.25M […]
-
Reverse Engineering Apple’s Neural Engine to Train Transformers on M4
Key points A developer reverse-engineered Apple’s Neural Engine (ANE) on M4 silicon and used it to train a transformer model, which Apple has never officially supported. The open-source project bypasses CoreML and talks directly to the hardware through private APIs, reaching 9.3ms per training step at 1.78 TFLOPS sustained on an M4 Mac Mini running […]
-
Qwen 3.5 Small Models: 9B Parameters That Beat 120B
Key points On March 2, 2026, Alibaba’s Qwen team completed the Qwen 3.5 family with four small dense models of 0.8B, 2B, 4B, and 9B parameters for on-device and edge deployment. All four models are open-weight under Apache 2.0 and available on Hugging Face and ModelScope. Qwen3.5-9B outperforms models 3-13 times its size across language, […]
-
KittenTTS: State-of-the-Art Voice Synthesis in Under 25 MB
Key points KittenTTS was released on February 19, 2026 by KittenML as an open-source text-to-speech model that fits in under 25 MB. Its smallest configuration uses 14–15 million parameters and runs entirely on CPUs without any GPU requirement. It ships in three variants: Nano at 14–15M parameters and about 25 MB INT8, Micro at 40M […]
-
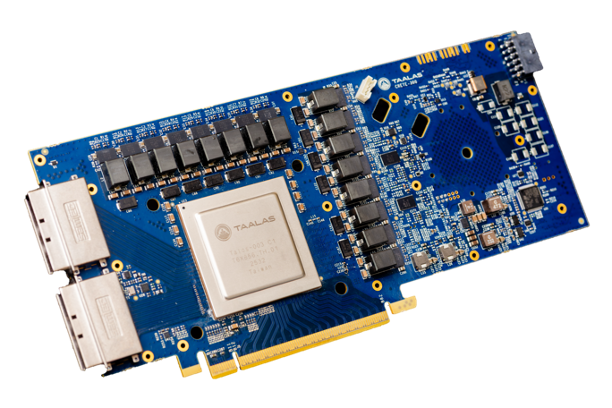
Taalas HC1: Hardwiring Llama 3.1 Into Silicon for 17,000 Tokens/Second
Key points On February 21, 2026, Toronto-based startup Taalas unveiled the HC1, a custom ASIC that hard-codes Meta’s Llama 3.1 8B language model directly into silicon. Taalas says the HC1 delivers up to 17,000 tokens per second per user, roughly ten times faster than today’s best GPU-based solutions, at a fraction of the cost and […]
-
Google AI Edge Gallery: Exploring On-Device Generative AI on Android
Google has introduced the AI Edge Gallery, an experimental Android application that brings the capabilities of Generative AI directly to users’ devices. This app allows users to experience and evaluate on-device machine learning (ML) and Generative AI use cases without the need for an internet connection once models are loaded.(YouTube, GitHub) Key points Google introduced […]