Tag: inference
-
DLoop: Looped Speculative Decoding Cuts Target-Model Passes
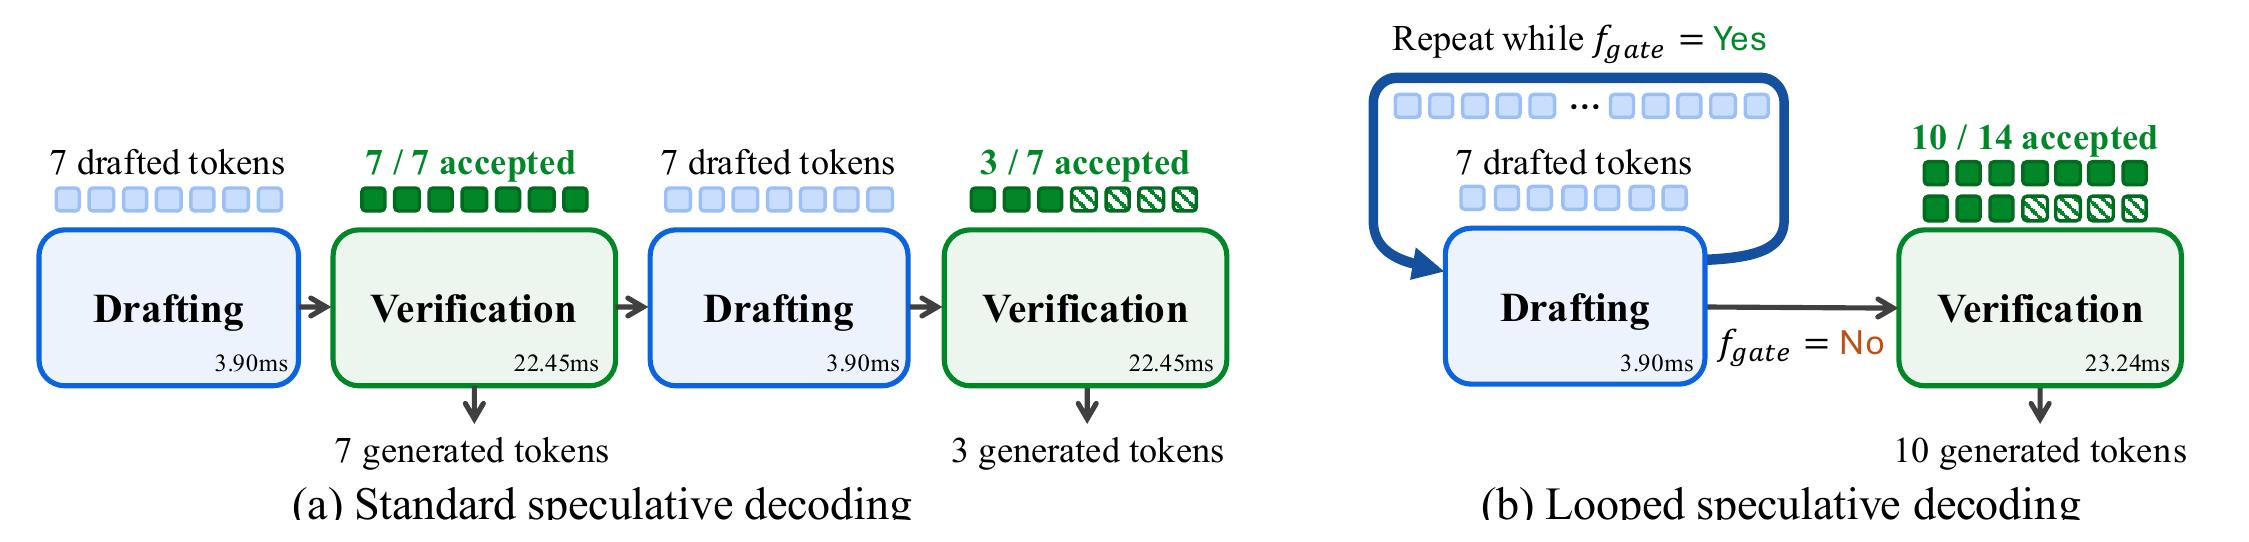
NAVER AI Lab has proposed DLoop, a change to speculative decoding that lets a single verification pass cover several rounds of drafting instead of just one. In a preprint posted to arXiv on October 6, 2026, the team reports wall-clock speedups 5 to 41 percent higher than the draft models it builds on — EAGLE-3, […]
-
Liquid AI Releases Open-Weight d1 Decision Models for the Edge
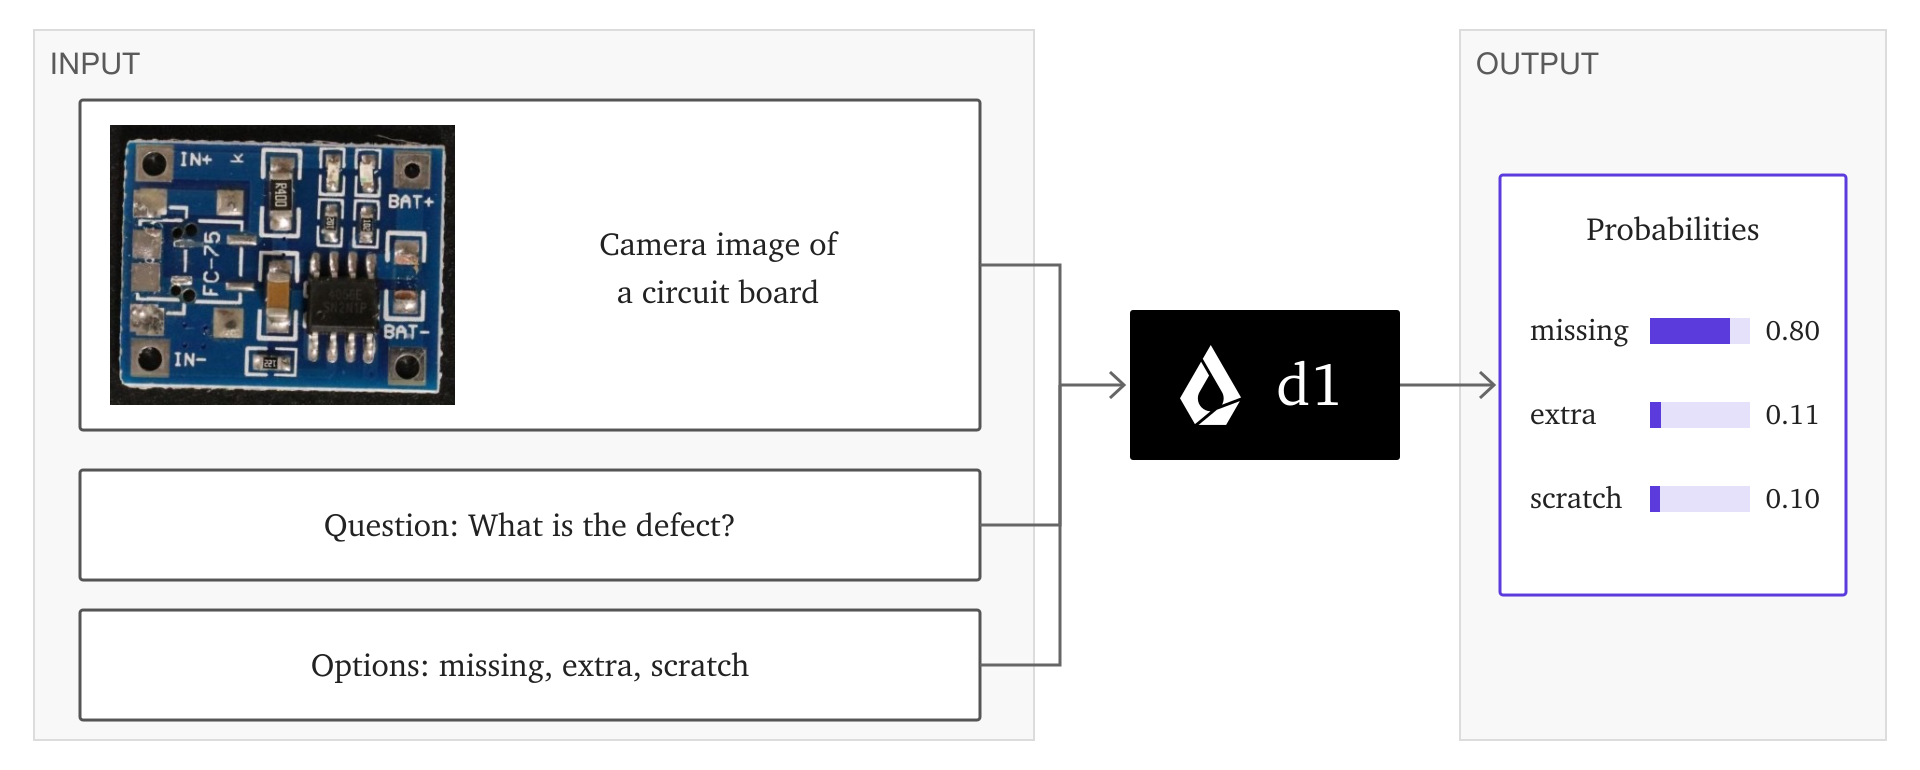
On October 7, 2026, Liquid AI released two open-weight “decision models”: d1-3B and d1-omni-600M. Unlike the generative Liquid Foundation Models (LFMs) they are built from, neither writes text. Given a state — text, JSON, one or more images, or, for the smaller model, a voice clip of up to 30 seconds — plus a set […]
-
NVIDIA RTX PRO 5500 Blackwell: 5090 Compute, 84 GB, Built for Racks
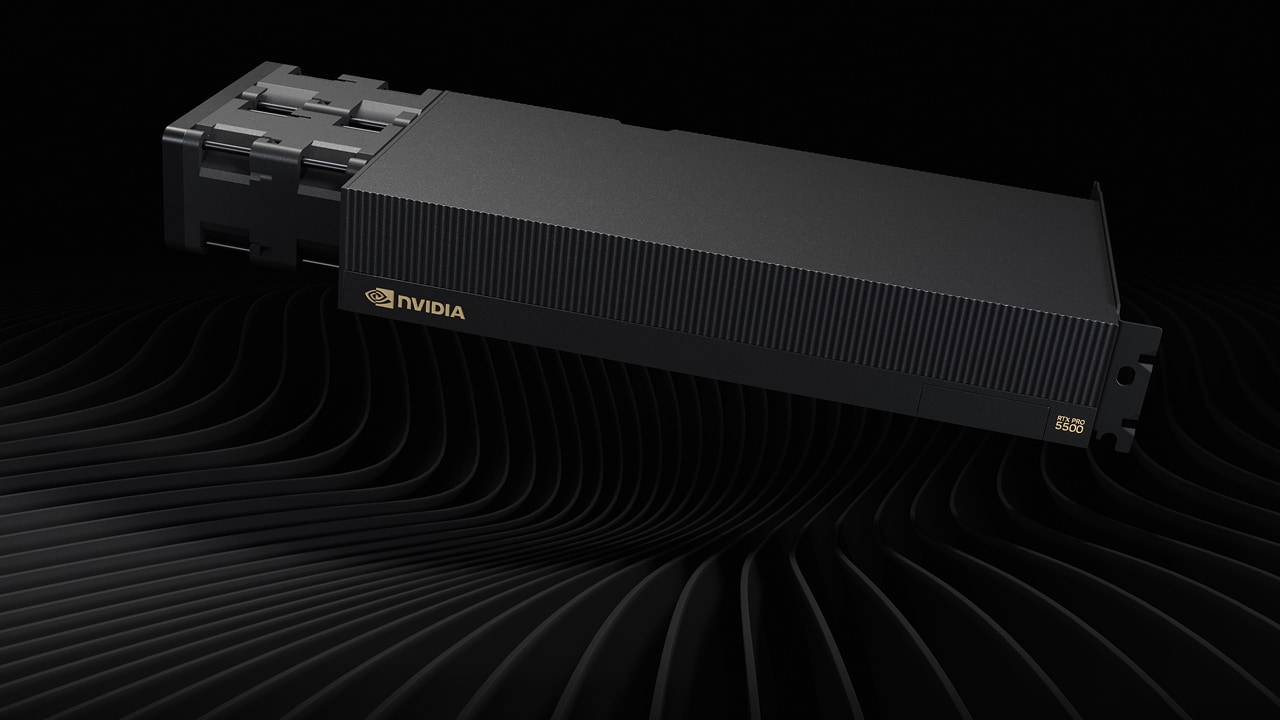
NVIDIA has added the RTX PRO 5500 Blackwell Workstation Edition to its professional GPU lineup. Product listings went up on September 14, 2026. The card pairs the same 21,760 CUDA cores as the consumer GeForce RTX 5090 with 84 GB of ECC GDDR7 memory, 2.6 times the 5090’s 32 GB, and draws up to 600 […]
-
AMD Acquires Taalas, the Startup Etching LLMs Into Silicon
On August 6, 2026, AMD announced a definitive agreement to acquire Taalas — the Toronto startup whose chips abandon the idea of loading a model from memory altogether, and instead etch its weights permanently into the transistors themselves. Financial terms were not disclosed. The deal is subject to regulatory approval and is expected to close […]
-
NInfer: 700 tok/s on One RTX 5090, With a Rare Honest Audit
NInfer is a from-scratch C++/CUDA inference engine that runs exactly two model checkpoints on exactly one GPU. Published under Apache 2.0 and first committed on June 26, 2026, the project by developer Neroued supports only Qwen3.6-27B and Qwen3.6-35B-A3B, only on an NVIDIA GeForce RTX 5090, and only one request at a time. In return for […]
-
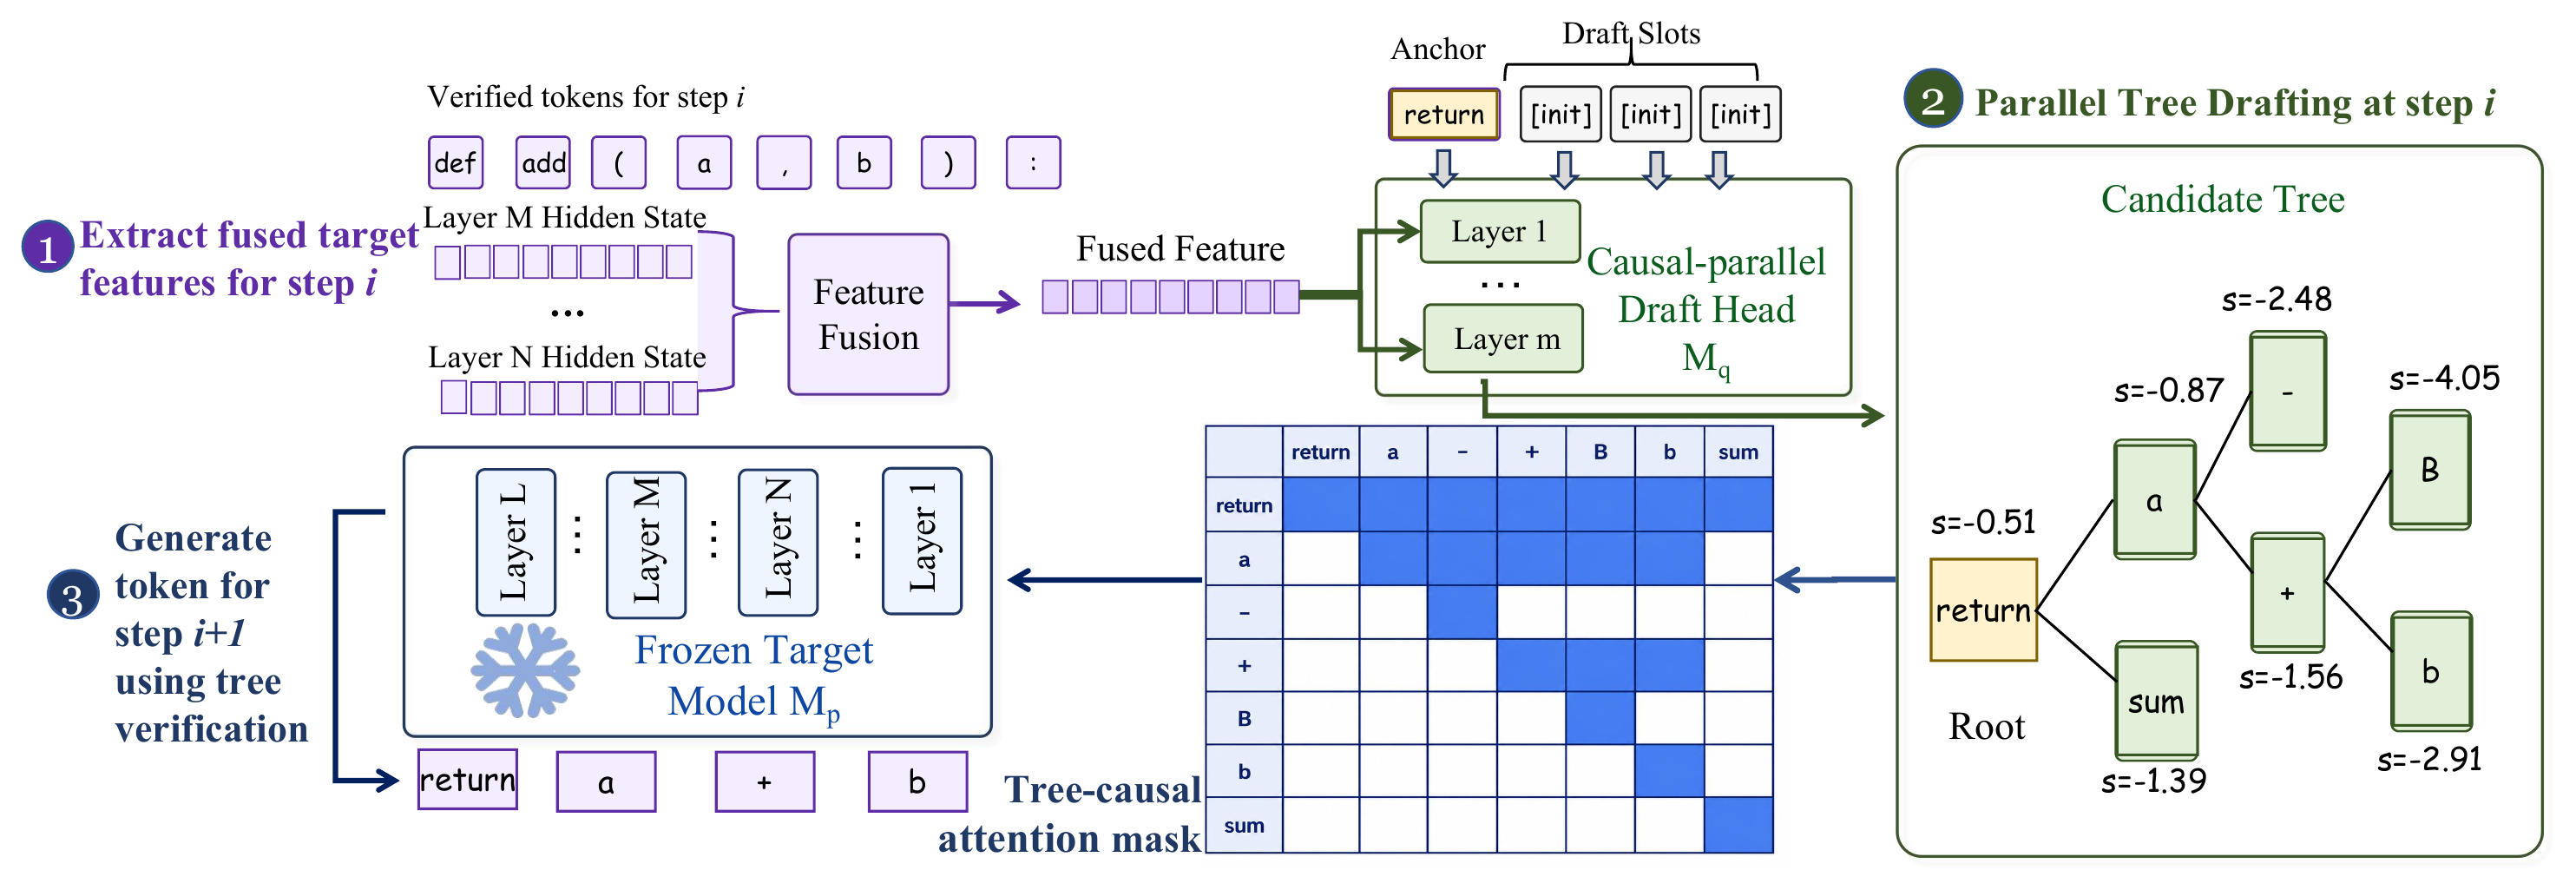
JetSpec: Causal Parallel Tree Drafting Hits 9.64x Faster LLM Inference
On June 26, 2026, researchers at UC San Diego’s Hao AI Lab released JetSpec — a speculative decoding method that accelerates large language model inference by up to 9.64× while leaving the model’s outputs unchanged. JetSpec trains a small “causal parallel draft head” on top of a frozen target model, generating a scored tree of […]
-
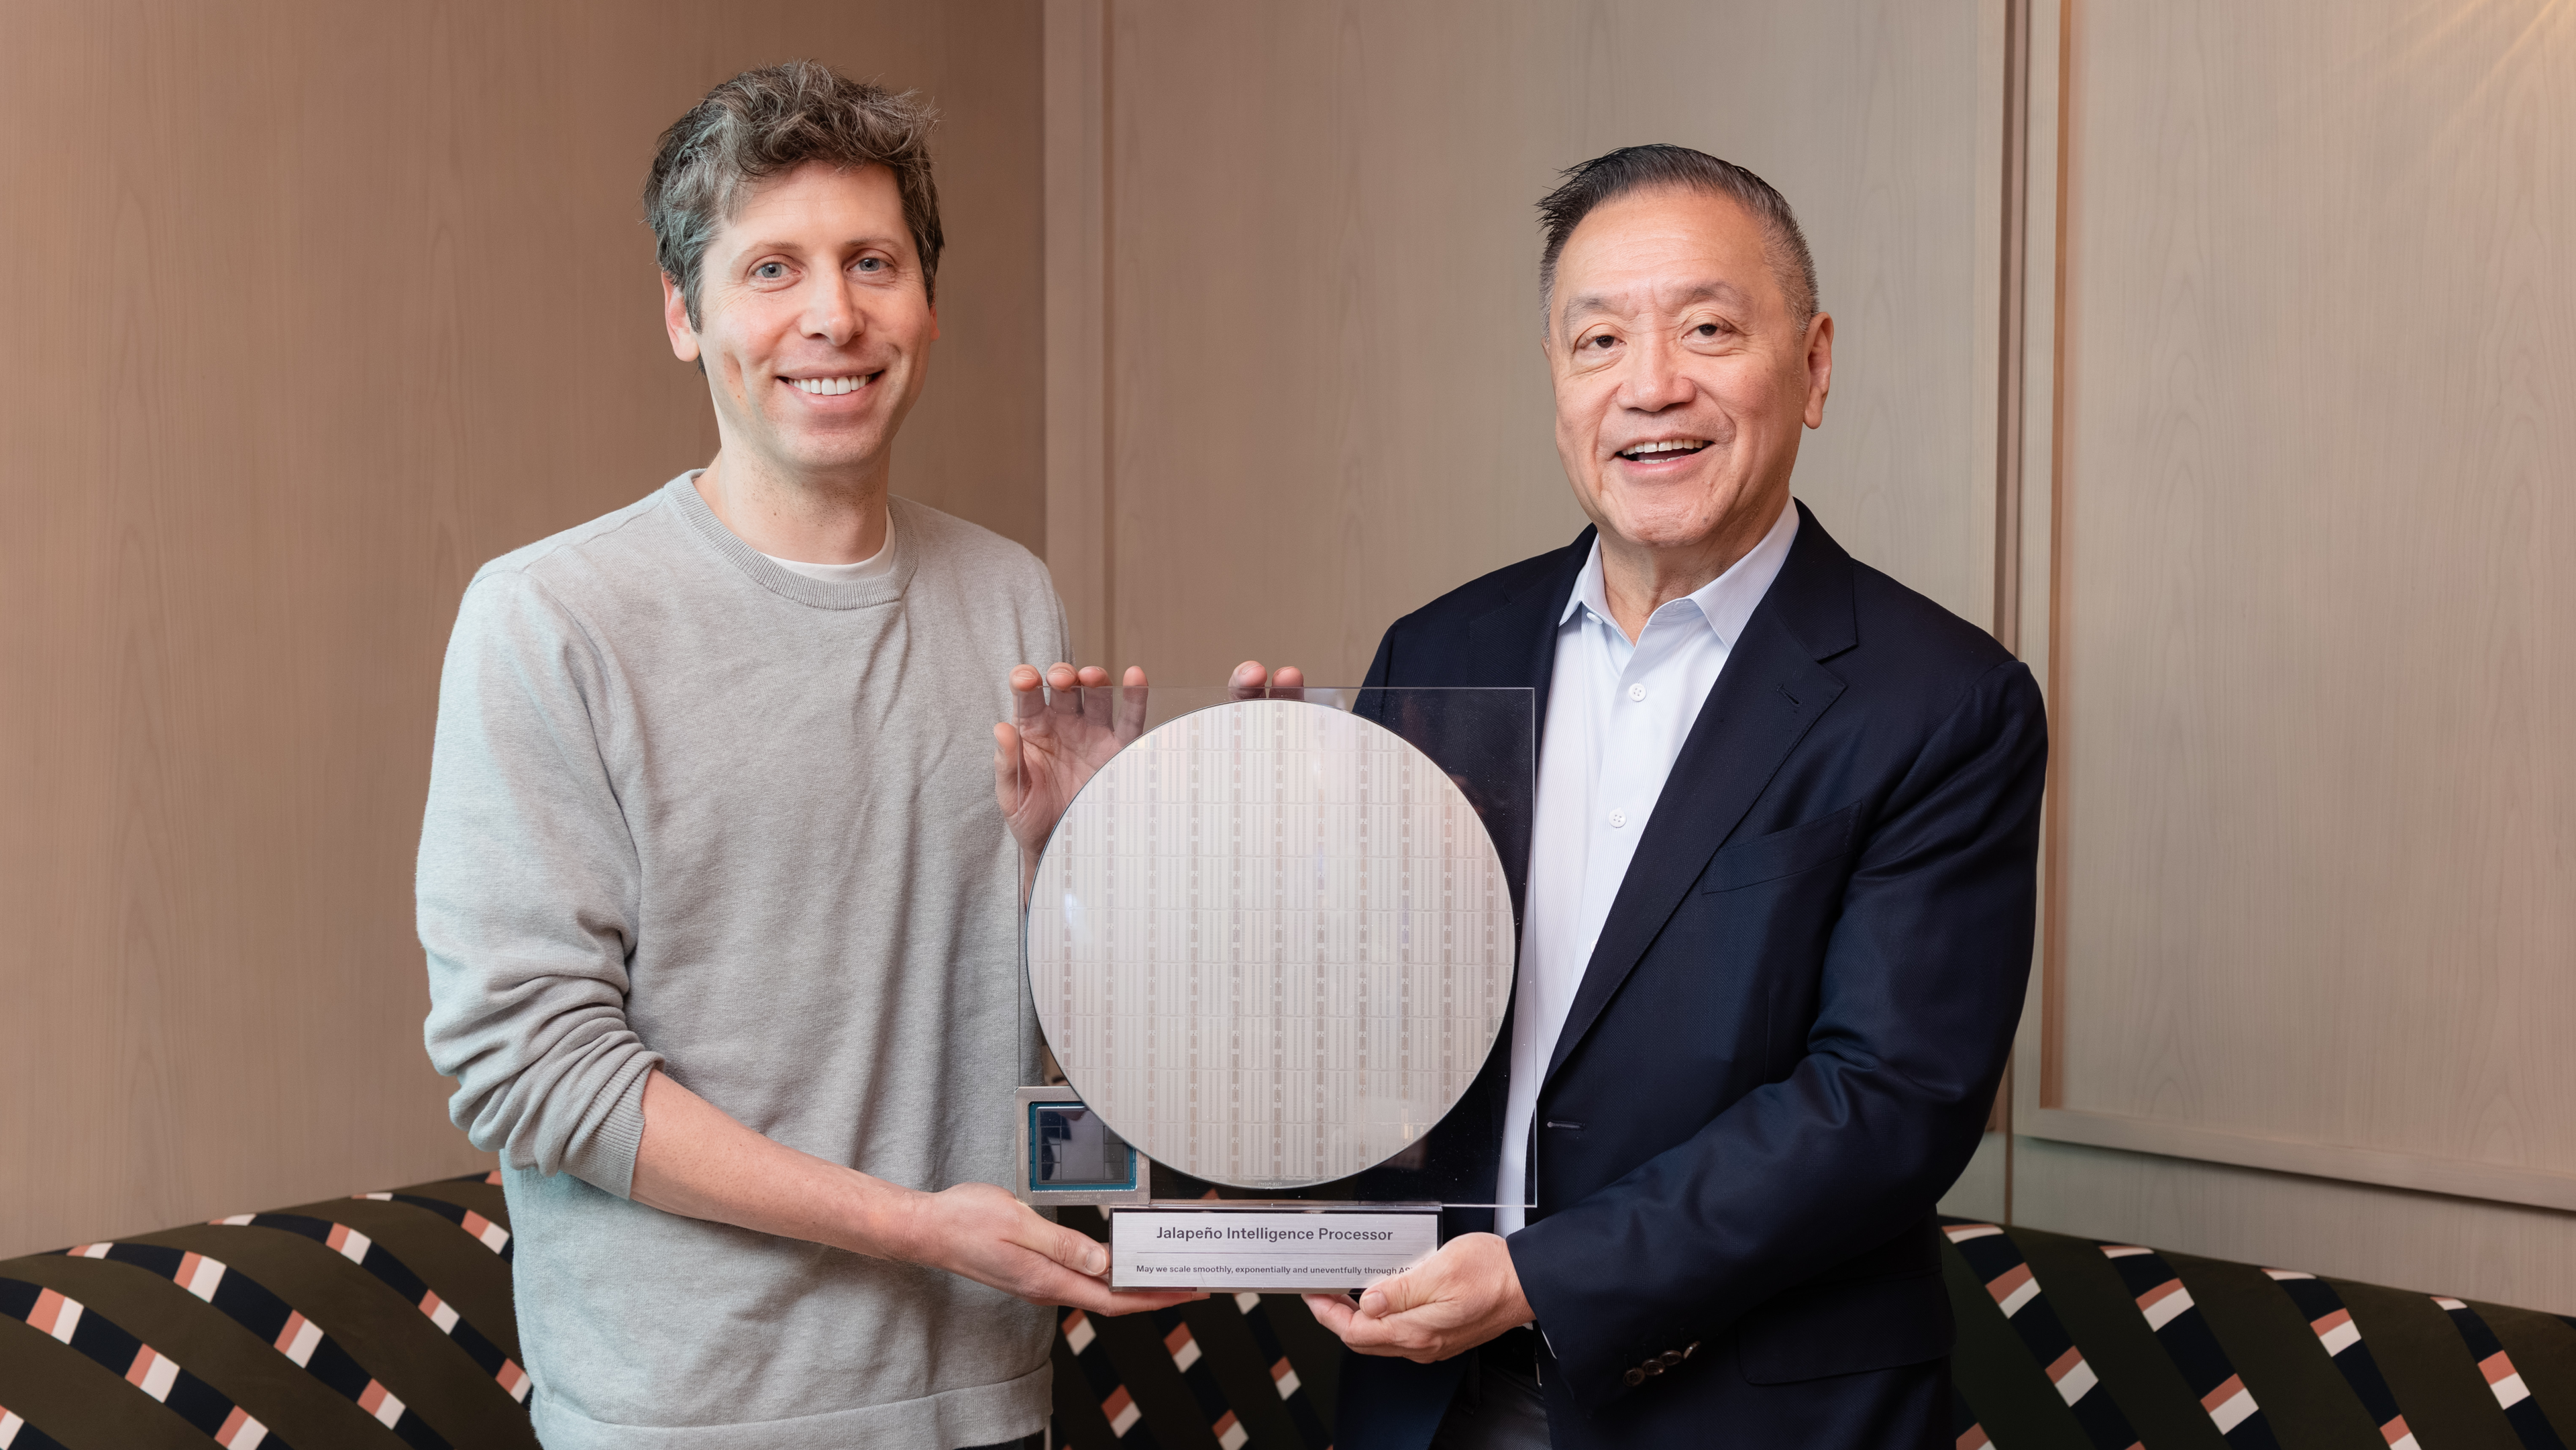
OpenAI and Broadcom Unveil Jalapeño, a Custom LLM Inference Chip
OpenAI and Broadcom on June 24, 2026 unveiled Jalapeño, OpenAI’s first custom-designed silicon — an “Intelligence Processor” built from scratch for large language model inference. The chip is the first product of the companies’ 10-gigawatt accelerator partnership announced last October, and OpenAI says it was taken from initial design to manufacturing tape-out in just nine […]
-
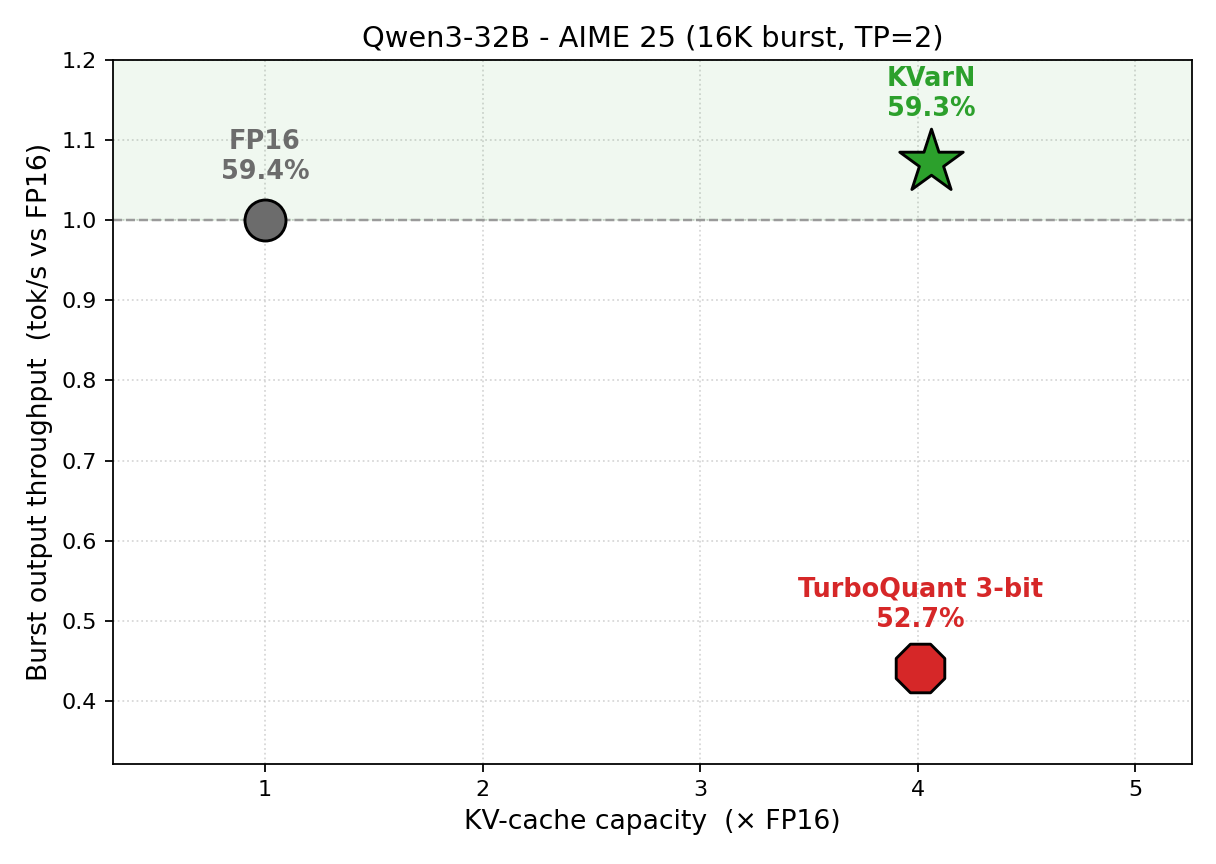
Huawei’s KVarN Hits 5x KV-Cache Capacity at FP16 Accuracy and Throughput
On June 2, 2026, Huawei researchers released KVarN — a variance-normalized KV-cache quantization backend for vLLM that breaks the long-standing tradeoff between cache compression and inference speed. KVarN delivers 3–5× more context capacity at 2-bit precision while keeping FP16-level accuracy and beating FP16 throughput, all behind a single vLLM flag with no calibration. It ships […]
-
NVIDIA Star Elastic: One Checkpoint, Three Reasoning Models, Zero-Shot Slicing
On May 7, 2026, NVIDIA released Star Elastic — a single 30-billion-parameter reasoning checkpoint that contains two smaller production-ready models, 23B and 12B, embedded in its weights. Developers can extract the smaller variants with a one-shot slicing script, no fine-tuning required. The release introduces a “many-in-one” approach to LLM packaging that NVIDIA reports cuts post-training […]
-
Gemma 4 Gets Multi-Token Prediction Drafters: 3x Faster Inference, Same Outputs
Lead — On May 5, 2026, Google released Multi-Token Prediction (MTP) drafters for the Gemma 4 family of open models. The drafters use speculative decoding to deliver up to a 3x speedup in inference latency without changing model outputs, and they ship under the same Apache 2.0 license as the underlying models. Advanced Key points […]