Tag: Level: Advanced
-
Google Open Sources Harness2 for Self-Improving AI Agents
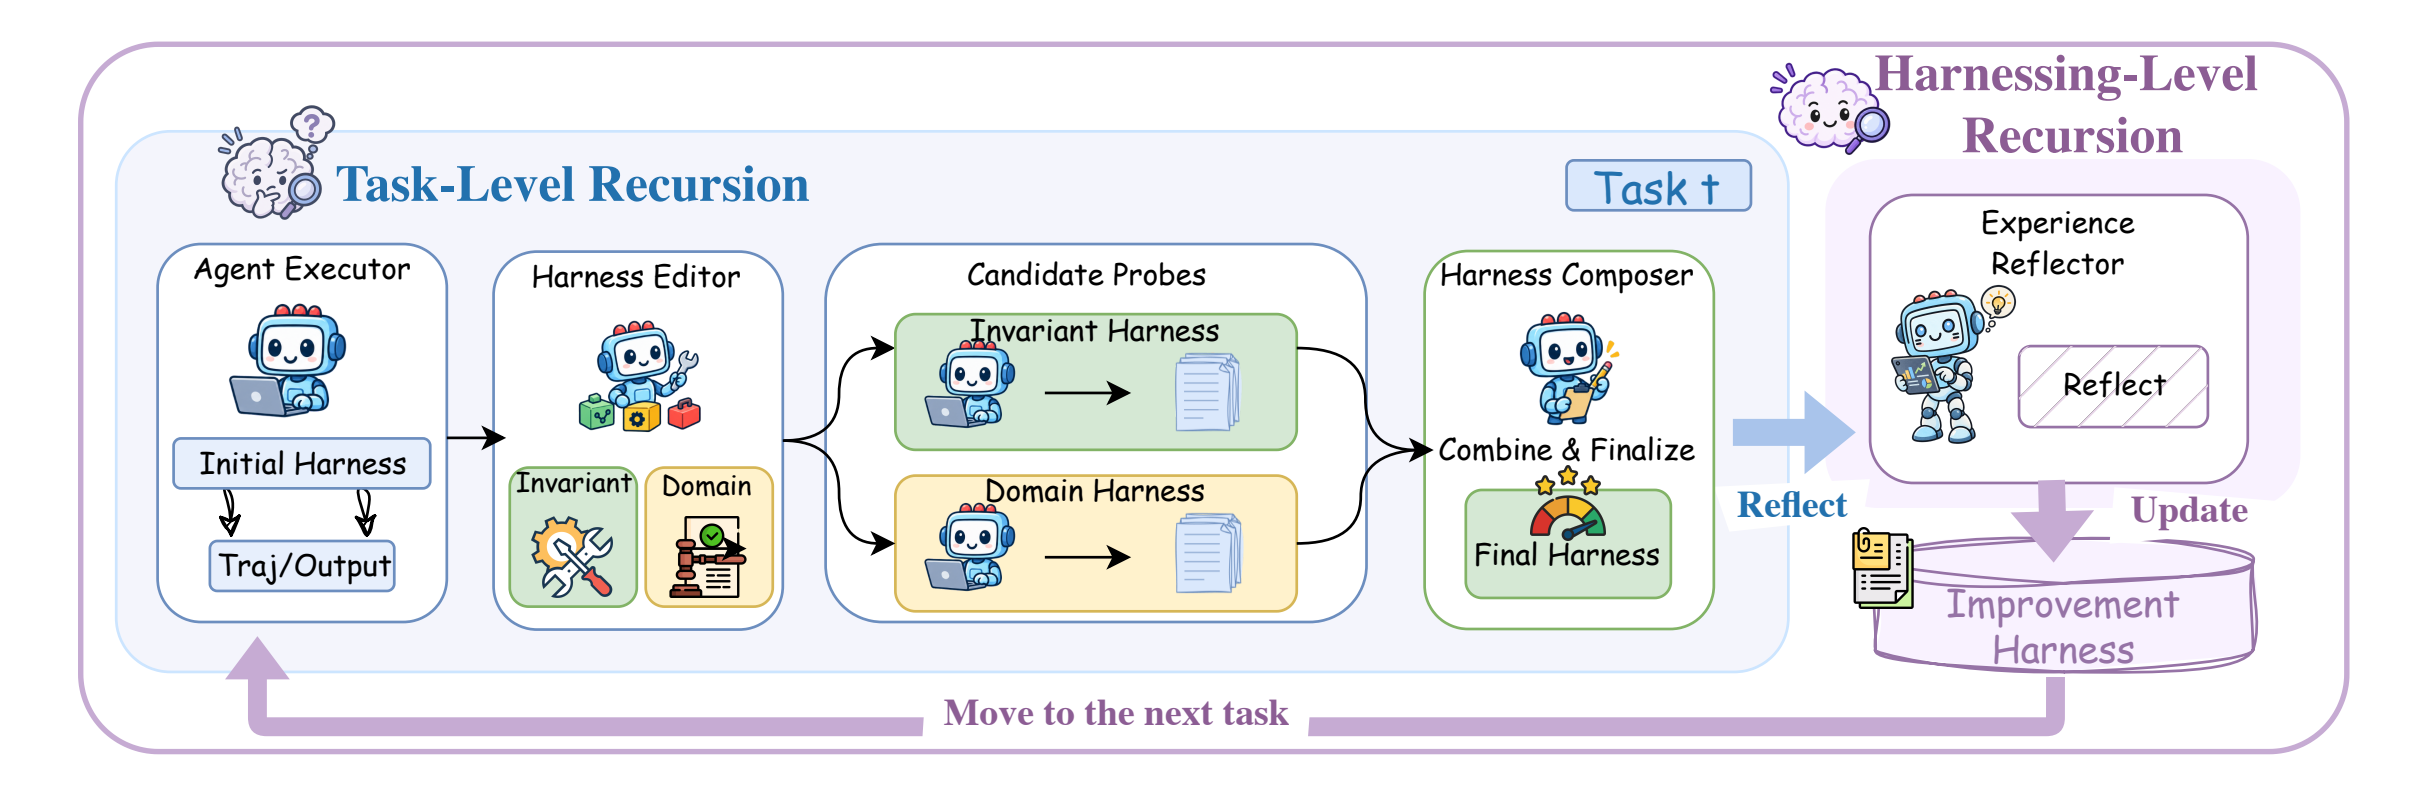
On October 9, 2026, researchers from Google Cloud AI Research and Northwestern University posted Harness²: Recursive Agent Harnessing for an Open World and released the accompanying code on GitHub under the Apache 2.0 licence. The framework improves an AI agent’s harness — the prompts, tools, memory, skills and orchestration wrapped around a model — while […]
-
DeepSeek Ships V4.1-Flash-1017: Faster Agents, Same Price
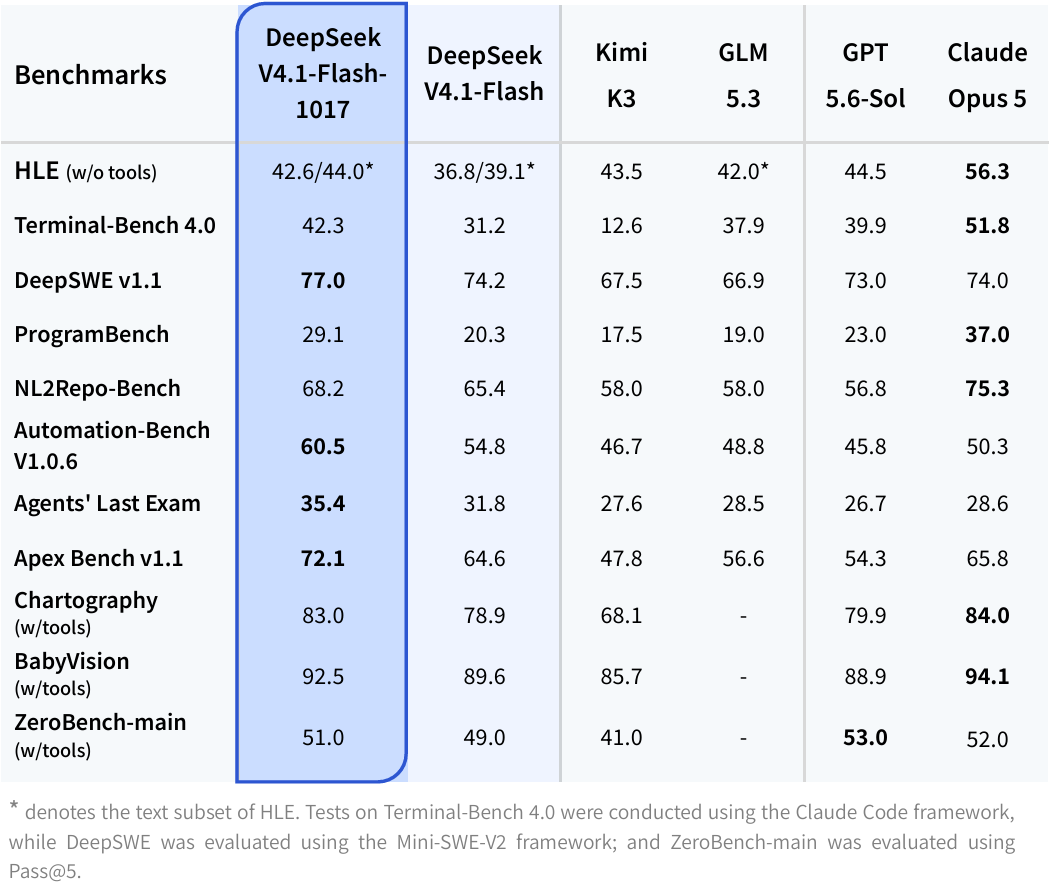
DeepSeek replaced V4.1-Flash with DeepSeek-V4.1-Flash-1017 on October 17, 2026, shipping the new checkpoint to its website, mobile app and API the same day and publishing MIT-licensed weights on Hugging Face and ModelScope. DeepSeek calls it a minor update; it improves all eleven benchmarks in the company’s comparison table, shortens outputs, and leaves API pricing unchanged. […]
-
Meta Opens Muse Spark Weights: 816B MoE, 1M Context
On October 15, 2026, Meta Superintelligence Labs released the weights for Muse Spark Open — an 816-billion-parameter sparse mixture-of-experts model that activates 42 billion parameters per token, with a 1,048,576-token context window. Meta calls it “the most capable US open-weight model to date,” and the release is as much a hardware story as a benchmark […]
-
Qwen Releases QwenGyre for Long-Horizon Agent RL Training
Alibaba’s Qwen team has detailed QwenGyre — an elastic reinforcement learning (RL) framework for training AI agents on what the authors call “extreme-long” (xLong) tasks, where a single execution spans hours, hundreds of model–environment interactions, and close to one million tokens. The paper, submitted to arXiv on September 27, 2026 and announced by the Qwen […]
-
OpenBMB Releases MiniCPM-V 4.7, Its First MoE Multimodal Model
OpenBMB released MiniCPM-V 4.7 on October 12, 2026 — the latest entry in its MiniCPM-V vision-language series and the first in that line to use a mixture-of-experts (MoE) architecture. The release ships two open-weight models under Apache 2.0: MiniCPM-V 4.7 35B-A3B and MiniCPM-V 4.7 1B. The headline claim is an efficiency one. OpenBMB describes the […]
-
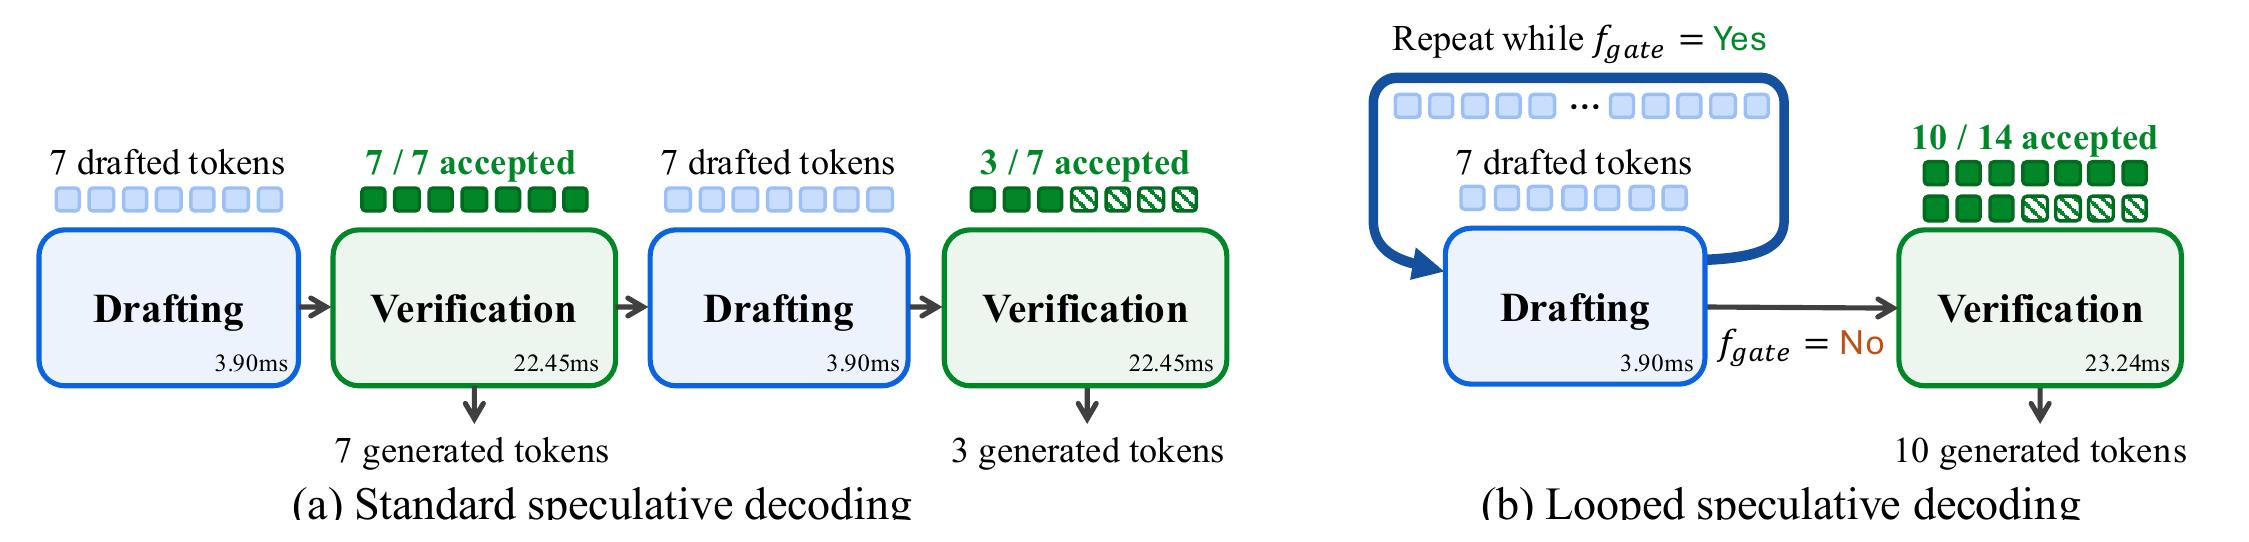
DLoop: Looped Speculative Decoding Cuts Target-Model Passes
NAVER AI Lab has proposed DLoop, a change to speculative decoding that lets a single verification pass cover several rounds of drafting instead of just one. In a preprint posted to arXiv on October 6, 2026, the team reports wall-clock speedups 5 to 41 percent higher than the draft models it builds on — EAGLE-3, […]
-
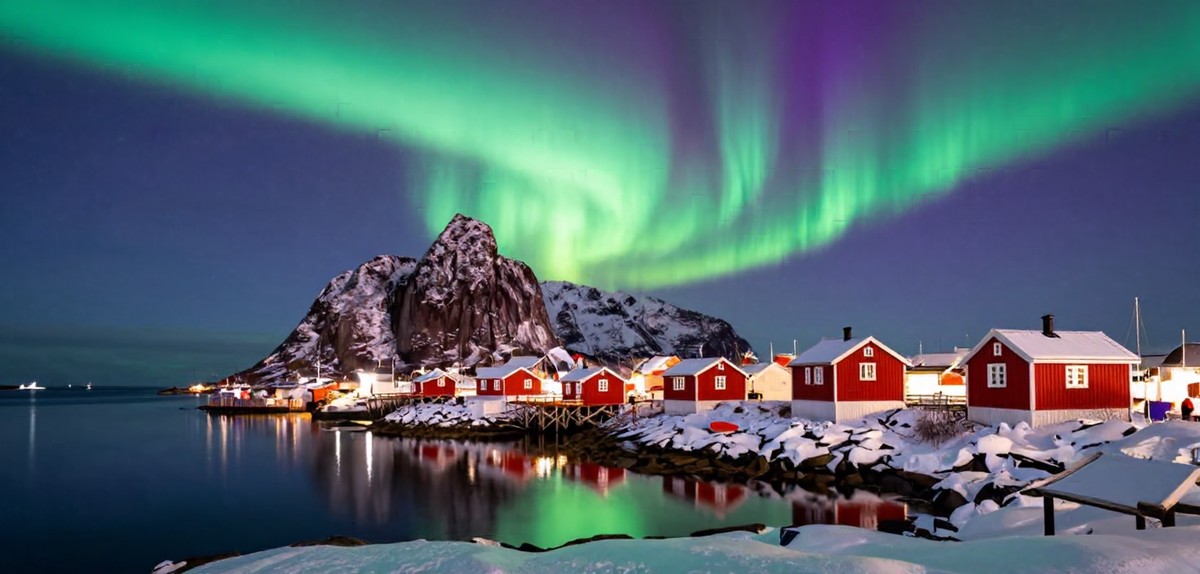
SperidLabs Releases Iris-3B, a Pixel-Space Image Model Without a VAE
Lead — On October 7, 2026, the research lab SperidLabs posted Iris-3B, a 3-billion-parameter text-to-image model that generates pictures with no VAE and no latent space: the network paints every pixel directly. The weights and training code went up on Hugging Face under the Apache 2.0 licence, and the accompanying paper reports that pixel-space generation […]
-
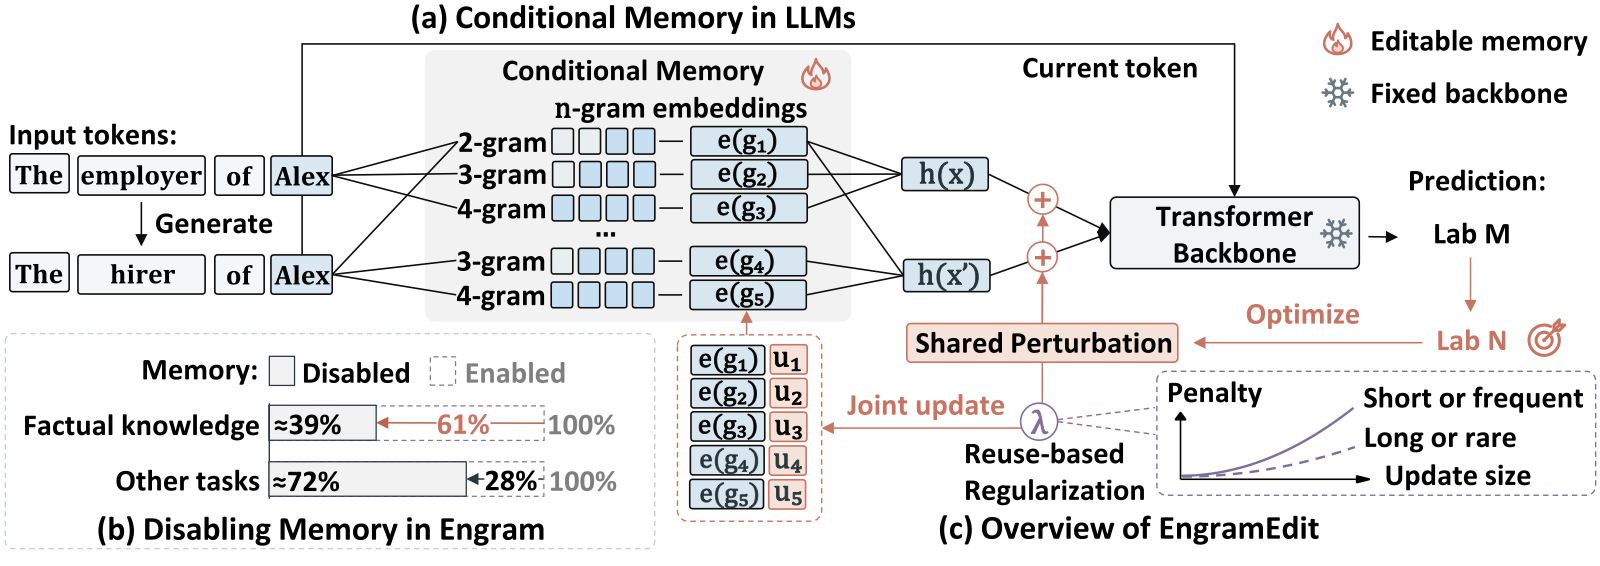
EngramEdit Rewrites LLM Facts by Editing Conditional Memory
On October 7, 2026, researchers from The Hong Kong Polytechnic University, Hangzhou Diagens Biotechnology, and the University of Science and Technology of China posted EngramEdit (arXiv:2610.10533), a method that revises facts inside a large language model by editing only its conditional memory — the n-gram lookup tables of an Engram-style architecture — while leaving the […]
-
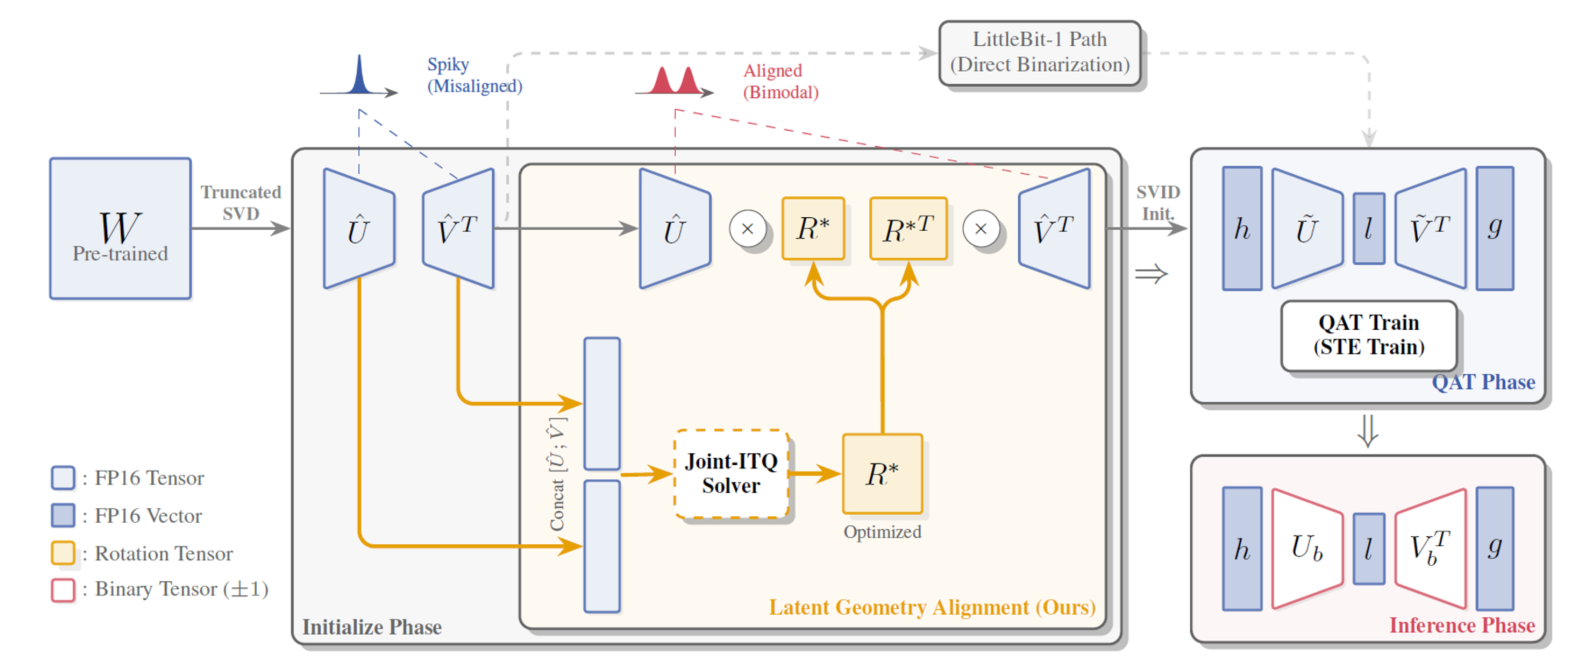
LittleBit-2: Samsung’s Sub-1-Bit LLMs via Latent Geometry Alignment
Lead — On July 23, 2026, Samsung Research published LittleBit-2, the successor to a compression method that pushes large language models below one bit per weight. Presented at ICML 2026, LittleBit-2 keeps the original LittleBit architecture from NeurIPS 2025 but changes one thing: how the compressed weights are initialized. That single change takes the method […]
-
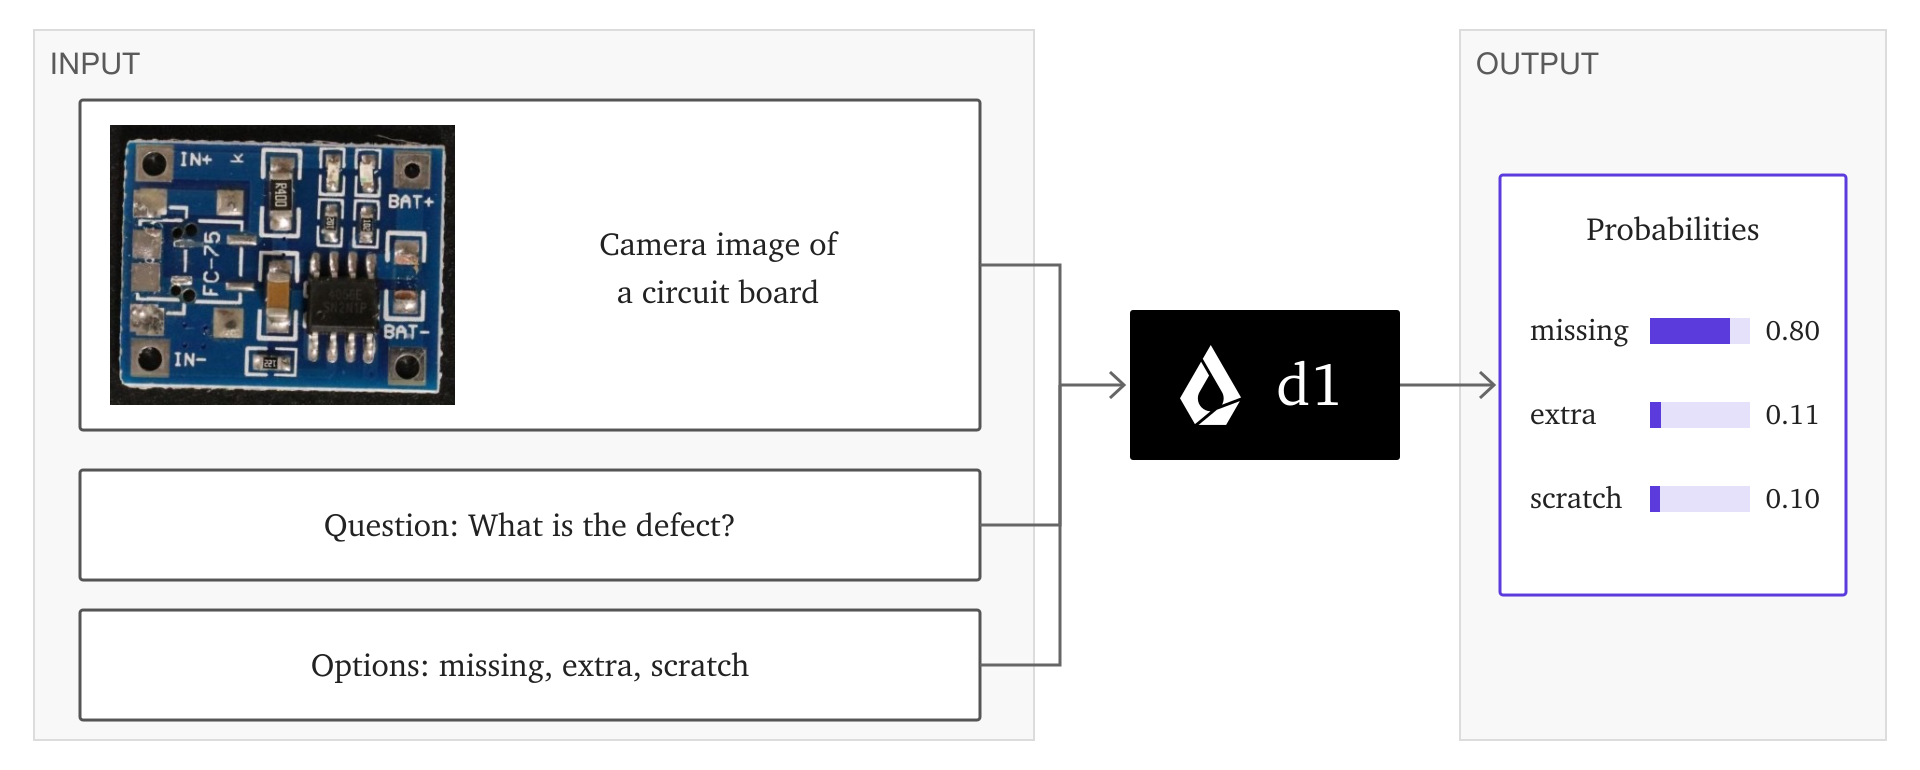
Liquid AI Releases Open-Weight d1 Decision Models for the Edge
On October 7, 2026, Liquid AI released two open-weight “decision models”: d1-3B and d1-omni-600M. Unlike the generative Liquid Foundation Models (LFMs) they are built from, neither writes text. Given a state — text, JSON, one or more images, or, for the smaller model, a voice clip of up to 30 seconds — plus a set […]