Tag: Level: Intermediate
-
OpenAI Ships Official Codex Plugin for Anthropic’s Claude Code
OpenAI has released an official plugin that embeds its Codex coding agent directly inside Anthropic’s Claude Code CLI. Announced on March 30, 2026, the open-source codex-plugin-cc plugin lets developers invoke Codex for code reviews, adversarial analysis, and task delegation — all without leaving the Claude Code terminal. The move is notable because OpenAI is deliberately […]
-
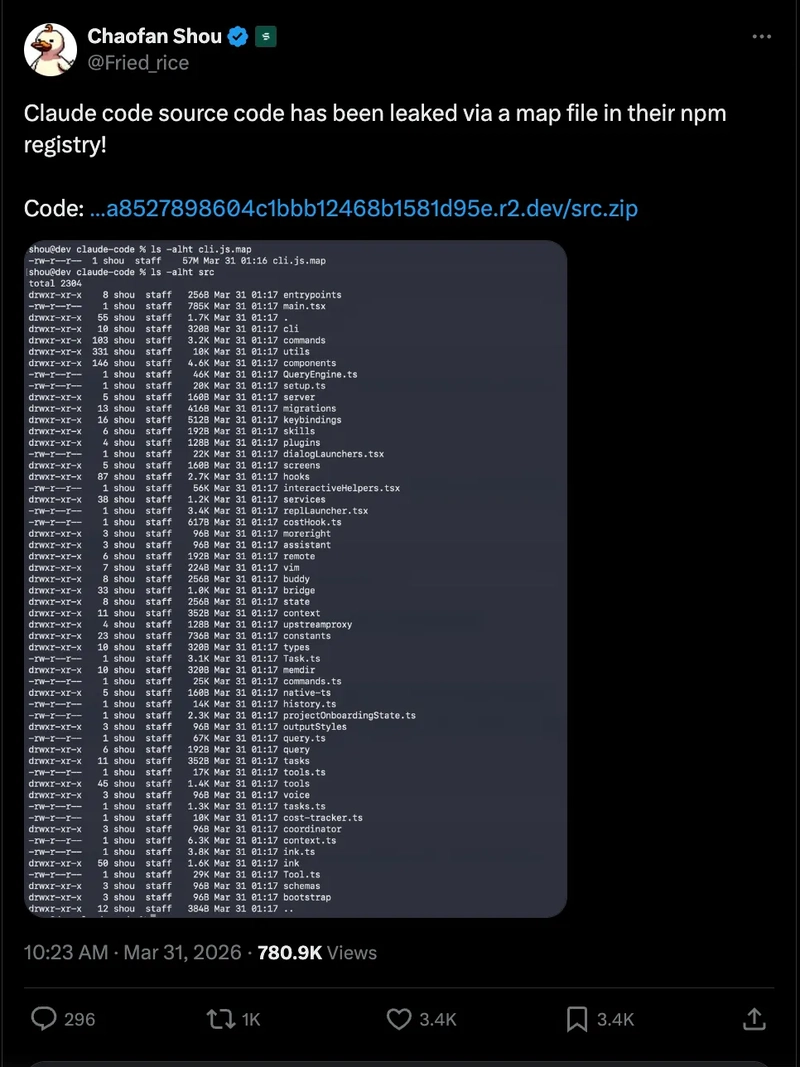
Claude Code’s Entire Source Code Leaked via npm Source Maps
On March 31, 2026, security researcher Chaofan Shou discovered that Anthropic’s Claude Code — its flagship agentic coding CLI — had its entire source code exposed through a source map file accidentally published to the npm registry. The leak revealed 1,900 files and over 512,000 lines of TypeScript code, exposing the full internal architecture, unreleased […]
-
Agents of Chaos: What Happens When Autonomous AI Agents Get Real Tools
On February 23, 2026, a team of 38 researchers from Northeastern University, Harvard, Stanford, Carnegie Mellon, MIT, and other institutions published Agents of Chaos — a red-teaming study that gave six autonomous AI agents real tools, persistent memory, and unrestricted shell access, then watched what happened over two weeks. The results reveal that individually aligned […]
-
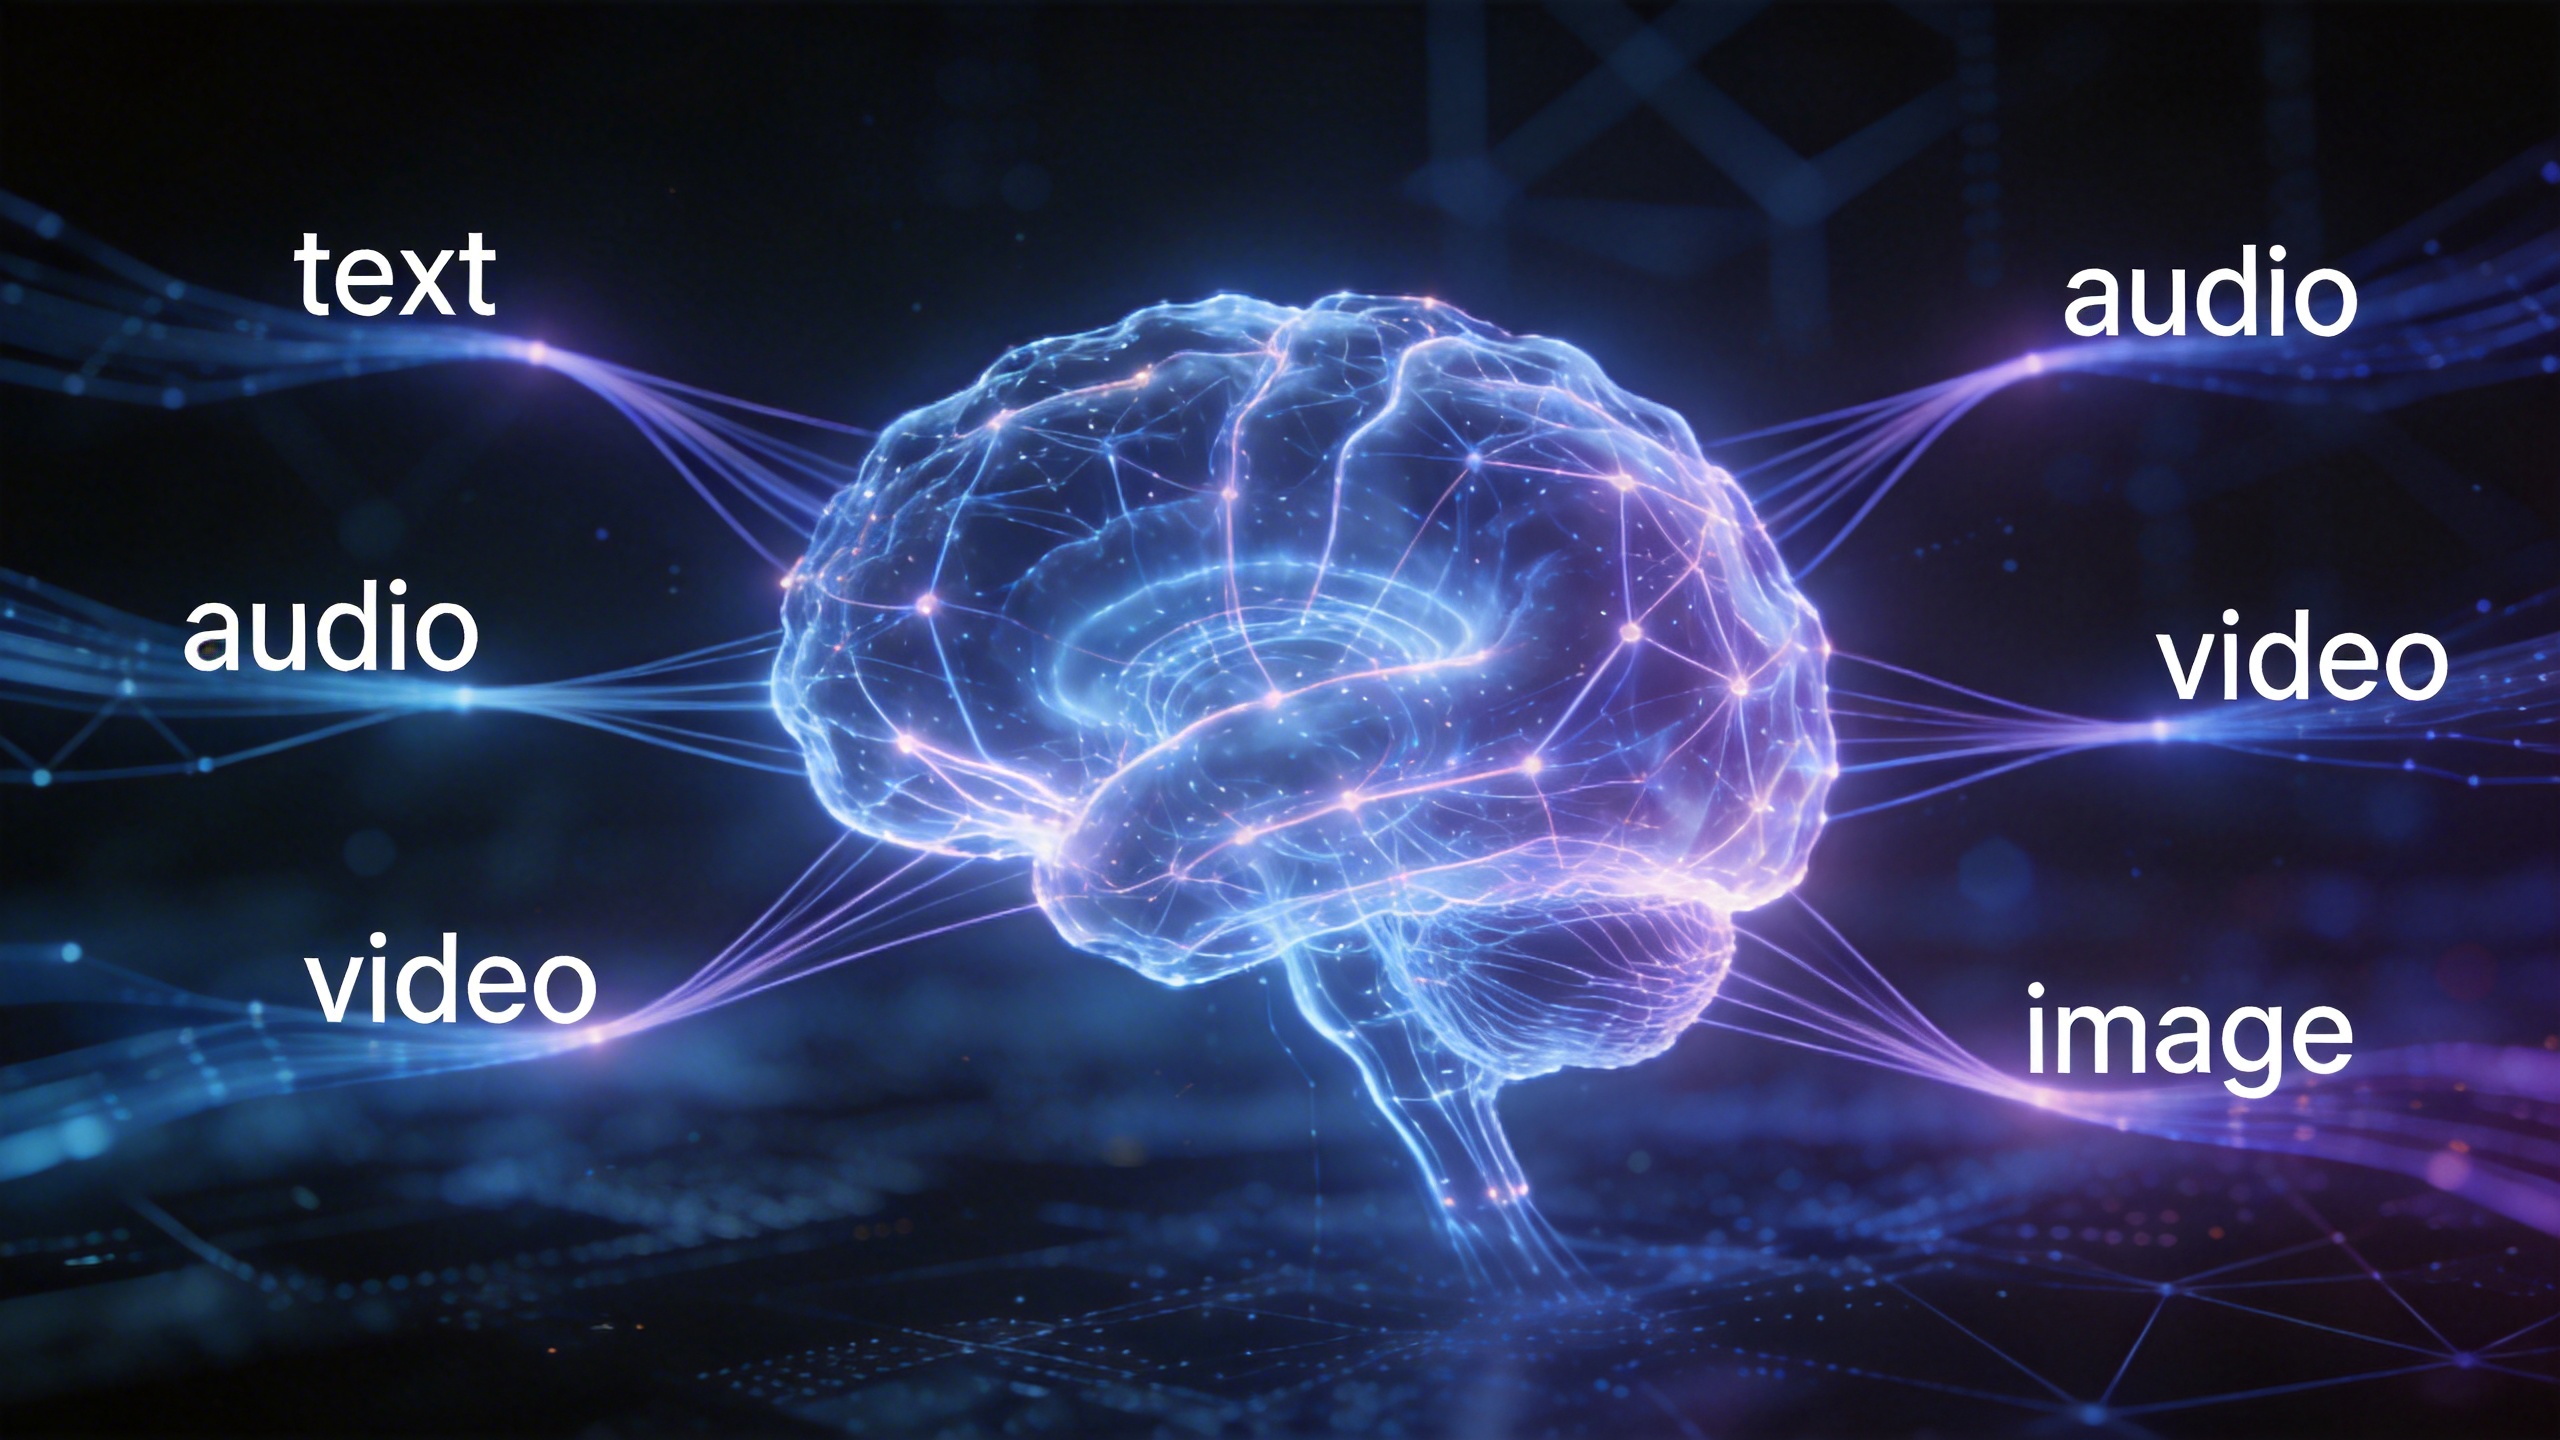
Qwen3.5-Omni: Alibaba’s Omnimodal AI Speaks 36 Languages and Codes from Voice
On March 30, 2026, Alibaba’s Qwen team released Qwen3.5-Omni — a natively omnimodal AI model that processes text, images, audio, and video while generating real-time speech output. Available in three sizes (Plus, Flash, and Light), the model claims 215 state-of-the-art benchmark results and introduces features like semantic interruption, voice cloning, and an emergent “Audio-Visual Vibe […]
-
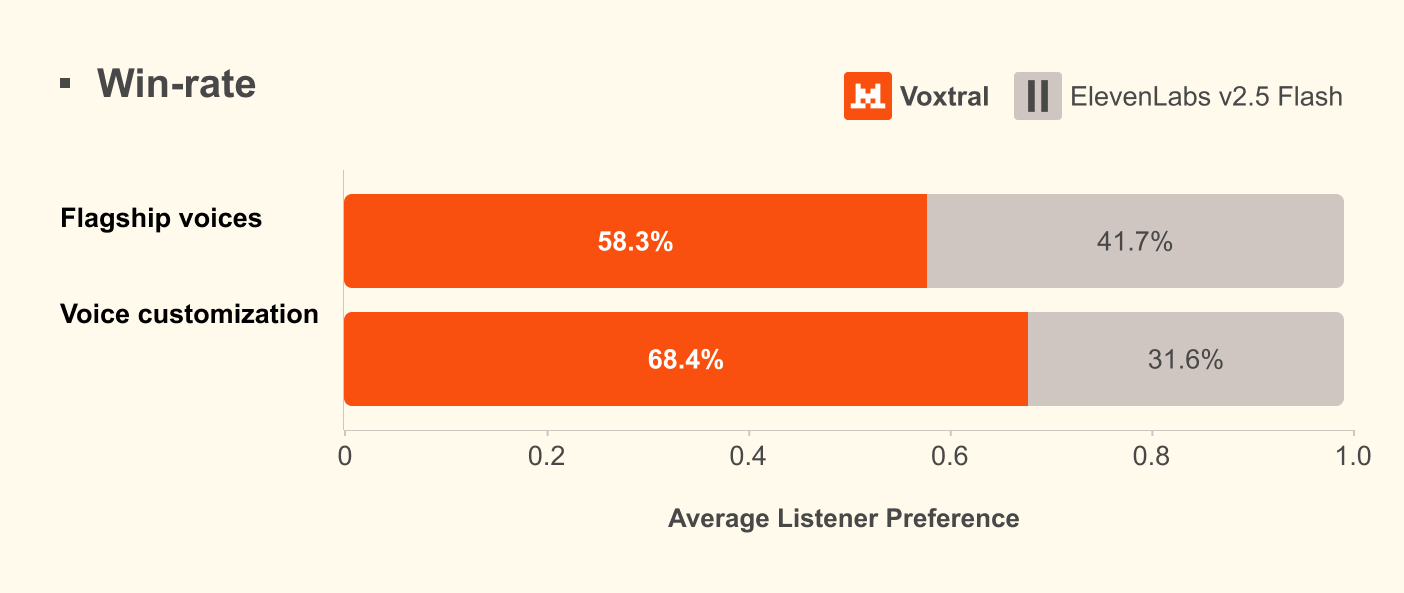
Voxtral TTS: Mistral’s Open-Weight Text-to-Speech Model Rivals ElevenLabs
On March 26, 2026, Mistral AI released Voxtral TTS — a 4-billion-parameter open-weight text-to-speech model that the company says outperforms ElevenLabs Flash v2.5 in human preference tests while matching ElevenLabs v3 in lifelike interactions. Built on Ministral 3B, Voxtral TTS supports nine languages, clones voices from just three seconds of audio, and achieves 70ms latency […]
-
Cohere Transcribe: 2B Open-Source ASR Model Takes #1 on Leaderboard
On March 26, 2026, Cohere released Cohere Transcribe — a 2-billion-parameter open-source automatic speech recognition (ASR) model that claims the #1 spot on the Hugging Face Open ASR Leaderboard. Licensed under Apache 2.0 and designed to run on consumer-grade GPUs, Transcribe marks Cohere’s first entry into voice AI and signals growing competition in the open-source […]
-
MiniMax M2.7: The First AI Model That Helps Train Itself
MiniMax has released M2.7, the first frontier AI model designed to participate in its own training loop. Announced on March 18, 2026, M2.7 introduces what MiniMax calls “self-evolution” — the model autonomously analyzes its own failure trajectories, modifies its scaffold code, and runs evaluations across 100+ iterative rounds, achieving a 30% performance improvement on internal […]
-
Unsloth Studio: Open-Source No-Code UI for Local LLM Training and Inference
On March 17, 2026, Unsloth AI launched Unsloth Studio — an open-source, no-code web interface that lets users train, run, and export large language models from a single local dashboard. The beta release positions Unsloth Studio as the first tool to unify fine-tuning, inference, and deployment in one local application, promising 2x faster training with […]
-
Mistral Small 4: Four Models Unified in One Open-Source MoE
On March 16, 2026, Mistral AI released Mistral Small 4 — a 119-billion-parameter Mixture-of-Experts model that unifies instruction following, reasoning, multimodal understanding, and agentic coding into a single deployment. With only 6 billion active parameters per token (8B including embedding layers), it delivers frontier-class performance at a fraction of the cost and latency of larger […]
-
Foundation-1: A Producer-Focused AI Model for Structured Music Sample Generation
RoyalCities has released Foundation-1, a specialized text-to-sample AI model built on Stability AI’s Stable Audio Open architecture. Unlike general-purpose music generators that output full songs, Foundation-1 is designed for actual music production workflows — generating tempo-synced, key-aware, bar-structured audio loops with fine-grained control over instrumentation, timbre, effects, and musical phrasing. Intermediate Key points RoyalCities released […]