Tag: Level: Intermediate
-
Google Releases Gemma 4 12B: Frontier Multimodal AI on a Laptop
Lead — On June 3, 2026, Google DeepMind released Gemma 4 12B, a unified, encoder-free multimodal model that brings frontier-class intelligence to a single 16 GB laptop. The 11.95-billion-parameter model handles text, images, and audio in one decoder-only transformer, supports a 256K-token context across 140+ languages, and ships under a fully permissive Apache 2.0 license. Google […]
-
PrismML Releases 1-Bit Bonsai Image 4B for Local Generation
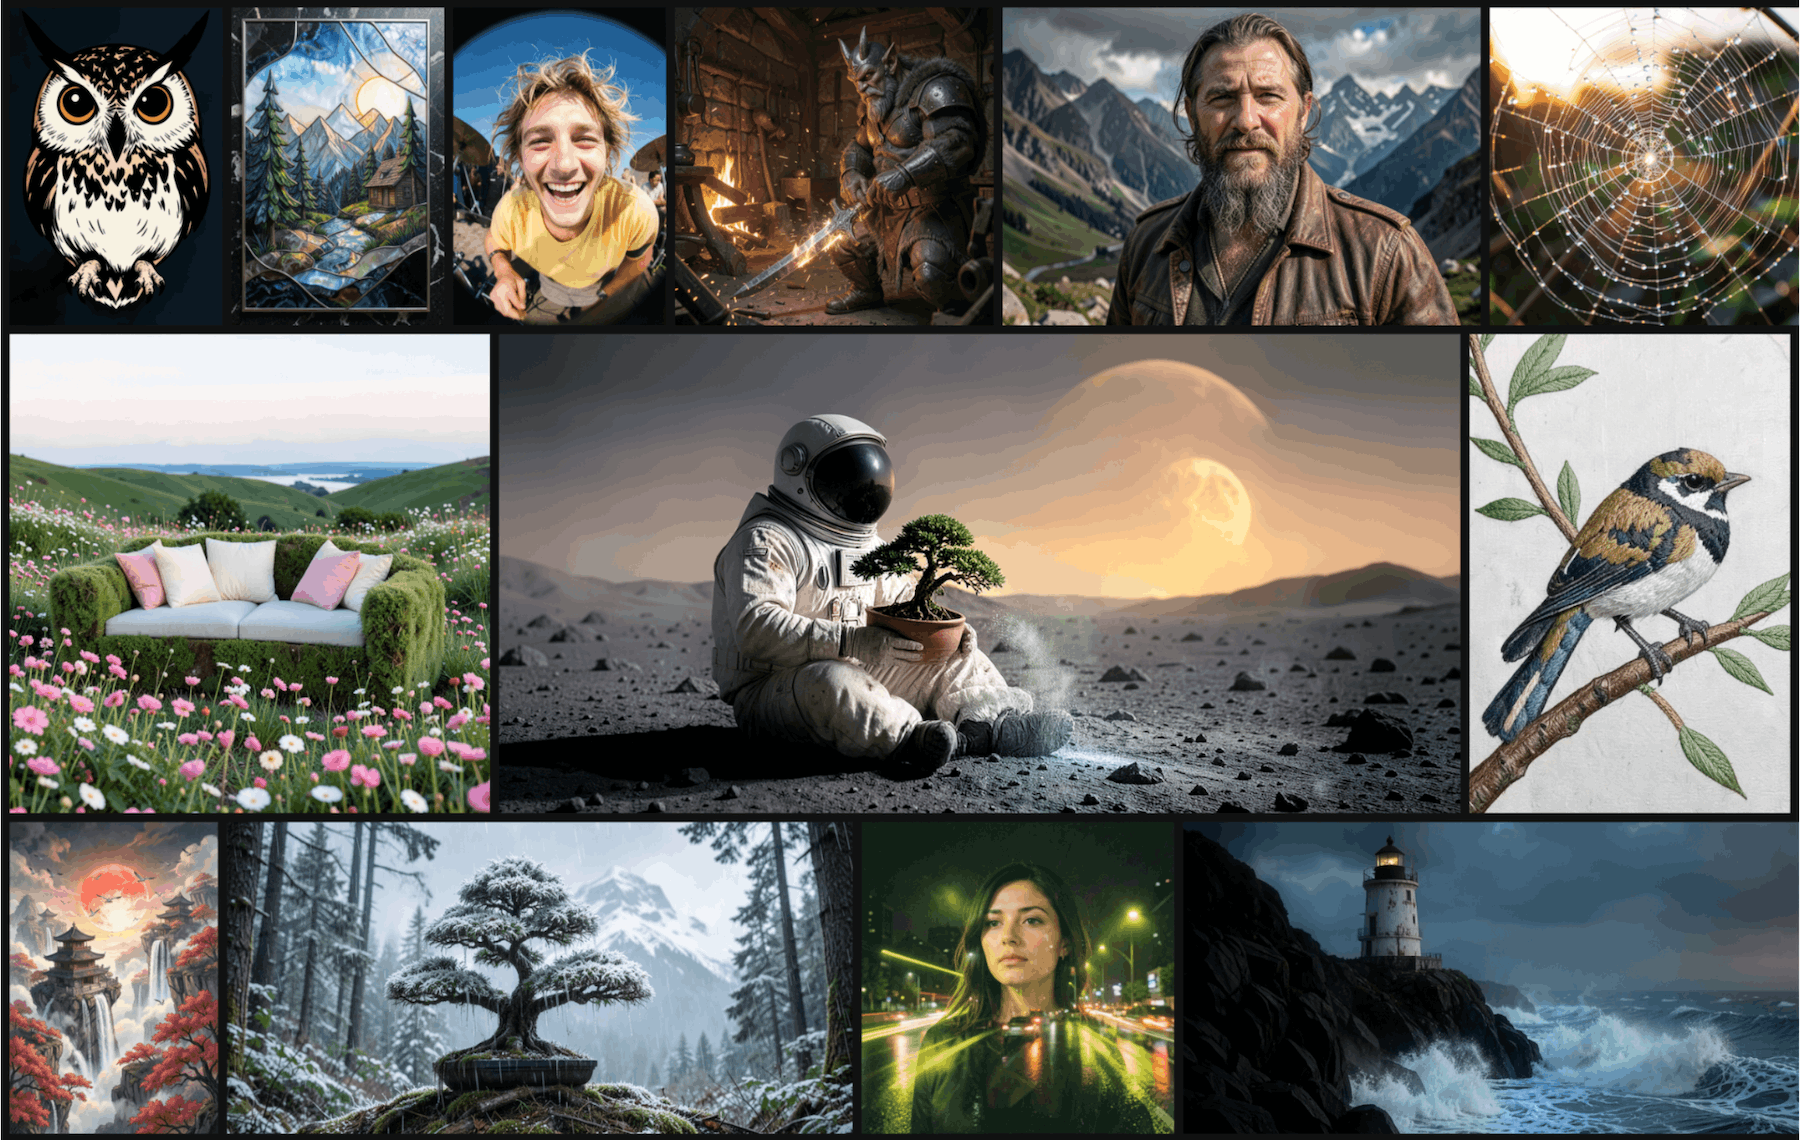
PrismML released Bonsai Image 4B, a 1-bit and ternary text-to-image diffusion transformer family, extending the company’s Bonsai quantization push from language models into image generation. The notable claim is local accessibility: PrismML says the models are small enough to run fully in a browser through WebGPU while still producing competitive text-to-image outputs. Intermediate Key points […]
-
ByteDance Releases Lance, a 3B Unified Multimodal Model
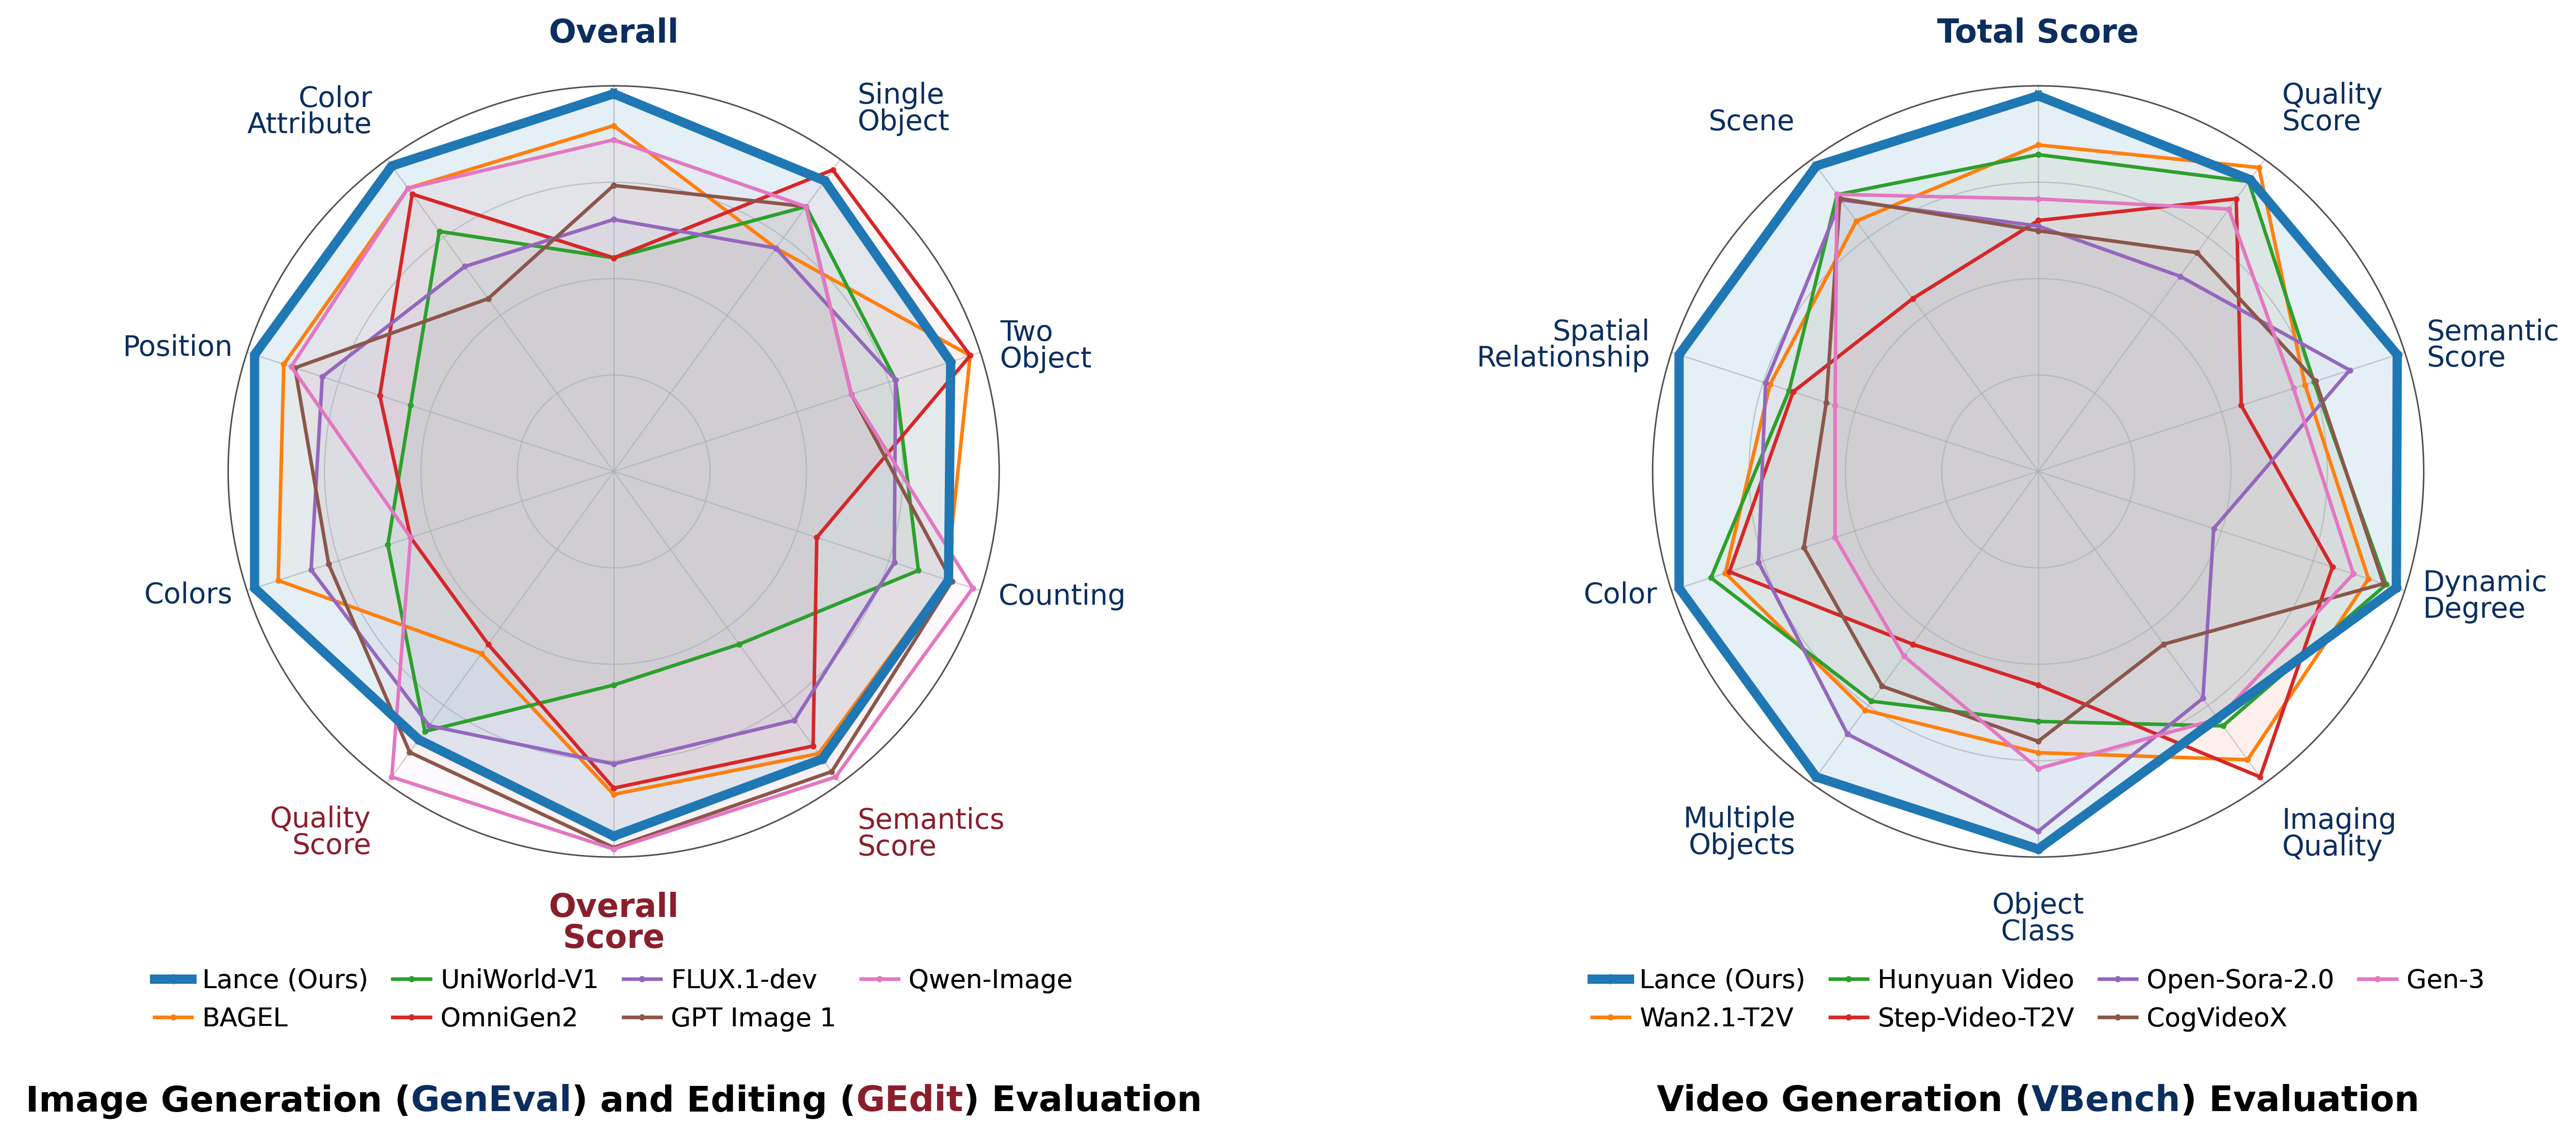
ByteDance released Lance, a 3-billion-parameter native unified multimodal model, aiming to handle image understanding, text-to-image, image editing, text-to-video, and image-to-video in one lightweight open model. The release drew attention because it tries to compress a broad creative AI stack into a model size that is closer to local experimentation than cloud-only frontier systems. Intermediate Key […]
-
Google Introduces Gemini Omni and Gemini 3.5 at I/O
Google introduced Gemini Omni and Gemini 3.5 updates during I/O 2026, putting the Gemini app on a more multimodal, agentic path. The headline is not just a larger model: Google is presenting Gemini as an interface that can hear, see, reason over screens and documents, generate media, and connect those capabilities across Search, Workspace, Android, […]
-
BadHost Starlette Bug Puts AI Agent Infrastructure on Alert
A critical Starlette vulnerability known as BadHost is drawing attention from AI infrastructure teams because Starlette is widely used in Python web services, including stacks around vLLM, MCP servers, and agent tooling. The issue, tracked as CVE-2026-48710, involves improper handling of untrusted Host headers and can enable cache poisoning, poisoned password reset links, and server-side […]
-
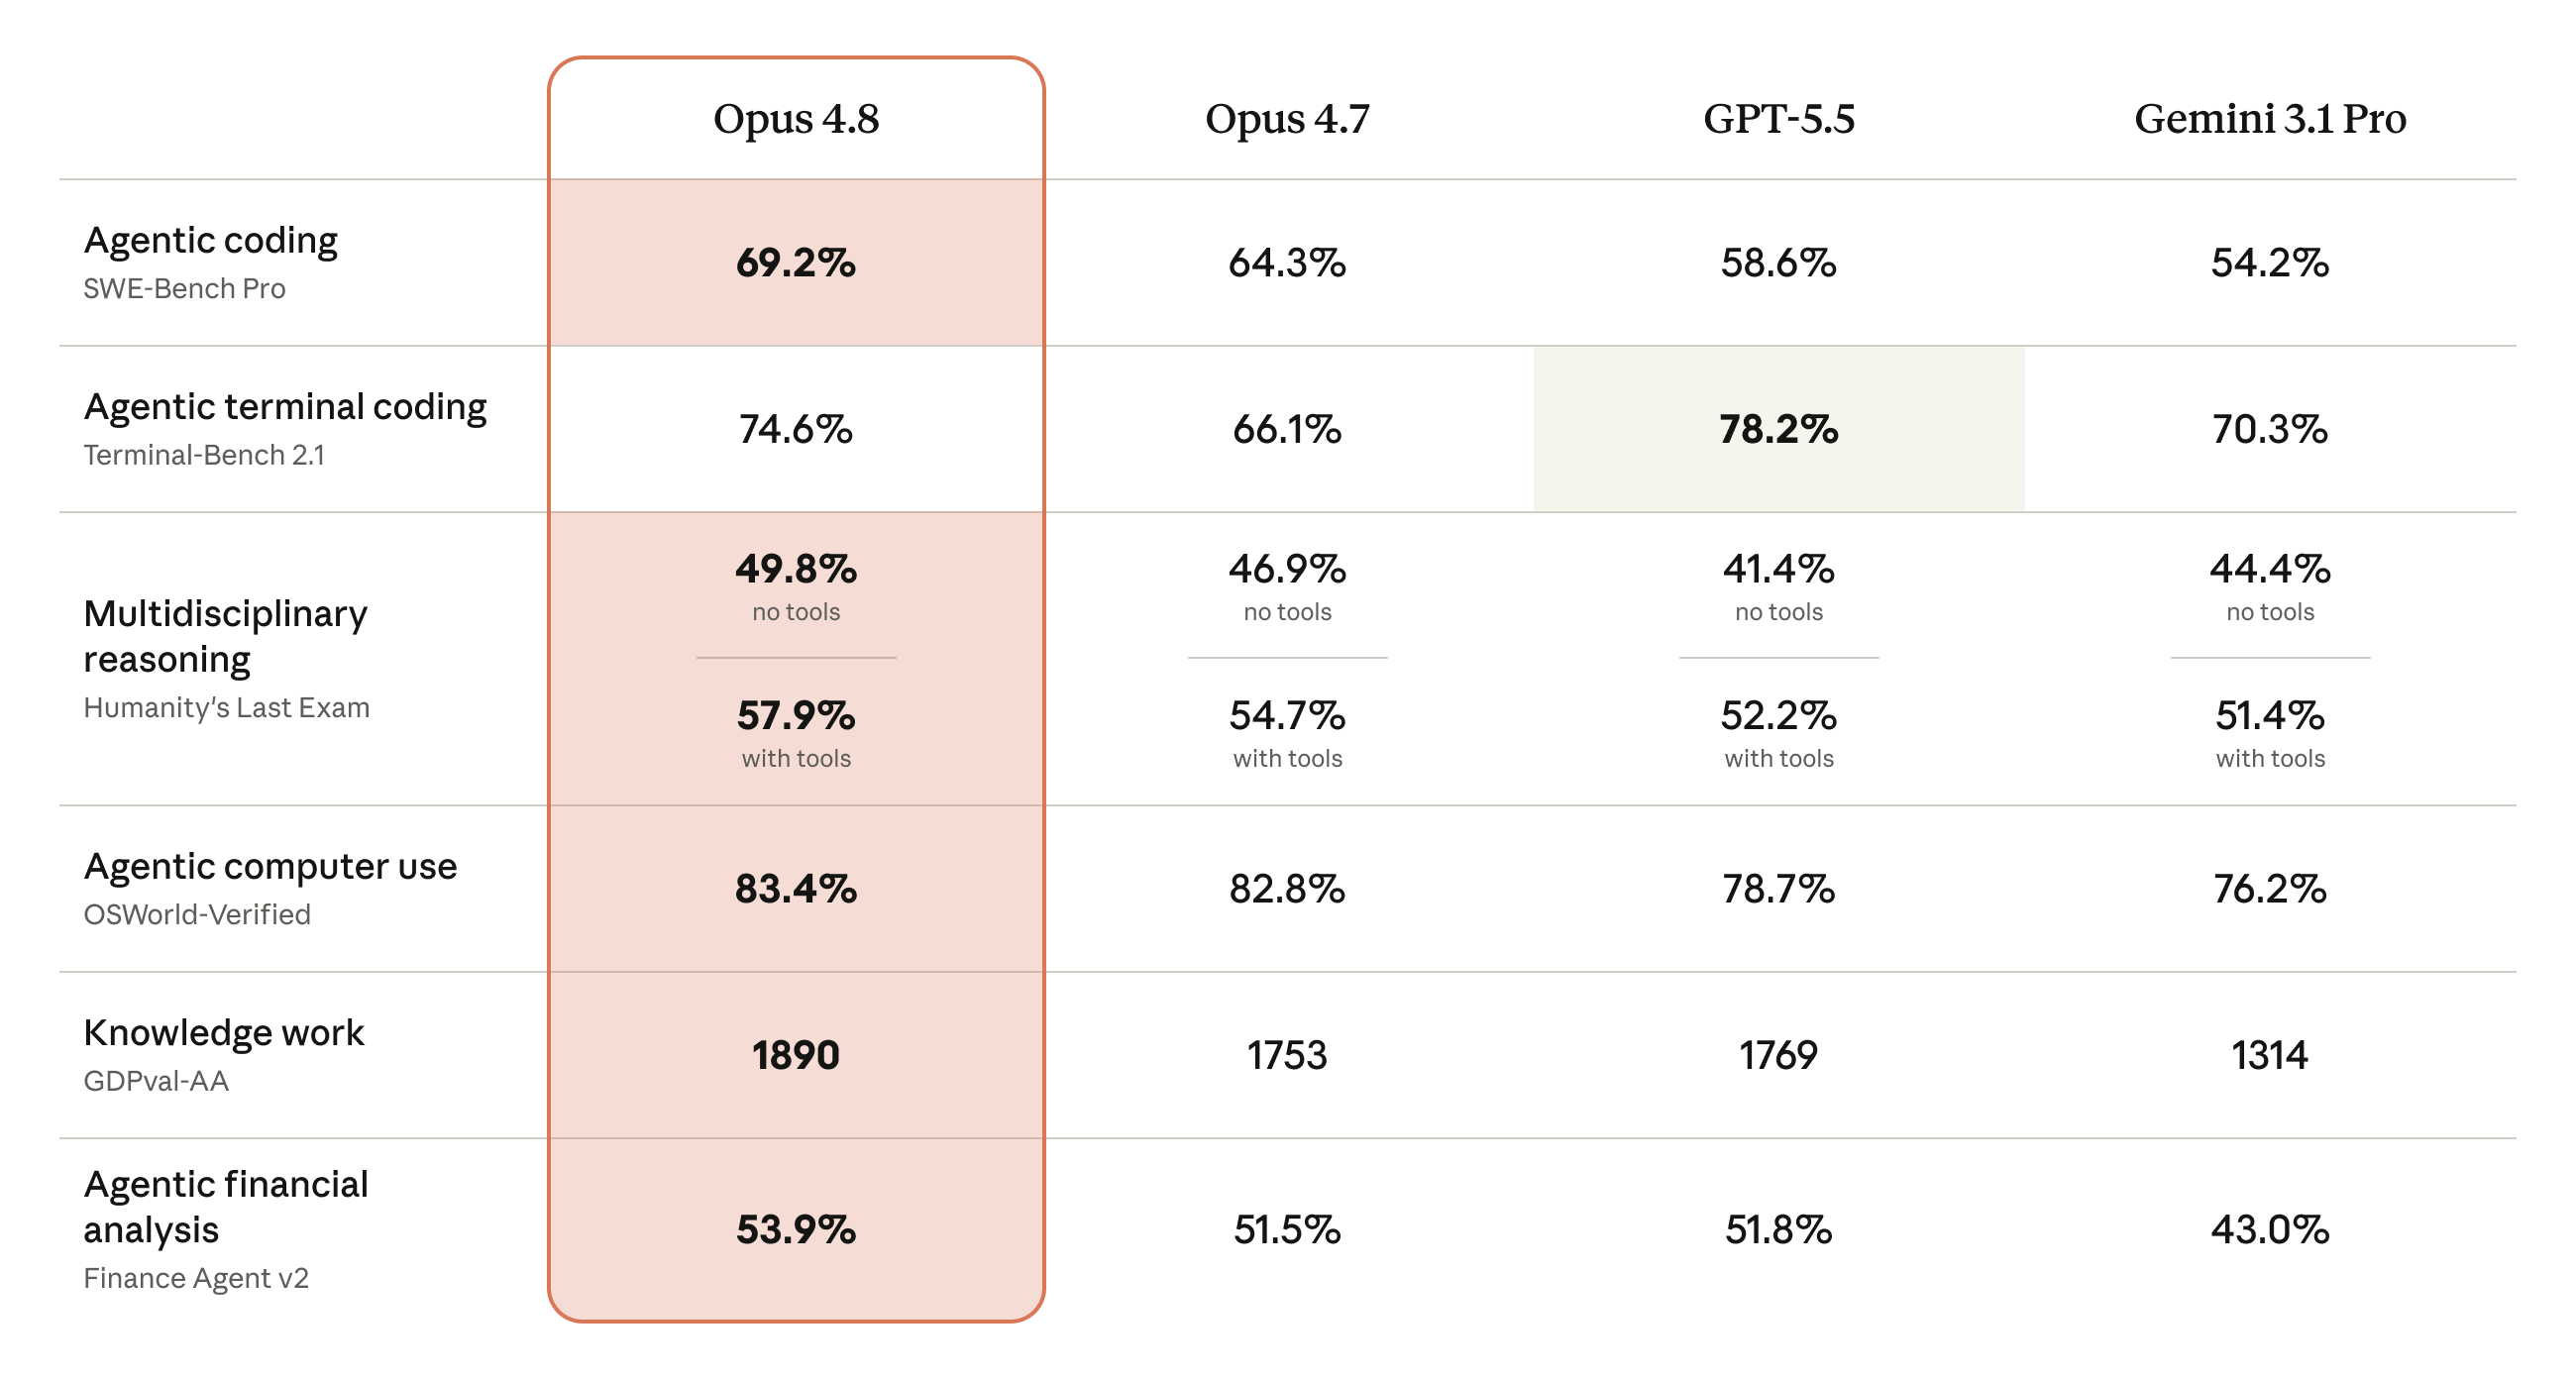
Anthropic Releases Claude Opus 4.8 for Longer Agentic Coding
Anthropic released Claude Opus 4.8 on May 28, 2026, upgrading its flagship generally available model for long-horizon coding agents, professional knowledge work, and enterprise workflows. The release is not a radical architecture reveal; its significance is more practical: better benchmark results, a cheaper fast mode, stronger self-checking behavior, and new Claude Code workflows that let […]
-
Thinking Machines Unveils Interaction Models for Real-Time Human-AI Collaboration
Thinking Machines Lab announced its first “interaction models” on May 11, 2026, unveiling TML-Interaction-Small — a 276B-parameter mixture-of-experts model (12B active) designed for real-time, multimodal collaboration. Rather than waiting for the user to finish speaking, the model interleaves 200-millisecond chunks of audio and video input with simultaneous output generation, eliminating the turn-taking pause that defines […]
-
MiniCPM-V 4.6: A 1.3B Multimodal Model Built for Phones
OpenBMB released MiniCPM-V 4.6 on May 11, 2026 — the smallest entry in the MiniCPM-V family to date. At just 1.3B parameters, the new multimodal model handles single-image, multi-image, and video understanding while running on consumer phones across iOS, Android, and HarmonyOS. The model is open-weight under Apache 2.0 and ships with vLLM, SGLang, llama.cpp, […]
-
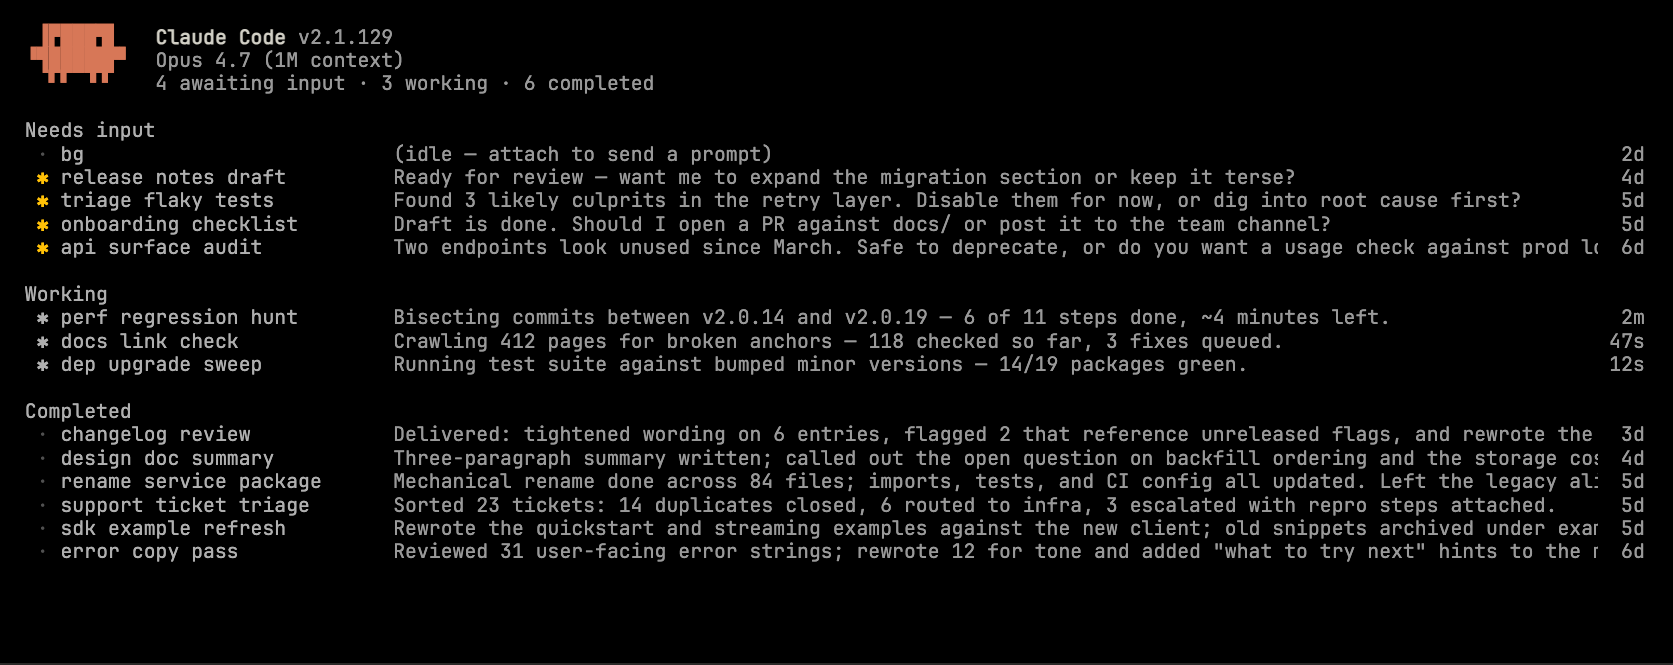
Anthropic Ships Agent View: A Multi-Session Dashboard for Claude Code
Anthropic has shipped Agent View, a research preview that turns Claude Code into a multi-session command center. Launched on May 11, 2026 and available in Claude Code v2.1.139 or later, the new claude agents view lets developers dispatch, monitor, and reply to many parallel coding sessions from a single screen — without keeping a terminal […]
-
NVIDIA Releases Kimodo: Controllable Text-to-Motion for Characters and Humanoid Robots
On March 16, 2026, NVIDIA released Kimodo — a kinematic motion diffusion model that turns text prompts and sparse kinematic constraints into high-quality 3D human and humanoid-robot motion. Trained on 700 hours of commercially-friendly optical motion capture data, Kimodo ships as an open-source project on GitHub and Hugging Face, with seven model checkpoints spanning the […]