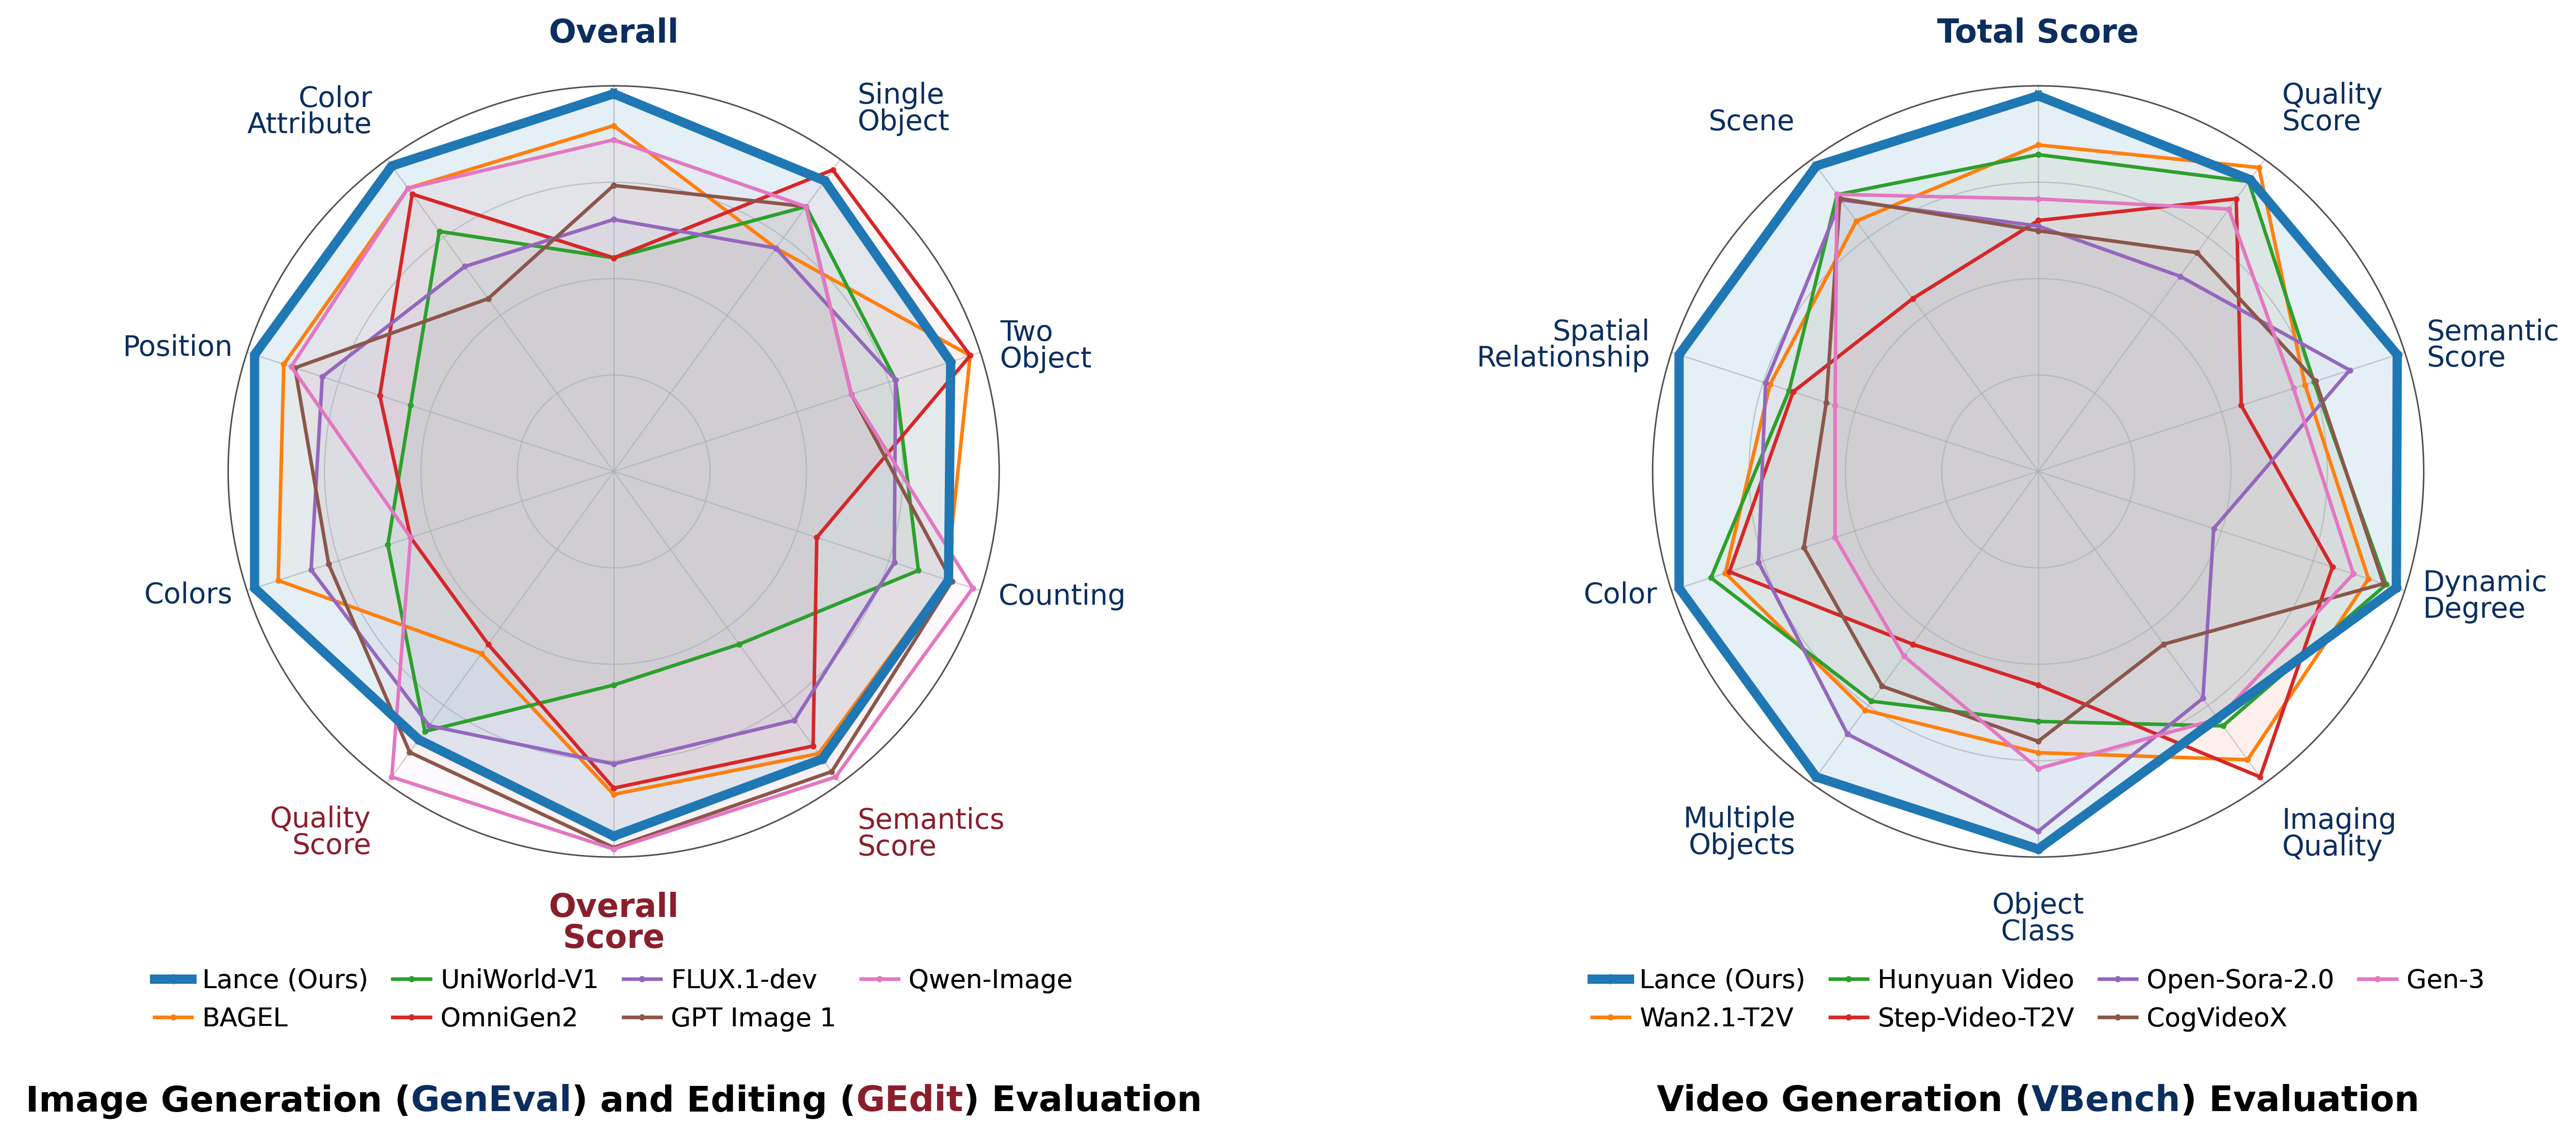
ByteDance released Lance, a 3-billion-parameter native unified multimodal model, aiming to handle image understanding, text-to-image, image editing, text-to-video, and image-to-video in one lightweight open model. The release drew attention because it tries to compress a broad creative AI stack into a model size that is closer to local experimentation than cloud-only frontier systems.
Intermediate
Key points
- ByteDance released Lance, a 3-billion-parameter native unified multimodal model.
- The model aims to handle image understanding, text-to-image, image editing, text-to-video, and image-to-video in one lightweight open model.
- ByteDance presents Lance as a single multimodal system trained to move between understanding and generation tasks, rather than separate vision-language, image-generation, and video-generation models wired together.
- The article says a model this small will not replace the highest-quality commercial video models, but it makes multimodal experimentation more accessible.
- The article notes Lance will become more useful if it gains reliable ComfyUI, web UI, and local inference support, plus clear benchmarks for image editing consistency and video temporal coherence.
A Small Model With Many Jobs
Lance’s pitch is native unification. Instead of wiring separate vision-language, image generation, and video generation models together, ByteDance presents Lance as a single multimodal system trained to move between understanding and generation tasks. The Hugging Face model page highlights image understanding, text-to-image, image editing, text-to-video, and image-to-video as supported capabilities.
The 3B scale is the important detail. A model this small will not replace the highest-quality commercial video models, but it makes multimodal experimentation more accessible. Researchers can inspect behavior, fine-tune workflows, and test local creative pipelines without treating every output as an expensive API call.
Why Local AI Communities Care
Local multimodal models are still uneven. Text-only local LLMs have matured quickly, but image and video generation often require separate diffusion models, heavy VRAM budgets, and custom pipelines. Lance suggests a different path: one smaller model that can support multiple media tasks, even if each task has tradeoffs compared with specialized systems.
That design is useful for education and prototyping. A unified model lets students and builders test how image understanding, editing, and video generation interact in the same architecture. It also gives open-source tooling communities a concrete target for quantization, inference optimization, and UI integration.
What To Watch
The next question is not only output quality, but tooling. Lance will become more useful if it gains reliable ComfyUI, web UI, and local inference support, plus clear benchmarks across image editing consistency, video temporal coherence, prompt following, and multilingual behavior.
For now, Lance is best understood as a compact multimodal research release: ambitious in scope, modest in parameter count, and likely to matter most if the local AI ecosystem can make it easy to run.
Related Coverage
- Seedance 2.0: ByteDance’s Multimodal Audio-Video AI Model – ByteDance’s earlier audio-video generation direction.
- Google Launches Gemini Embedding 2 – related context on unified multimodal representations.
This post was drafted with AI assistance and reviewed by RITS staff.
Leave a Reply