Tag: text-to-video
-
LTX-2.5 Adds Native Multi-Shot Video and a Diffusion Decoder
LTX released LTX-2.5 on August 11, 2026 — an update to its 22-billion-parameter open-weights audio-video model that replaces the VAE reconstruction stage with a diffusion video decoder, adds native multi-shot generation in a single pass, and ships with day-one ComfyUI support. The Israeli company behind Lightricks says the model generates a 10-second clip in 6.8 […]
-
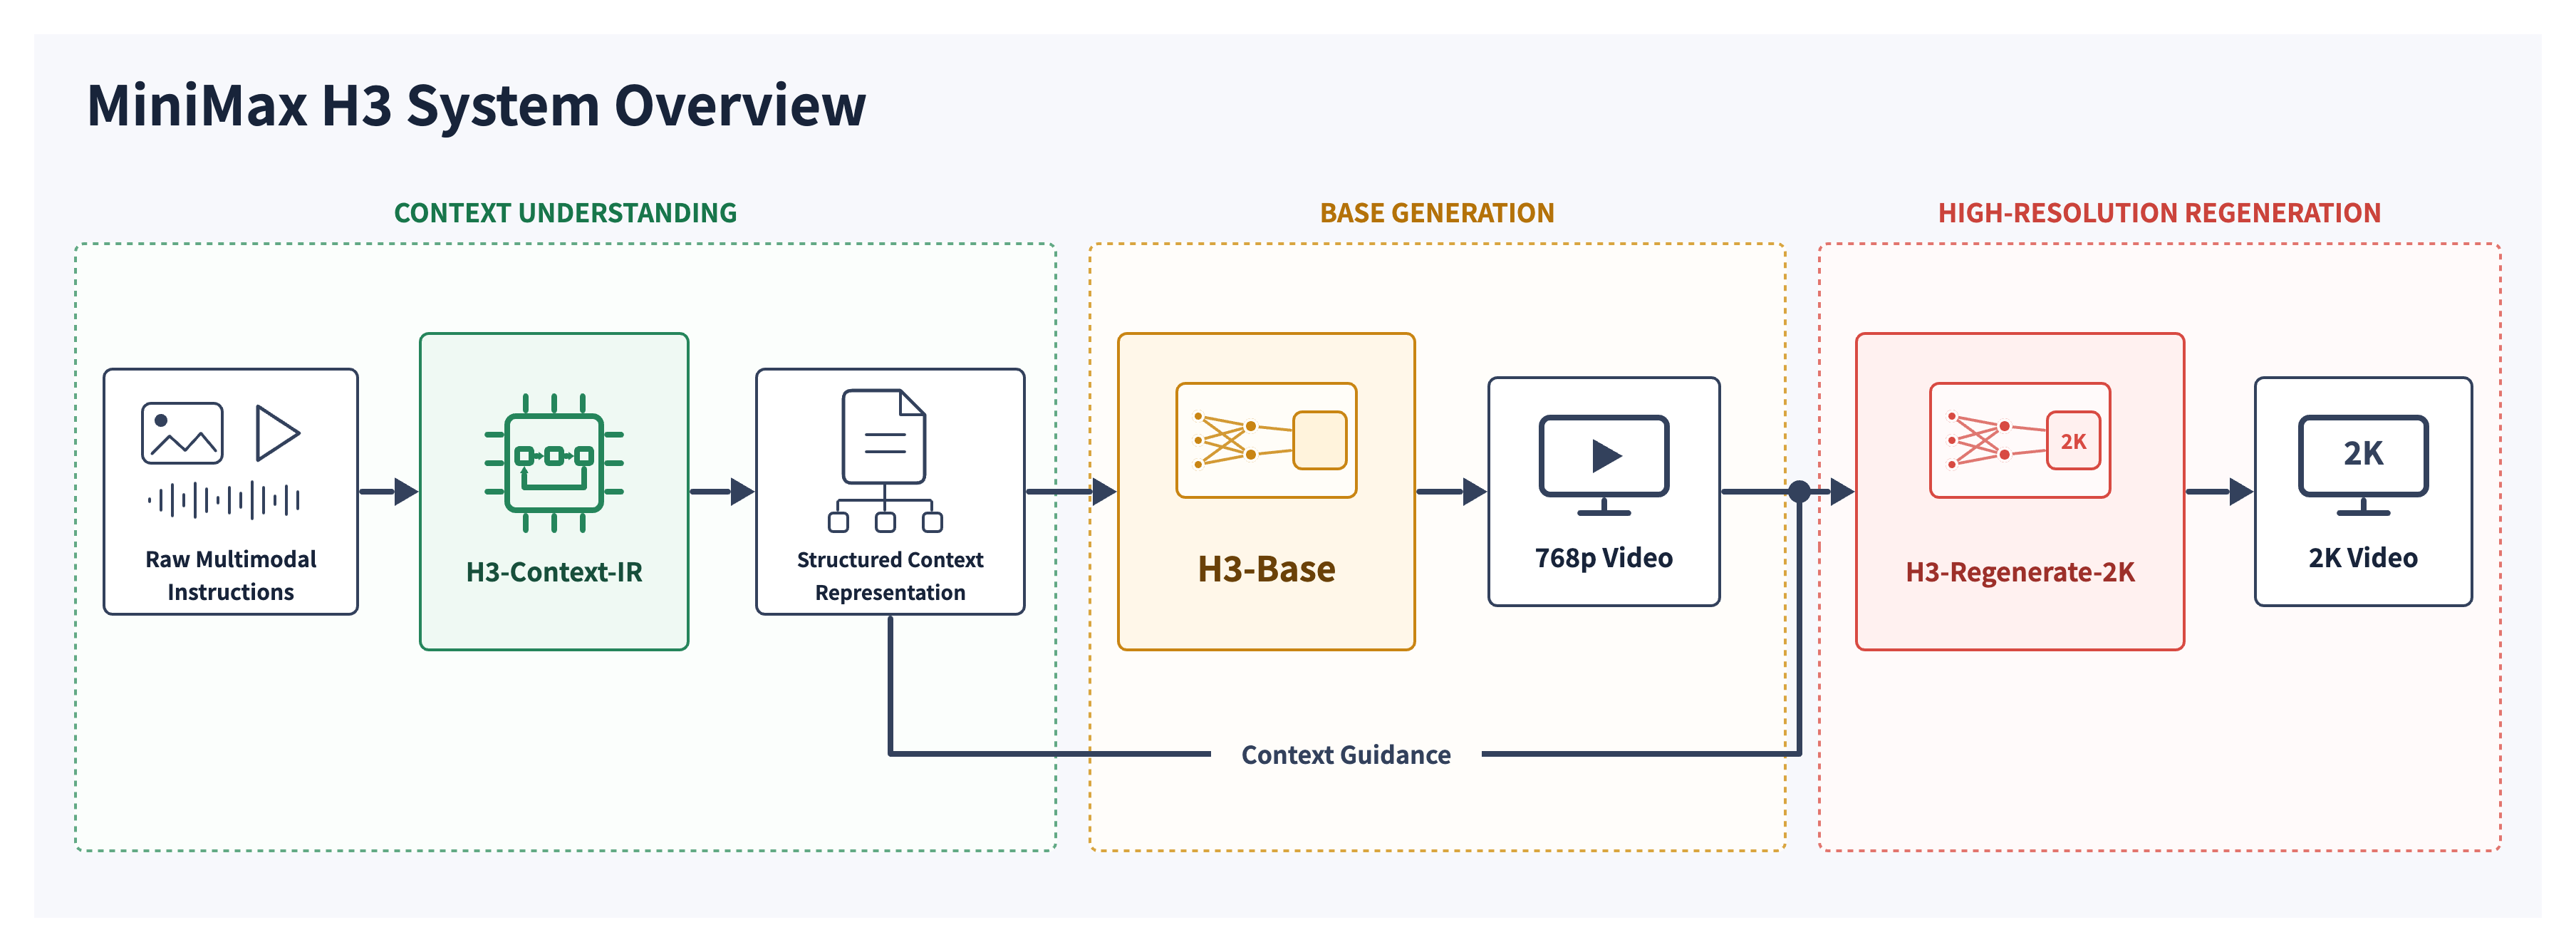
MiniMax Ships H3 Weights — With the US and EU Excluded
MiniMax published the MiniMax-H3 weights to Hugging Face on August 3, 2026 — three days after announcing the omni-modal video model and promising an open release “in the coming days.” The checkpoints are real, the quantized build is small enough to matter, and ComfyUI shipped day-0 support. But the accompanying MiniMax H3 Community License carves […]
-
MiniMax Releases H3: 2K Video With Native Audio, Open Weights Promised
MiniMax released H3 on July 30, 2026 — a general-purpose multimodal video model that generates clips of up to 15 seconds at native 2K resolution with synchronized stereo audio, and takes text, images, video, and audio as reference inputs in a single request. The Shanghai company says it will publish H3’s weights “within days,” which […]
-
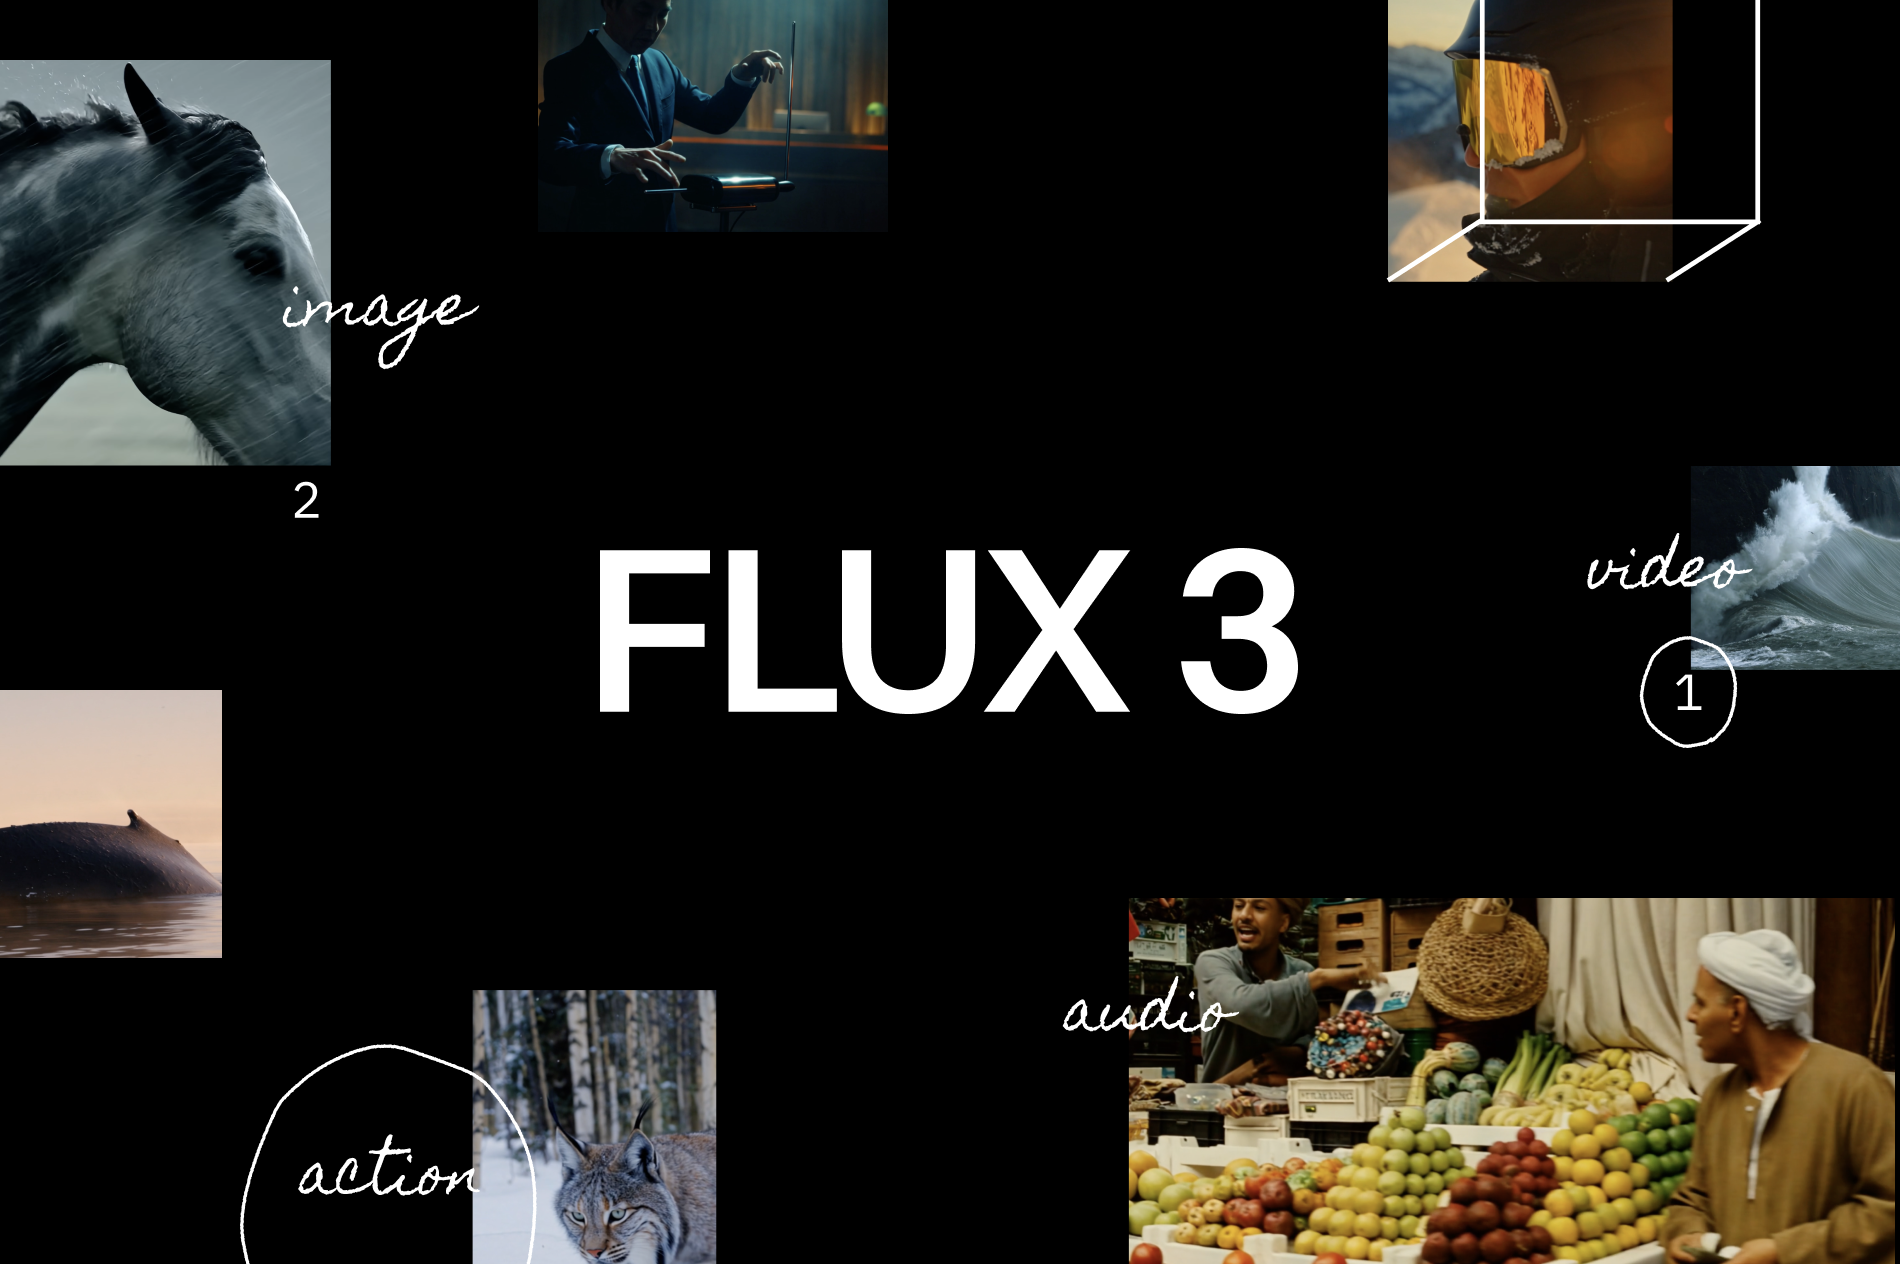
Black Forest Labs Unveils FLUX 3, a Multimodal Image, Video, Audio and Action Model
Black Forest Labs unveiled FLUX 3 on July 23, 2026 — a multimodal frontier model that jointly learns from images, video, and audio in a single unified architecture. The German lab that made its name with the open-weight FLUX.1 image models is pivoting from still images toward what it calls “visual intelligence,” with a headline […]
-
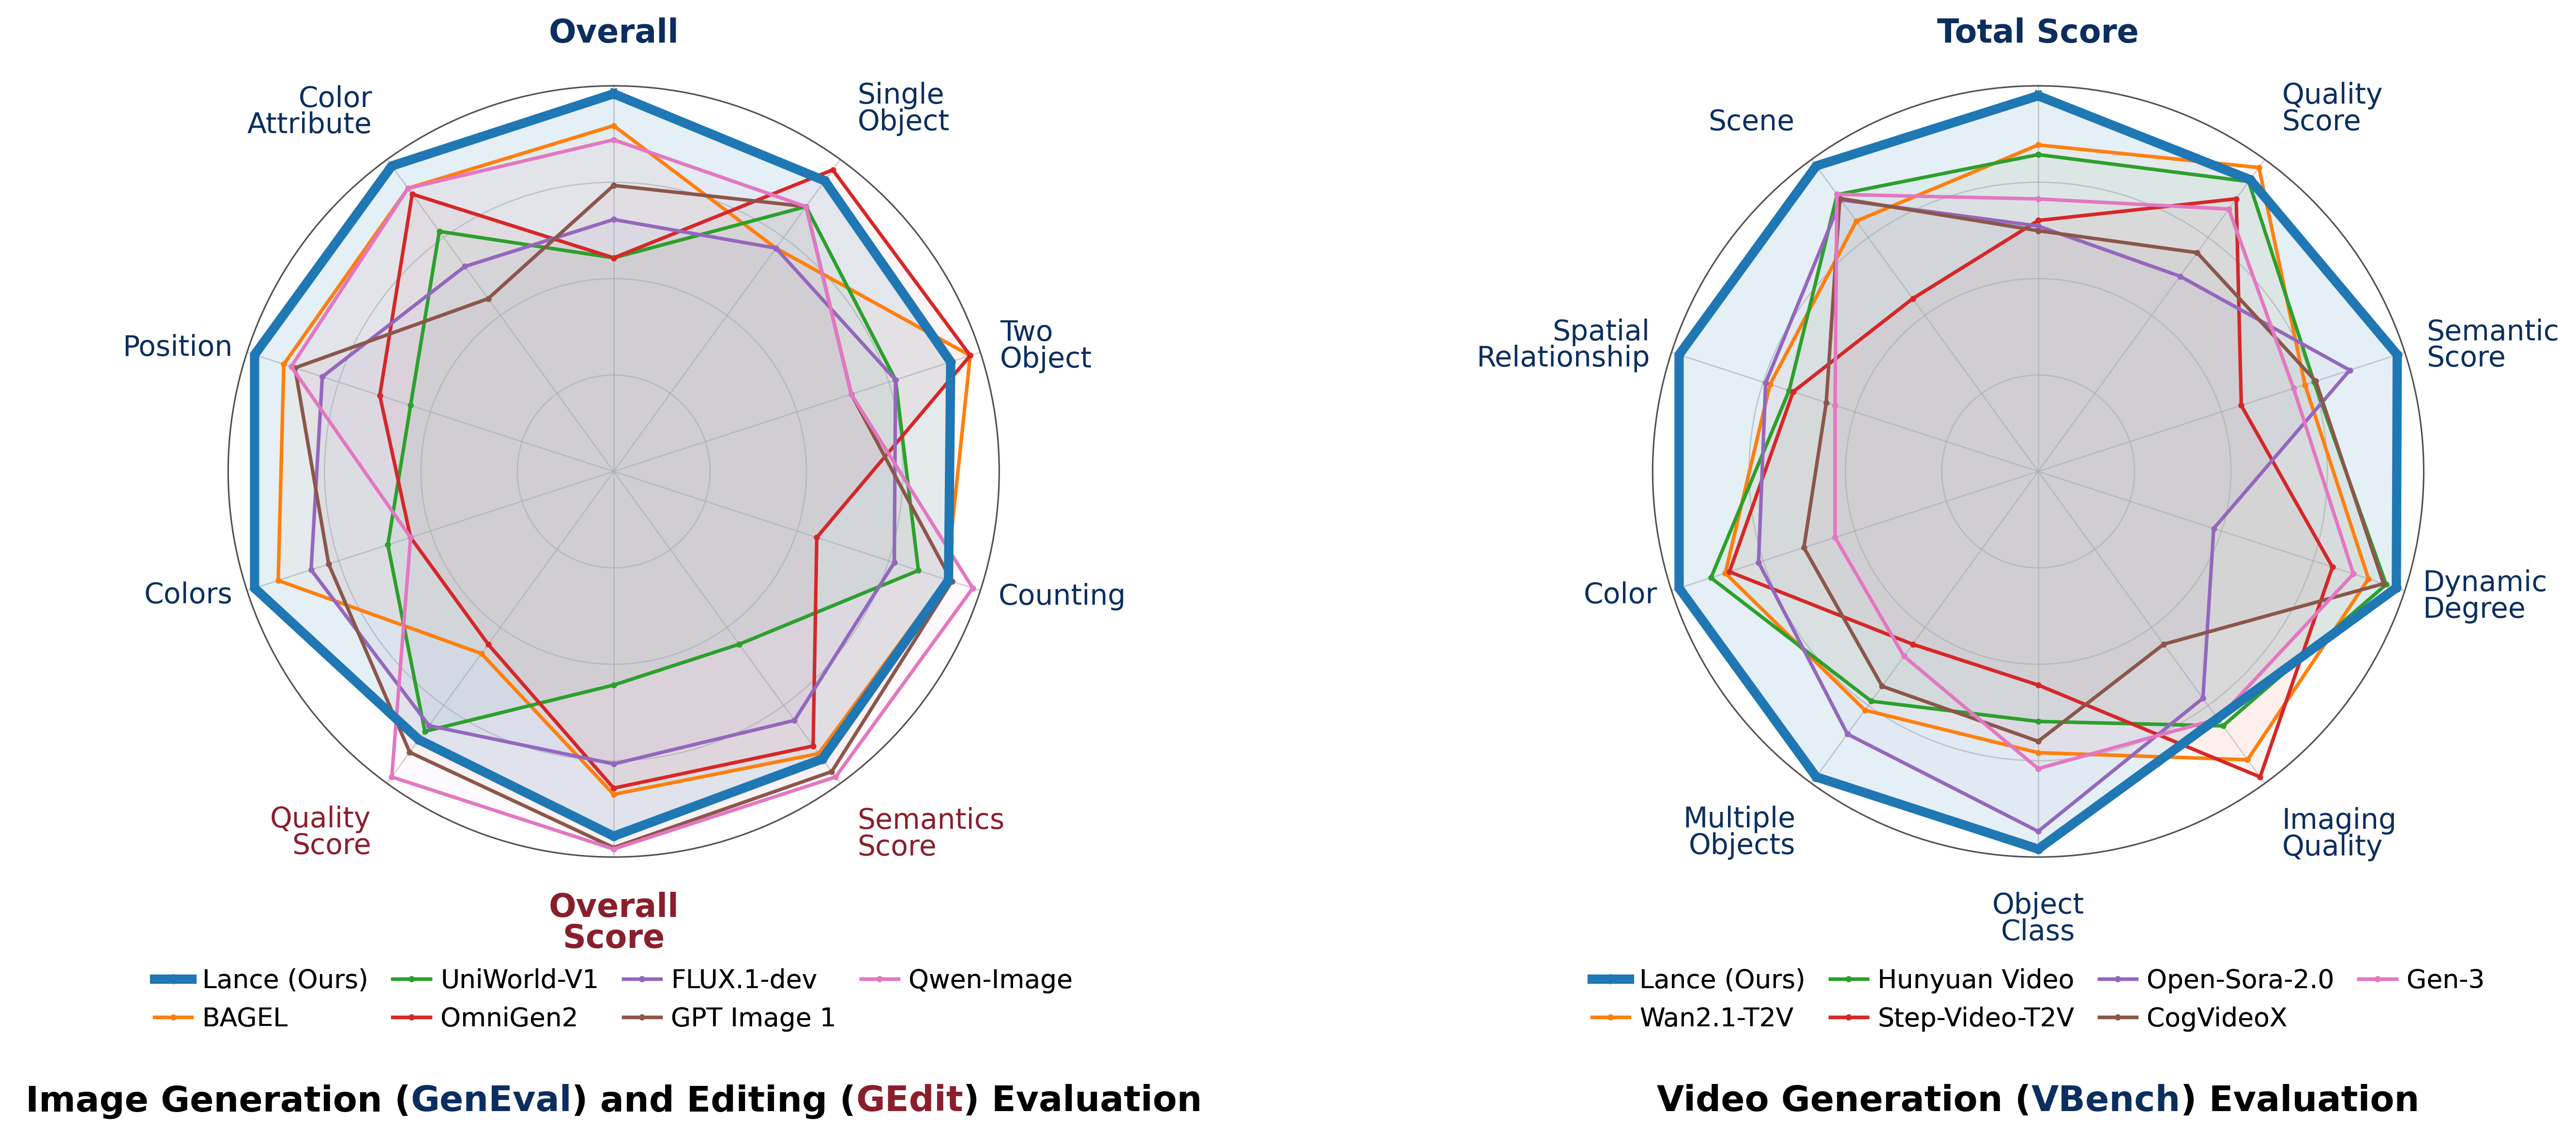
ByteDance Releases Lance, a 3B Unified Multimodal Model
ByteDance released Lance, a 3-billion-parameter native unified multimodal model, aiming to handle image understanding, text-to-image, image editing, text-to-video, and image-to-video in one lightweight open model. The release drew attention because it tries to compress a broad creative AI stack into a model size that is closer to local experimentation than cloud-only frontier systems. Intermediate Key […]
-
OpenAI Shuts Down Sora: AI Video App Discontinued After Six Months
OpenAI announced on March 24, 2026 that it is shutting down Sora, its AI video generation app and API, just six months after its splashy launch. The decision also torpedoed a $1 billion partnership with Disney and marks OpenAI’s first major product discontinuation as the company pivots toward more profitable coding and enterprise AI tools […]
-
LTX-2.3: Sharper Video, Native Portrait, and Cleaner Audio in Lightricks’ Latest Open-Source Model
Key points Lightricks released LTX-2.3 on March 5, 2026 under an Apache 2.0 license as a refinement of the 22-billion-parameter LTX-2 Diffusion Transformer that generates synchronized video and audio from a single architecture. The update focuses on four areas: a rebuilt VAE for sharper detail, an upgraded gated-attention text connector for prompt adherence, native portrait […]
-
Seedance 2.0: ByteDance’s Multimodal Audio-Video AI Model
Key points ByteDance launched Seedance 2.0 on February 12, 2026, describing it as a unified multimodal audio-video joint generation architecture. Users can feed the model up to 9 images, 3 video clips, 3 audio clips, and natural language instructions at once, 12 files in total. Output videos can run up to 15 seconds at native […]
-
OpenAI Launches Sora 2: A New Frontier in AI Video Generation
OpenAI has officially unveiled Sora 2, its next-generation video and audio synthesis model, packaged into a brand-new Sora mobile app. (OpenAI) The system promises more realistic visuals, synchronized audio, stronger control over content, and greater creative flexibility than its predecessor. (OpenAI) Key points OpenAI has officially unveiled Sora 2, its next-generation video and audio synthesis […]
-
Let Them Talk: Audio-Driven Multi-Person Conversational Video Generation with MultiTalk
Modern generative AI has made impressive strides in creating lifelike talking-head and full-body videos from single-speaker audio, but when multiple people converse, existing solutions often falter—mixing up who’s speaking or failing to follow a direction. Enter MultiTalk, a new framework designed specifically for multi-person, audio-driven video generation. Key points MultiTalk is a framework for multi-person, […]