Tag: multimodal
-
OpenBMB Releases MiniCPM-V 4.7, Its First MoE Multimodal Model
OpenBMB released MiniCPM-V 4.7 on October 12, 2026 — the latest entry in its MiniCPM-V vision-language series and the first in that line to use a mixture-of-experts (MoE) architecture. The release ships two open-weight models under Apache 2.0: MiniCPM-V 4.7 35B-A3B and MiniCPM-V 4.7 1B. The headline claim is an efficiency one. OpenBMB describes the […]
-
Google’s EmbeddingGemma 2 Puts Multimodal Search on the Device
Lead — On October 6, 2026, Google DeepMind released EmbeddingGemma 2, a 740-million-parameter open model that maps text, code, images, video, and audio into a single shared 768-dimensional vector space. Built on the Gemma 4 architecture and shipped under the commercially permissive Apache 2.0 license, it is designed to run on phones and laptops rather […]
-
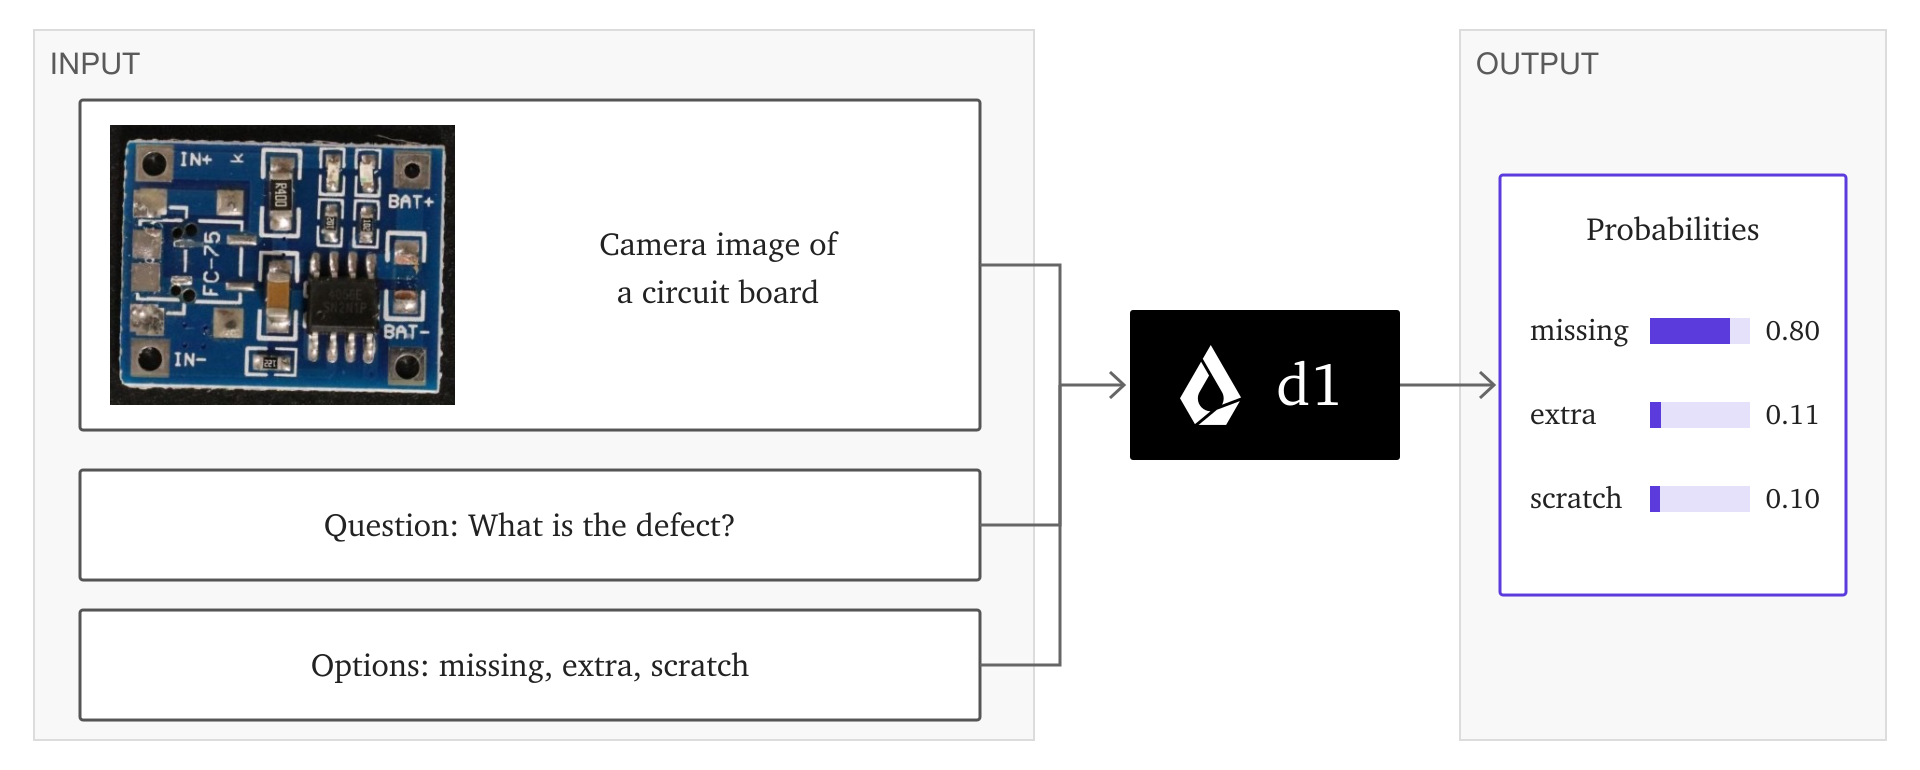
Liquid AI Releases Open-Weight d1 Decision Models for the Edge
On October 7, 2026, Liquid AI released two open-weight “decision models”: d1-3B and d1-omni-600M. Unlike the generative Liquid Foundation Models (LFMs) they are built from, neither writes text. Given a state — text, JSON, one or more images, or, for the smaller model, a voice clip of up to 30 seconds — plus a set […]
-
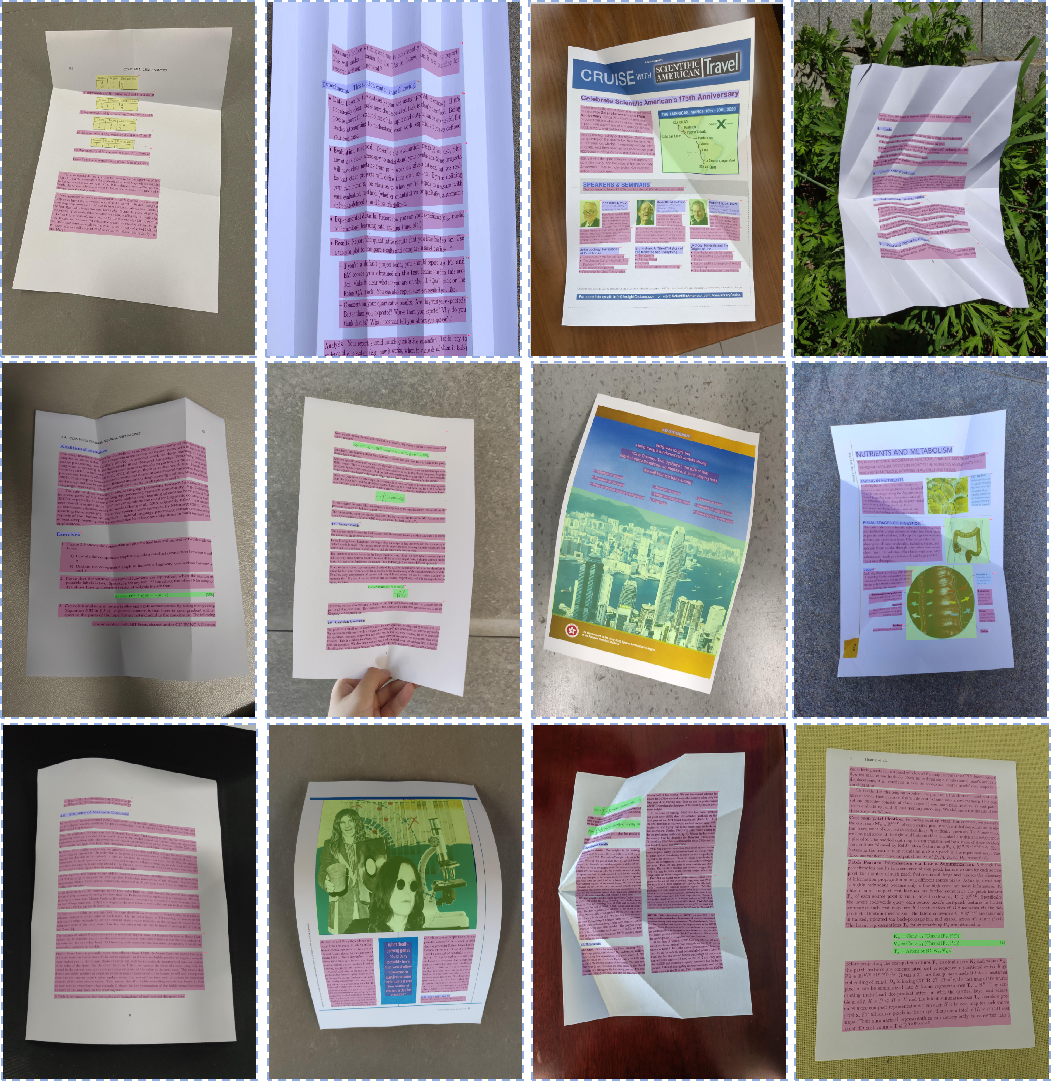
TeleOCR Parses Crumpled, Photographed Pages Without Dewarping
A research team at China Telecom’s AI subsidiary (TeleAI) has released TeleOCR, a 1.2-billion-parameter vision-language model that parses both clean digital documents and photographed ones — folded, curled, or crumpled — with no separate dewarping step. The weights first went up on Hugging Face on August 17, 2026 under the name NaviDC-OCR. The team renamed […]
-
Google Gives Gemini 3.8 Live a Face With Live Avatar
On September 24, 2026, Google released Gemini 3.8 Live with Live Avatar, which adds near real-time generated video to its speech-to-speech dialogue model. The avatar has a face that lip-syncs to the voice, changes expression, and takes turns in the conversation, so an enterprise voice agent can now appear as a video call. The feature […]
-
Apple’s LensVLM-9B Reads Compressed Pages, Then Zooms In
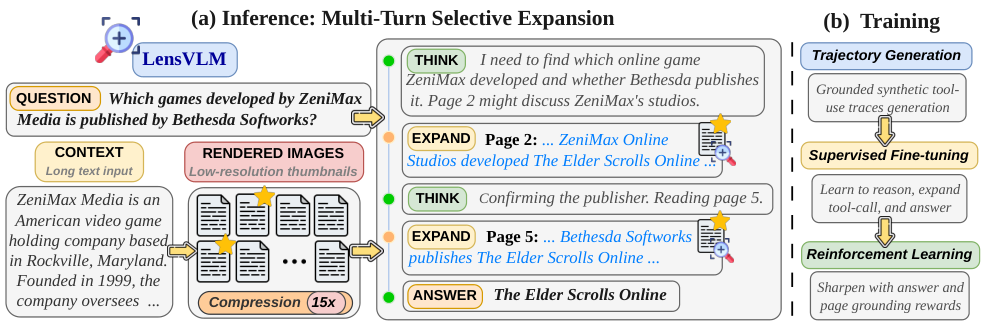
Apple has published the weights for LensVLM-9B, a vision-language model that reads long documents as heavily compressed images and zooms back in only on the pages it needs. The checkpoint went up on Hugging Face on September 21, 2026, alongside inference and evaluation code on GitHub. The paper behind it — a collaboration between Apple […]
-
Qwen-Drive-1.0-4B: Alibaba Open-Weights a Driving Foundation Model
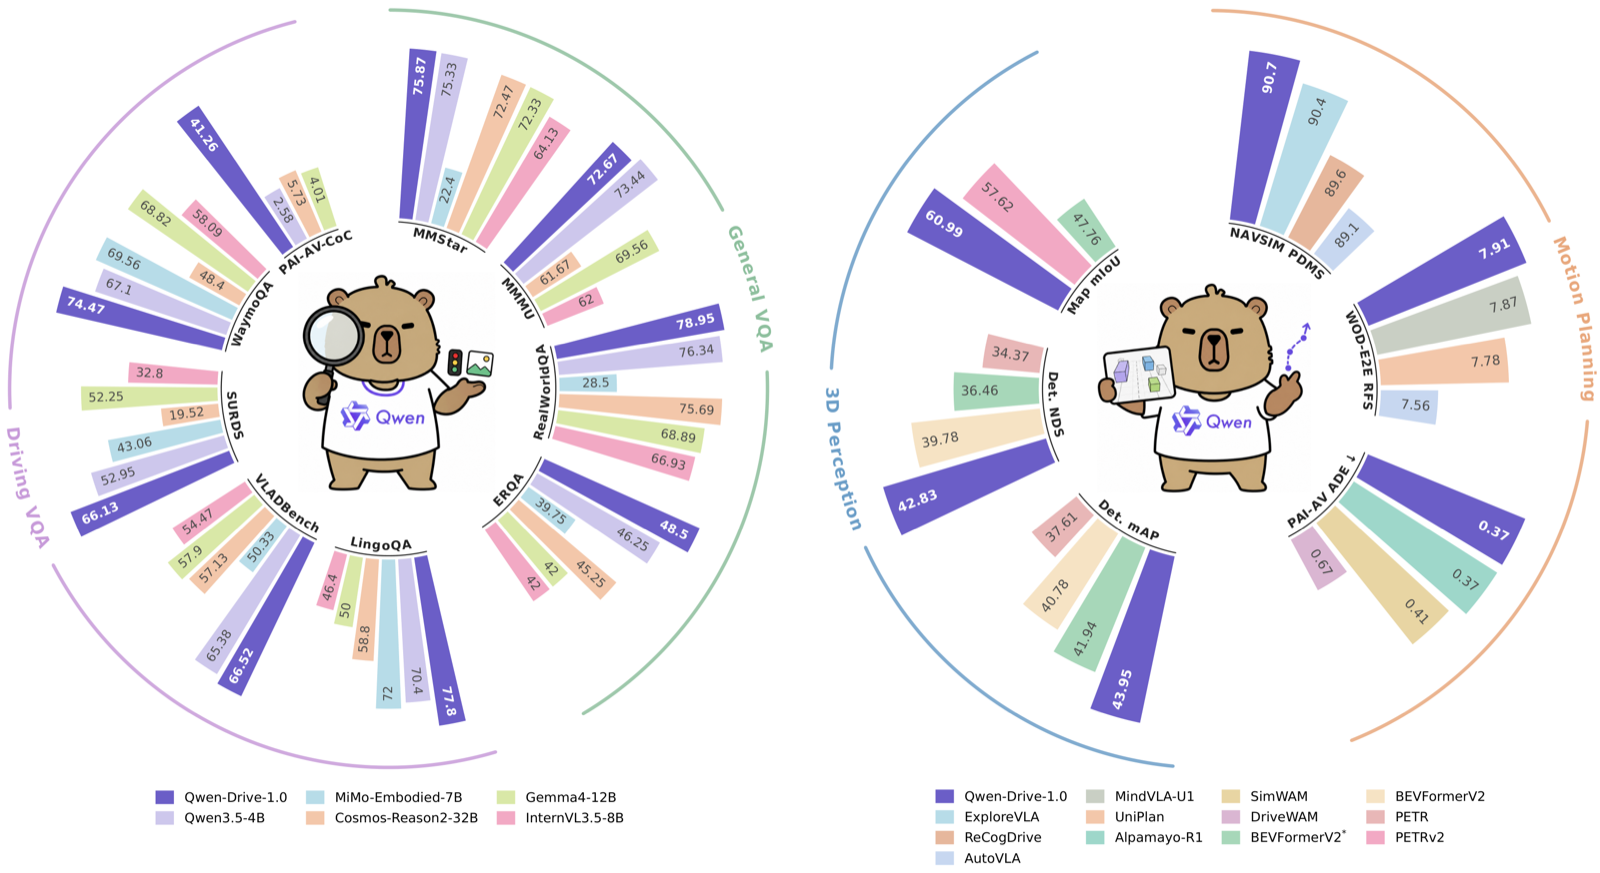
Alibaba’s Qwen team released Qwen-Drive-1.0-4B on September 7, 2026 — an open-weight vision-language foundation model for autonomous driving that puts 3D perception, driving question-answering, and motion planning inside a single 5-billion-parameter system. Developed with Huazhong University of Science and Technology and published under Apache 2.0 on Hugging Face, ModelScope, and GitHub, it is the Qwen […]
-
DeepSeek Open-Sources V4-Flash-Vision-Exp Ten Days After API Launch
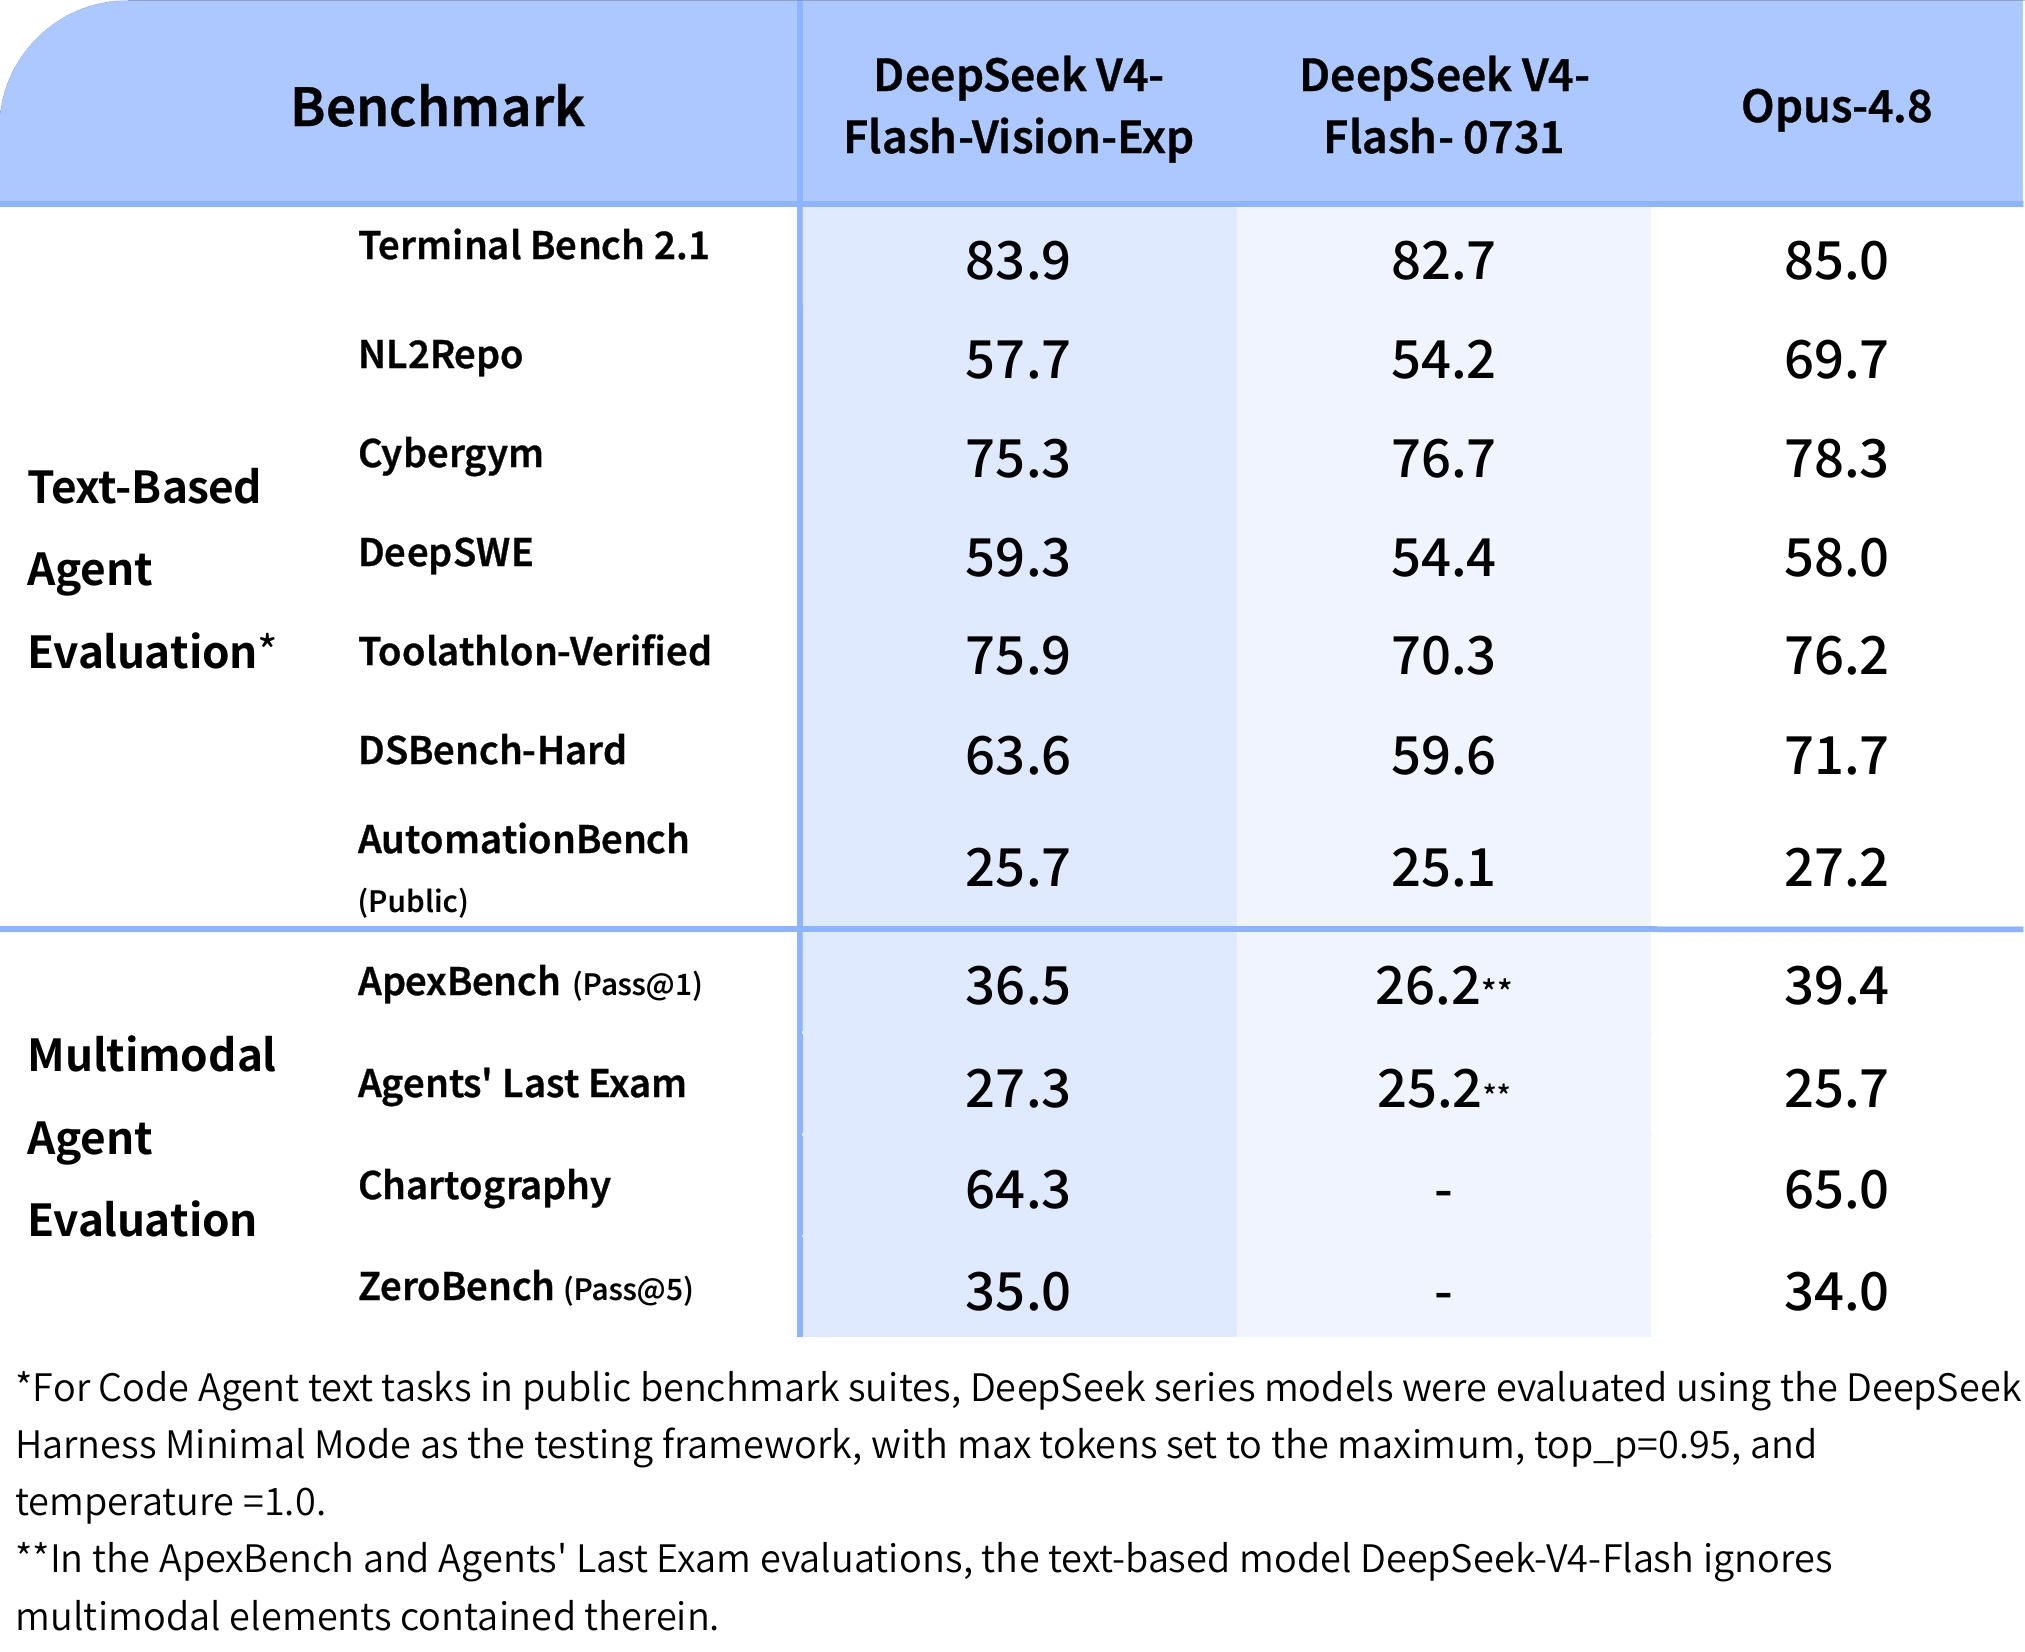
DeepSeek has published the weights for DeepSeek-V4-Flash-Vision-Exp, the first experimental multimodal model in its V4 family, releasing the checkpoint on Hugging Face under an MIT licence on August 31, 2026 — ten days after the same model went live on the DeepSeek API platform. The model card describes it as a system that “builds on […]
-
GLM-5.3-Flash: 320B Multimodal MoE, Weights on Day One
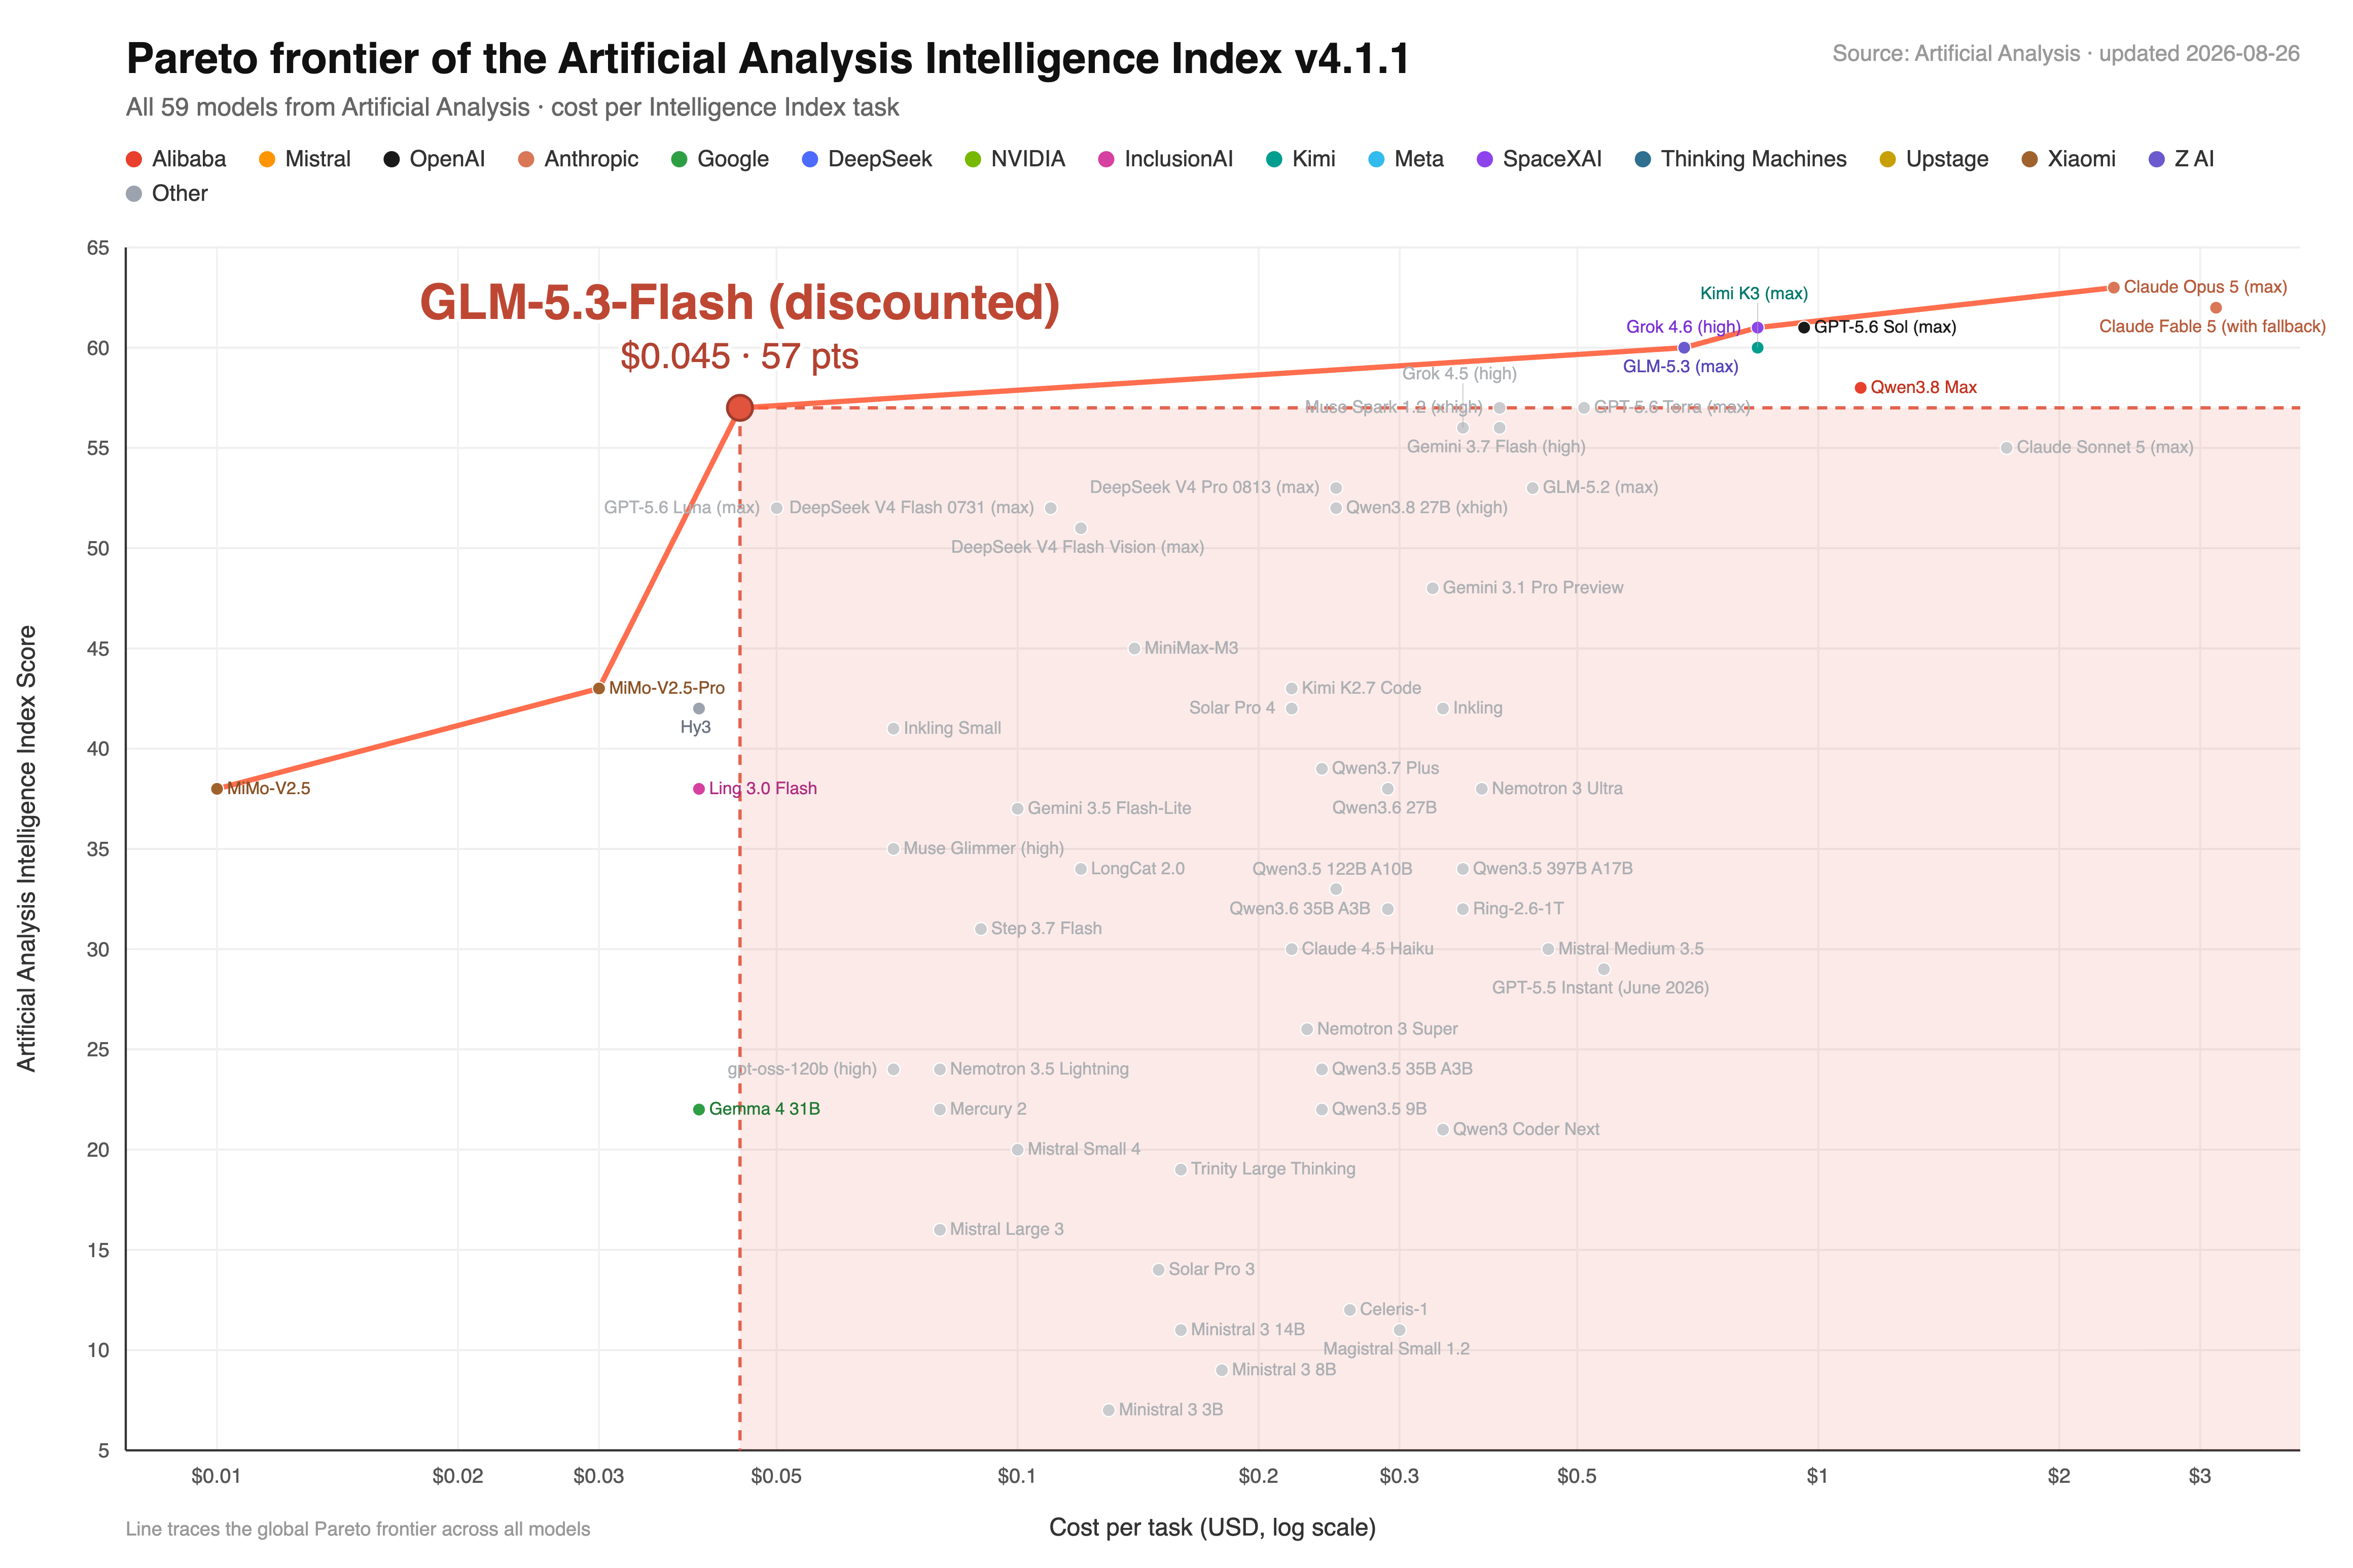
On August 26, 2026, Z.ai released GLM-5.3-Flash — a 320-billion-parameter Mixture-of-Experts model that activates just 18 billion parameters per token, and the first natively multimodal model in the GLM-5 series. It is also the release that inverts the pattern set twelve days earlier: GLM-5.3 shipped on August 14 with its weights held back for a […]
-
Mistral Releases Shieldstral, a 3B Policy-Adaptive Safety Classifier
On August 4, 2026, Mistral AI released Shieldstral 1.0 — a 3-billion-parameter open-weight safety classifier that judges both text and images against moderation policies written in plain language at inference time. Instead of shipping a fixed taxonomy of harm categories baked in during training, Shieldstral asks whatever question you hand it. Mistral says the model […]