Tag: multimodal
-
Black Forest Labs Unveils FLUX 3, a Multimodal Image, Video, Audio and Action Model
Black Forest Labs unveiled FLUX 3 on July 23, 2026 — a multimodal frontier model that jointly learns from images, video, and audio in a single unified architecture. The German lab that made its name with the open-weight FLUX.1 image models is pivoting from still images toward what it calls “visual intelligence,” with a headline […]
-
Qwen3.8-Max Preview: Alibaba’s 2.4T-Parameter Bid for the Frontier
Alibaba’s Qwen team announced Qwen3.8-Max-Preview on July 19, 2026 — a 2.4 trillion-parameter multimodal model the team calls its most capable system yet, claiming performance “second only to Fable 5” among the models it evaluated. The preview landed just two days after Moonshot AI’s 2.8 trillion-parameter Kimi K3 open-weight release, underscoring how quickly China’s frontier […]
-
Thinking Machines Releases Inkling, Its First Open-Weight Model
On July 15, 2026, Thinking Machines Lab released Inkling — its first model trained from scratch and, notably, its first open-weight release. Founded in February 2025 by former OpenAI CTO Mira Murati, the lab is best known for the Tinker fine-tuning platform; Inkling is a 975-billion-parameter Mixture-of-Experts model (41B active) published under the permissive Apache […]
-
SupraLabs Ships a 30M-Parameter Any-to-Any Model
SupraLabs has released Supra-A2A-Nano-Exp, an experimental ~30-million-parameter “any-to-any” model that handles text, images, and video in a single autoregressive transformer — small enough to run on a laptop CPU. Released under Apache 2.0 by the independent research group behind a string of trending ultra-small models, it is framed not as a capable generator but as […]
-
Google Releases Gemma 4 12B: Frontier Multimodal AI on a Laptop
Lead — On June 3, 2026, Google DeepMind released Gemma 4 12B, a unified, encoder-free multimodal model that brings frontier-class intelligence to a single 16 GB laptop. The 11.95-billion-parameter model handles text, images, and audio in one decoder-only transformer, supports a 256K-token context across 140+ languages, and ships under a fully permissive Apache 2.0 license. Google […]
-
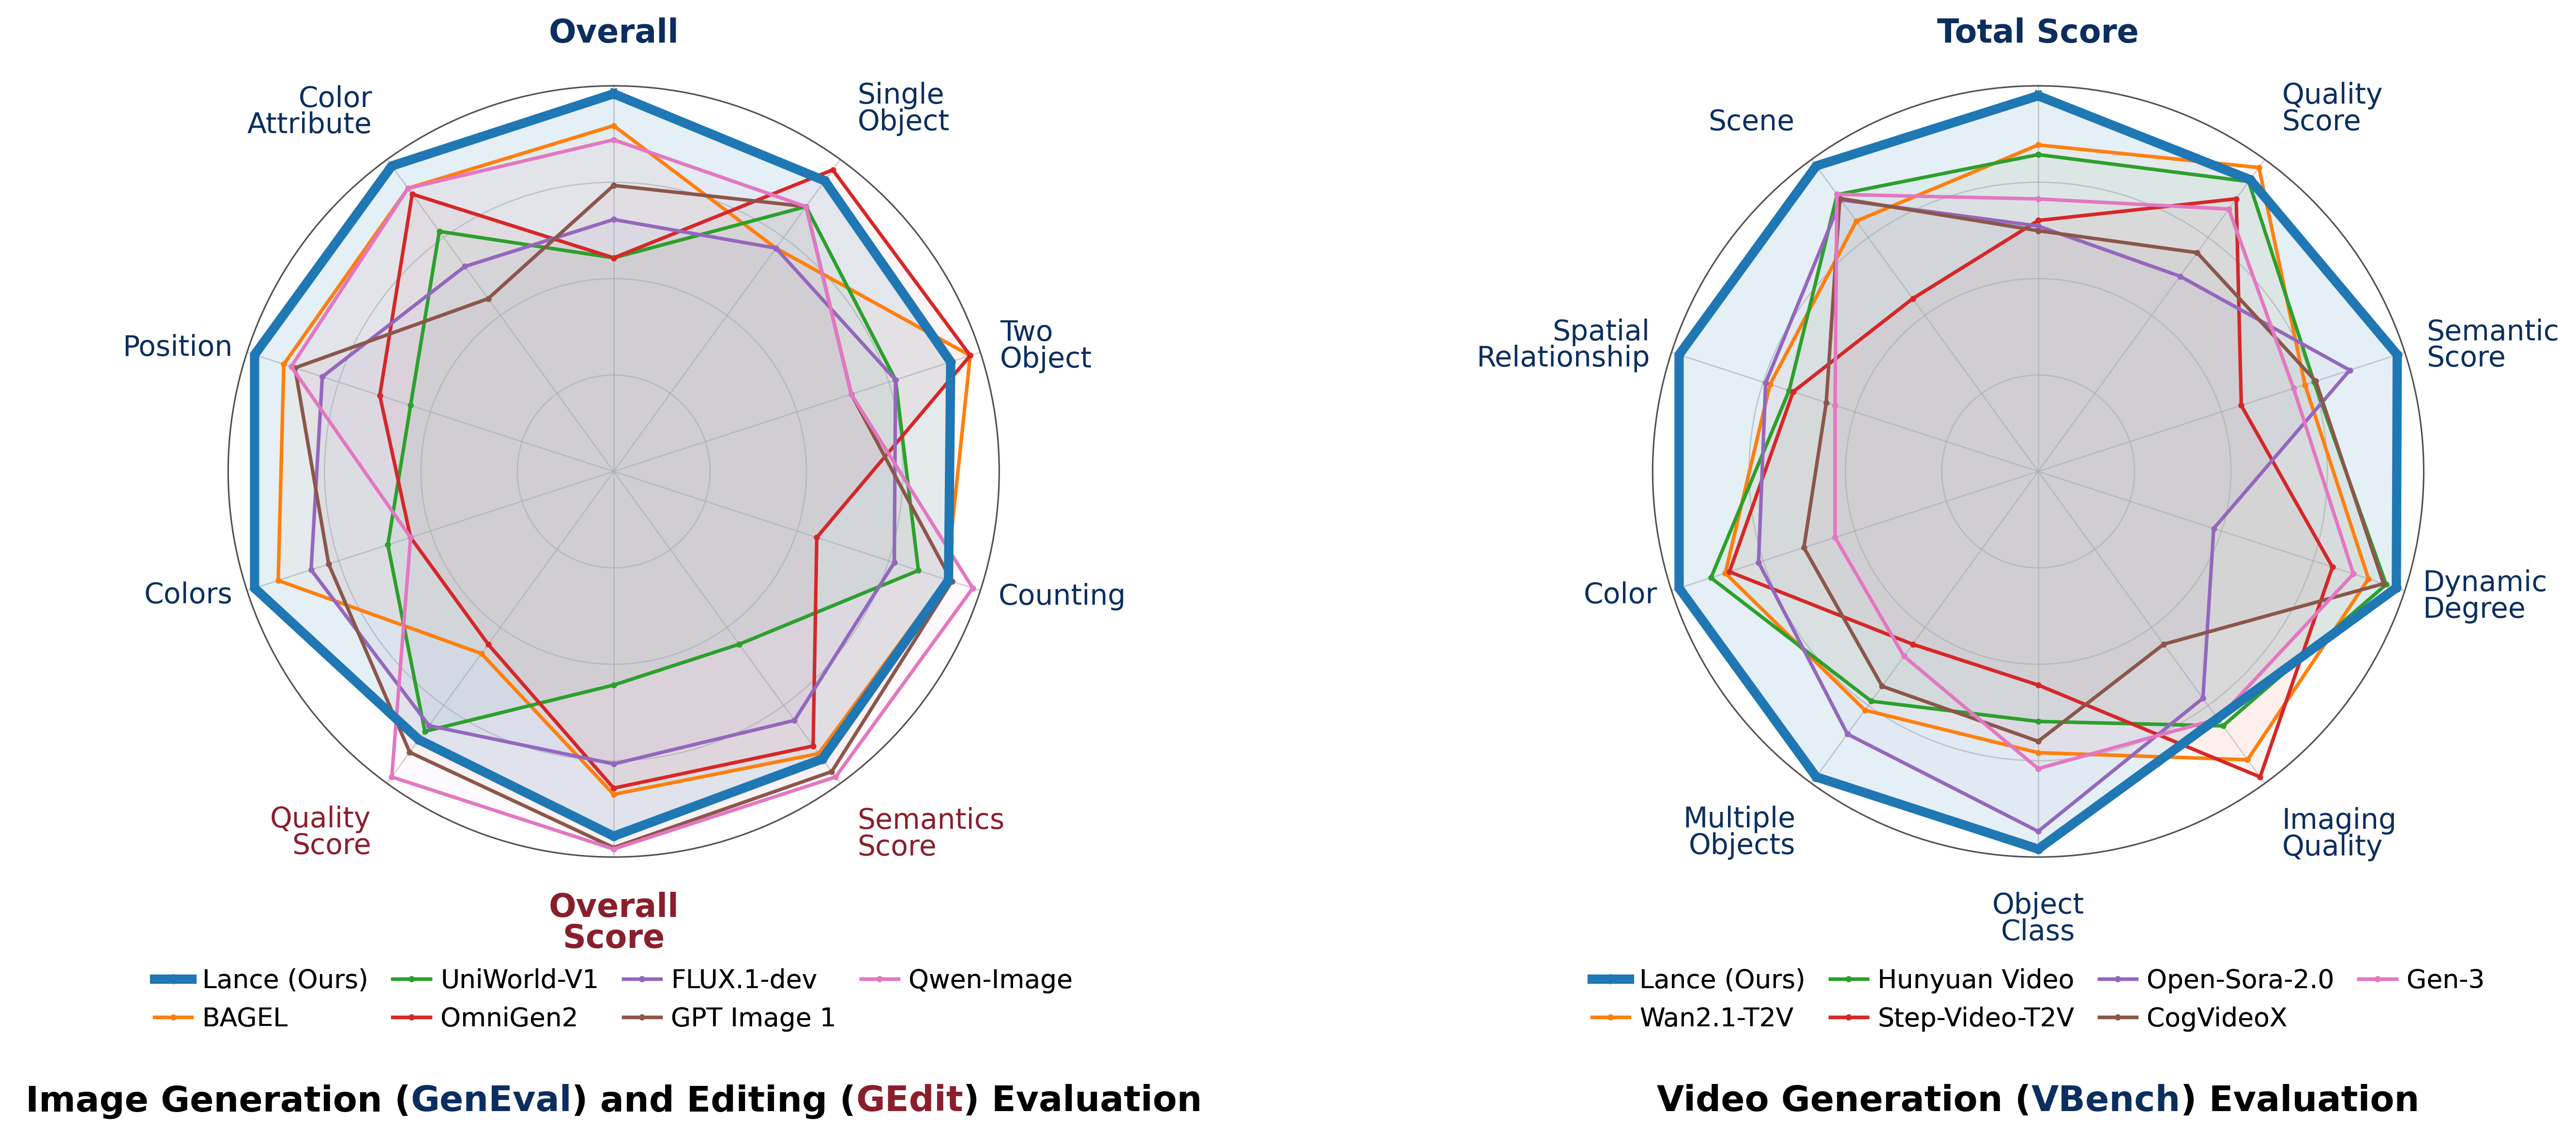
ByteDance Releases Lance, a 3B Unified Multimodal Model
ByteDance released Lance, a 3-billion-parameter native unified multimodal model, aiming to handle image understanding, text-to-image, image editing, text-to-video, and image-to-video in one lightweight open model. The release drew attention because it tries to compress a broad creative AI stack into a model size that is closer to local experimentation than cloud-only frontier systems. Intermediate Key […]
-
Google Introduces Gemini Omni and Gemini 3.5 at I/O
Google introduced Gemini Omni and Gemini 3.5 updates during I/O 2026, putting the Gemini app on a more multimodal, agentic path. The headline is not just a larger model: Google is presenting Gemini as an interface that can hear, see, reason over screens and documents, generate media, and connect those capabilities across Search, Workspace, Android, […]
-
Thinking Machines Unveils Interaction Models for Real-Time Human-AI Collaboration
Thinking Machines Lab announced its first “interaction models” on May 11, 2026, unveiling TML-Interaction-Small — a 276B-parameter mixture-of-experts model (12B active) designed for real-time, multimodal collaboration. Rather than waiting for the user to finish speaking, the model interleaves 200-millisecond chunks of audio and video input with simultaneous output generation, eliminating the turn-taking pause that defines […]
-
MiniCPM-V 4.6: A 1.3B Multimodal Model Built for Phones
OpenBMB released MiniCPM-V 4.6 on May 11, 2026 — the smallest entry in the MiniCPM-V family to date. At just 1.3B parameters, the new multimodal model handles single-image, multi-image, and video understanding while running on consumer phones across iOS, Android, and HarmonyOS. The model is open-weight under Apache 2.0 and ships with vLLM, SGLang, llama.cpp, […]
-
Liquid AI’s LFM2-VL-450M: Vision-Language AI in Half a Billion Parameters
Liquid AI has released LFM2-VL-450M, a 450-million-parameter vision-language model designed for on-device inference. Built on Liquid’s LFM2-350M language backbone and an 86M-parameter SigLIP2 NaFlex vision encoder, the model delivers 2× faster inference than comparable VLMs on GPUs while processing images at native resolution — all under an Apache 2.0 license. Intermediate Key points Liquid AI […]