Tag: multimodal
-
Google Releases Gemma 4: Frontier Open Models Under Apache 2.0
On April 2, 2026, Google DeepMind released Gemma 4 — its most capable open model family to date, purpose-built for advanced reasoning and agentic workflows. Available under a fully permissive Apache 2.0 license, Gemma 4 delivers frontier-class multimodal intelligence across four model sizes, from edge devices to high-performance workstations. Intermediate Key points On April 2, […]
-
Qwen3.5-Omni: Alibaba’s Omnimodal AI Speaks 36 Languages and Codes from Voice
On March 30, 2026, Alibaba’s Qwen team released Qwen3.5-Omni — a natively omnimodal AI model that processes text, images, audio, and video while generating real-time speech output. Available in three sizes (Plus, Flash, and Light), the model claims 215 state-of-the-art benchmark results and introduces features like semantic interruption, voice cloning, and an emergent “Audio-Visual Vibe […]
-
Google Launches Gemini Embedding 2: Its First Multimodal Embedding Model
On March 10, 2026, Google DeepMind released Gemini Embedding 2 — the company’s first natively multimodal embedding model. Unlike traditional embedding models that handle only text, Gemini Embedding 2 maps text, images, video, audio, and documents into a single unified vector space, enabling cross-modal search, classification, and clustering across over 100 languages. Intermediate Key points […]
-
Microsoft Releases Phi-4-Reasoning-Vision-15B: Small Model, Big Vision
Key points Microsoft released Phi-4-reasoning-vision-15B on March 4, 2026, a compact open-weight multimodal model that combines high-resolution visual perception with selective reasoning. It uses a mid-fusion architecture pairing a SigLIP-2 Naflex vision encoder, which processes up to 3,600 visual tokens at dynamic resolution, with the Phi-4-Reasoning language backbone. About 80% of training data uses <nothink> […]
-
Qwen 3.5 Small Models: 9B Parameters That Beat 120B
Key points On March 2, 2026, Alibaba’s Qwen team completed the Qwen 3.5 family with four small dense models of 0.8B, 2B, 4B, and 9B parameters for on-device and edge deployment. All four models are open-weight under Apache 2.0 and available on Hugging Face and ModelScope. Qwen3.5-9B outperforms models 3-13 times its size across language, […]
-
Qwen 3.5 Medium Series: Frontier AI That Fits on Your GPU
Key points On February 24, 2026, Alibaba’s Qwen team expanded the Qwen 3.5 family with three Apache 2.0 open-weight models — Qwen3.5-27B, Qwen3.5-35B-A3B, and Qwen3.5-122B-A10B — available on Hugging Face. Qwen3.5-27B is a dense model with all 27 billion parameters active at inference, optimized for coding and instruction-following, and uses a 3:1 hybrid ratio of […]
-
Google Releases Gemini 3.1 Pro with 2× Reasoning Performance
Key points Google DeepMind released Gemini 3.1 Pro on February 19, 2026, describing it as its most capable model to date and the first in the Gemini family to receive a “.1” mid-cycle update rather than the usual “.5” increment. Gemini 3.1 Pro scores 77.1% on ARC-AGI-2, which the article says is more than double […]
-
Qwen 3.5: Alibaba’s Native Multimodal Agent Model Arrives
Key points Alibaba’s Qwen team released Qwen 3.5 on February 16, 2026, with a flagship 397B-parameter mixture-of-experts model built for the agentic AI era. The flagship Qwen3.5-397B-A17B activates only 17 billion parameters per forward pass despite having 397 billion total parameters. Listed specifications include a 256K-token native context window, 1M tokens on the hosted Qwen3.5-Plus, […]
-
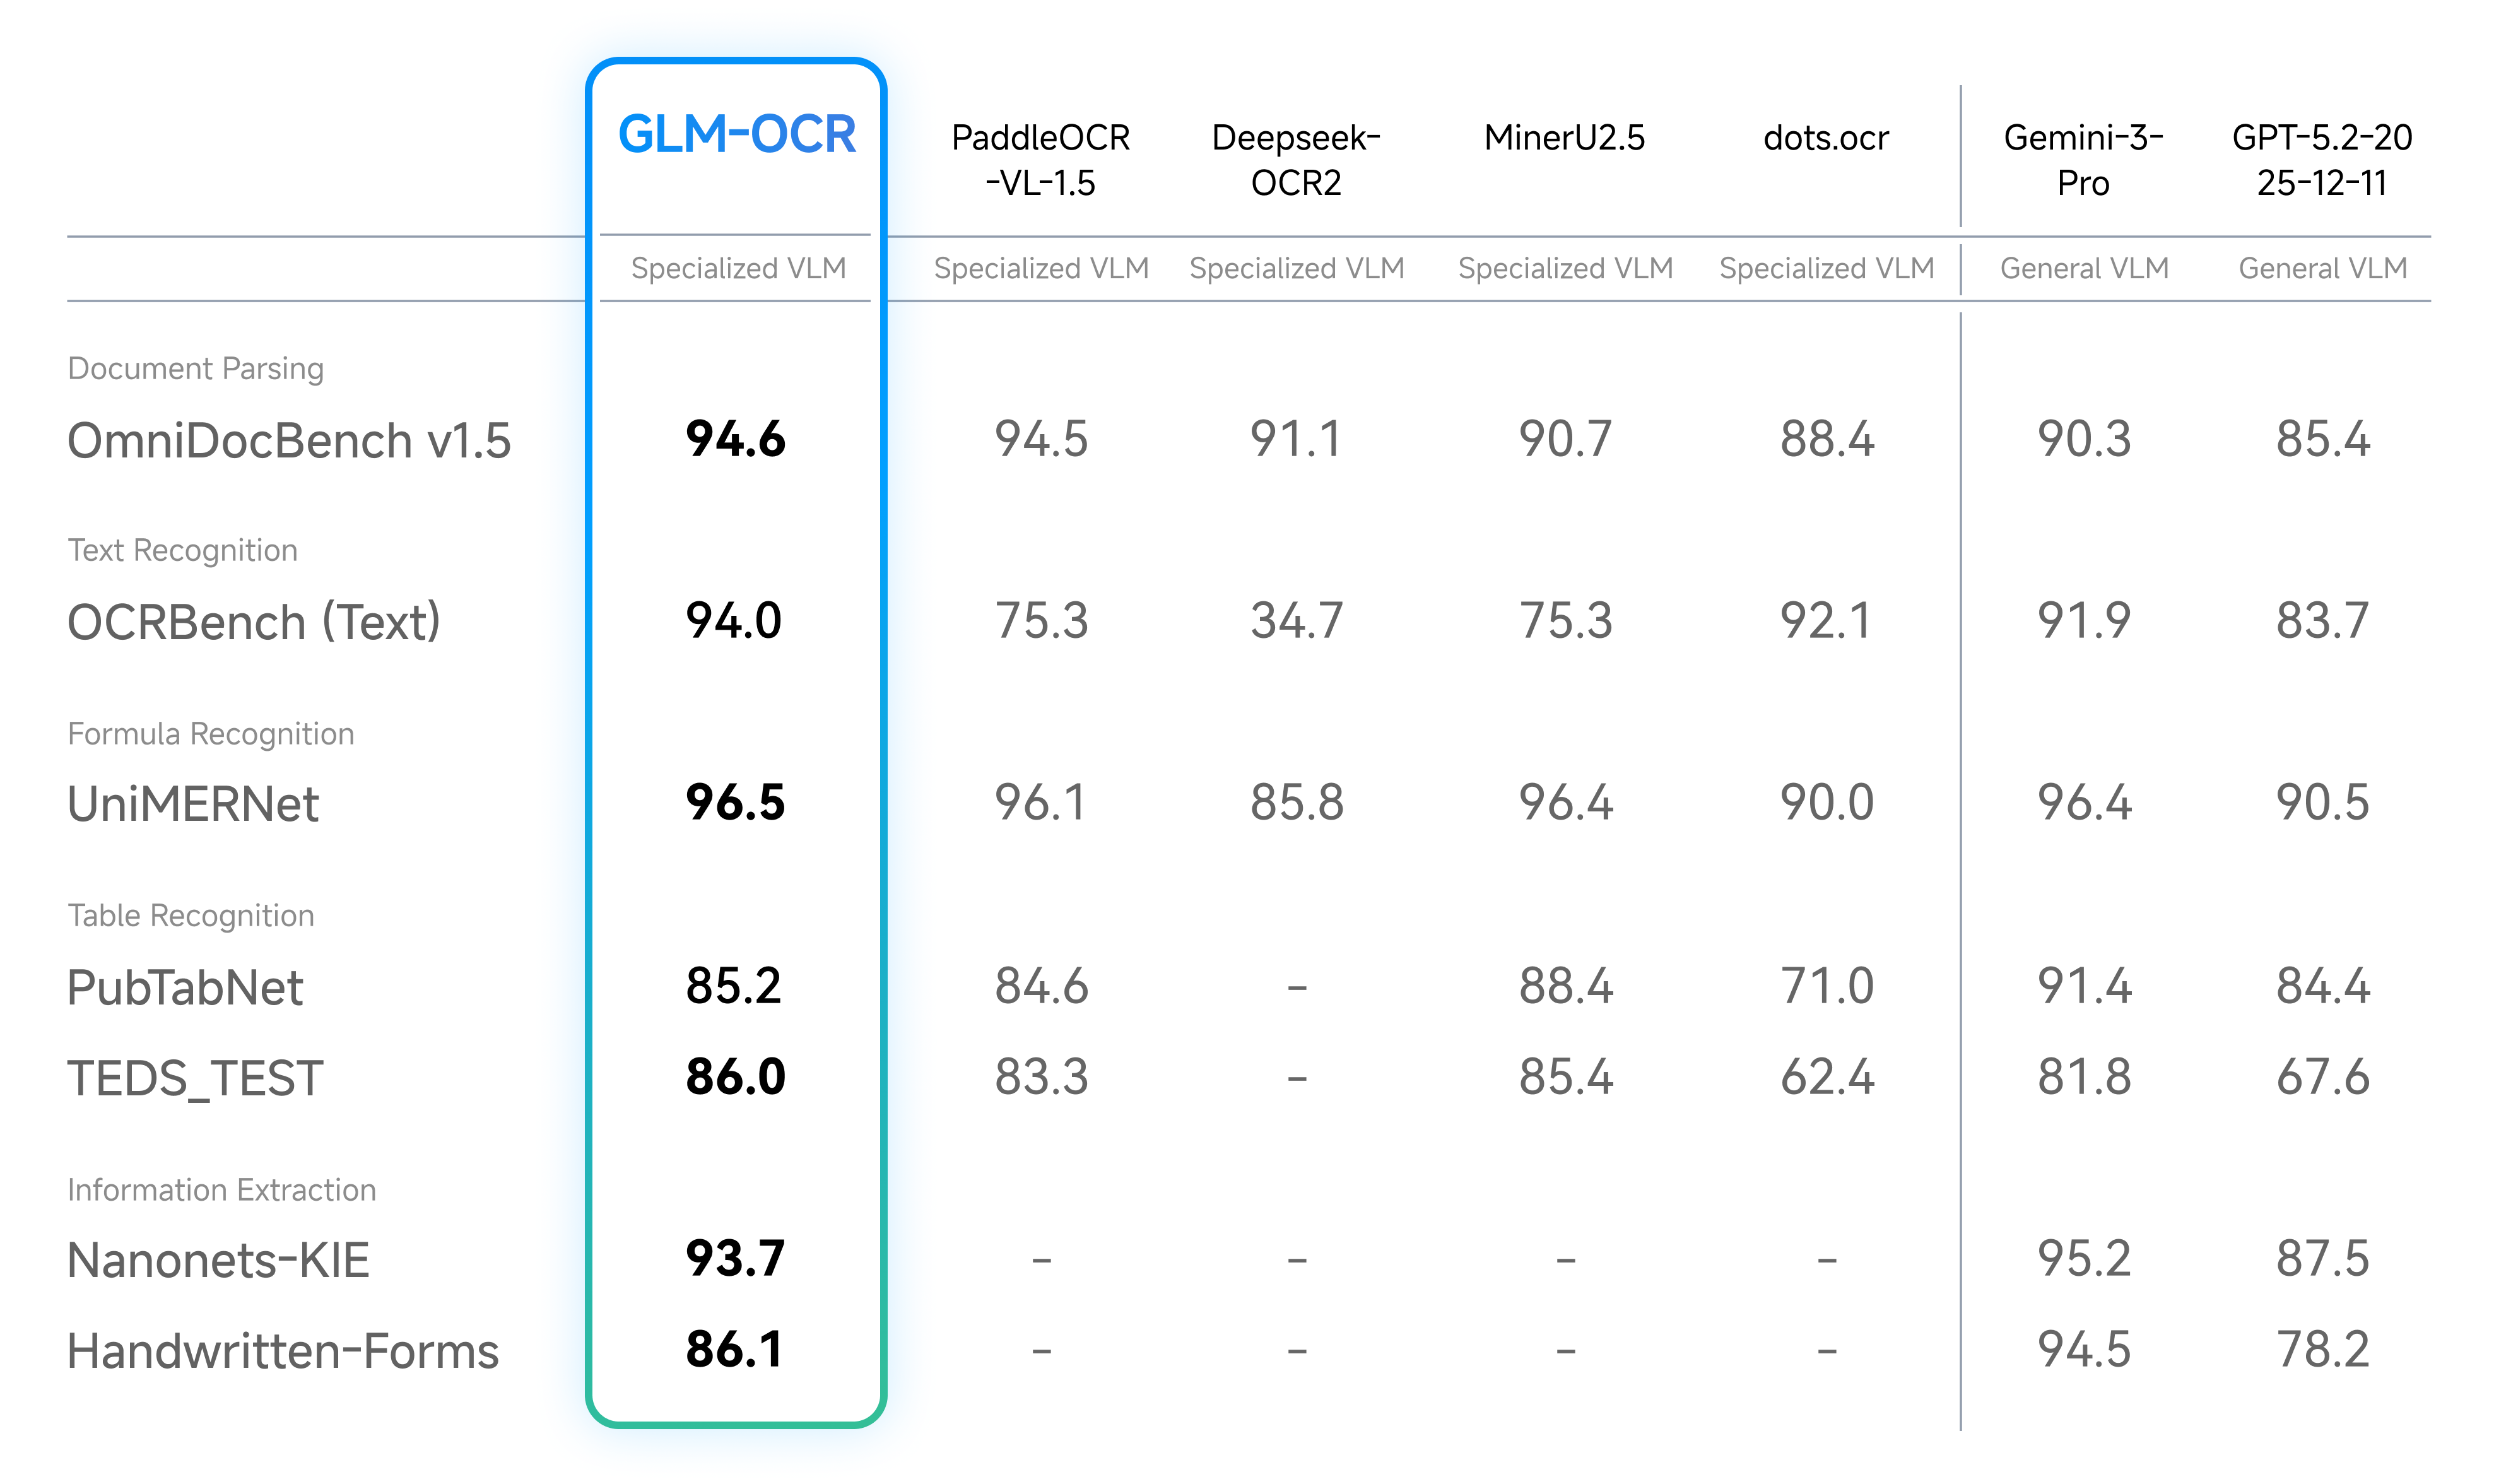
GLM-OCR: Z.ai’s 0.9B Model Takes the Top Spot on Document Understanding Benchmarks
Key points Z.ai has open-sourced GLM-OCR, a compact multimodal model with 0.9 billion parameters that ranks first on OmniDocBench V1.5 with a score of 94.62. GLM-OCR is a multimodal optical character recognition model developed by Z.ai, the commercial arm of ZhipuAI, and designed specifically for complex document understanding. It supports three core recognition modes: general […]
-
Moonshot AI Releases Kimi K2.5 with Agent Swarm and Frontier Vision
Key points Moonshot AI released Kimi K2.5 on January 27, 2026, an open-weight model combining a trillion-parameter Mixture-of-Experts architecture with native multimodal reasoning and Agent Swarm. Kimi K2.5 is built on a Mixture-of-Experts architecture with 1 trillion total parameters, of which only 32 billion are activated per token. Agent Swarm decomposes complex tasks into subtasks […]