On April 2, 2026, Google DeepMind released Gemma 4 — its most capable open model family to date, purpose-built for advanced reasoning and agentic workflows. Available under a fully permissive Apache 2.0 license, Gemma 4 delivers frontier-class multimodal intelligence across four model sizes, from edge devices to high-performance workstations.
Intermediate
Key points
- On April 2, 2026, Google DeepMind released Gemma 4, which it describes as its most capable open model family to date, under a fully permissive Apache 2.0 license.
- Gemma 4 ships in four variants: E2B with 2.3B effective parameters, E4B with 4.5B effective parameters, a 26B A4B mixture-of-experts model with 26B total and 3.8B active parameters, and a 31B dense flagship with 30.7B parameters.
- Google’s reported benchmark figures put the flagship 31B model at 89.2% on AIME 2026, 85.2% on MMLU Pro, 80.0% on LiveCodeBench v6 and 84.3% on GPQA Diamond, with the 26B A4B behind on each.
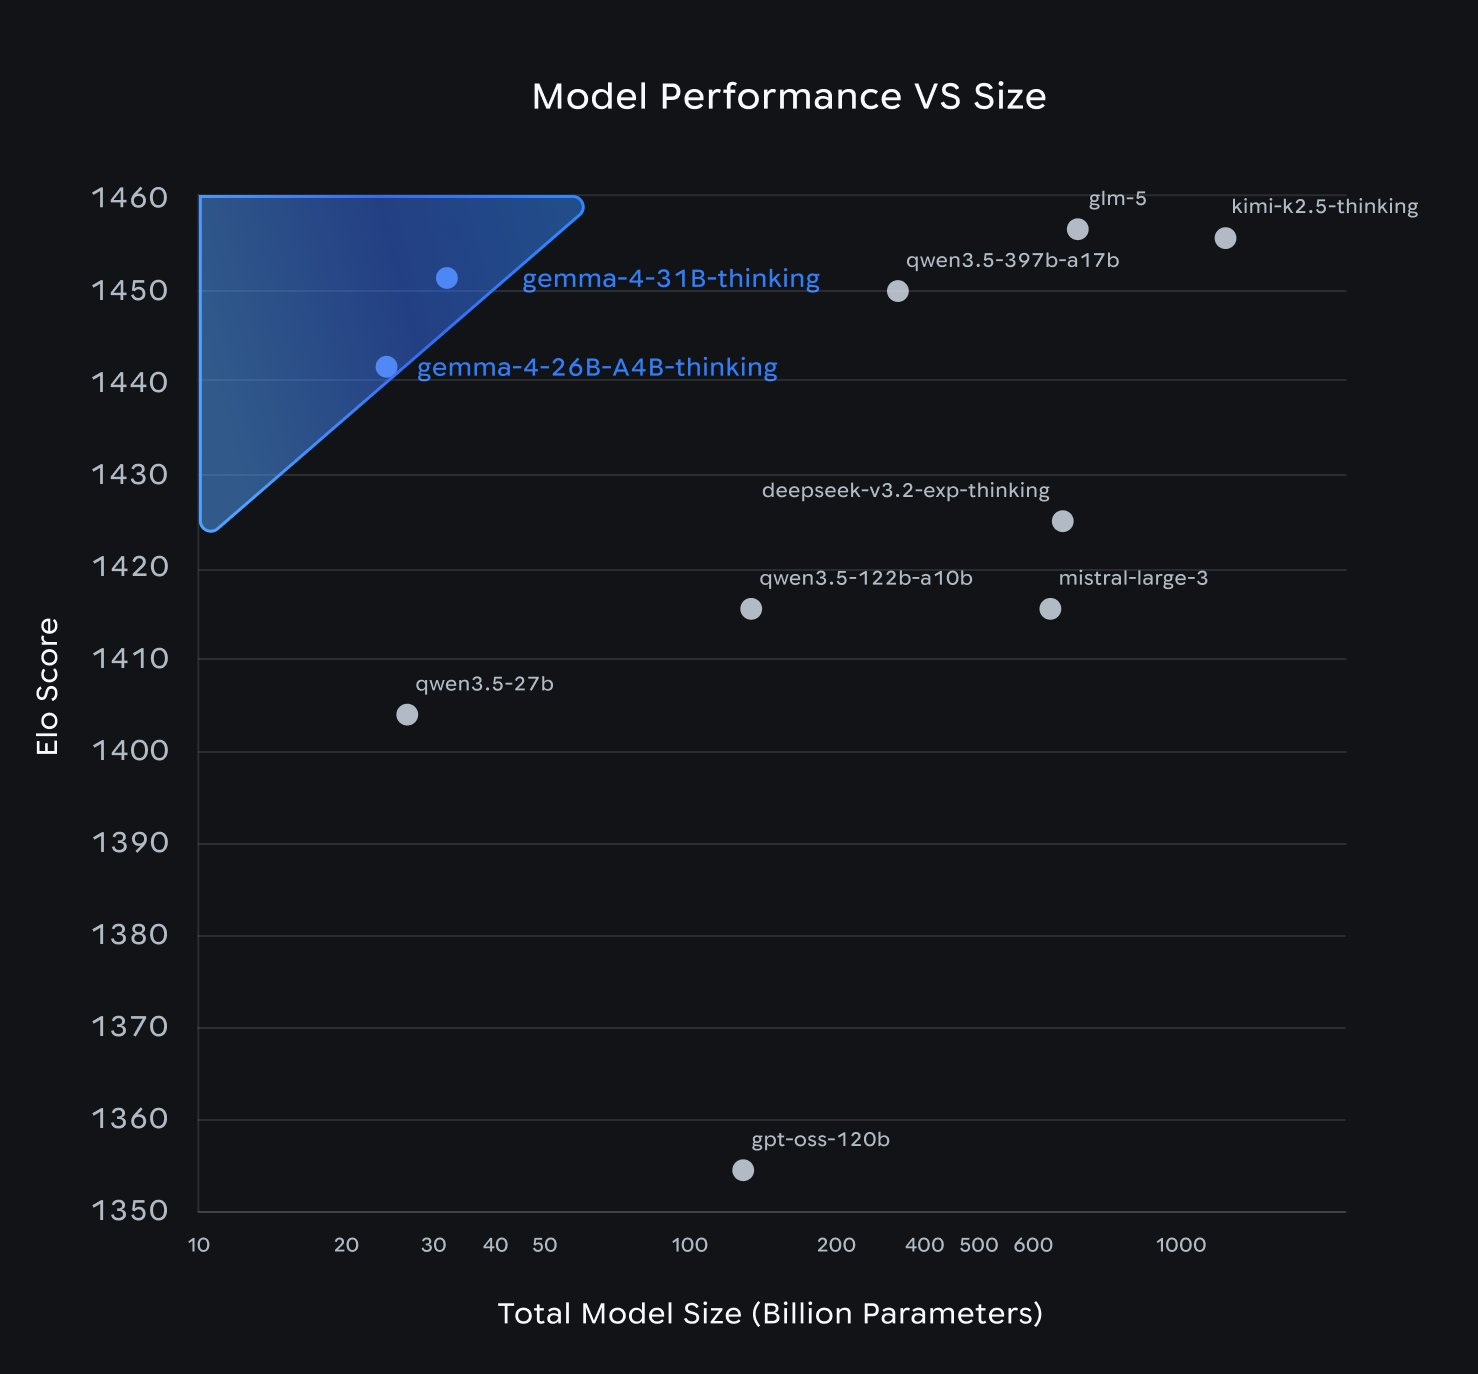
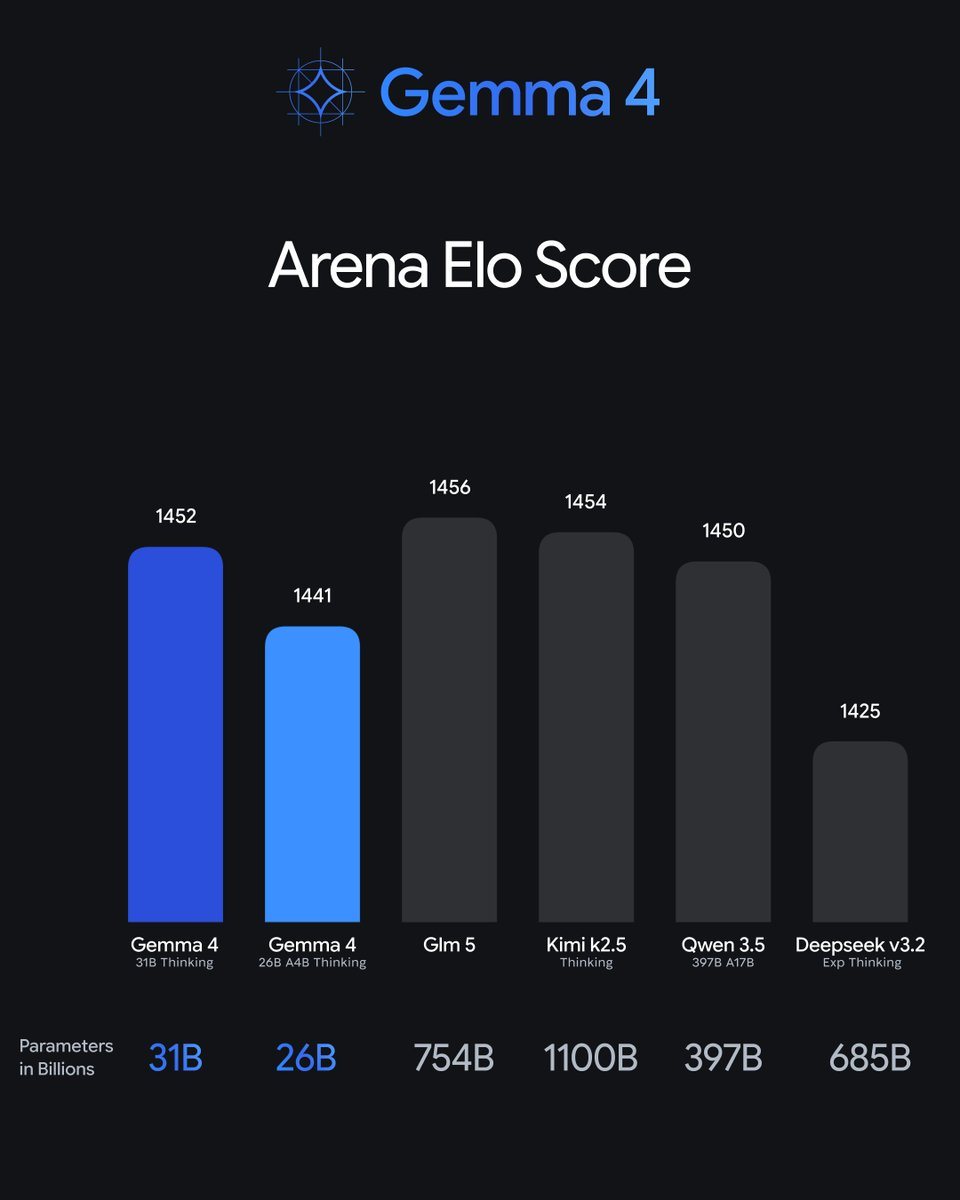
- The source reports the 31B model ranked #3 among all open models on the LMArena text leaderboard at about 1,452, with the 26B MoE close behind at #6 around 1,441 despite using only 4B active parameters per forward pass.
- Gemma 4 adds architectural features including Alternating Attention, Per-Layer Embeddings, a shared KV cache and a dynamic vision encoder supporting configurable token budgets.
Four Models, One Family
Gemma 4 ships in four variants, each targeting a different deployment scenario:
- E2B (2.3B effective parameters) — ultra-compact edge model with 128K context, native audio input
- E4B (4.5B effective parameters) — mid-range edge model with 128K context, native audio input
- 26B A4B (Mixture-of-Experts: 26B total, 3.8B active) — MoE model with 256K context, only 4B parameters active per inference
- 31B Dense (30.7B parameters) — the flagship dense model with 256K context window
All models are natively multimodal, processing text and images with variable resolution support. The edge models (E2B and E4B) additionally support native audio input for real-time speech understanding on-device. Video processing is supported across the family.
Benchmark Performance
Gemma 4’s flagship 31B dense model delivers impressive results that compete with models many times its size:
- AIME 2026: 89.2% (31B) / 88.3% (26B A4B)
- MMLU Pro: 85.2% (31B) / 82.6% (26B A4B)
- LiveCodeBench v6: 80.0% (31B) / 77.1% (26B A4B)
- GPQA Diamond: 84.3% (31B) / 82.3% (26B A4B)
- Codeforces ELO: 2,150 (31B)
- MMMU Pro (Vision): 76.9% (31B) / 73.8% (26B A4B)
- MATH-Vision: 85.6% (31B) / 82.4% (26B A4B)
The 31B model currently ranks #3 among all open models on the LMArena text leaderboard (score ~1,452), with the 26B MoE close behind at #6 (~1,441) — despite using only 4B active parameters per forward pass.
Architecture Innovations
Under the hood, Gemma 4 introduces several architectural advances built on the Gemini 3 foundation:
- Alternating Attention: Interleaves local sliding-window attention (512–1024 tokens) with global full-context layers, balancing efficiency and long-range reasoning
- Per-Layer Embeddings (PLE): A second embedding table feeds residual signals into every decoder layer for richer representations
- Shared KV Cache: Later layers reuse key-value states from earlier ones, cutting memory without sacrificing quality
- Dynamic Vision Encoder: Supports variable aspect ratios with configurable token budgets (70 to 1,120 tokens per image), letting developers trade off detail for speed
Apache 2.0 and the Open Model Landscape
Perhaps the most significant change from previous Gemma releases is the shift to a full Apache 2.0 license — granting unrestricted commercial use, modification, and redistribution with no royalties or usage restrictions. This positions Gemma 4 directly against other permissively licensed models like Meta’s Llama family and Mistral’s offerings.
The models are already available on Hugging Face with Day 1 support across major frameworks including Transformers, llama.cpp (GGUF quantizations), MLX for Apple Silicon, and ONNX for edge deployment. Google is also integrating Gemma 4 as the foundation for the next generation of Gemini Nano on Android devices.
Related Coverage
- Unveiling T5Gemma: Google’s New Encoder-Decoder Gemma Models — Google’s encoder-decoder models built on the Gemma 2 architecture
- Gemma 7B is the new SOTA 7B LLM — the original Gemma launch in February 2024
- Google Releases Gemini 3.1 Pro with 2x Reasoning Performance — the Gemini 3 foundation that powers Gemma 4
This post was drafted with AI assistance and reviewed by RITS staff.
Sources
- Gemma 4: Byte for byte, the most capable open models — Google Blog
- Welcome Gemma 4: Frontier multimodal intelligence on device — Hugging Face
- Gemma 4 Model Card — Google AI for Developers
- Gemma 4: Expanding the Gemmaverse with Apache 2.0 — Google Open Source Blog
- Google announces open Gemma 4 model with Apache 2.0 license — 9to5Google
Leave a Reply