Tag: llm
-
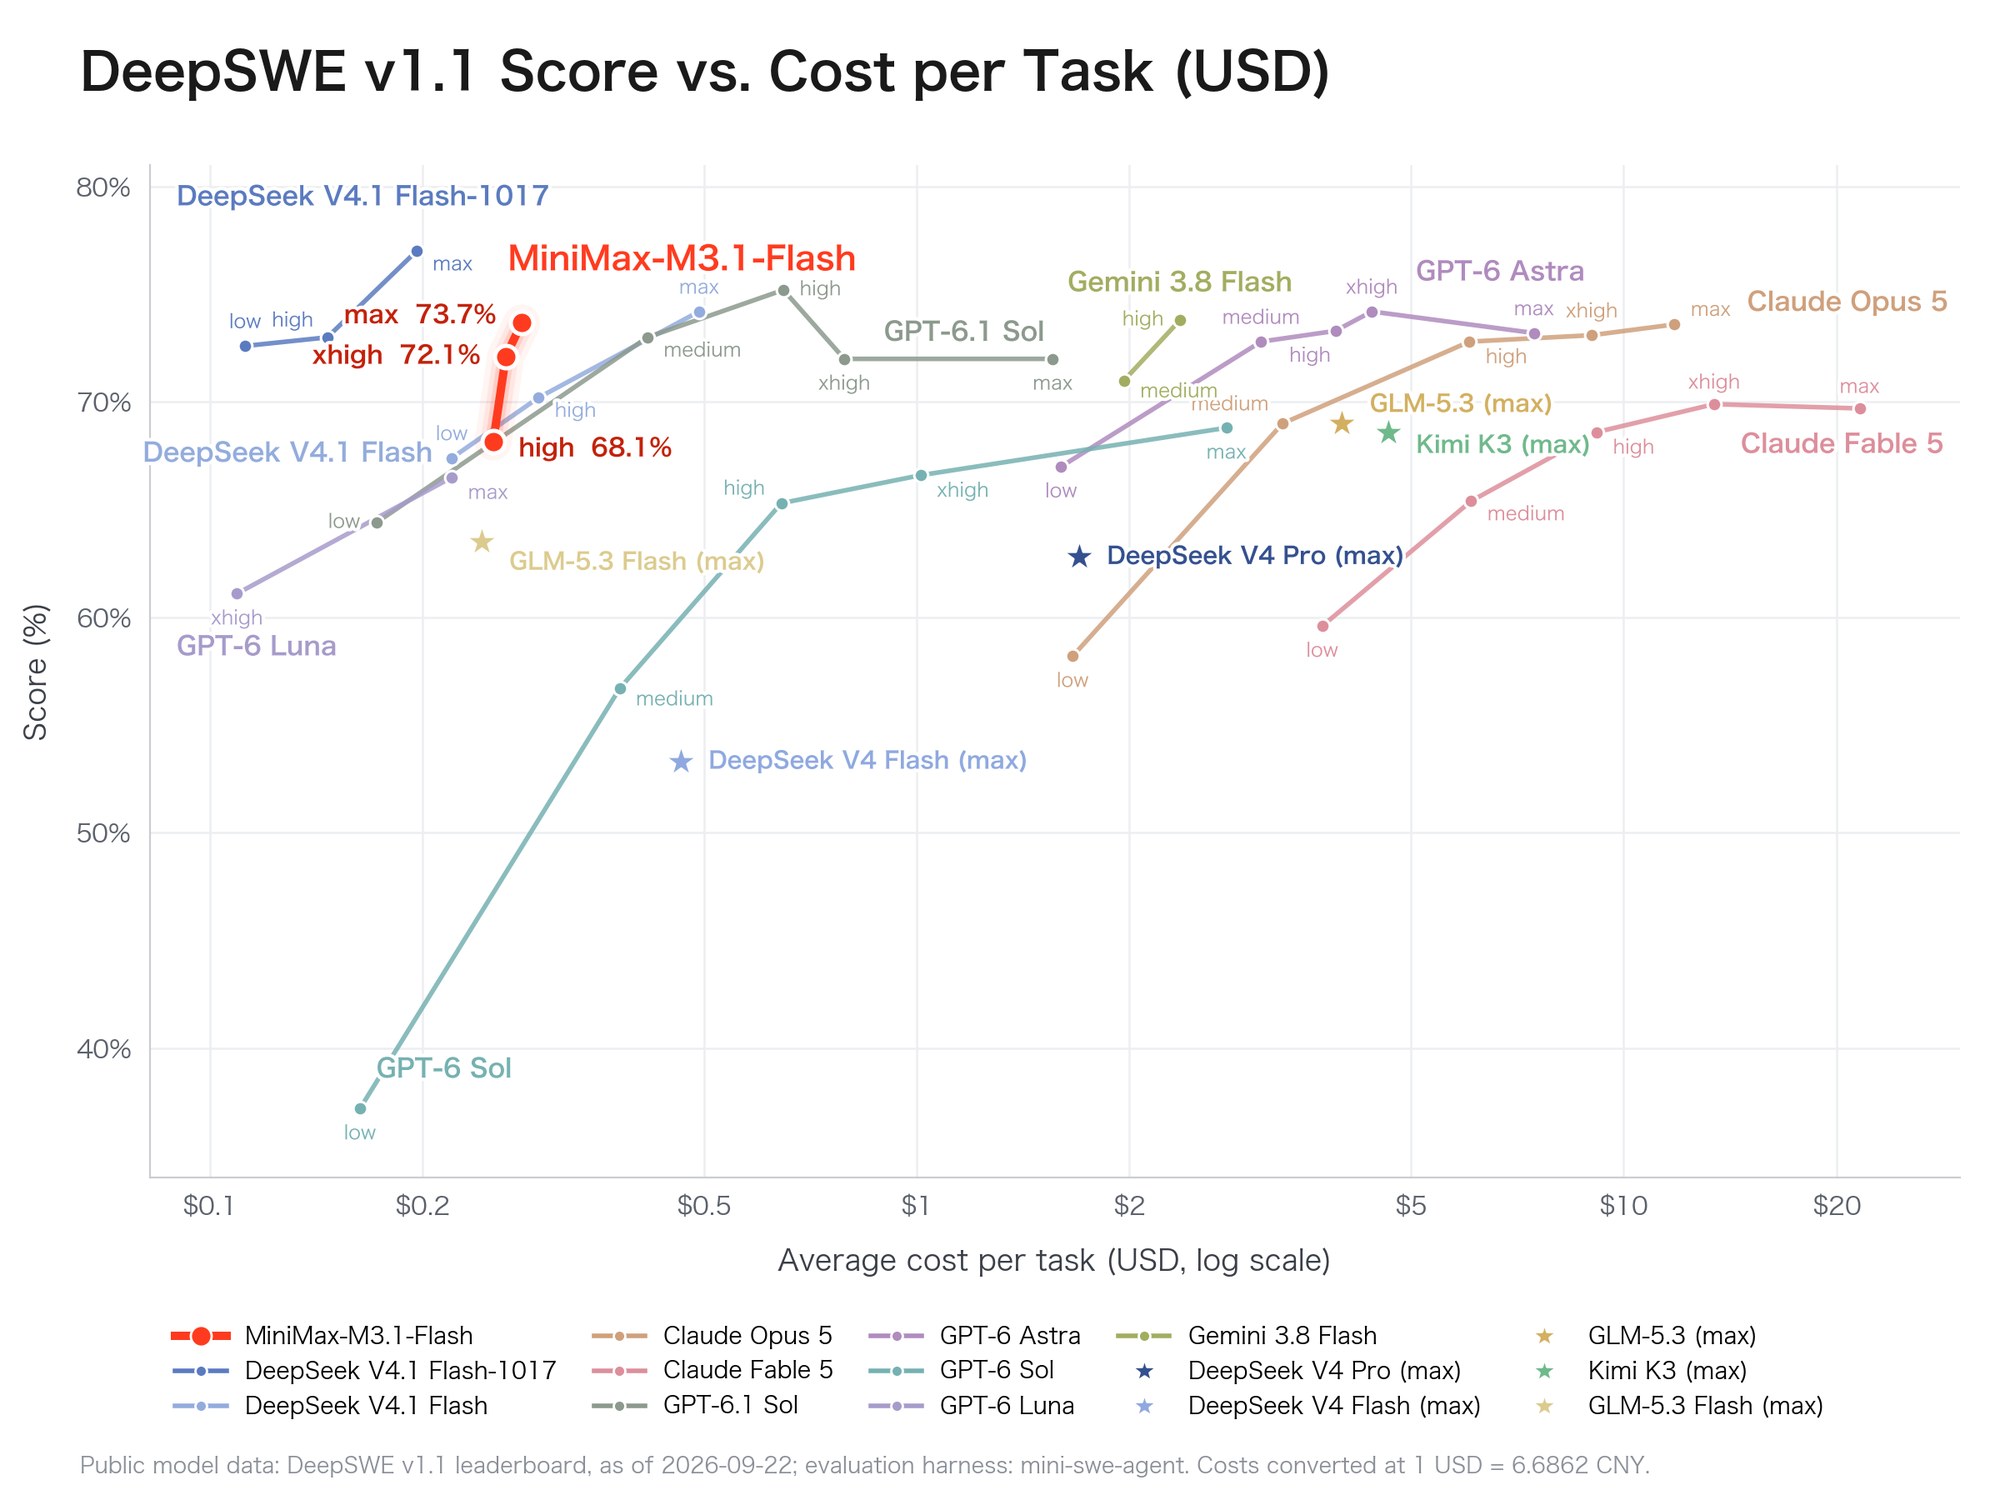
MiniMax Ships M3.1 Flash: API Now, Weights Due October 23
On October 19, 2026, MiniMax released M3.1 Flash, a faster and cheaper successor to June’s M3, and put it on its API the same day — but the weights are not out yet. MiniMax’s launch post says only that the weights “will be released later”. The Decoder and SiliconANGLE both report October 23. Until a […]
-
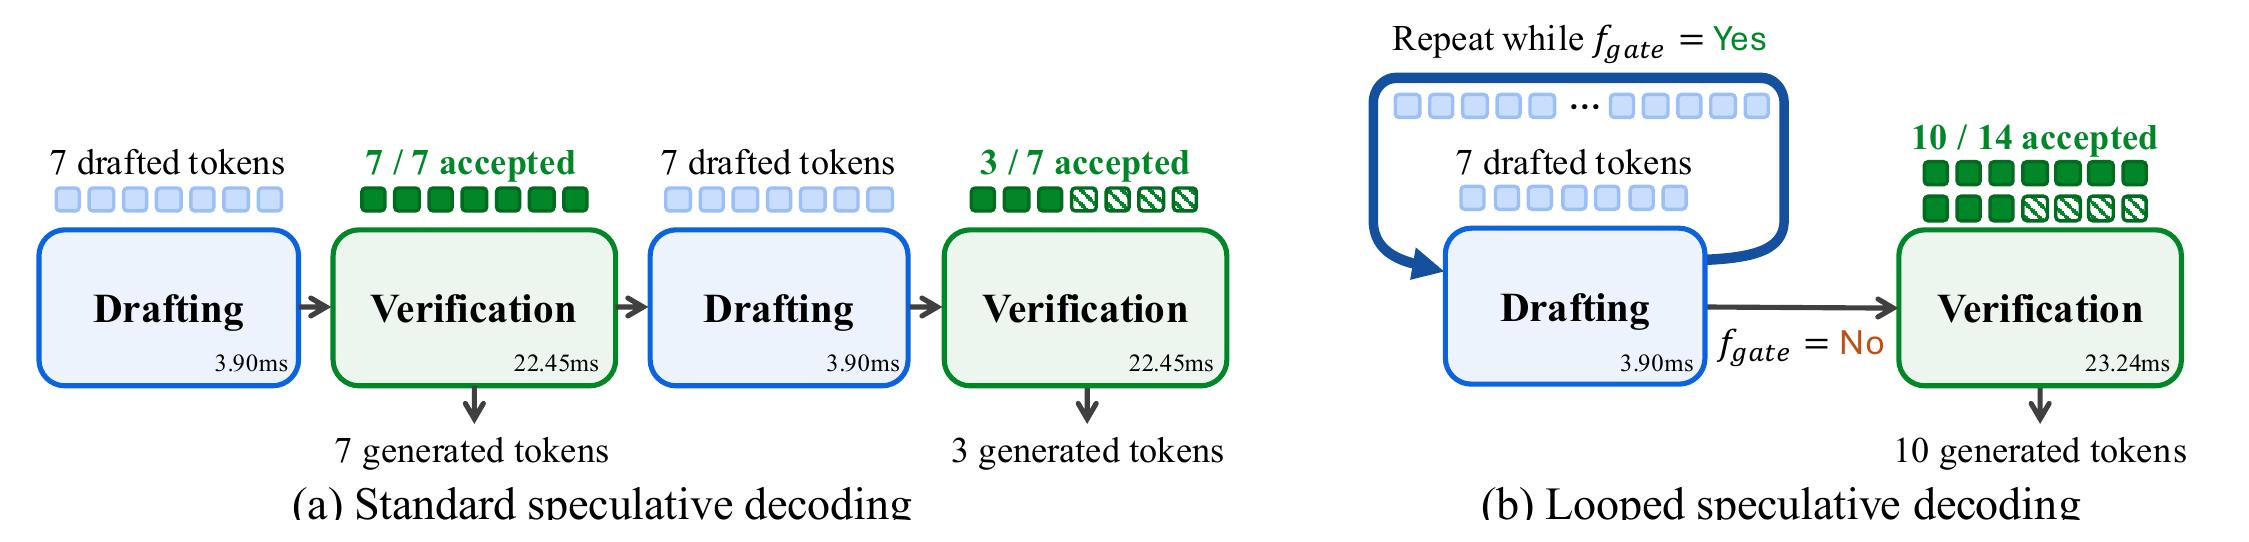
DLoop: Looped Speculative Decoding Cuts Target-Model Passes
NAVER AI Lab has proposed DLoop, a change to speculative decoding that lets a single verification pass cover several rounds of drafting instead of just one. In a preprint posted to arXiv on October 6, 2026, the team reports wall-clock speedups 5 to 41 percent higher than the draft models it builds on — EAGLE-3, […]
-
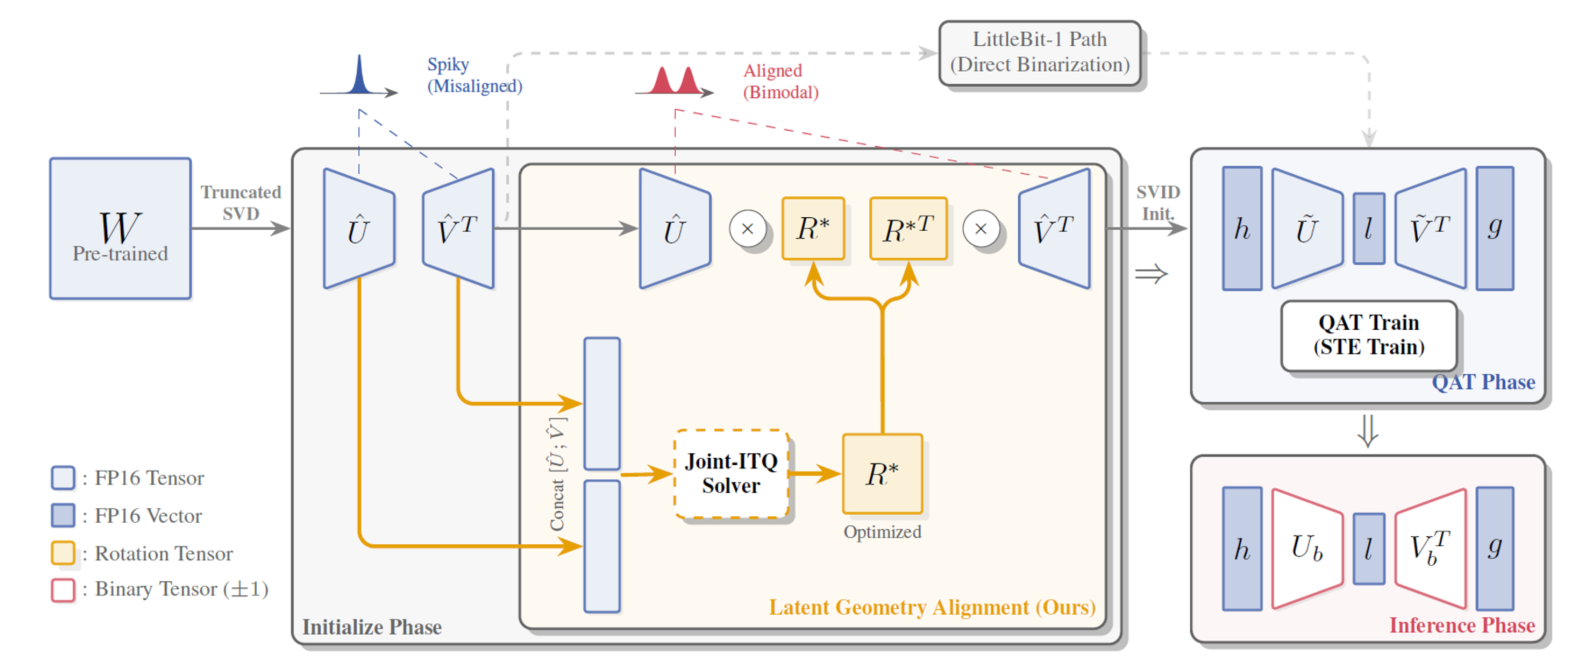
LittleBit-2: Samsung’s Sub-1-Bit LLMs via Latent Geometry Alignment
Lead — On July 23, 2026, Samsung Research published LittleBit-2, the successor to a compression method that pushes large language models below one bit per weight. Presented at ICML 2026, LittleBit-2 keeps the original LittleBit architecture from NeurIPS 2025 but changes one thing: how the compressed weights are initialized. That single change takes the method […]
-
Mistral Large 4: Europe’s 1T Open-Weight Model Enters Preview
On October 6, 2026, Mistral AI opened a public preview of Mistral Large 4 — a 1.05-trillion-parameter, natively multimodal model with 52 billion active parameters. Nicknamed “le Chonk” and unofficially ML4, it is the Paris-based lab’s largest model to date and, on Mistral’s own numbers, the strongest open-weight model developed outside China. The preview API […]
-
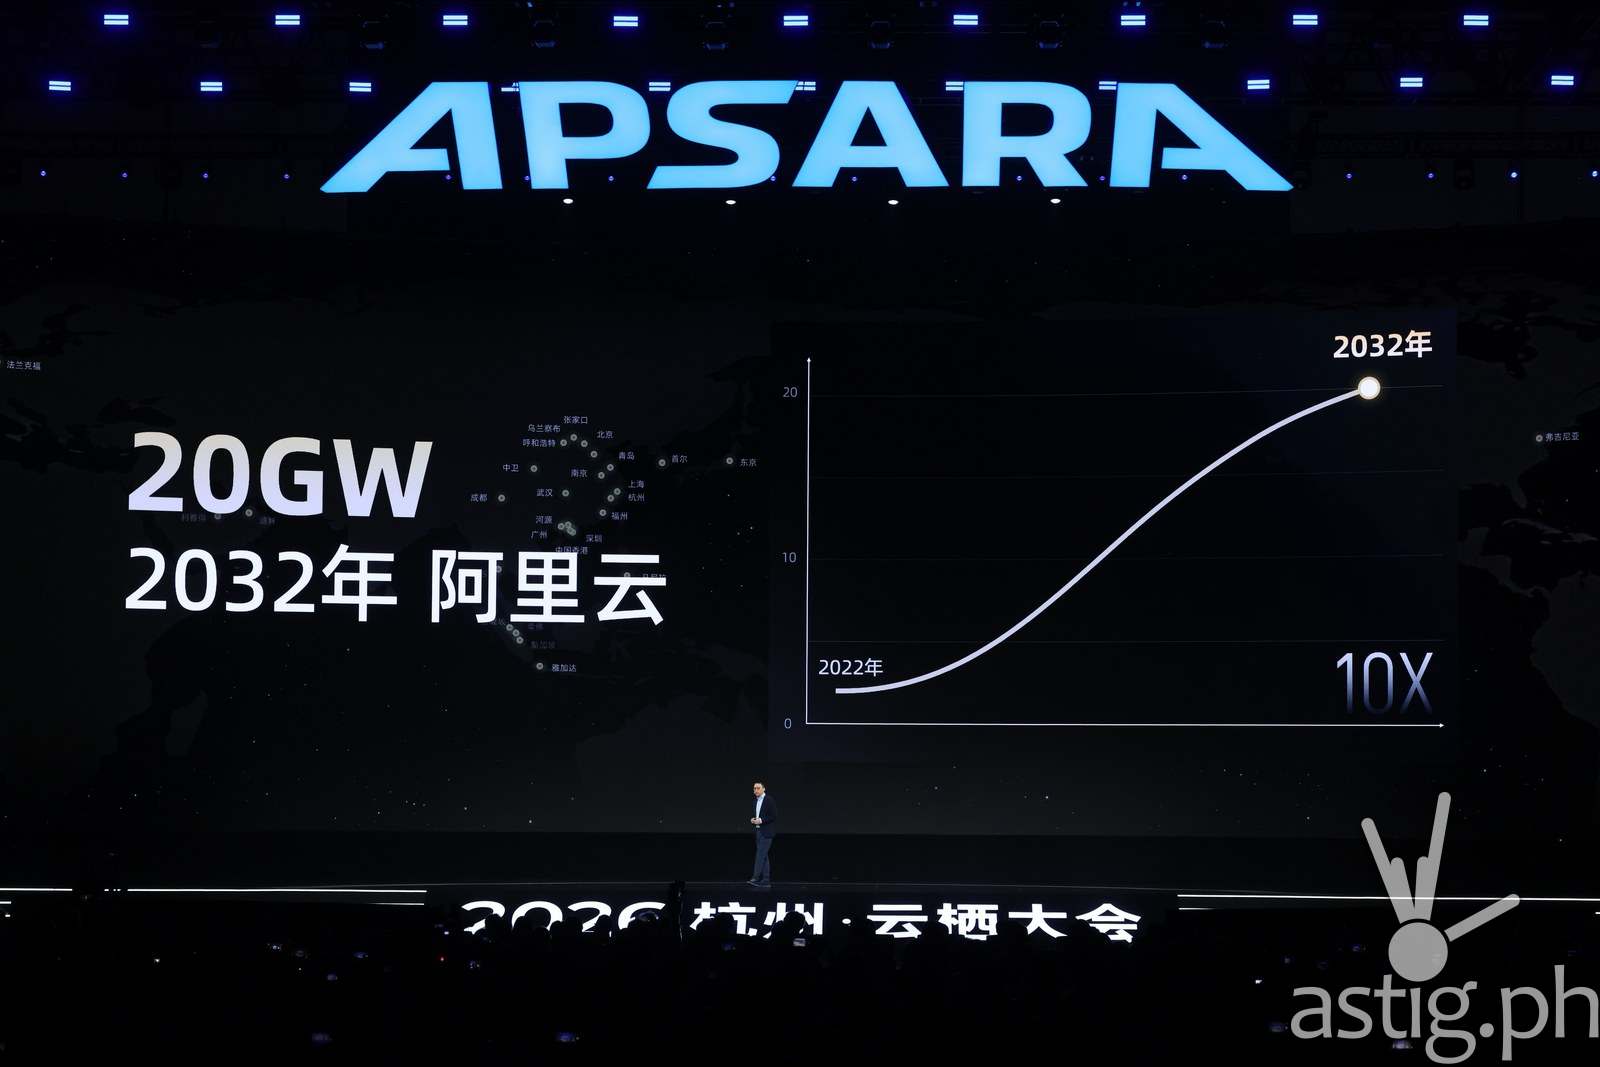
Alibaba at Apsara 2026: Qwen 4 in Training, 10T Models Next
At its annual Apsara Conference in Hangzhou on September 22, 2026, Alibaba laid out the next stage of its model roadmap: Qwen 4 is now in training, and the Qwen 4.5 and Qwen 5 series that follow are projected to reach 5 to 10 trillion parameters. In the same keynote, Alibaba Group CEO Eddie Wu […]
-
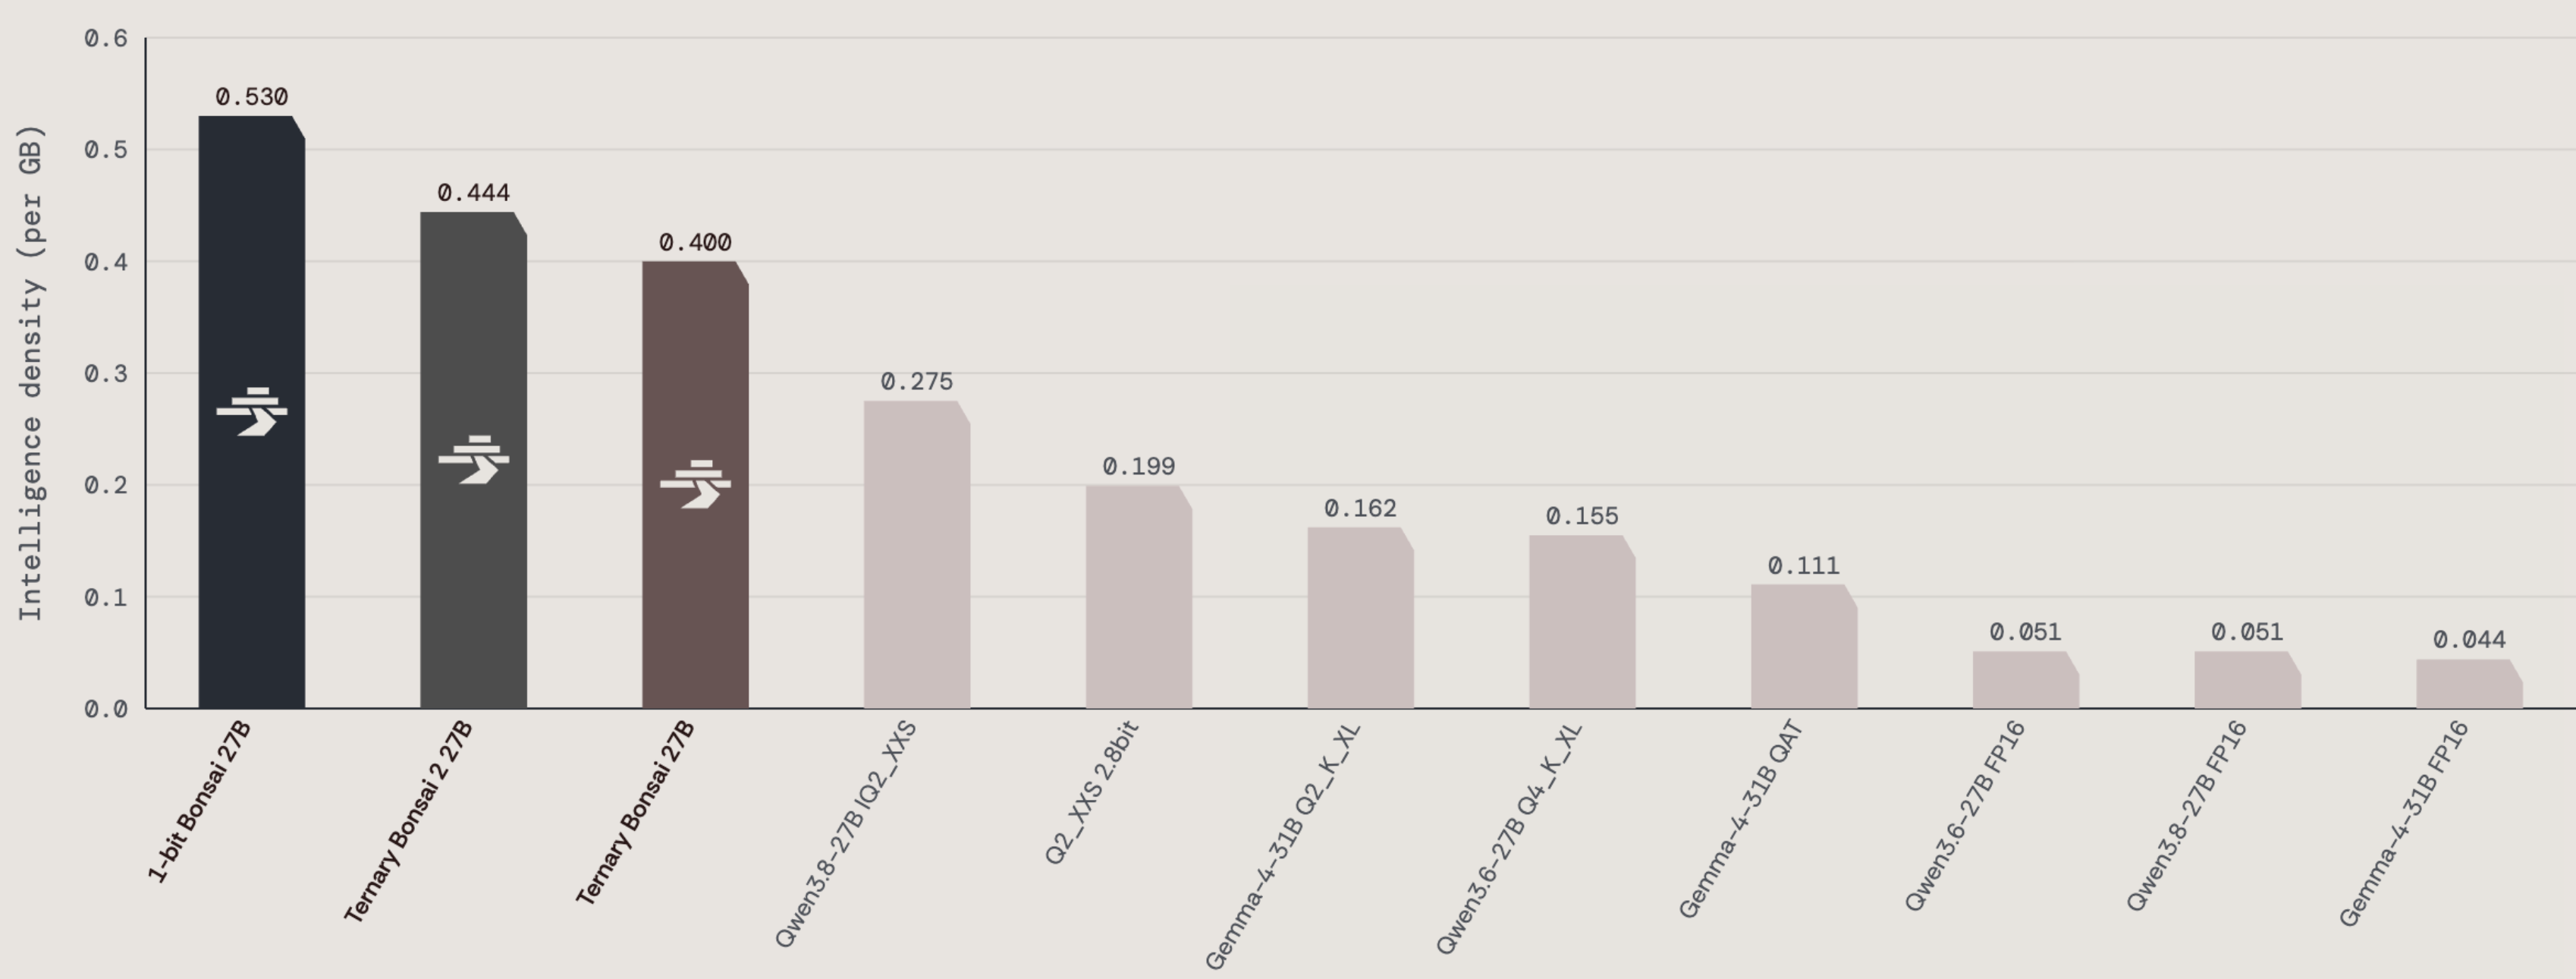
Bonsai 2 27B: Qwen3.8 in 5.9 GB at 98% of Full Precision
On September 17, 2026, PrismML released Ternary Bonsai 2 27B — a 1.76-bit-per-weight build of Alibaba’s Qwen3.8-27B that fits in 5.93 GB and, on the company’s 20-benchmark suite, keeps 98.2% of the full-precision model’s score. July’s Ternary Bonsai 27B, built on the older Qwen3.6 base, retained about 95%. The new build ships under Apache 2.0 […]
-
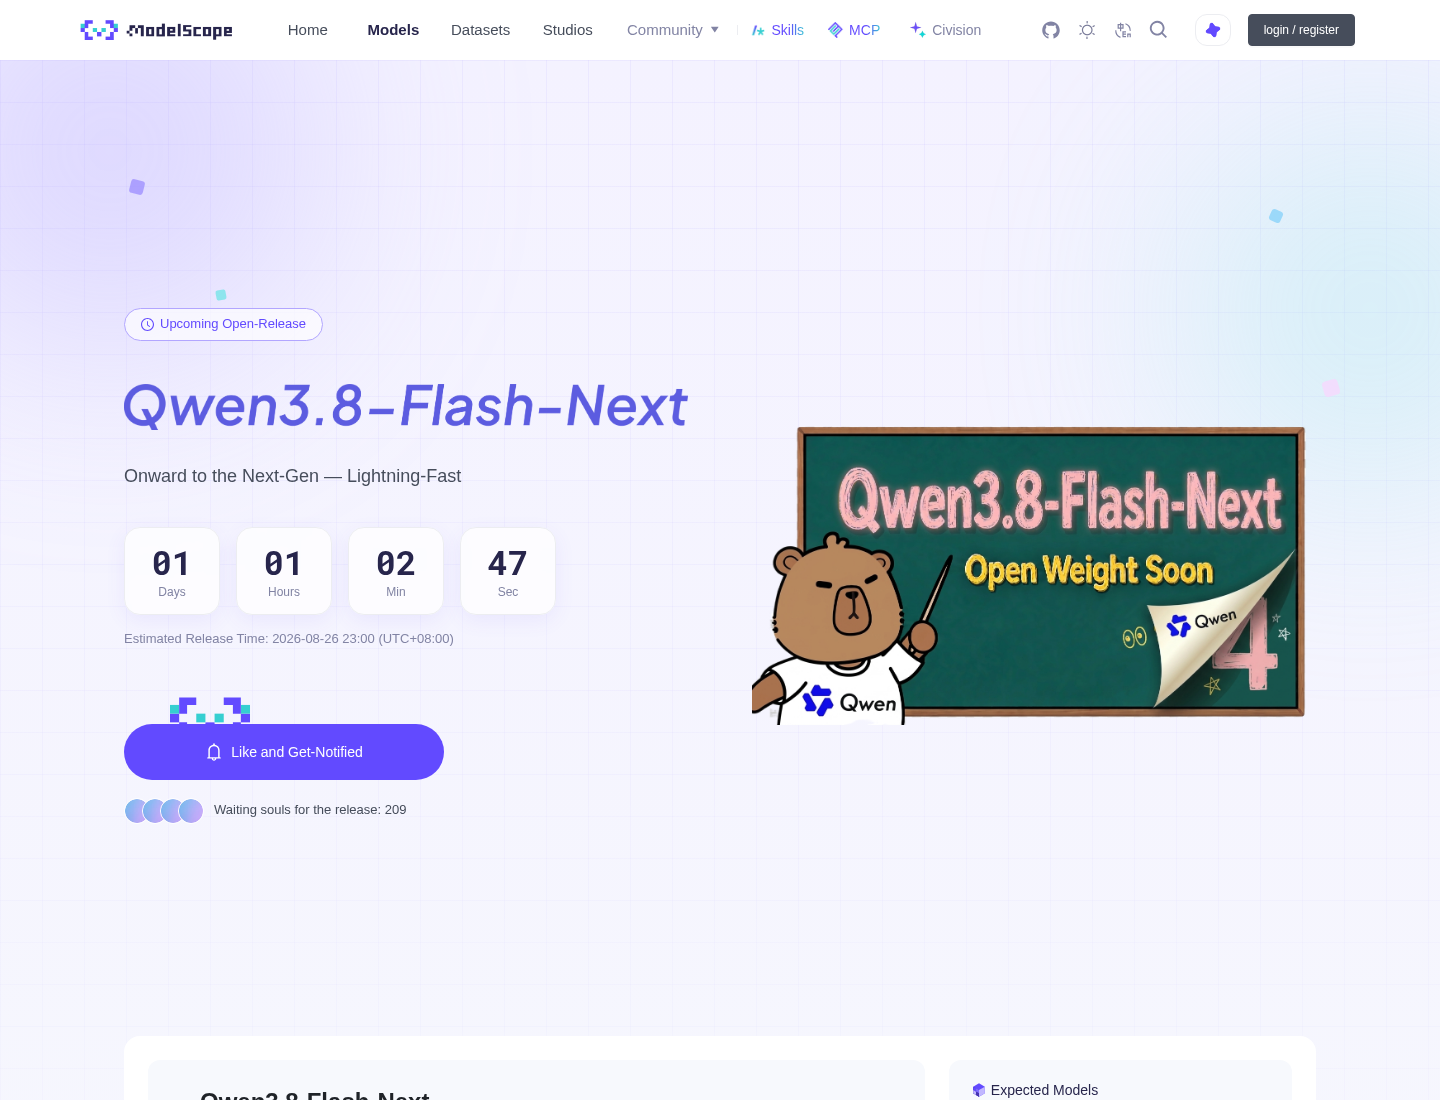
Qwen3.8-Flash-Next: Alibaba Previews the Qwen4 Architecture
Alibaba’s Qwen team has scheduled an open-weight release of Qwen3.8-Flash-Next for 23:00 on August 26, 2026 (UTC+08:00), describing it on ModelScope as “a multimodal MoE model built on the next-generation Qwen4 architecture.” The weights were not yet public at the time of writing. What has circulated instead is a specification block that appeared briefly on […]
-
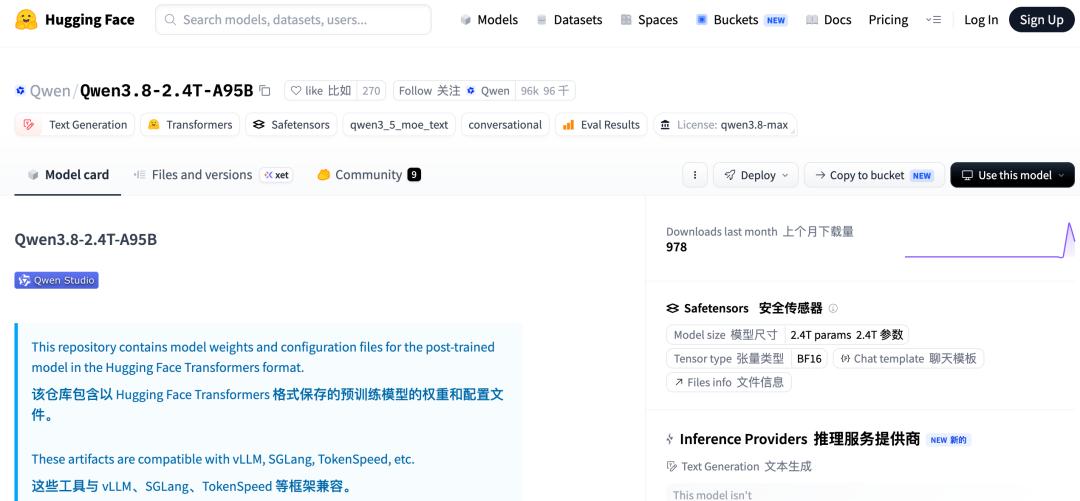
Qwen3.8-2.4T-A95B: Alibaba Open-Weights Its Max-Tier Flagship
Alibaba published the weights for Qwen3.8-2.4T-A95B on August 13, 2026 — the open-weight release of Qwen3.8-Max, the 2.4-trillion-parameter Mixture-of-Experts model it launched as an API product ten days earlier. It is the first time Alibaba has released a Max-tier model’s weights, and at 2.4T total parameters it is the largest open-weight language model published to […]
-
Meta Releases Muse Glimmer, a 30B Agent Model for a Single GPU
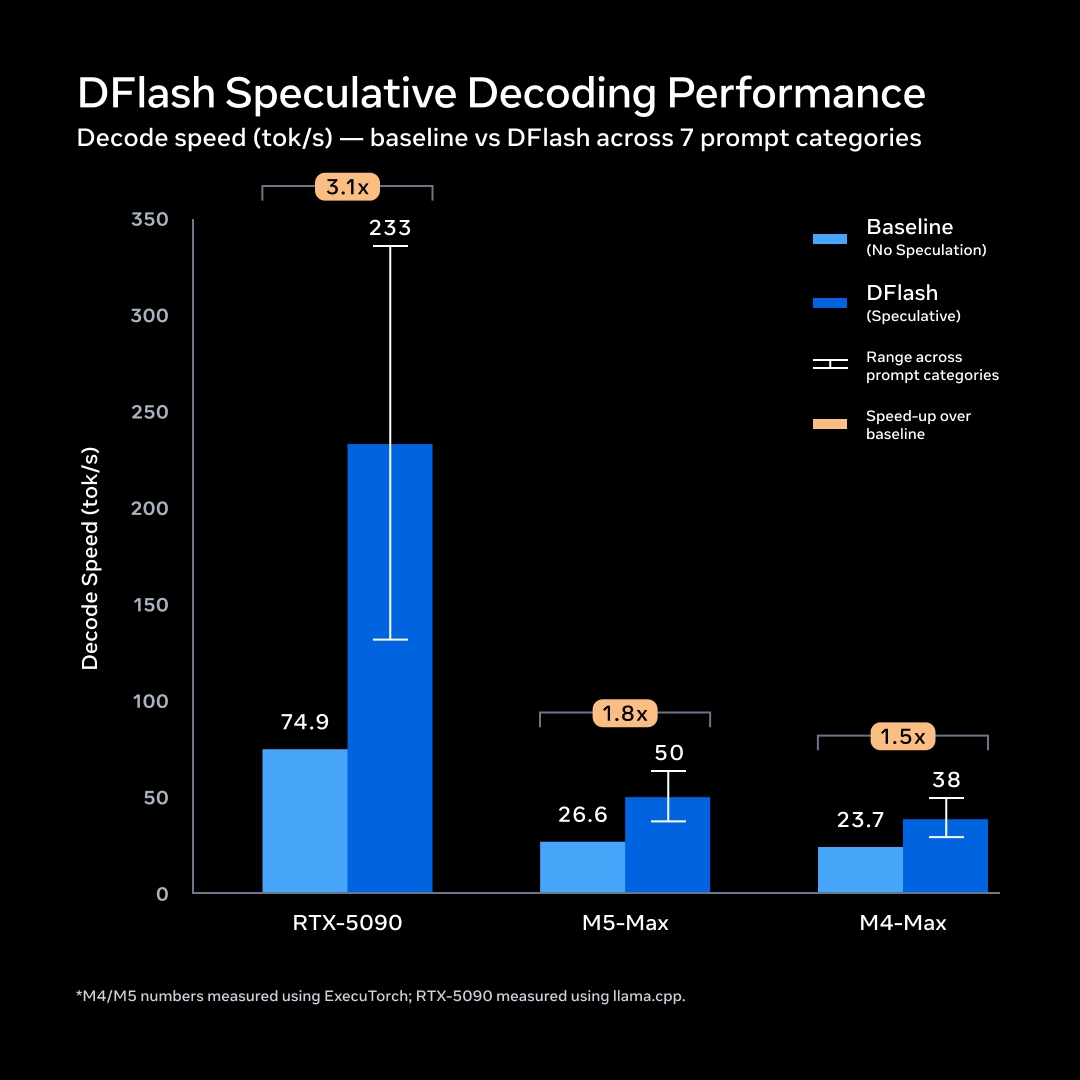
On August 10, 2026, Meta released Muse Glimmer — a 30-billion-parameter open-weight model, licensed Apache 2.0, built specifically to run agent workflows locally on a single consumer GPU. It is distilled from Muse Spark, the closed frontier model Meta Superintelligence Labs launched in April, and it is the clearest statement yet of where Meta draws […]
-
Language Model Builder: Train a Small LLM From Scratch on Your Mac
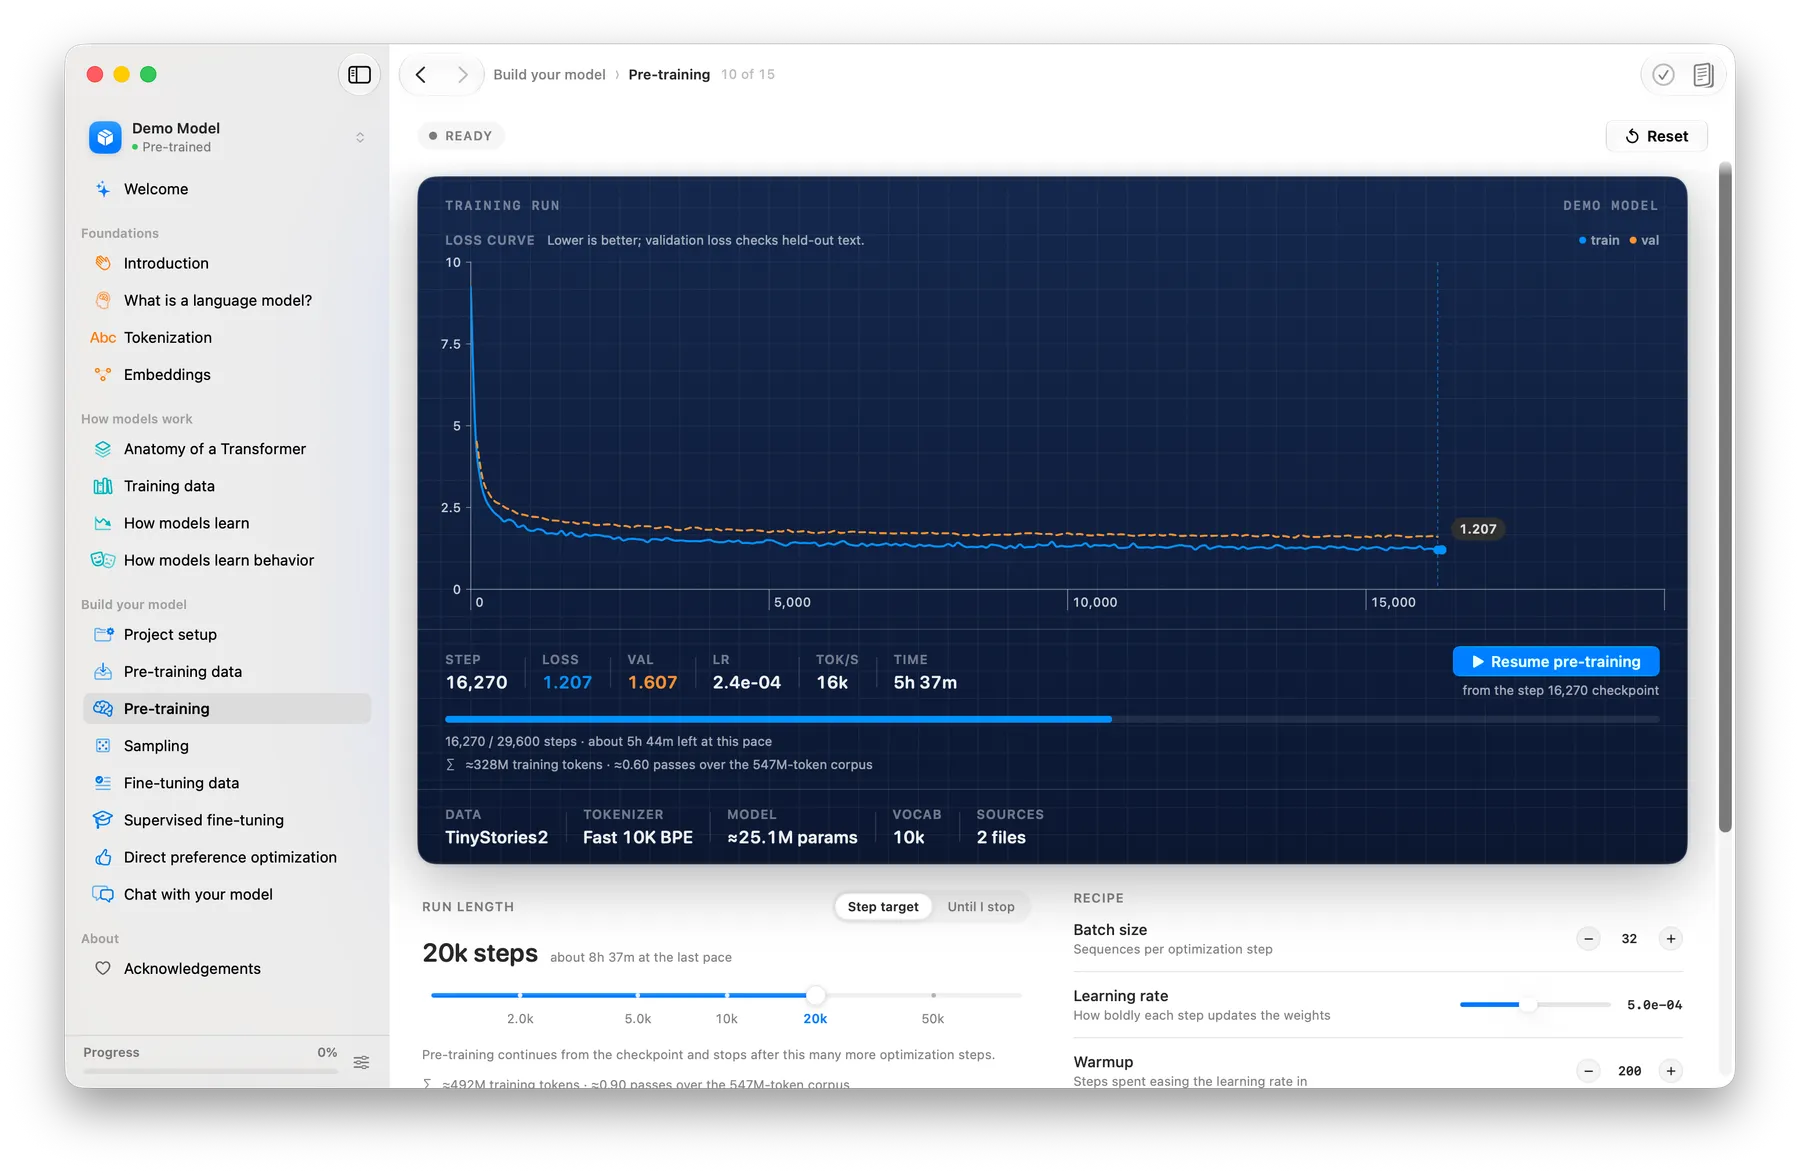
On July 21, 2026, developer Felix Rieseberg released Language Model Builder — a free native macOS app that walks you through building a small language model from scratch on your own hardware. It pairs an interactive textbook on tokenization, embeddings, attention, and transformers with a real training pipeline: pre-training, supervised fine-tuning, and direct preference optimization, […]