Tag: llm
-
Poolside Releases Laguna S 2.1, a 118B Open-Weight Coding Model
On July 21, 2026, San Francisco-based Poolside released Laguna S 2.1 — a 118-billion-parameter Mixture-of-Experts model built for agentic coding that activates only 8 billion parameters per token. It tops the SWE-Bench Multilingual table at 78.5%, holds its own against models ten to twenty times its size on long-horizon coding benchmarks, and fits on a […]
-
Qwen3.8-Max Preview: Alibaba’s 2.4T-Parameter Bid for the Frontier
Alibaba’s Qwen team announced Qwen3.8-Max-Preview on July 19, 2026 — a 2.4 trillion-parameter multimodal model the team calls its most capable system yet, claiming performance “second only to Fable 5” among the models it evaluated. The preview landed just two days after Moonshot AI’s 2.8 trillion-parameter Kimi K3 open-weight release, underscoring how quickly China’s frontier […]
-
Thinking Machines Releases Inkling, Its First Open-Weight Model
On July 15, 2026, Thinking Machines Lab released Inkling — its first model trained from scratch and, notably, its first open-weight release. Founded in February 2025 by former OpenAI CTO Mira Murati, the lab is best known for the Tinker fine-tuning platform; Inkling is a 975-billion-parameter Mixture-of-Experts model (41B active) published under the permissive Apache […]
-
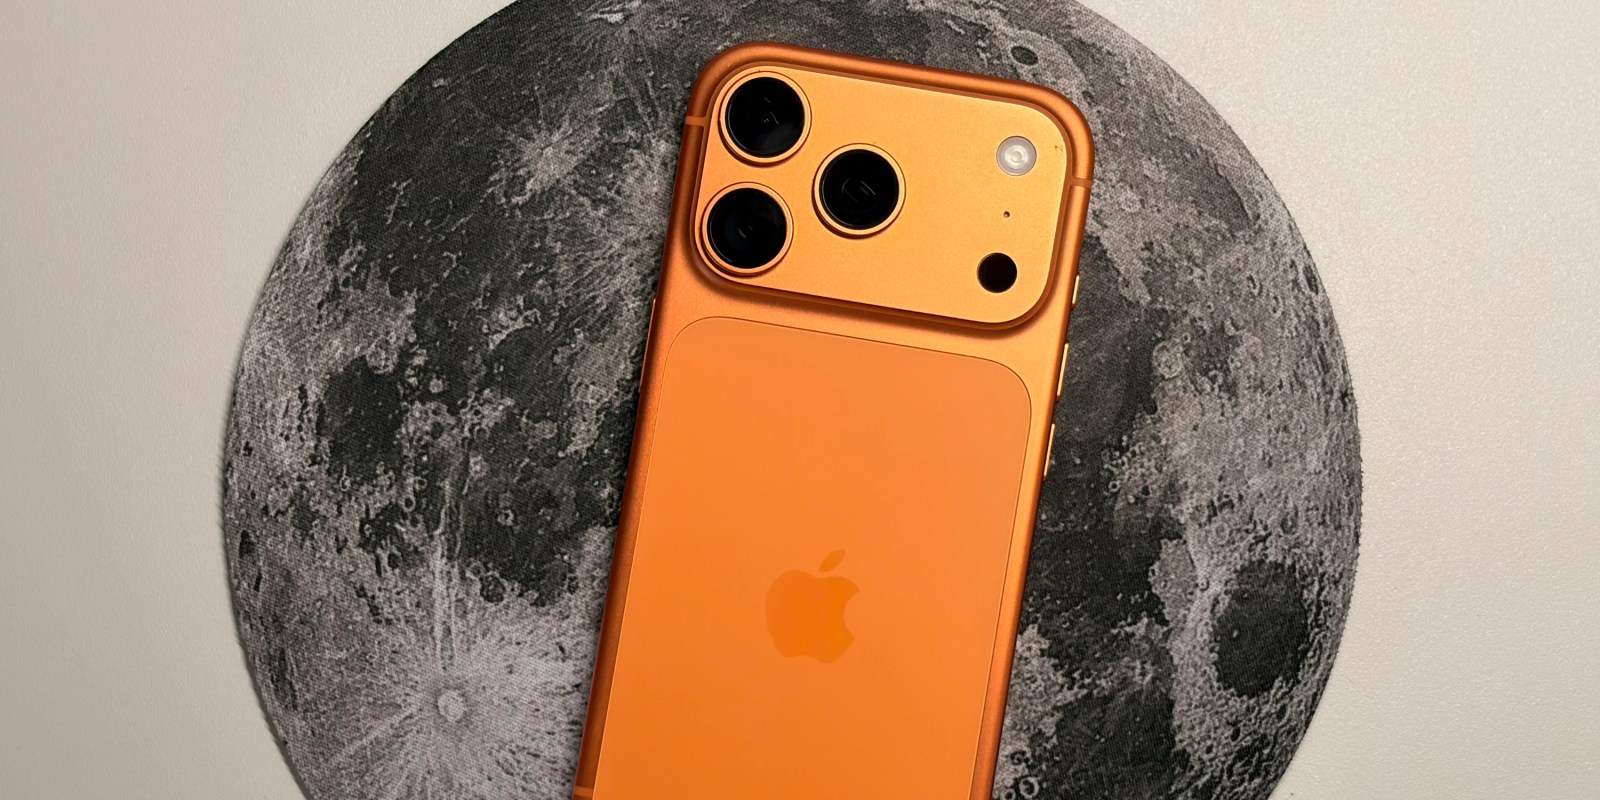
Bonsai 27B: A 27B-Class AI Model That Runs on a Phone
On July 14, 2026, PrismML released Bonsai 27B — a pair of extreme-quantization builds of Alibaba’s Qwen3.6-27B that the company calls the first 27B-class model capable of running on a phone. The 1-bit variant fits in 3.9 GB and runs on an iPhone 17 Pro, while a higher-quality ternary variant fits in 5.9 GB for […]
-
Tencent Releases Hy3: 295B Open MoE Model Under Apache 2.0
Tencent has released Hy3, the full production version of its Hunyuan reasoning-and-agent model, following up on the Hy3 Preview that launched in late April 2026. Hy3 is a 295-billion-parameter Mixture-of-Experts (MoE) model with 21 billion active parameters, and it ships fully open-source under the Apache 2.0 license — weights, quantized variants, and inference recipes included. […]
-
Anthropic Launches Claude Sonnet 5, Closing the Gap With Opus
Anthropic released Claude Sonnet 5 on June 30, 2026 — its “most agentic Sonnet model yet,” bringing performance close to the flagship Opus 4.8 while running at a fraction of the cost. The mid-tier model posts large gains over Sonnet 4.6 in coding, reasoning, tool use, and knowledge work, and ships with introductory pricing of […]
-
JetSpec: Causal Parallel Tree Drafting Hits 9.64x Faster LLM Inference
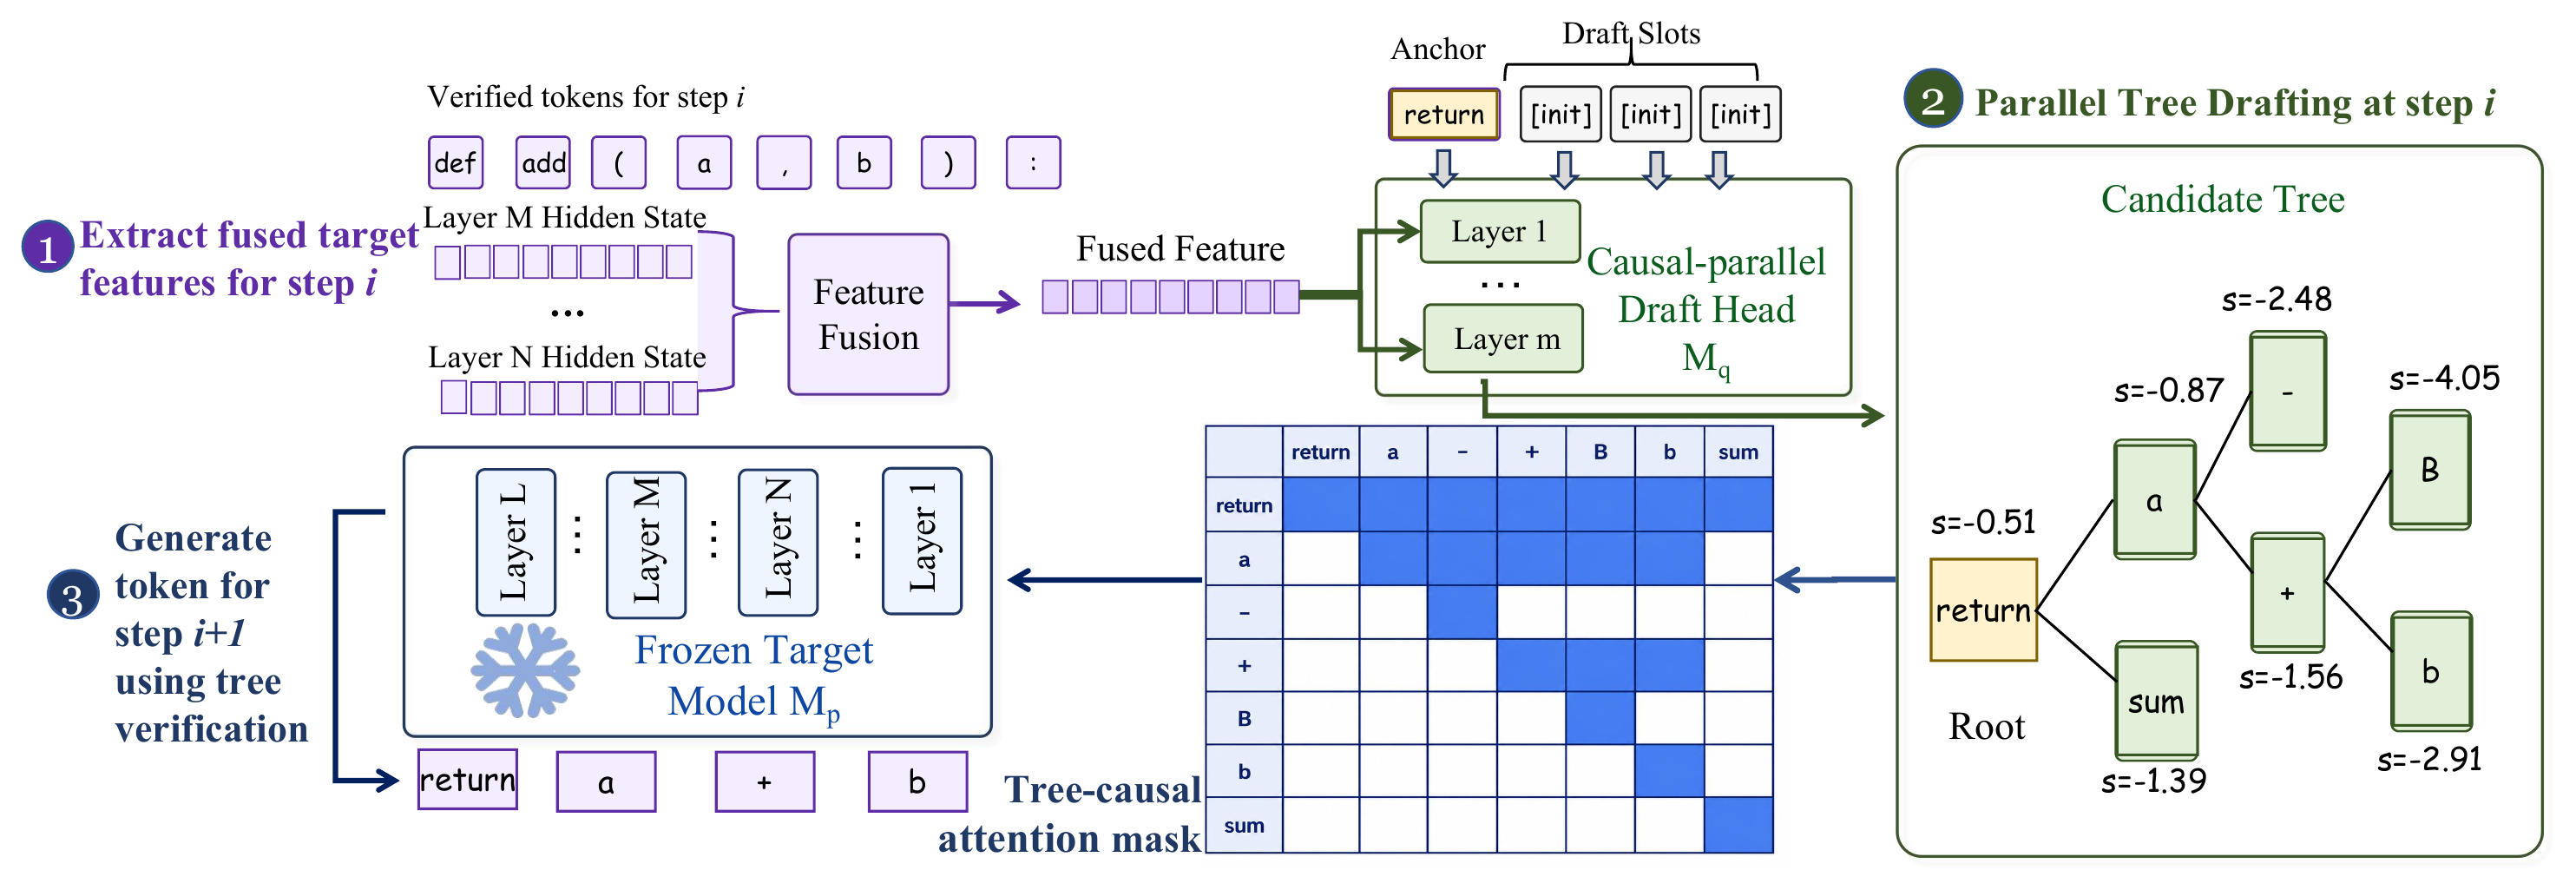
On June 26, 2026, researchers at UC San Diego’s Hao AI Lab released JetSpec — a speculative decoding method that accelerates large language model inference by up to 9.64× while leaving the model’s outputs unchanged. JetSpec trains a small “causal parallel draft head” on top of a frozen target model, generating a scored tree of […]
-
GLM-5.2: Z.ai’s Open-Weights Coder Beats GPT-5.5 at 1/6 the Cost
On June 13, 2026, Z.ai (formerly Zhipu AI) released GLM-5.2 — a 753-billion-parameter open-weights Mixture-of-Experts model built for long-horizon, autonomous coding. The headline claim is striking: GLM-5.2 edges past OpenAI’s GPT-5.5 on several multi-step engineering benchmarks while costing roughly one-sixth as much to run. The full weights ship under an unrestricted MIT license on Hugging […]
-
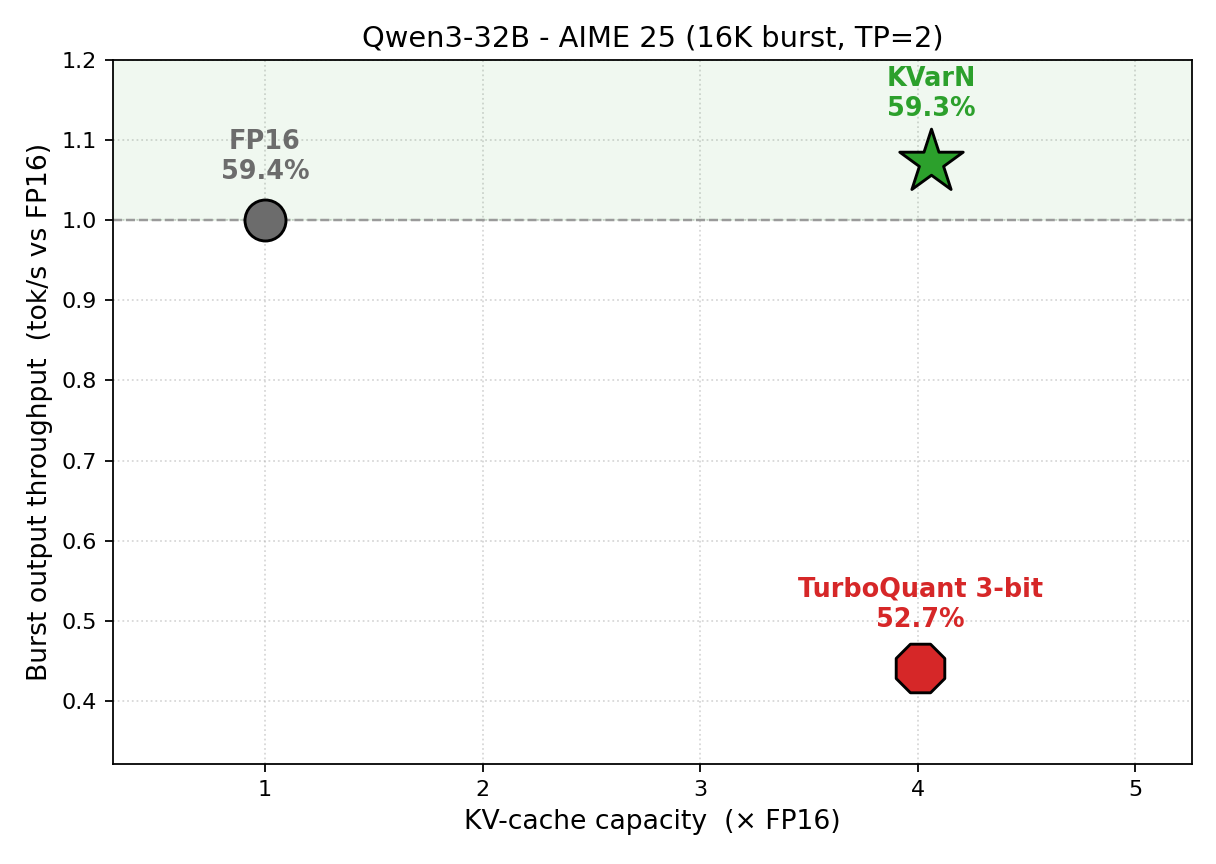
Huawei’s KVarN Hits 5x KV-Cache Capacity at FP16 Accuracy and Throughput
On June 2, 2026, Huawei researchers released KVarN — a variance-normalized KV-cache quantization backend for vLLM that breaks the long-standing tradeoff between cache compression and inference speed. KVarN delivers 3–5× more context capacity at 2-bit precision while keeping FP16-level accuracy and beating FP16 throughput, all behind a single vLLM flag with no calibration. It ships […]
-
Google Releases Gemma 4 12B: Frontier Multimodal AI on a Laptop
Lead — On June 3, 2026, Google DeepMind released Gemma 4 12B, a unified, encoder-free multimodal model that brings frontier-class intelligence to a single 16 GB laptop. The 11.95-billion-parameter model handles text, images, and audio in one decoder-only transformer, supports a 256K-token context across 140+ languages, and ships under a fully permissive Apache 2.0 license. Google […]