Tag: mixture of experts
-
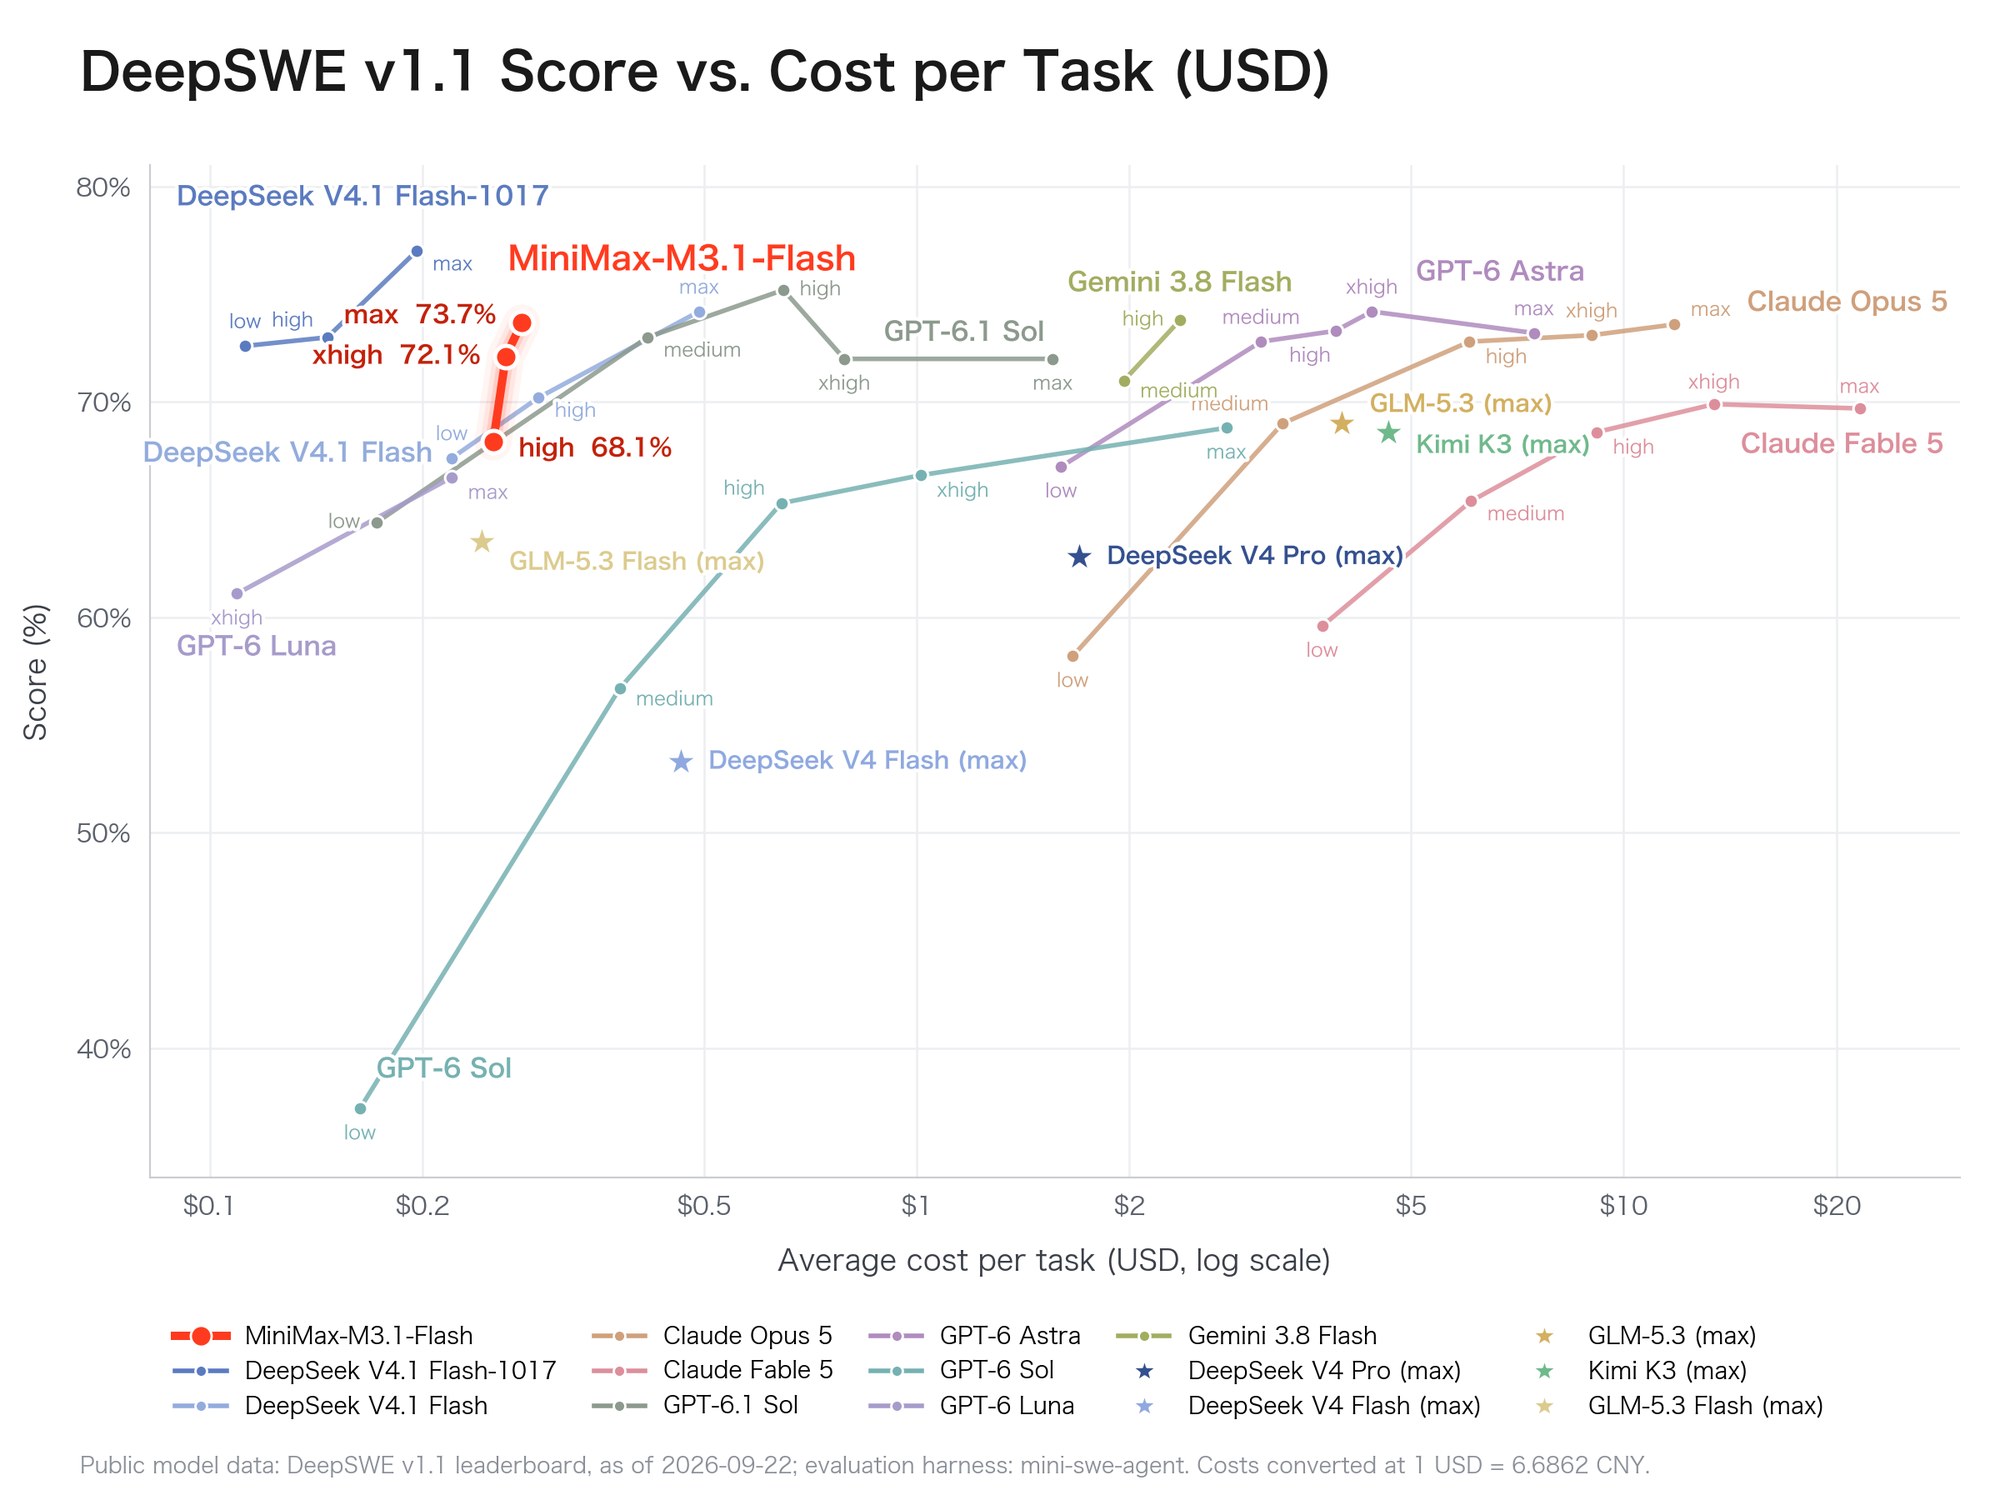
MiniMax Ships M3.1 Flash: API Now, Weights Due October 23
On October 19, 2026, MiniMax released M3.1 Flash, a faster and cheaper successor to June’s M3, and put it on its API the same day — but the weights are not out yet. MiniMax’s launch post says only that the weights “will be released later”. The Decoder and SiliconANGLE both report October 23. Until a […]
-
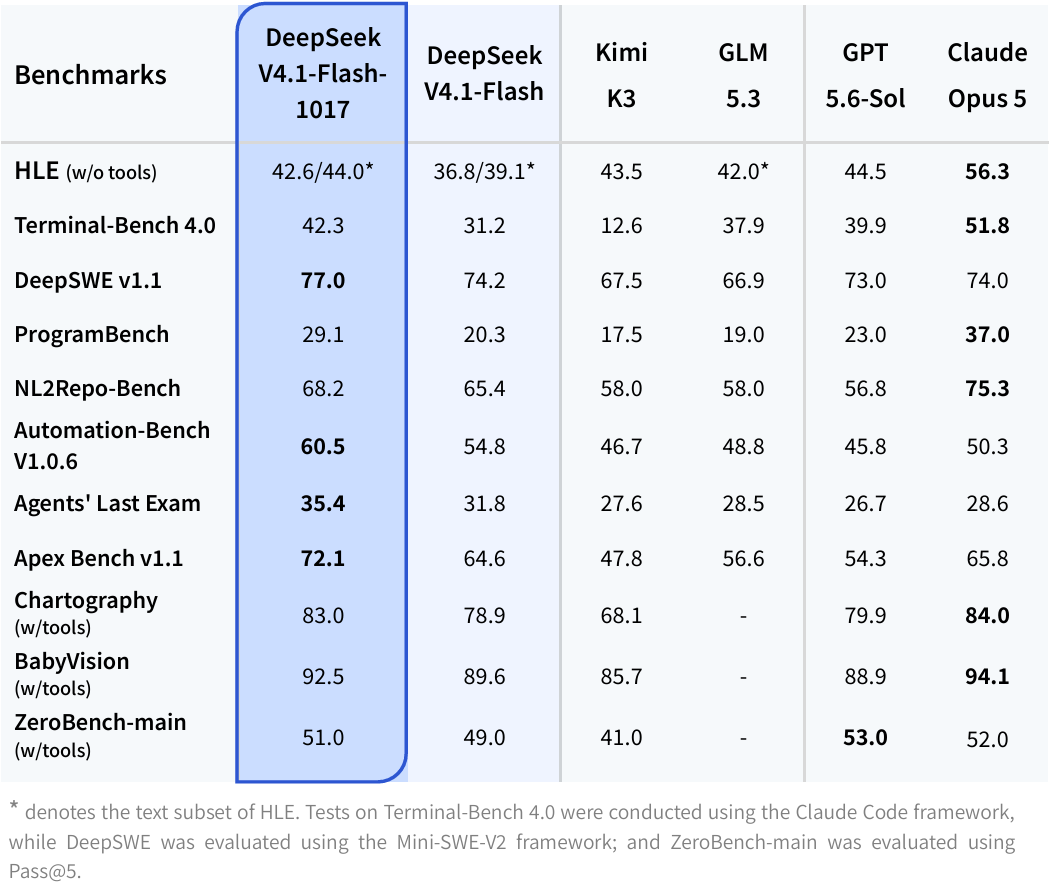
DeepSeek Ships V4.1-Flash-1017: Faster Agents, Same Price
DeepSeek replaced V4.1-Flash with DeepSeek-V4.1-Flash-1017 on October 17, 2026, shipping the new checkpoint to its website, mobile app and API the same day and publishing MIT-licensed weights on Hugging Face and ModelScope. DeepSeek calls it a minor update; it improves all eleven benchmarks in the company’s comparison table, shortens outputs, and leaves API pricing unchanged. […]
-
Meta Opens Muse Spark Weights: 816B MoE, 1M Context
On October 15, 2026, Meta Superintelligence Labs released the weights for Muse Spark Open — an 816-billion-parameter sparse mixture-of-experts model that activates 42 billion parameters per token, with a 1,048,576-token context window. Meta calls it “the most capable US open-weight model to date,” and the release is as much a hardware story as a benchmark […]
-
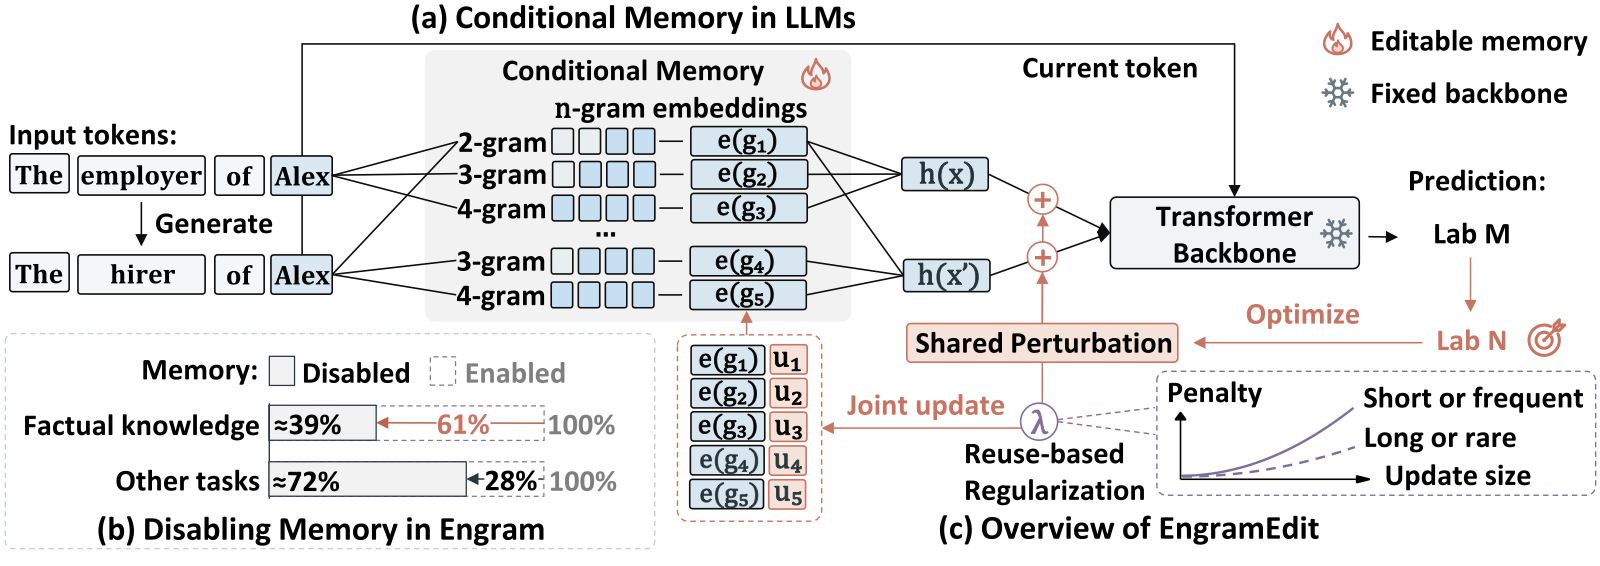
EngramEdit Rewrites LLM Facts by Editing Conditional Memory
On October 7, 2026, researchers from The Hong Kong Polytechnic University, Hangzhou Diagens Biotechnology, and the University of Science and Technology of China posted EngramEdit (arXiv:2610.10533), a method that revises facts inside a large language model by editing only its conditional memory — the n-gram lookup tables of an Engram-style architecture — while leaving the […]
-
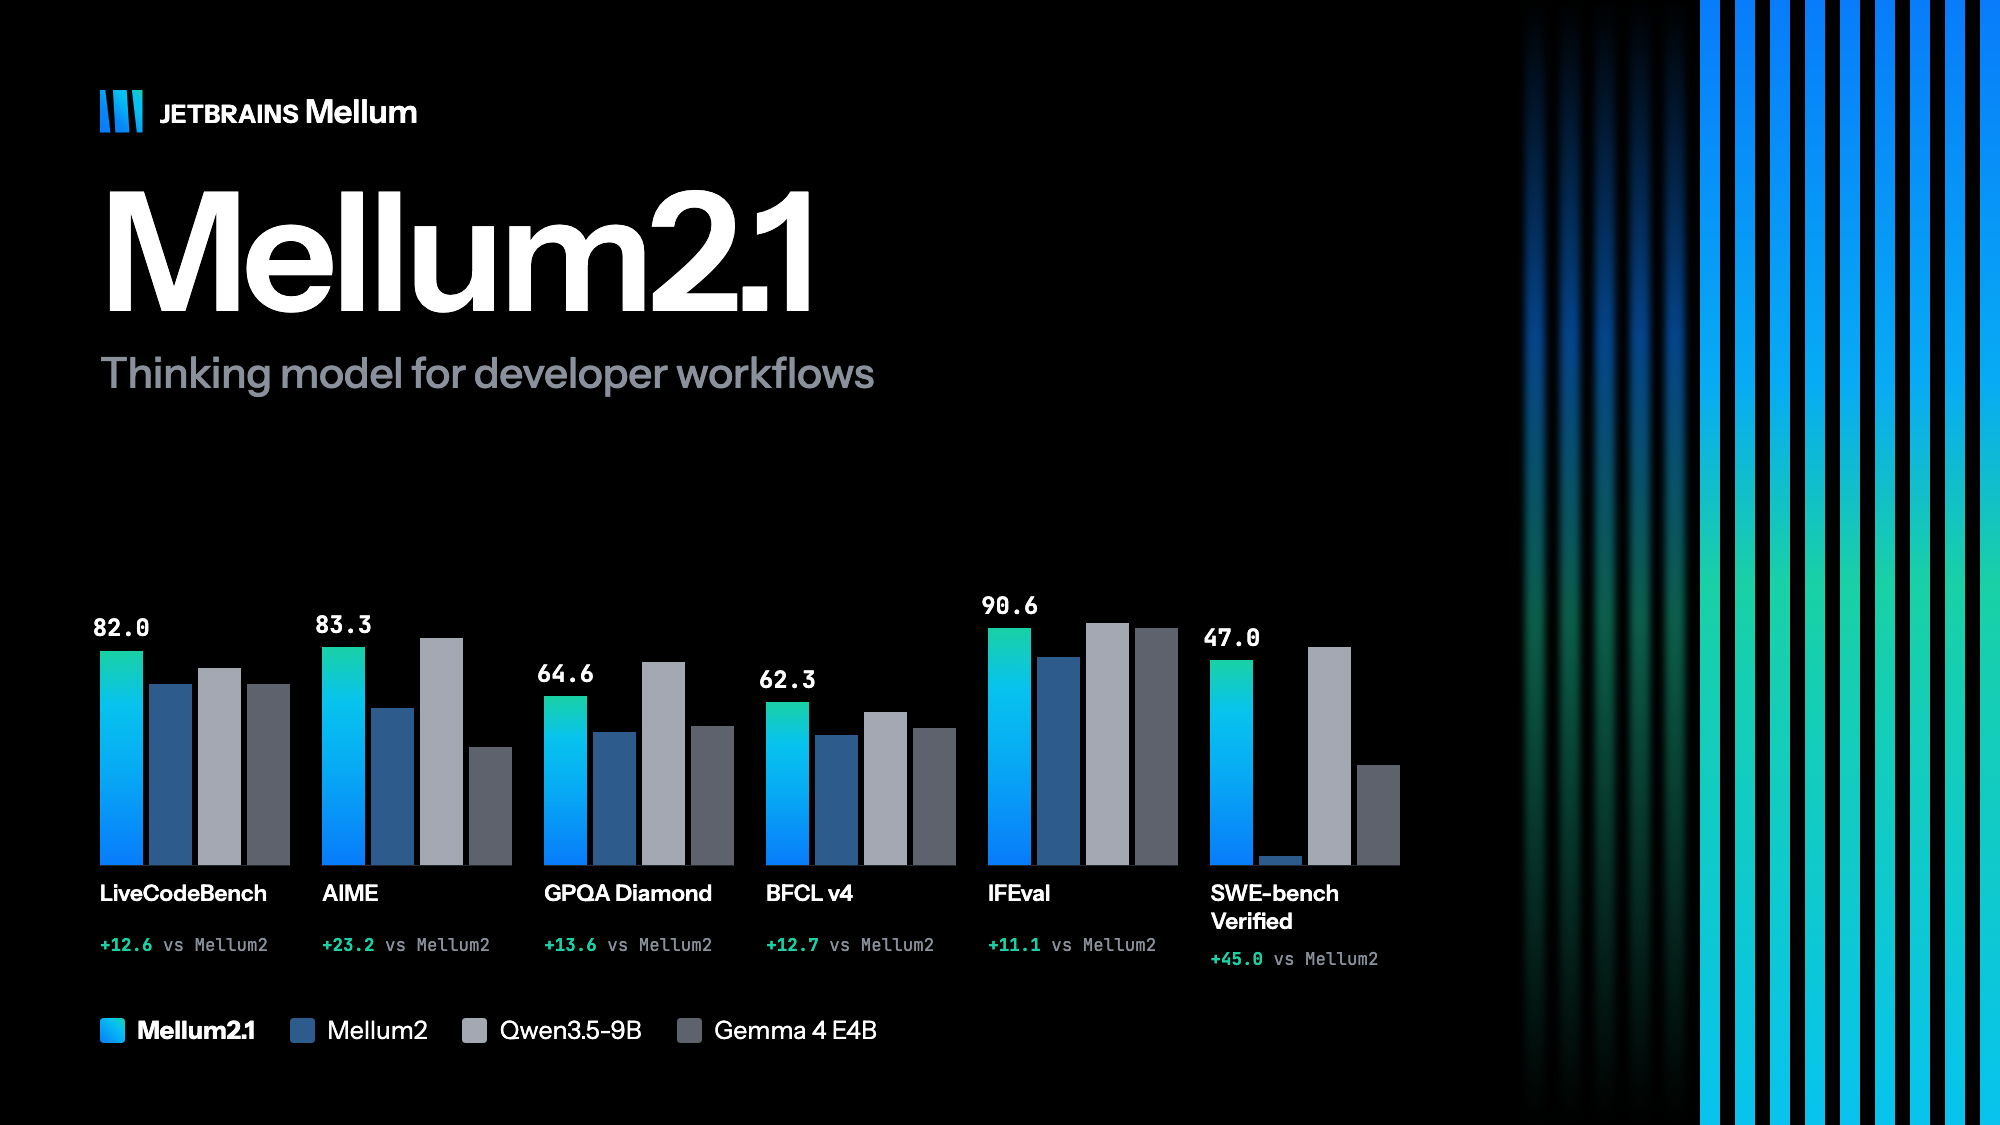
JetBrains Ships Mellum2.1, a 12B Open Model for Coding Agents
JetBrains released Mellum2.1 on October 8, 2026 — the next version of the 12-billion-parameter mixture-of-experts model it open-sourced in June. The architecture is unchanged, the license is still Apache 2.0, and the weights are on Hugging Face. What changed is everything after pre-training: JetBrains says the update was driven by scaling up reinforcement learning in […]
-
Xiaomi Open-Sources MiMo-V2.6 Pro and Flash, Plus Its RL Stack
Xiaomi has released the weights of MiMo-V2.6-Pro and MiMo-V2.6-Flash under the MIT licence, one week after it began streaming their reinforcement learning (RL) runs on a public dashboard. The two checkpoints went up on Hugging Face on September 21, 2026 (UTC), and Xiaomi’s official announcement is dated September 22. Pro is a 1.02-trillion-parameter Mixture-of-Experts (MoE) […]
-
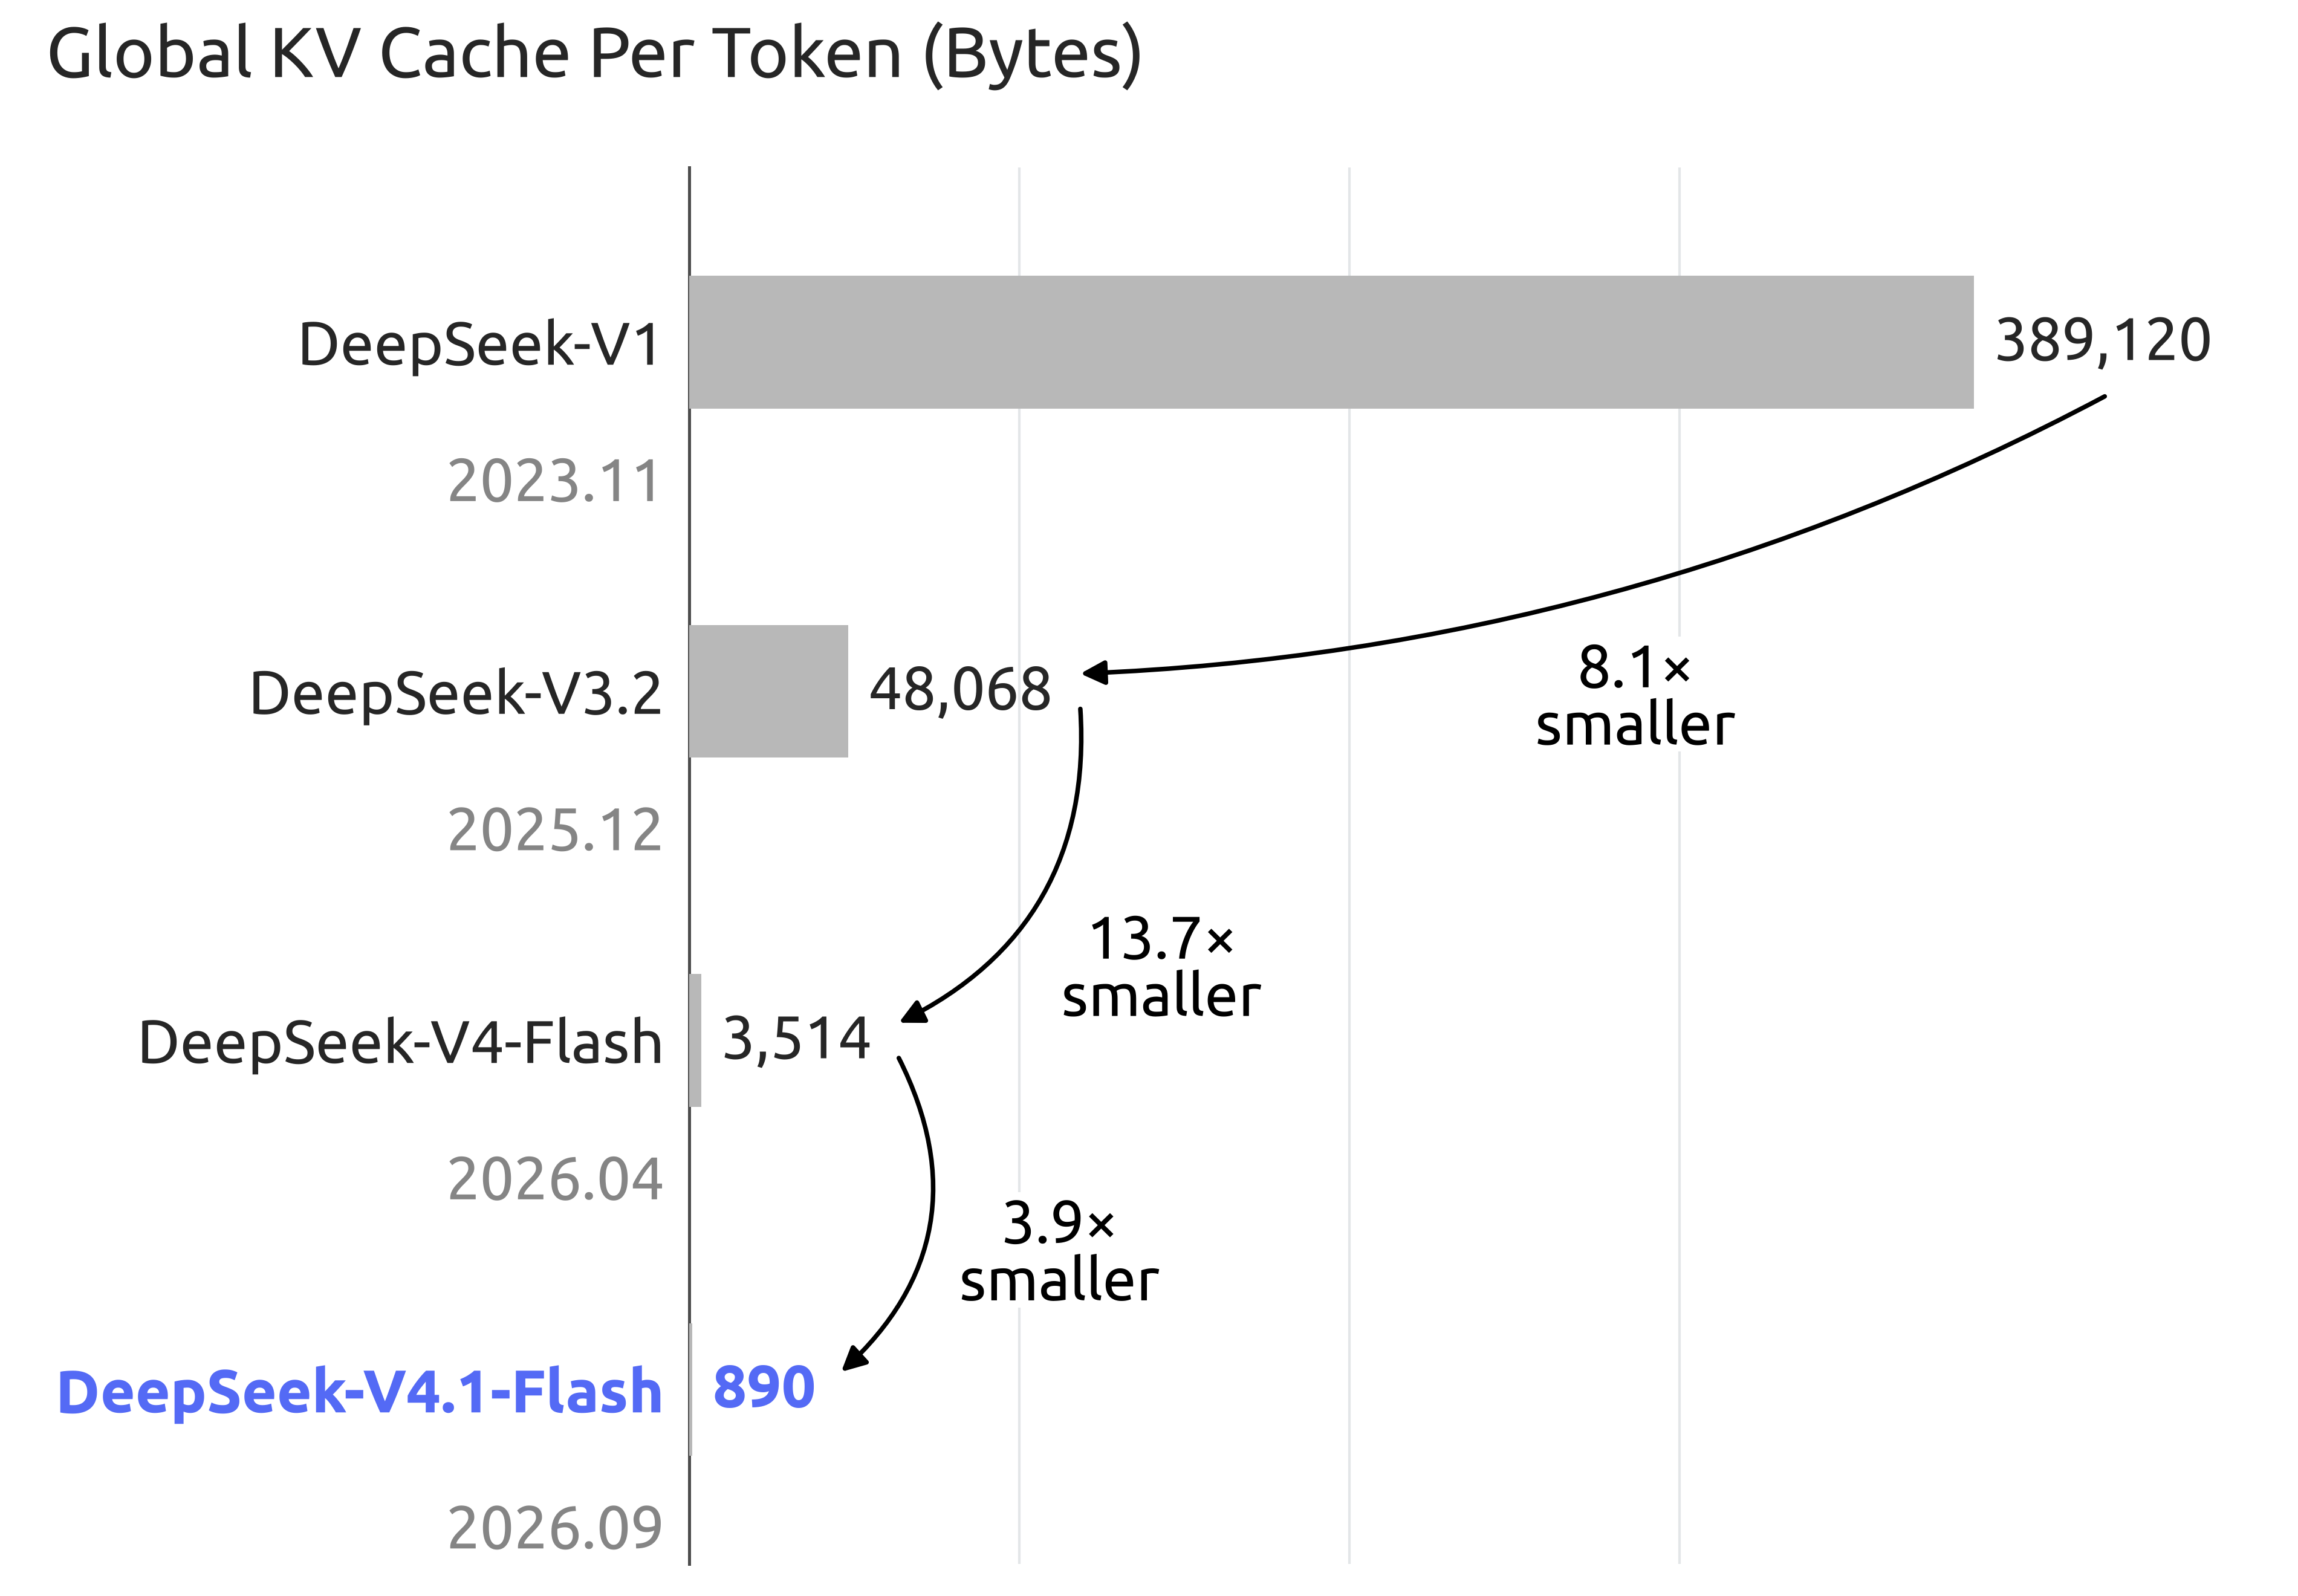
DeepSeek V4.1-Flash: 552B Params, 890 Bytes of KV Cache Per Token
DeepSeek released V4.1-Flash on September 10, 2026, publishing the weights on Hugging Face under an MIT licence the same day the model went live in its apps. The headline is not the parameter count but the memory footprint: a 552-billion-parameter Mixture-of-Experts backbone that holds a one-million-token context in 890 bytes of KV cache per token […]
-
IFM Releases K2 Horizon: Six Open Models With Data, Code, and Logs
The Institute of Foundation Models (IFM), launched by Mohamed bin Zayed University of Artificial Intelligence, released K2 Horizon on September 3, 2026 — six Apache 2.0 models spanning 0.9B to 375B parameters, published alongside the training data, code, configurations, intermediate checkpoints, and training logs that produced them. The flagship 375B-A23B scores 47 on the Artificial […]
-
DeepSeek V4-Pro Leaves Preview as API Prices Rise
DeepSeek has taken V4-Pro out of preview. The model card for DeepSeek-V4-Pro-0813 went up on Hugging Face on August 13, 2026, closing a preview period that ran since the V4 family launched in late April. The weights stay under an MIT licence, the architecture is unchanged from the preview, and the headline addition is a […]
-
SK Telecom Opens A.X K2: 688B Parameters and One Telling Benchmark
SK Telecom released A.X K2 on July 29, 2026 — a 688-billion-parameter Mixture-of-Experts model published on Hugging Face under Apache 2.0, and the largest model yet to come out of Korea’s government-backed sovereign AI program. The headline numbers are strong: 97.1 on AIME26, 80.5 on KMMLU-Pro, and a wall of perfect 100s on needle-in-a-haystack retrieval […]