Tag: mixture of experts
-
Kimi K3 Open Weights Ship: 2.8T Parameters, 1.4 TB to Run
Moonshot AI released the full Kimi K3 weights on July 27, 2026, hitting the date it promised when the model debuted eleven days earlier. K3 is a 2.8-trillion-parameter Mixture-of-Experts model with a 1-million-token context window and native vision — the first open 3T-class model ever published. The download is 1.56 TB across 118 files, and […]
-
Poolside Releases Laguna S 2.1, a 118B Open-Weight Coding Model
On July 21, 2026, San Francisco-based Poolside released Laguna S 2.1 — a 118-billion-parameter Mixture-of-Experts model built for agentic coding that activates only 8 billion parameters per token. It tops the SWE-Bench Multilingual table at 78.5%, holds its own against models ten to twenty times its size on long-horizon coding benchmarks, and fits on a […]
-
Kimi K3 Hits Third on Artificial Analysis; Open Weights Due July 27
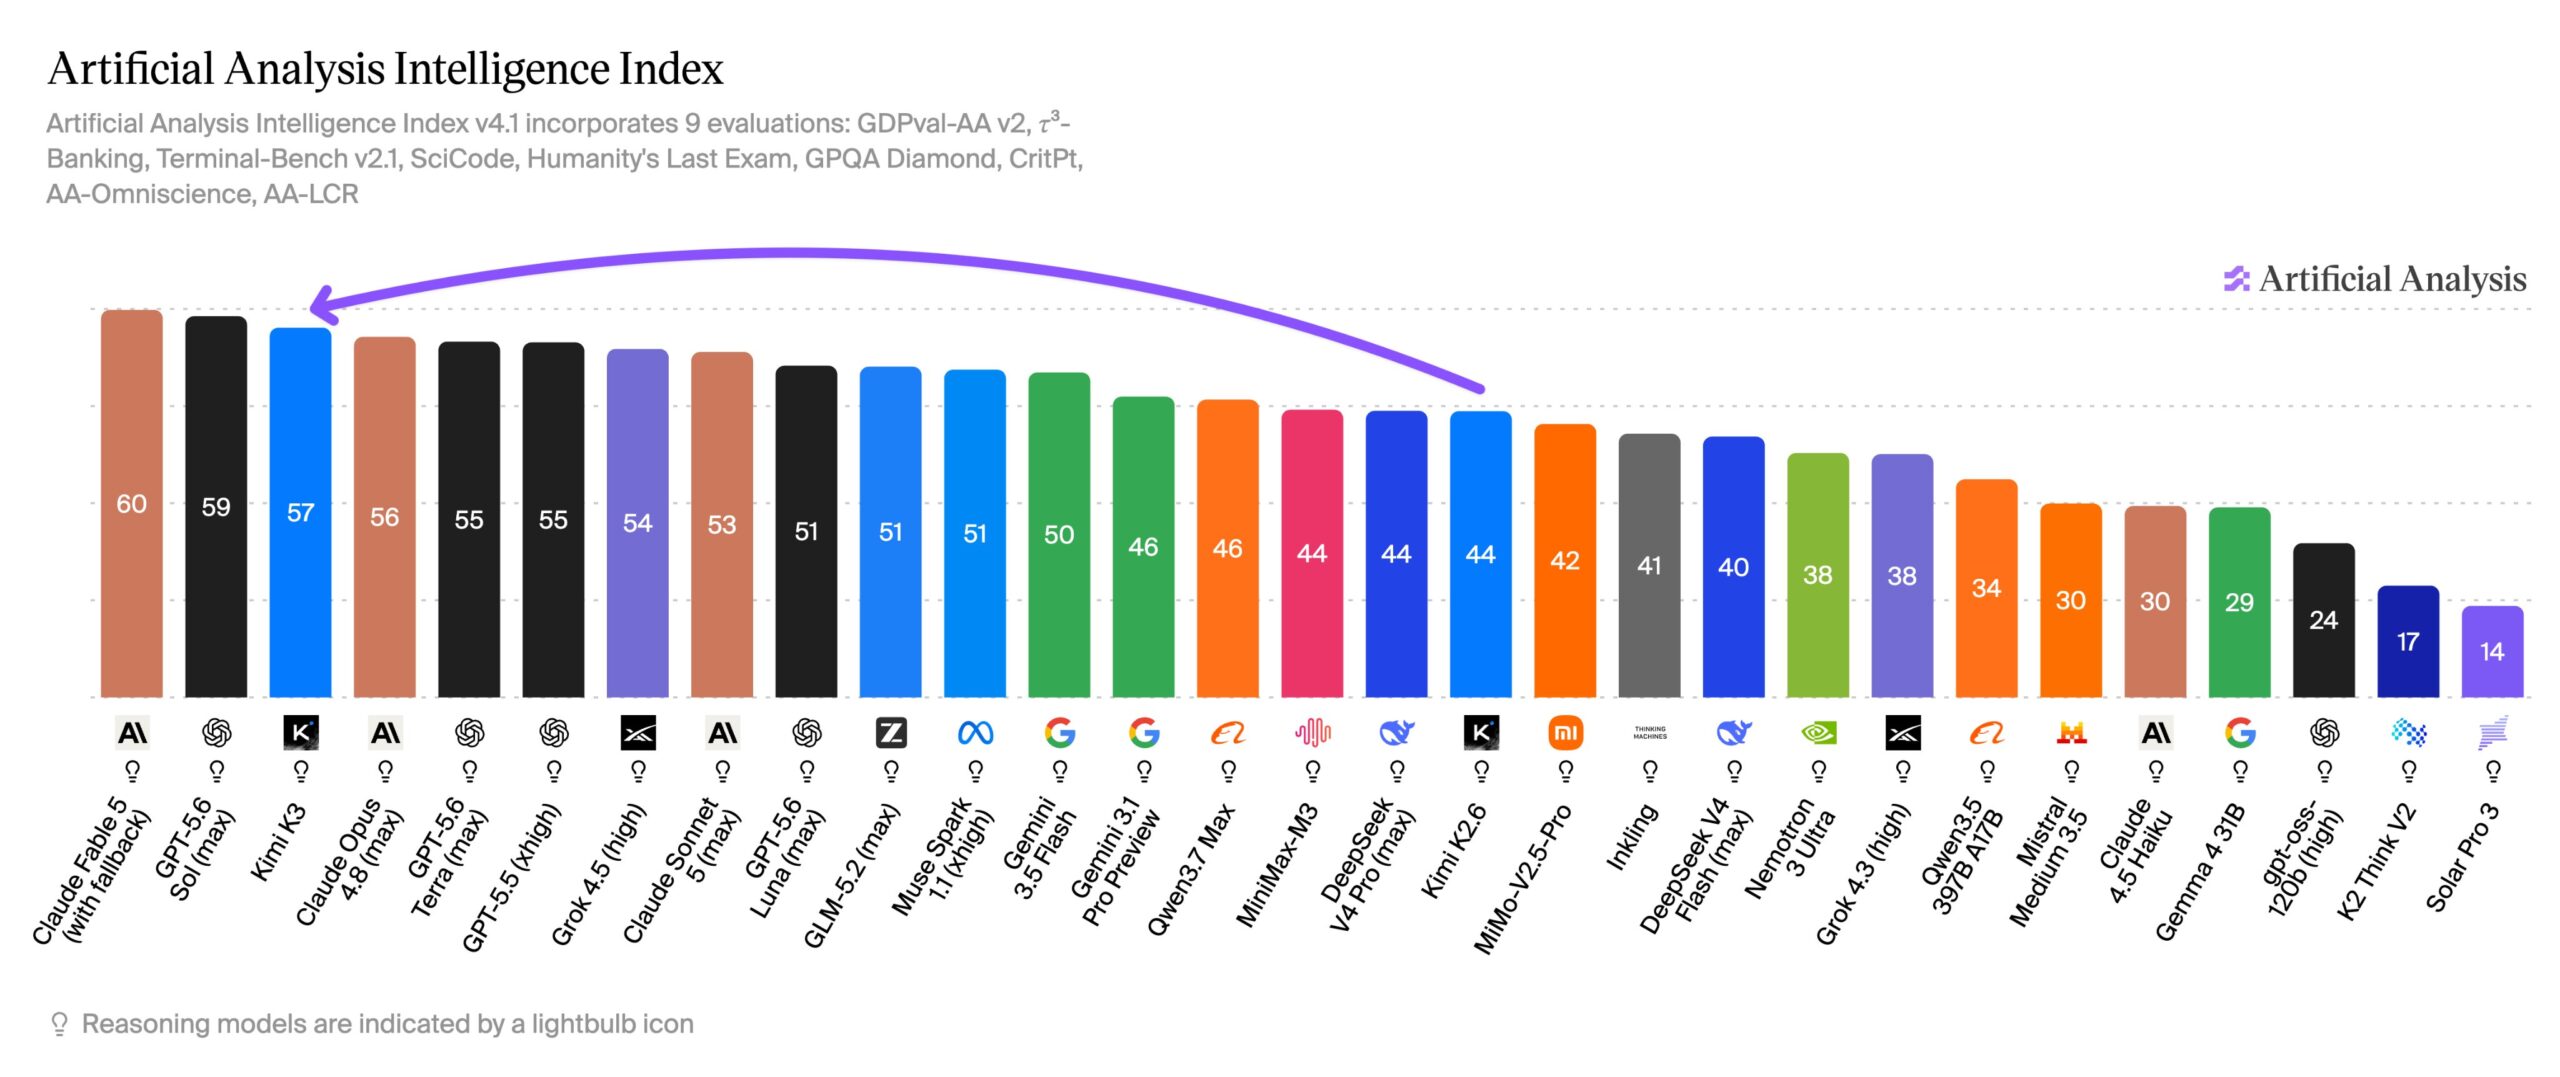
Moonshot AI launched Kimi K3 on July 16, 2026 — a 2.8-trillion-parameter Mixture-of-Experts model with a 1-million-token context window that now sits third on the Artificial Analysis Intelligence Index, ahead of Claude Opus 4.8 and behind only Claude Fable 5 and GPT-5.6 Sol. The full weights are promised by July 27, which would make K3 […]
-
Thinking Machines Releases Inkling, Its First Open-Weight Model
On July 15, 2026, Thinking Machines Lab released Inkling — its first model trained from scratch and, notably, its first open-weight release. Founded in February 2025 by former OpenAI CTO Mira Murati, the lab is best known for the Tinker fine-tuning platform; Inkling is a 975-billion-parameter Mixture-of-Experts model (41B active) published under the permissive Apache […]
-
Tencent Releases Hy3: 295B Open MoE Model Under Apache 2.0
Tencent has released Hy3, the full production version of its Hunyuan reasoning-and-agent model, following up on the Hy3 Preview that launched in late April 2026. Hy3 is a 295-billion-parameter Mixture-of-Experts (MoE) model with 21 billion active parameters, and it ships fully open-source under the Apache 2.0 license — weights, quantized variants, and inference recipes included. […]
-
Meituan Open-Sources LongCat-2.0, a 1.6T Model Trained on Chinese Chips
Meituan has open-sourced LongCat-2.0, a 1.6-trillion-parameter Mixture-of-Experts model that the Chinese food-delivery giant says is the first model of its scale to complete both pre-training and inference entirely on domestic AI chips. Released on June 30, 2026, LongCat-2.0 had already been quietly topping OpenRouter’s usage charts under the codename “Owl Alpha” before its identity was […]
-
MiniMax M3: Frontier Coding, 1M Context, and Sparse Attention
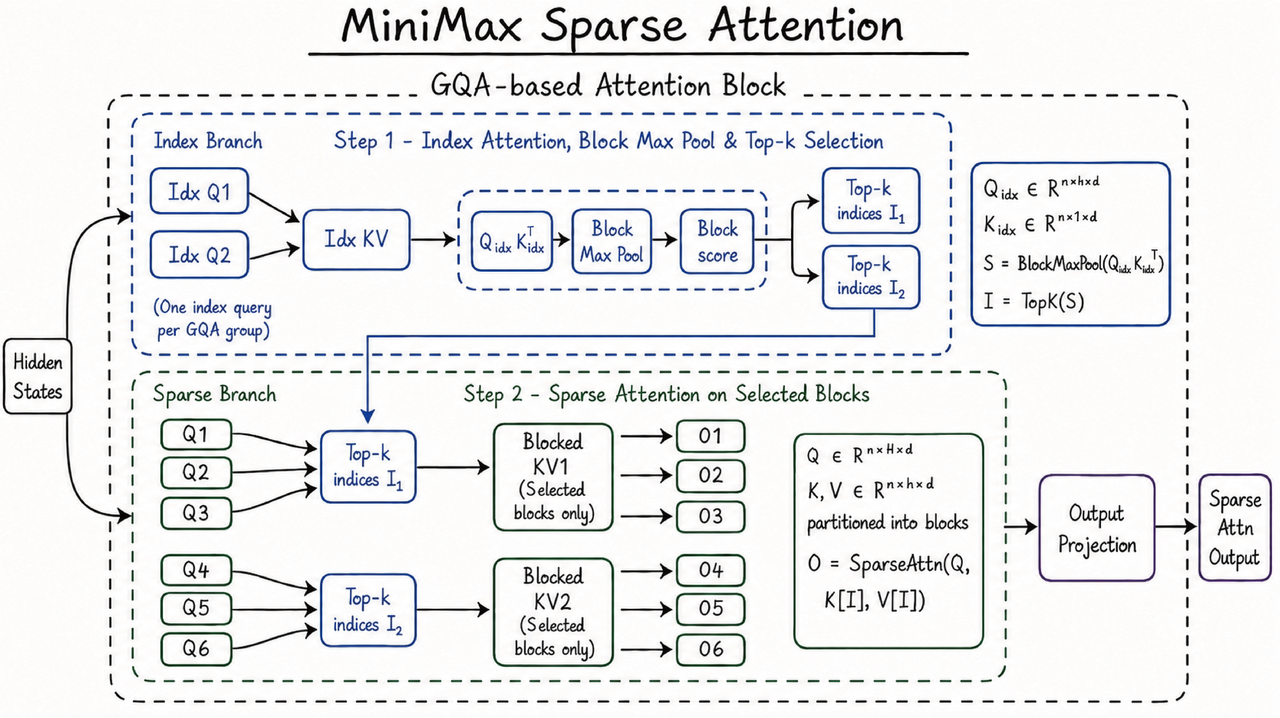
MiniMax released M3 on June 1, 2026, claiming the first open-weight model to combine frontier coding, a 1-million-token context window, and native multimodality in a single architecture. The headline is not just the benchmark sheet — it is the engine underneath: a new sparse-attention mechanism (MSA) that the company says cuts per-token compute at 1M […]
-
Thinking Machines Unveils Interaction Models for Real-Time Human-AI Collaboration
Thinking Machines Lab announced its first “interaction models” on May 11, 2026, unveiling TML-Interaction-Small — a 276B-parameter mixture-of-experts model (12B active) designed for real-time, multimodal collaboration. Rather than waiting for the user to finish speaking, the model interleaves 200-millisecond chunks of audio and video input with simultaneous output generation, eliminating the turn-taking pause that defines […]
-
Xiaomi Releases MiMo-V2.5-Pro: 1T-Parameter Open MoE Matches Frontier Coding Models
Xiaomi released MiMo-V2.5-Pro on April 22, 2026, a 1.02-trillion-parameter Mixture-of-Experts model with 42 billion active parameters that matches frontier coding and agentic benchmarks while costing a fraction of comparable closed models. The release also unifies reasoning and multimodal abilities into a single open-weights model with a 1-million-token context window. Intermediate Key points Xiaomi released MiMo-V2.5-Pro […]
-
DeepSeek Releases V4: Open-Source 1.6T MoE with 1M Context
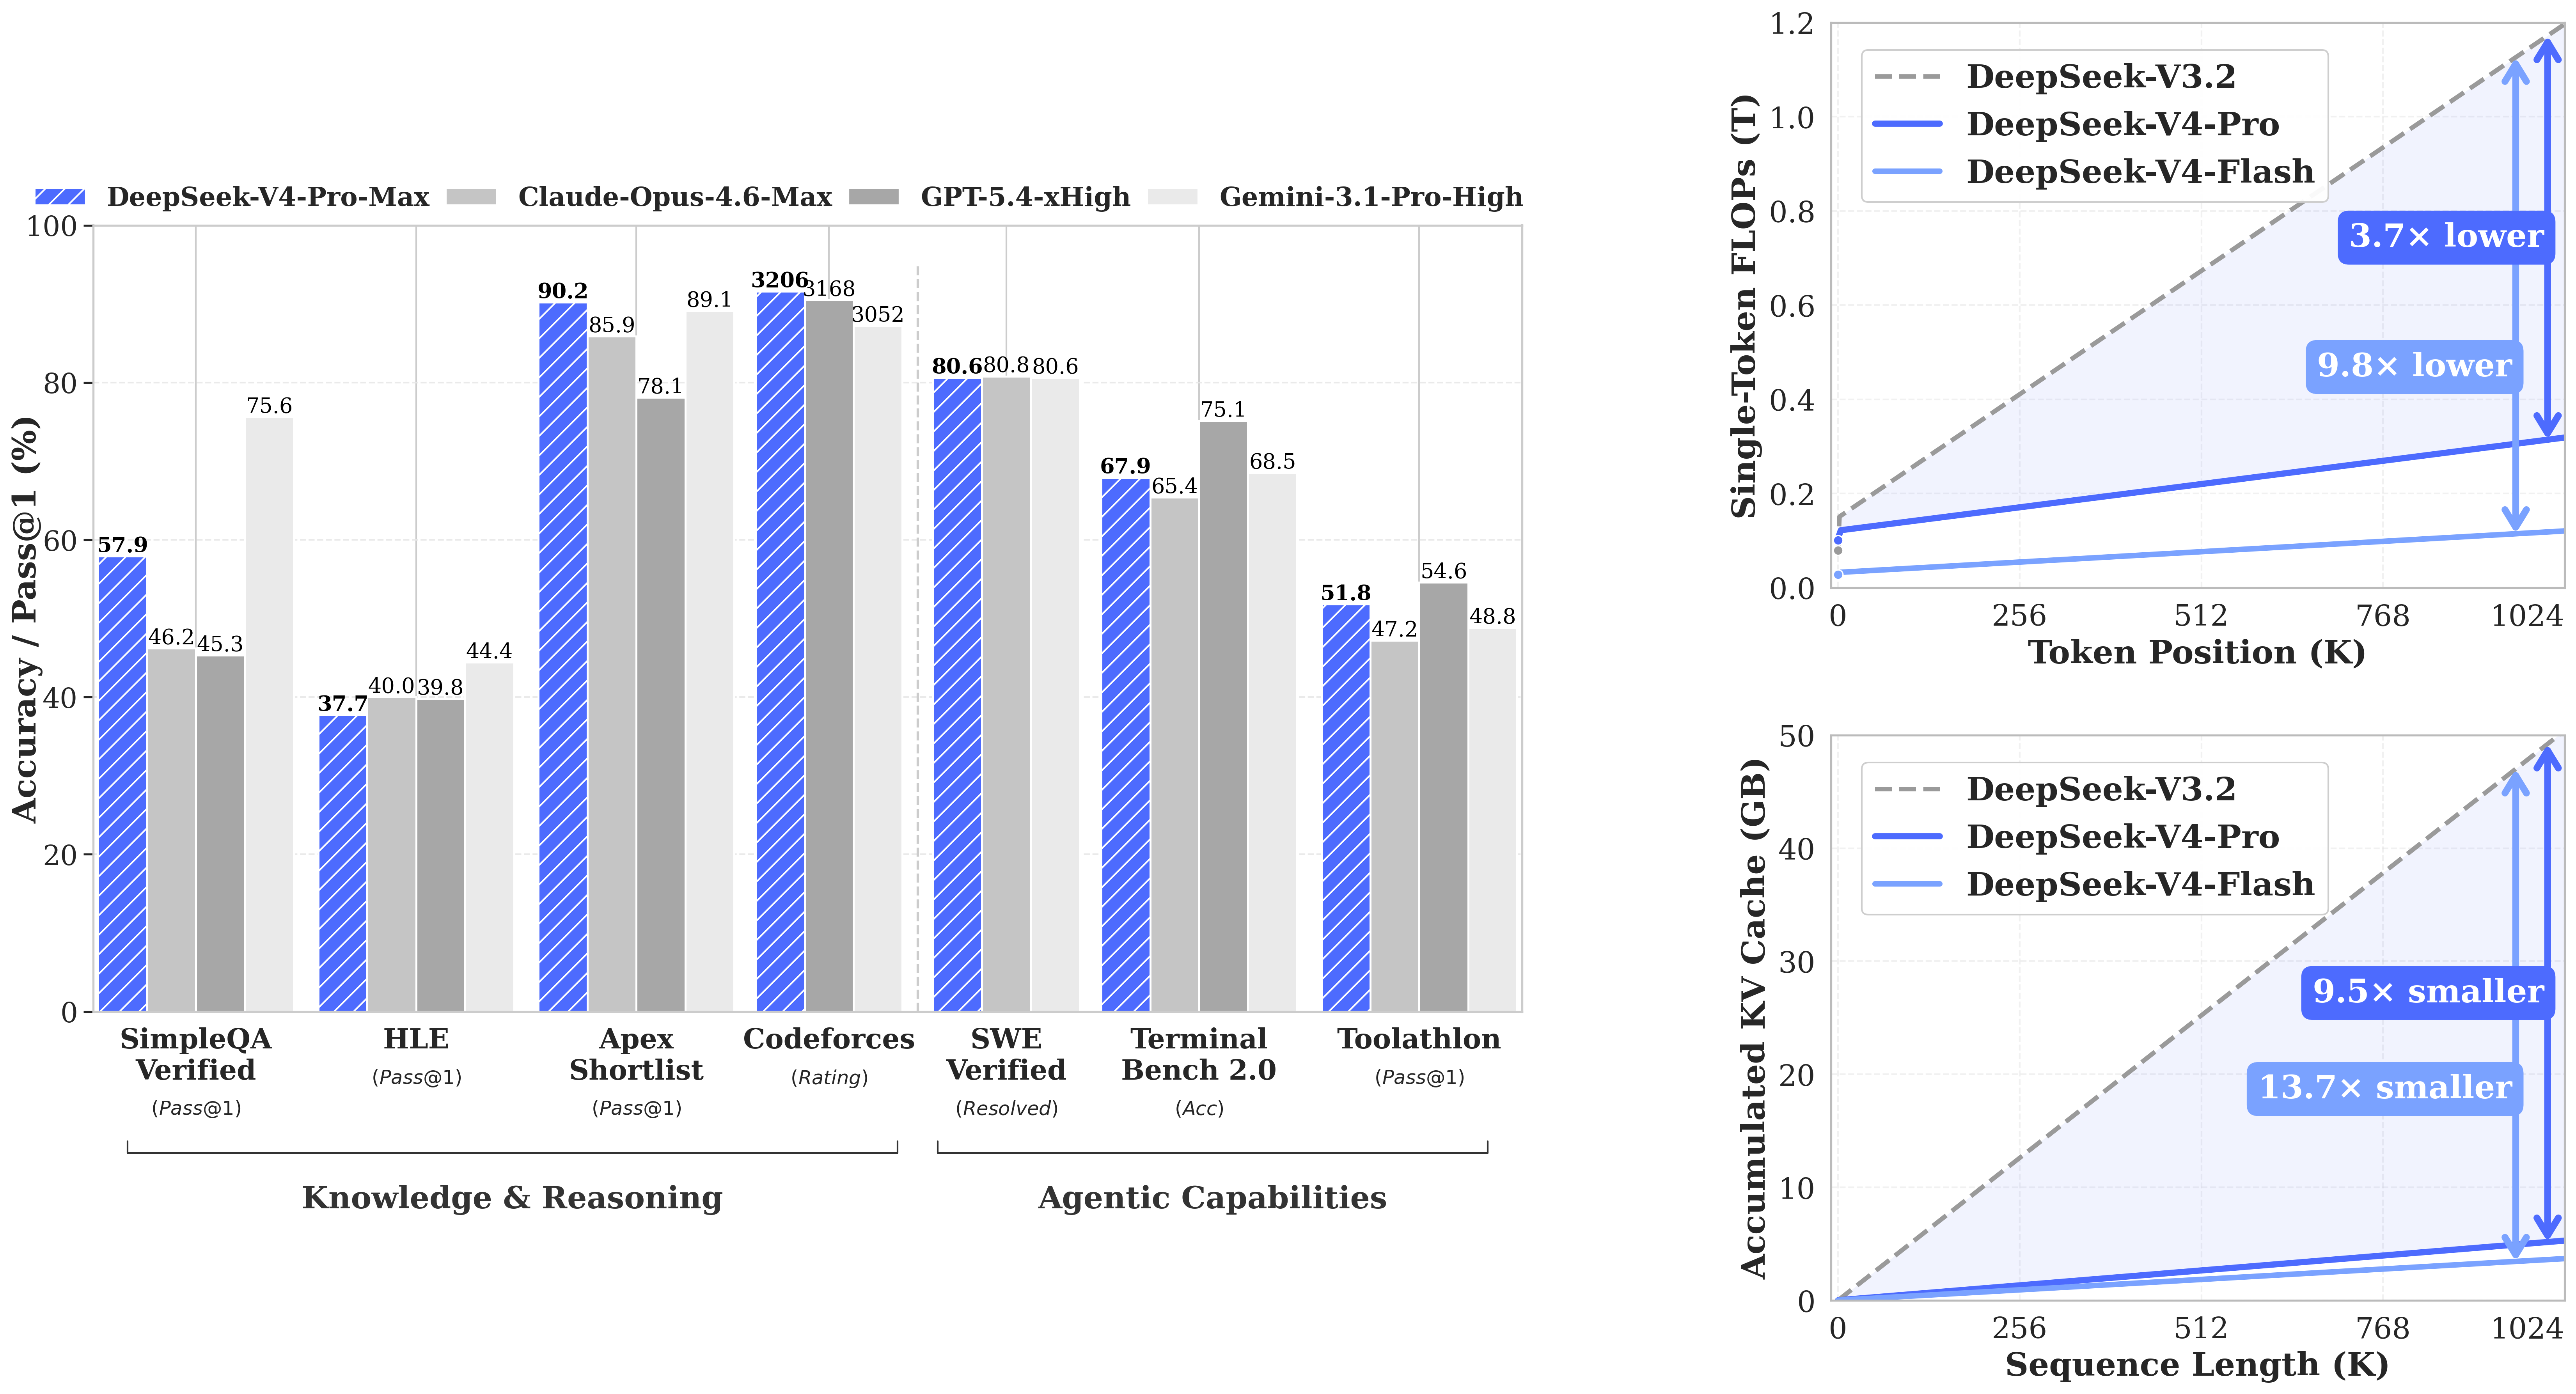
DeepSeek has launched V4, its newest flagship open-source language model, exactly one year after the V3/R1 releases that rattled Silicon Valley. Announced on April 24, 2026, the V4 family ships in two Mixture-of-Experts variants — a 1.6-trillion-parameter V4-Pro and a leaner 284-billion-parameter V4-Flash — both supporting a 1-million-token context window and both released with open […]