Tag: music
-
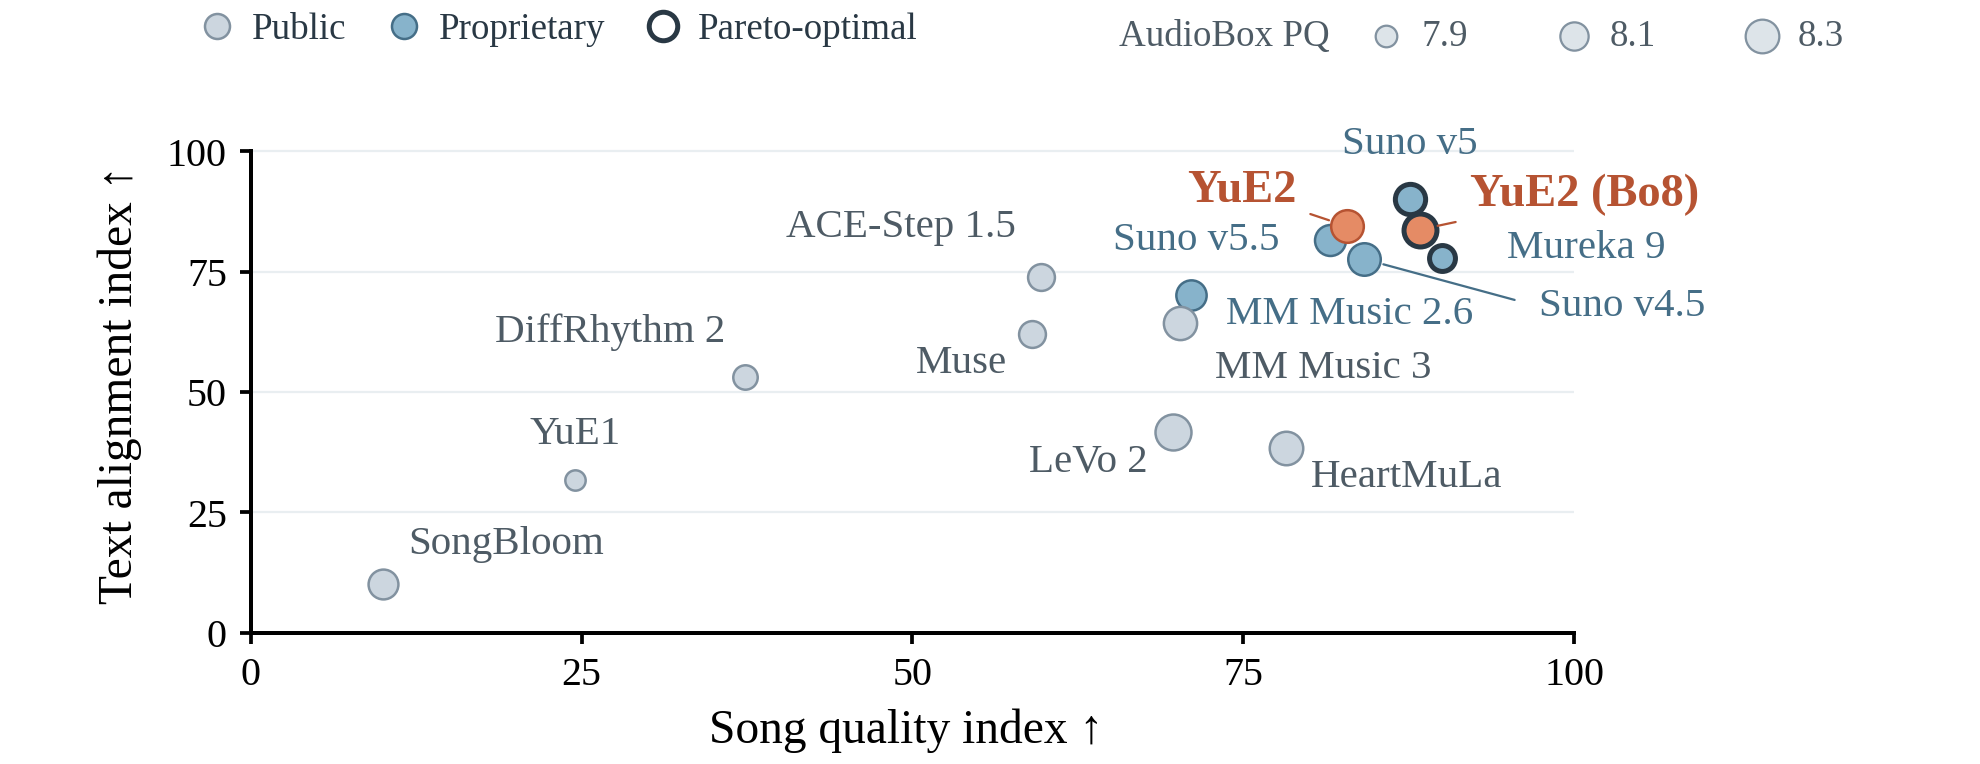
YuE2 Matches Suno v5 on Open Weights — With a Score You Can Edit
Multimodal Art Projection (M·A·P) published the weights for YuE2 on September 10, 2026 — a roughly 3.6-billion-parameter music generation model that turns a style prompt and lyrics into a complete 48 kHz stereo song, and, unusually, exposes the melody and chords it wrote as an editable score before rendering any audio. On WildSongBench, a 192-prompt […]
-
MiniMax Opens Music 3.0 Weights — No Territorial Carve-Out This Time
MiniMax published the weights for Music 3.0 on August 13, 2026, releasing an ~11.1B-parameter text-to-music model that generates complete five-minute songs — vocals, arrangement, and production — in a single pass. The weights are on Hugging Face, GitHub, and ModelScope, and ComfyUI shipped support the same day. Notably, the accompanying MiniMax-Music3 Community License contains no […]
-
Foundation-1: A Producer-Focused AI Model for Structured Music Sample Generation
RoyalCities has released Foundation-1, a specialized text-to-sample AI model built on Stability AI’s Stable Audio Open architecture. Unlike general-purpose music generators that output full songs, Foundation-1 is designed for actual music production workflows — generating tempo-synced, key-aware, bar-structured audio loops with fine-grained control over instrumentation, timbre, effects, and musical phrasing. Intermediate Key points RoyalCities released […]
-
ACE-Step 1.5: Open-Source Music Generation That Rivals Commercial AI
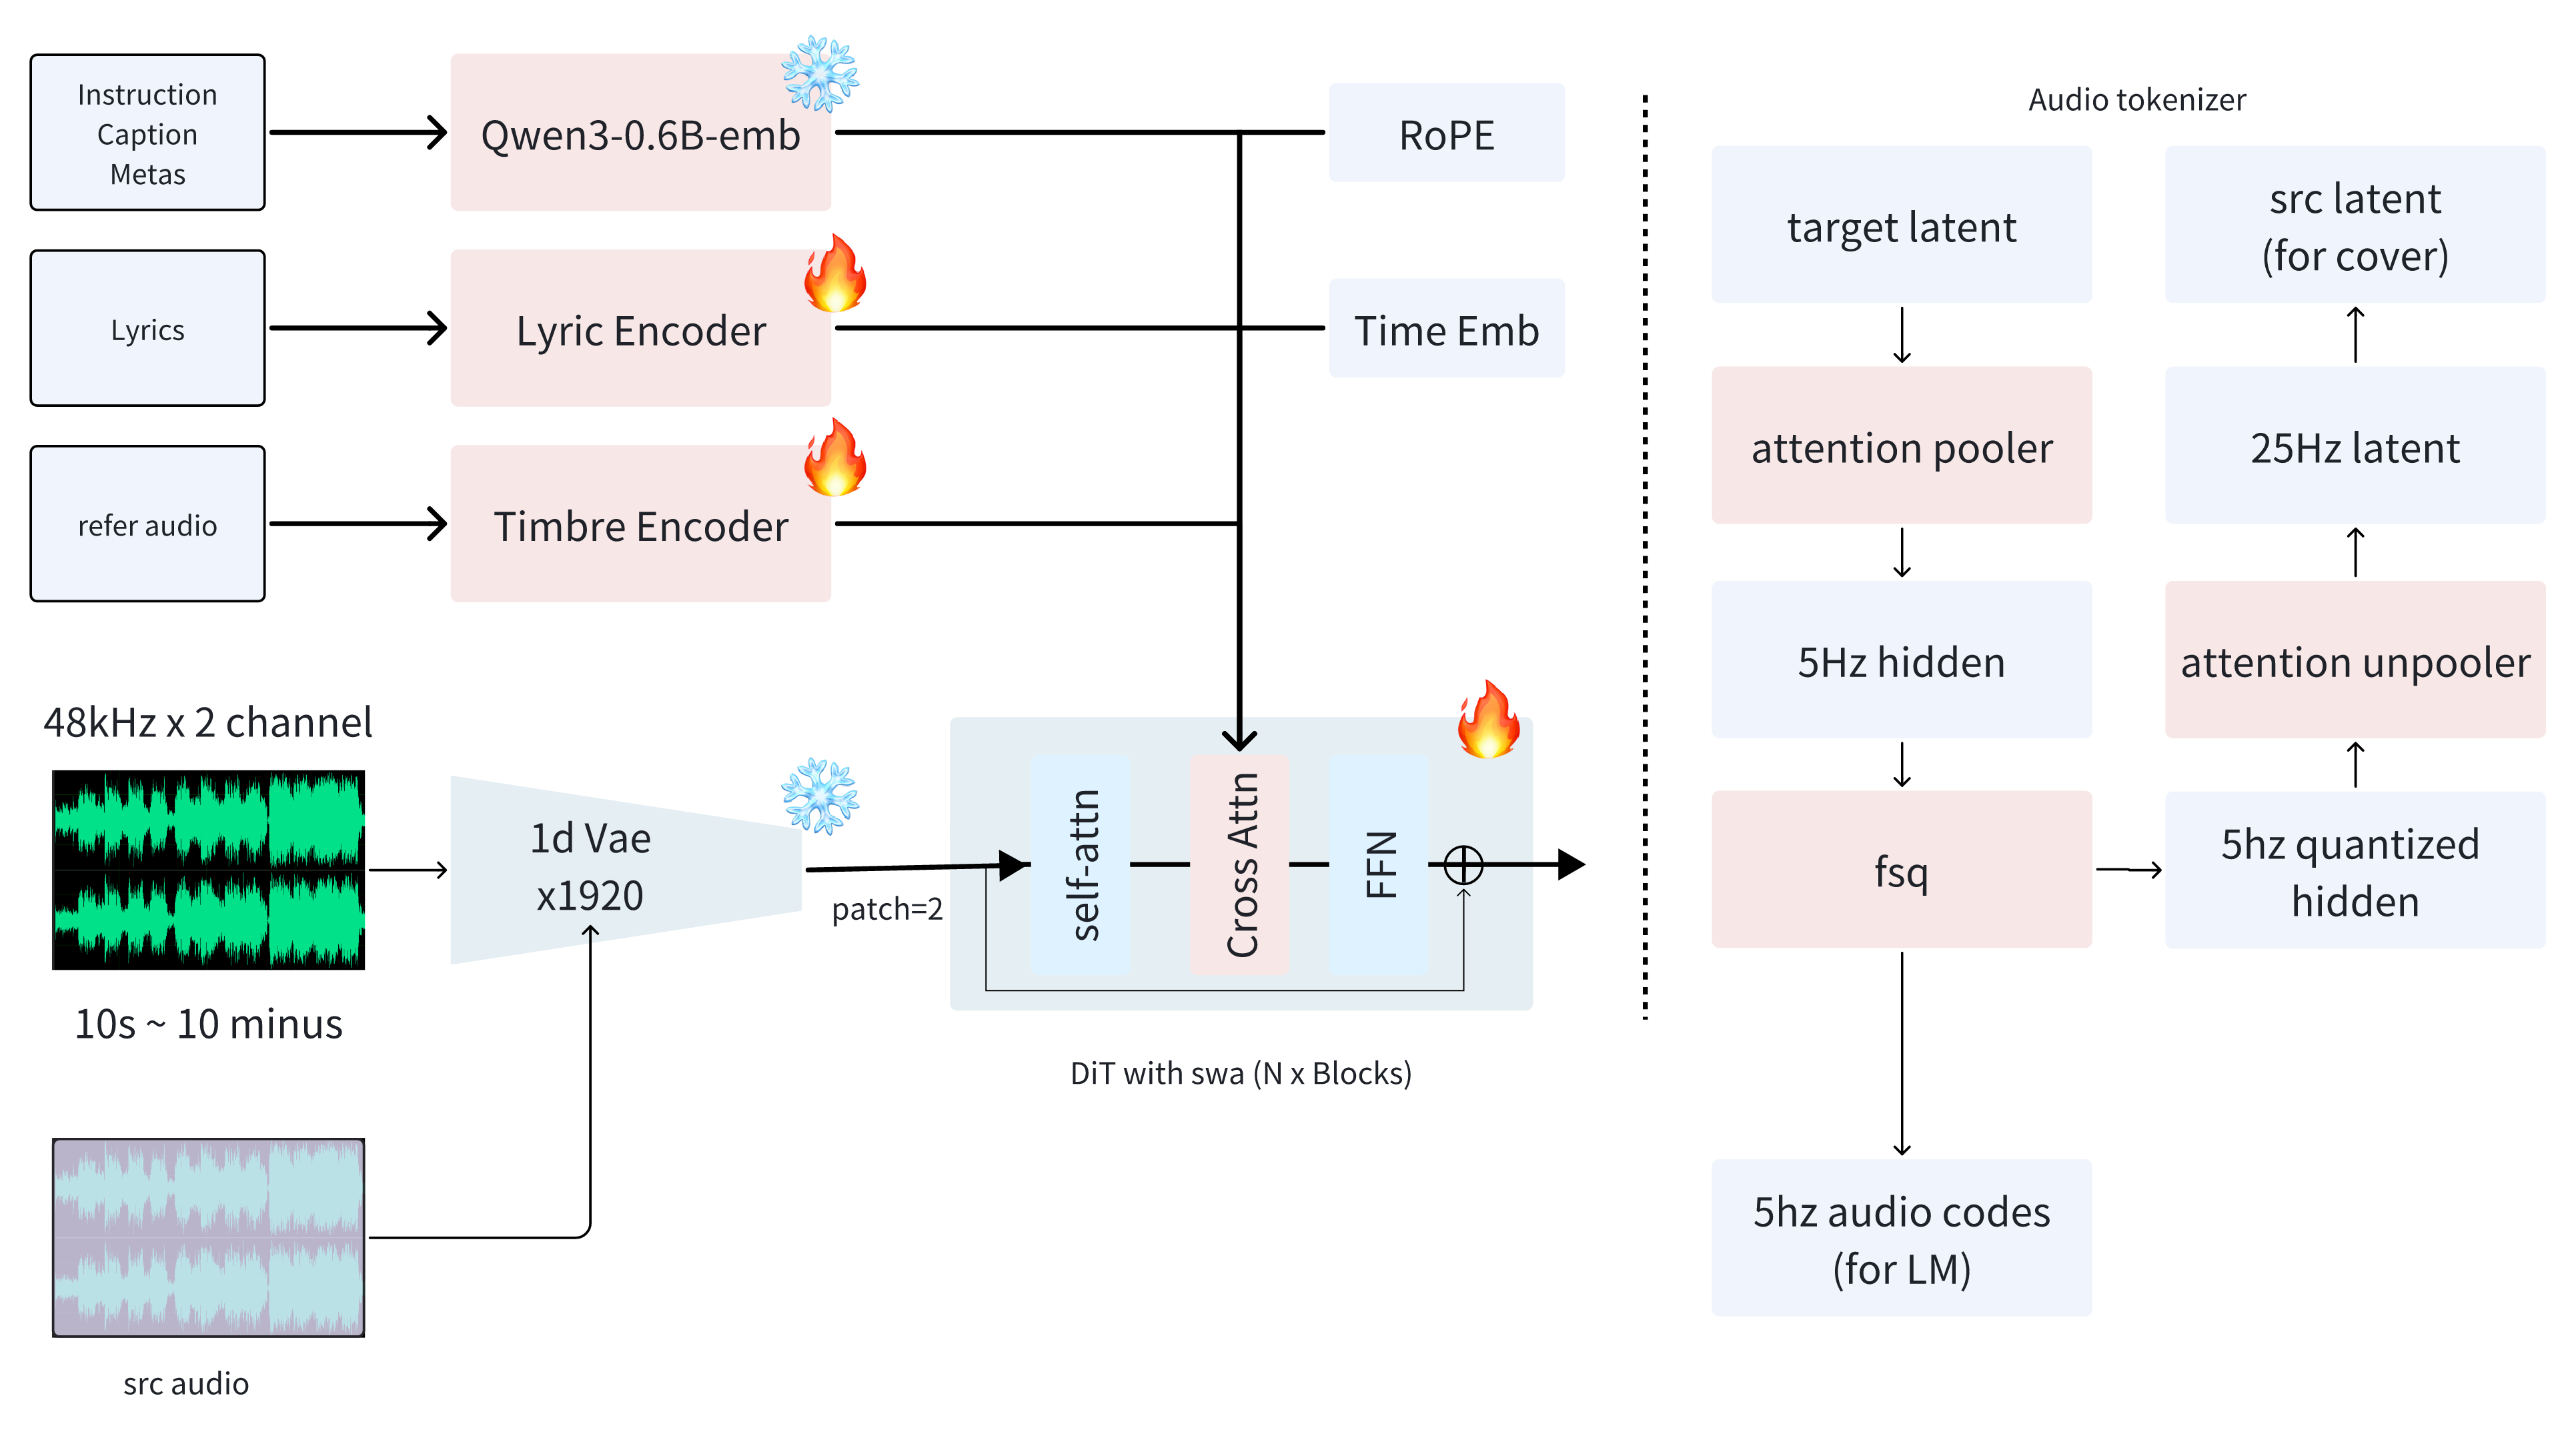
Key points ACE-Step 1.5, released on January 28, 2026, is an open-source music generation model jointly developed by ACE Studio and StepFun. It generates a full song in under 2 seconds on an A100 GPU or under 10 seconds on an RTX 3090 while requiring less than 4GB of VRAM. The model uses a two-stage […]
-
🎵 HeartMuLa: A Family of Open-Source Music Foundation Models
HeartMuLa is an open-source suite of AI models focused on music understanding and generation. It’s designed to help researchers and creators synthesize high-quality music using rich user prompts such as lyrics, style descriptions, and even reference audio. (HeartMuLa) Key points HeartMuLa is an open-source suite of AI models focused on music understanding and generation. It […]
-
🎵 Music Flamingo (MF) — Advanced Music Understanding with AI
Music Flamingo is a cutting-edge research project by NVIDIA’s Applied Deep Learning Research (ADLR) group that advances how AI systems understand music audio — not just speech. (NVIDIA) Key points Music Flamingo is a research project by NVIDIA’s Applied Deep Learning Research group that advances how AI systems understand music audio, not just speech. It […]
-
ElevenLabs Unveils Eleven Music: AI-Generated Studio-Quality Tracks from Text Prompts
In a significant leap forward for AI audio creation, ElevenLabs has officially launched Eleven Music—a cutting-edge text-to-music model designed to generate complete, studio-grade tracks simply from natural-language descriptions. (Eleven Labs, Eleven Labs) Key points ElevenLabs launched Eleven Music, a text-to-music model designed to generate complete, studio-grade tracks from natural-language descriptions. Users can request music with […]
-
Introducing MagentaRT: Google’s Open-Weights Real-Time Music Generation Model
Today, Google’s Magenta team unveiled Magenta RealTime (MagentaRT), an 800-million-parameter autoregressive transformer model designed to generate high-fidelity, 48 kHz stereo music in real time with low latency and full user control (magenta.withgoogle.com). Licensed permissively (with some bespoke terms), MagentaRT is the open-weights counterpart to Google’s proprietary Lyria RealTime model and aims to eventually run locally […]