Tag: AI
-
TinyGPU Brings NVIDIA and AMD eGPUs to Apple Silicon Macs
On March 31, 2026, George Hotz’s Tiny Corp announced that Apple has officially approved the TinyGPU driver extension — making it possible for Apple Silicon Mac users to run external NVIDIA and AMD GPUs over Thunderbolt/USB4 without disabling System Integrity Protection. After more than a year of engineering custom userspace GPU drivers, the approval marks […]
-
Google Releases Gemma 4: Frontier Open Models Under Apache 2.0
On April 2, 2026, Google DeepMind released Gemma 4 — its most capable open model family to date, purpose-built for advanced reasoning and agentic workflows. Available under a fully permissive Apache 2.0 license, Gemma 4 delivers frontier-class multimodal intelligence across four model sizes, from edge devices to high-performance workstations. Intermediate Key points On April 2, […]
-
OpenAI Ships Official Codex Plugin for Anthropic’s Claude Code
OpenAI has released an official plugin that embeds its Codex coding agent directly inside Anthropic’s Claude Code CLI. Announced on March 30, 2026, the open-source codex-plugin-cc plugin lets developers invoke Codex for code reviews, adversarial analysis, and task delegation — all without leaving the Claude Code terminal. The move is notable because OpenAI is deliberately […]
-
Agents of Chaos: What Happens When Autonomous AI Agents Get Real Tools
On February 23, 2026, a team of 38 researchers from Northeastern University, Harvard, Stanford, Carnegie Mellon, MIT, and other institutions published Agents of Chaos — a red-teaming study that gave six autonomous AI agents real tools, persistent memory, and unrestricted shell access, then watched what happened over two weeks. The results reveal that individually aligned […]
-
ZML: A Zig-Based Inference Engine Bringing LLMs to AMD GPUs
ZML, a Paris-based open-source project, is gaining traction as a production inference stack written almost entirely in Zig — bypassing the Python and PyTorch dependency chains that dominate AI infrastructure. With its v2 release on March 24, 2026, ZML now compiles large language models directly onto NVIDIA, AMD, Google TPU, and AWS Trainium hardware from […]
-
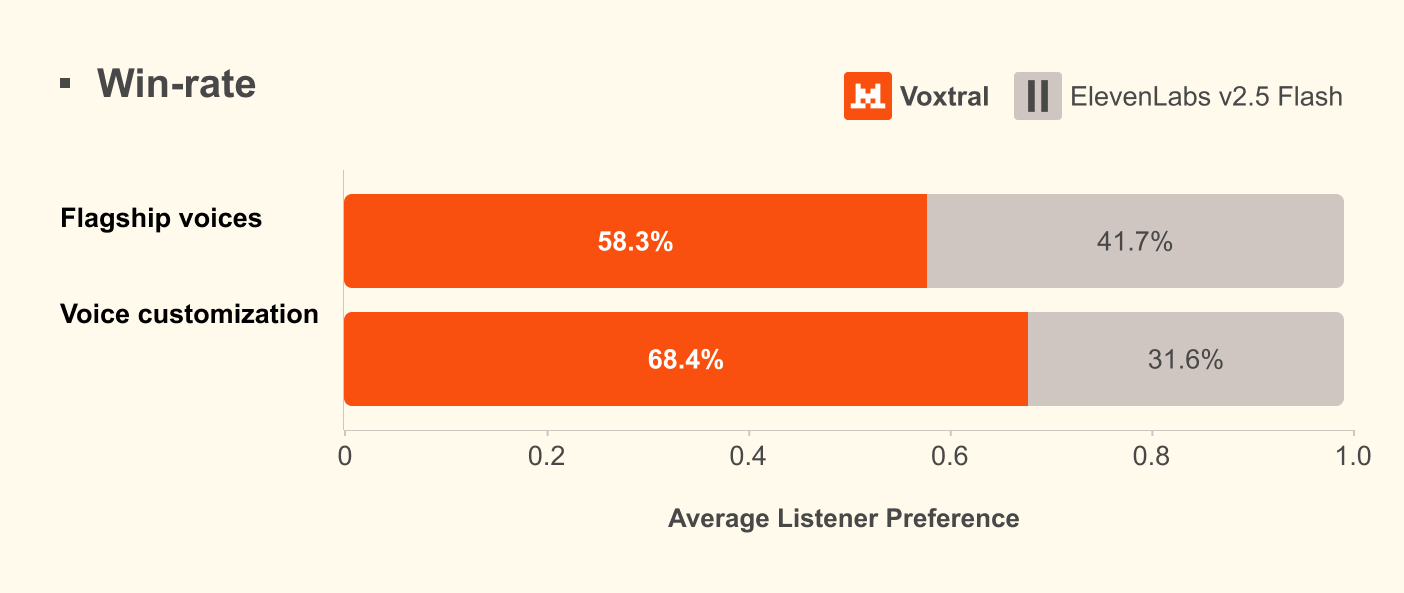
Voxtral TTS: Mistral’s Open-Weight Text-to-Speech Model Rivals ElevenLabs
On March 26, 2026, Mistral AI released Voxtral TTS — a 4-billion-parameter open-weight text-to-speech model that the company says outperforms ElevenLabs Flash v2.5 in human preference tests while matching ElevenLabs v3 in lifelike interactions. Built on Ministral 3B, Voxtral TTS supports nine languages, clones voices from just three seconds of audio, and achieves 70ms latency […]
-
Cohere Transcribe: 2B Open-Source ASR Model Takes #1 on Leaderboard
On March 26, 2026, Cohere released Cohere Transcribe — a 2-billion-parameter open-source automatic speech recognition (ASR) model that claims the #1 spot on the Hugging Face Open ASR Leaderboard. Licensed under Apache 2.0 and designed to run on consumer-grade GPUs, Transcribe marks Cohere’s first entry into voice AI and signals growing competition in the open-source […]
-
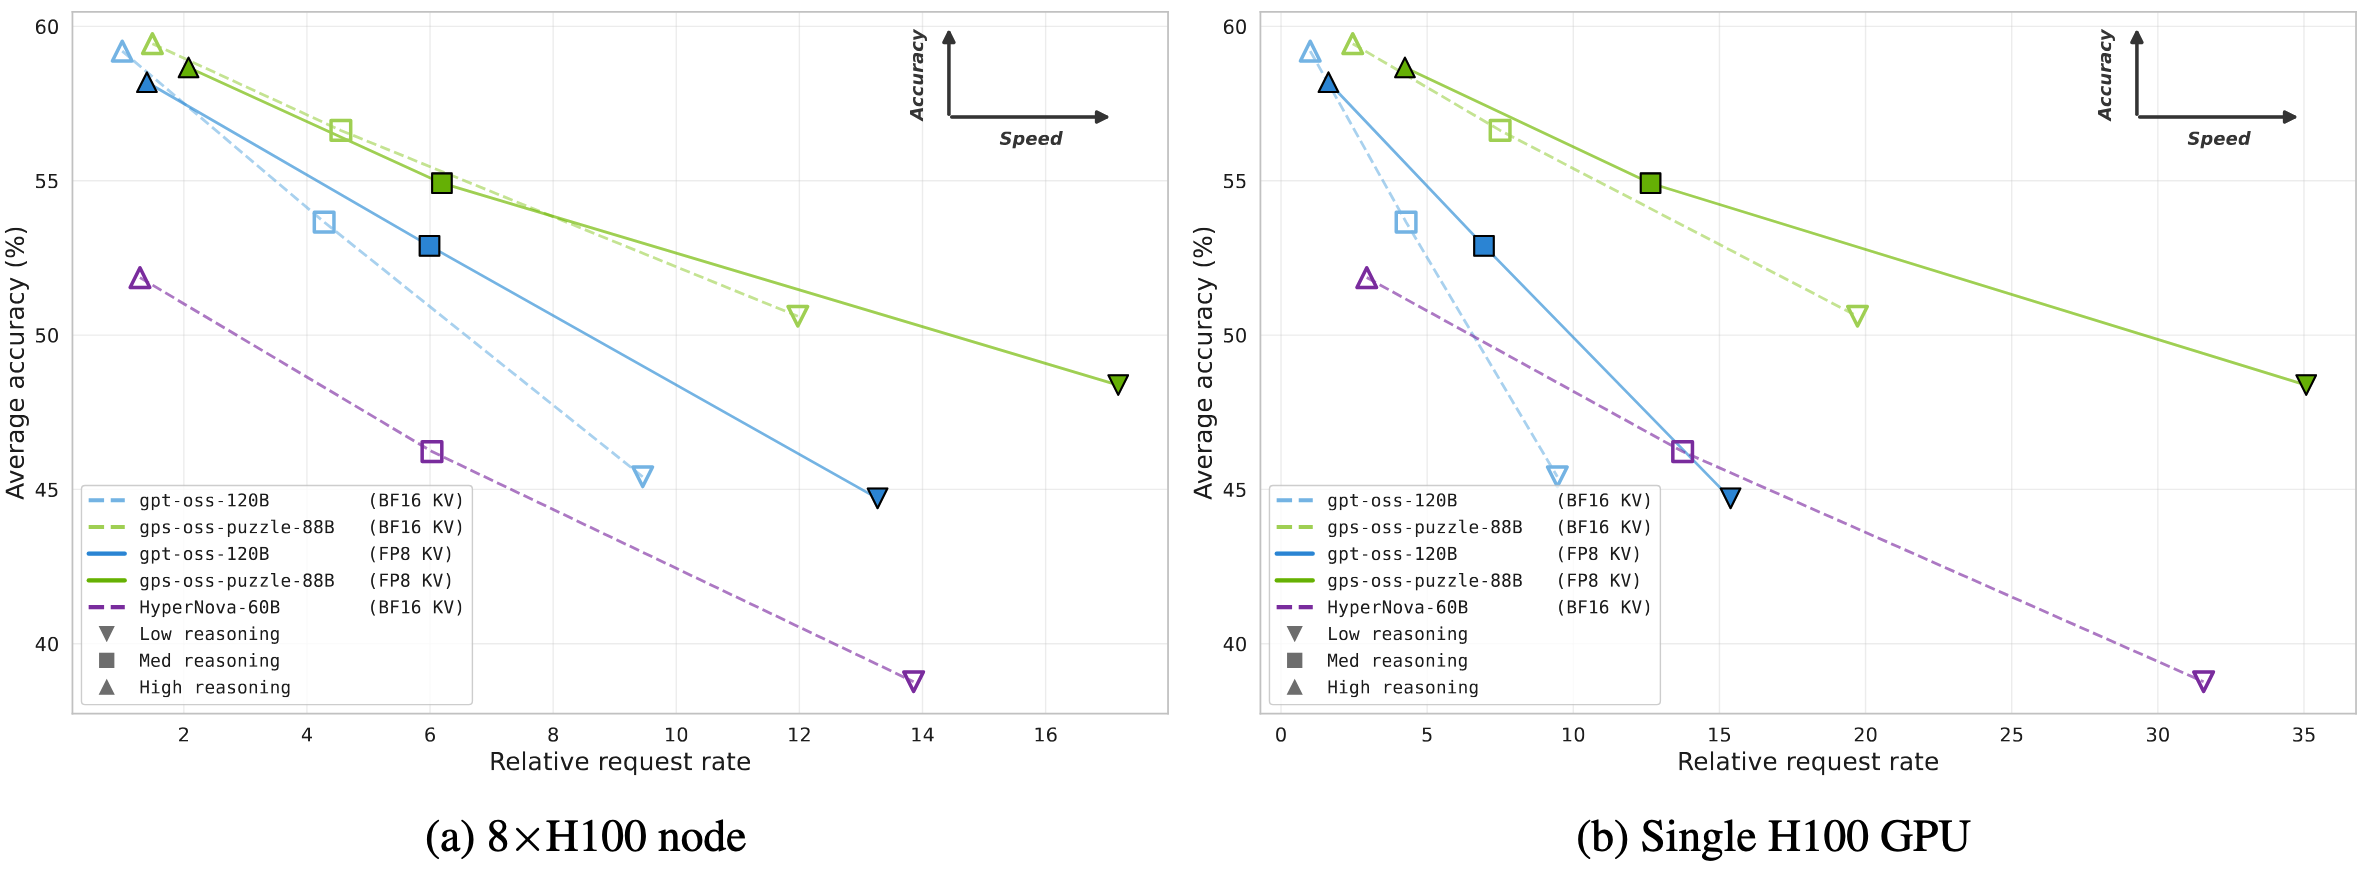
NVIDIA Releases gpt-oss-puzzle-88B: Up to 2.82× Faster Reasoning on a Single H100
On March 26, 2026, NVIDIA released gpt-oss-puzzle-88B — a deployment-optimized version of OpenAI’s gpt-oss-120B reasoning model that delivers up to 2.82× faster inference while matching or exceeding the original model’s accuracy. Created using NVIDIA’s Puzzle neural architecture search framework, the 88-billion-parameter model fits on a single H100 GPU and represents a significant step forward in […]
-
Google’s TurboQuant Cuts LLM Memory 6x with Zero Accuracy Loss
On March 25, 2026, Google Research introduced TurboQuant — a new compression algorithm that reduces LLM key-value (KV) cache memory by 6x and delivers up to 8x inference speedup on NVIDIA H100 GPUs, all with zero accuracy loss. The algorithm, set to be presented at ICLR 2026, could reshape how organizations deploy large language models […]
-
LiteLLM Backdoored, LM Studio Flagged: AI Tools Face Supply Chain Threats
Two major security incidents hit the AI developer ecosystem within hours on March 24, 2026: backdoored versions of LiteLLM, the popular LLM API proxy, were published to PyPI carrying a multi-stage credential stealer, while LM Studio users reported Windows Defender flagging the local AI tool as a trojan. Together, the incidents underscore how the software […]