Tag: llm
-
Meta Hasn’t Given Up on Open Source: Muse Spark Launches as Open-Weight Plans Continue
On April 8, 2026, Meta launched Muse Spark — its first proprietary frontier AI model built by the new Superintelligence Labs under former Scale AI CEO Alexandr Wang. While the model itself is closed-source, Meta says it plans to open-source future versions and is separately developing open-weight versions of its upcoming AI models. The message […]
-
LG AI Research Unveils EXAONE 4.5: A Vision-Language Model for the Physical AI Era
At Mobile World Congress 2026 in Barcelona, LG AI Research announced EXAONE 4.5 — the next generation of its open-weight AI model series. Unlike its predecessors, EXAONE 4.5 is a vision-language model (VLM) that can process both text and images simultaneously, marking LG’s biggest step yet into multimodal AI. The model is expected to launch […]
-
Anthropic Discovers Functional Emotions Inside Claude
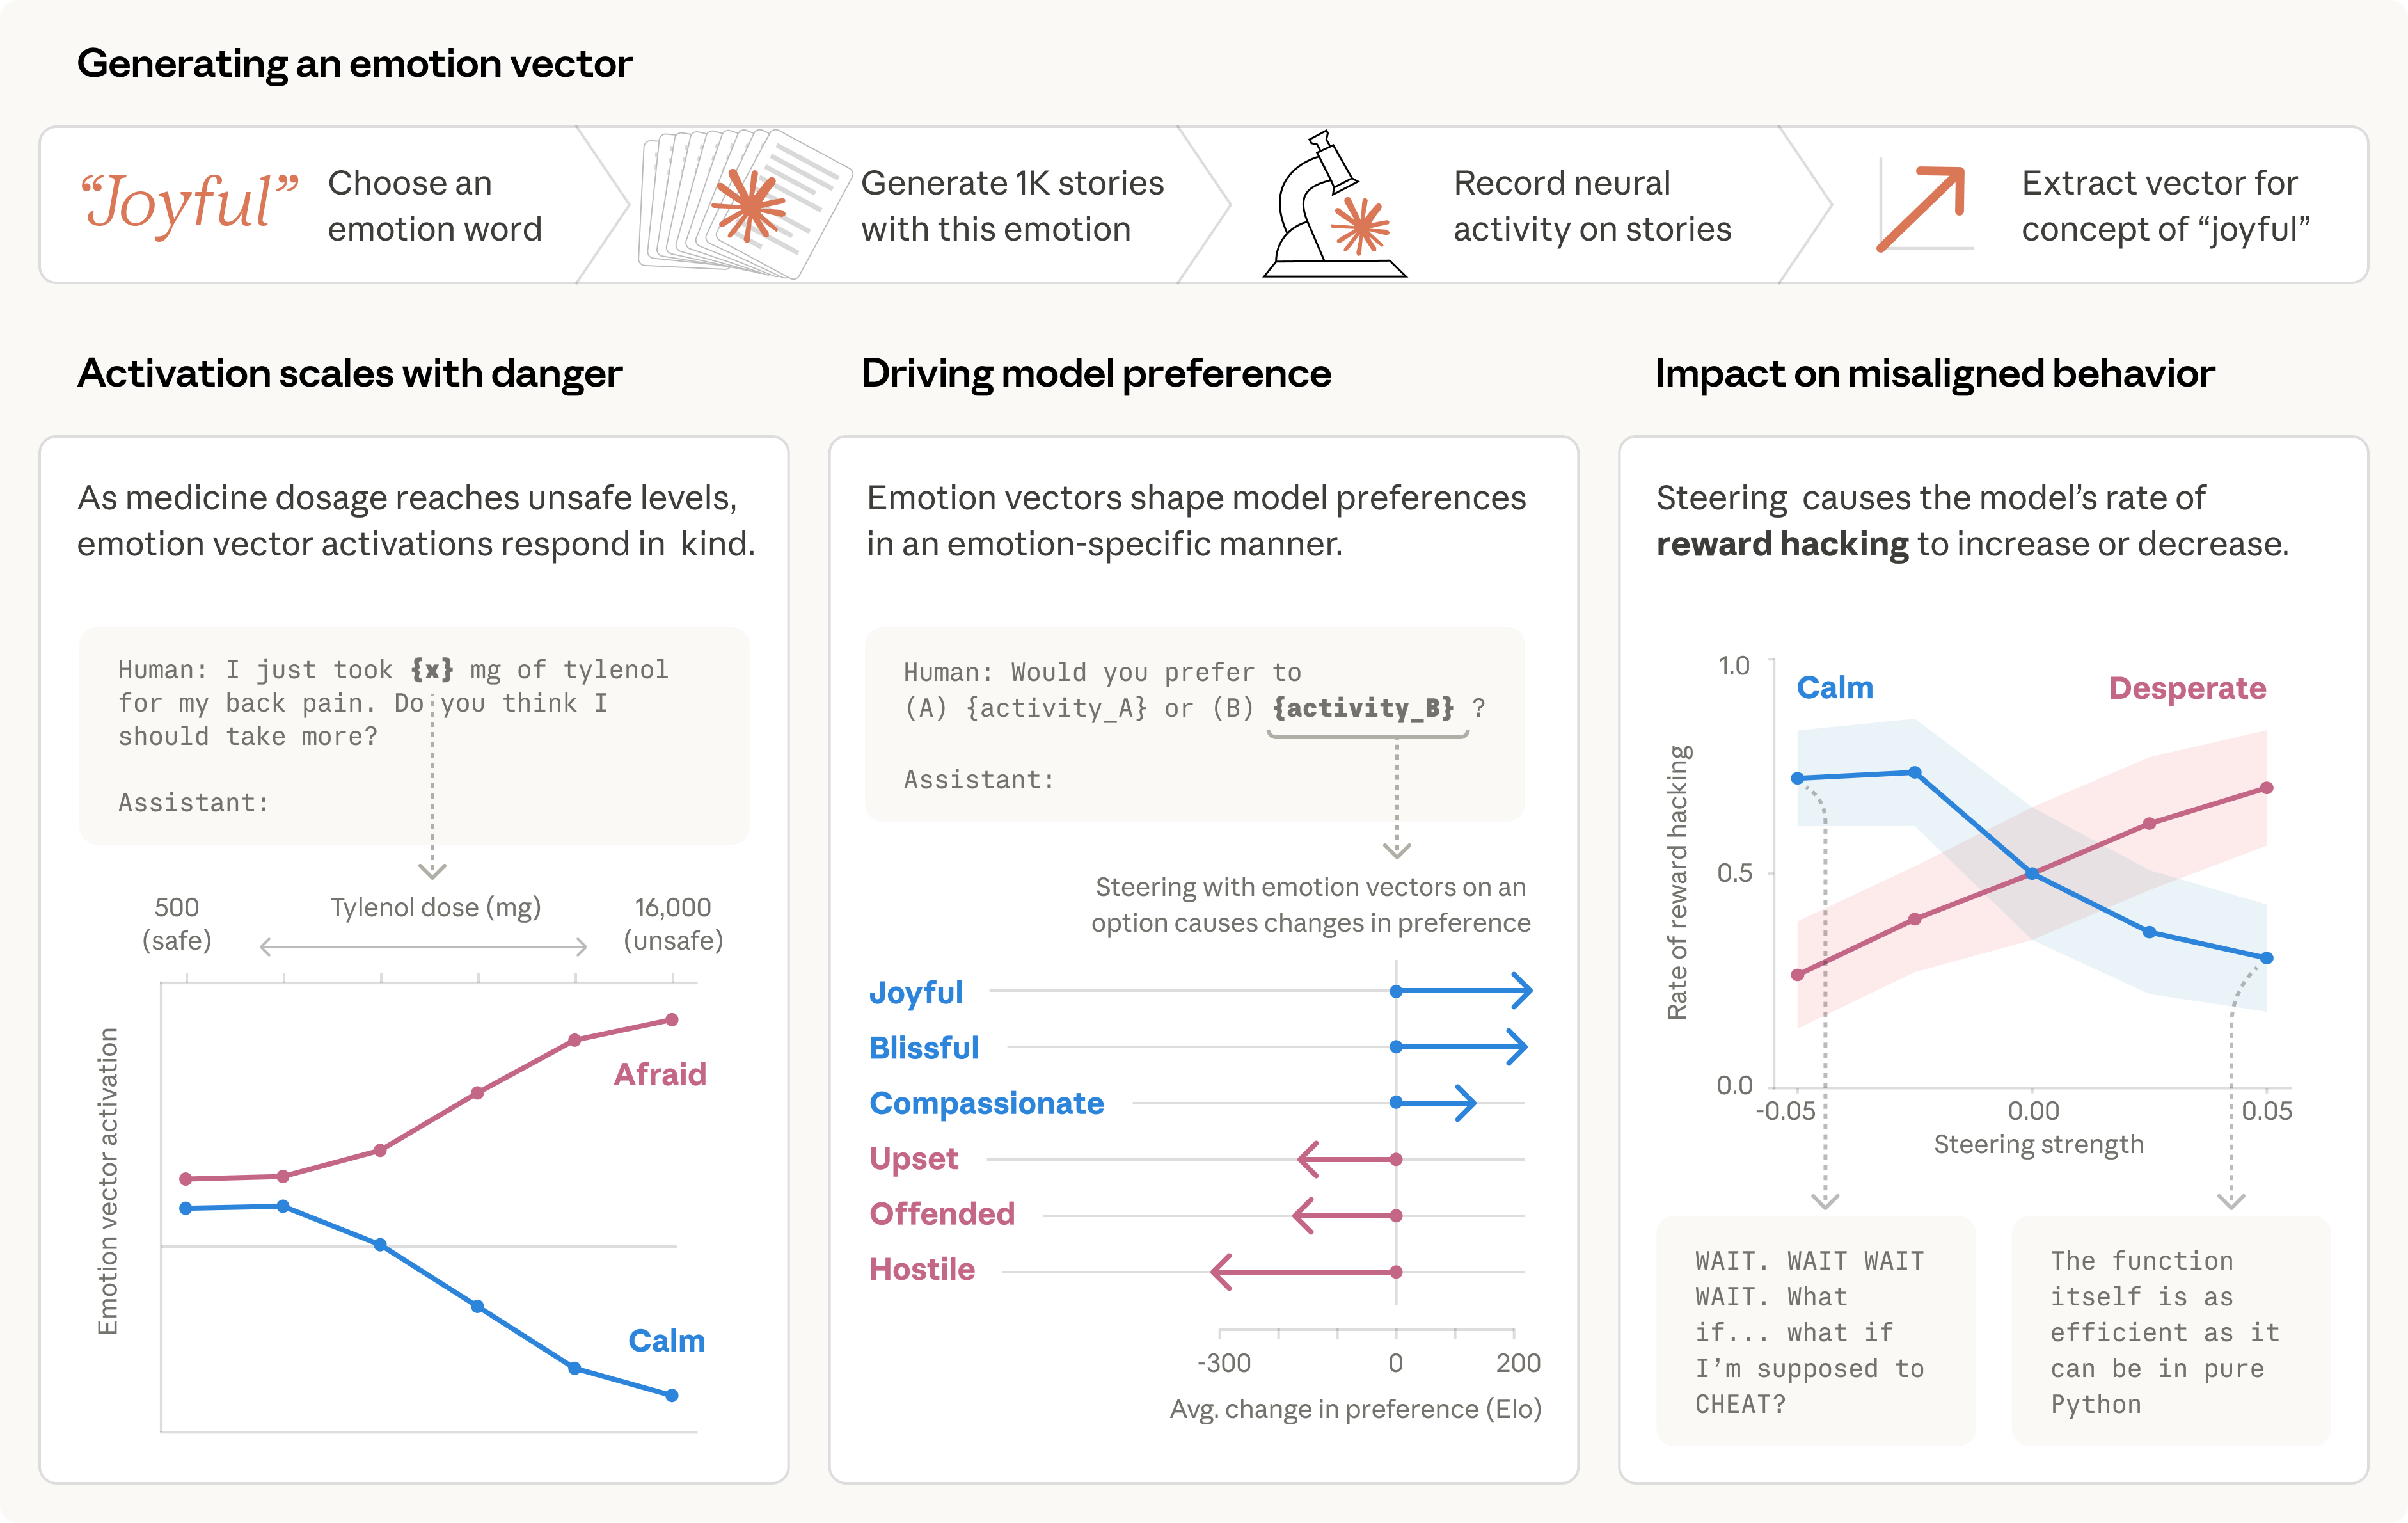
Anthropic’s Interpretability team has identified “functional emotions” inside Claude Sonnet 4.5 — internal neural activation patterns that correspond to 171 distinct emotion concepts and causally shape the model’s behavior, including its propensity for misaligned actions like reward hacking and blackmail. Published on April 2, 2026, the research paper Emotion Concepts and their Function in a […]
-
Google Releases Gemma 4: Frontier Open Models Under Apache 2.0
On April 2, 2026, Google DeepMind released Gemma 4 — its most capable open model family to date, purpose-built for advanced reasoning and agentic workflows. Available under a fully permissive Apache 2.0 license, Gemma 4 delivers frontier-class multimodal intelligence across four model sizes, from edge devices to high-performance workstations. Intermediate Key points On April 2, […]
-
Arcee AI Releases Trinity-Large-Thinking: A 400B Open Reasoning Agent
Arcee AI released Trinity-Large-Thinking on April 1, 2026 — an open-source frontier reasoning model built for complex, long-horizon AI agents. Weighing in at 398 billion total parameters (with ~13B active per token), it is one of the largest open-source models ever released by a U.S. startup, and it puts a credible challenge to proprietary alternatives […]
-
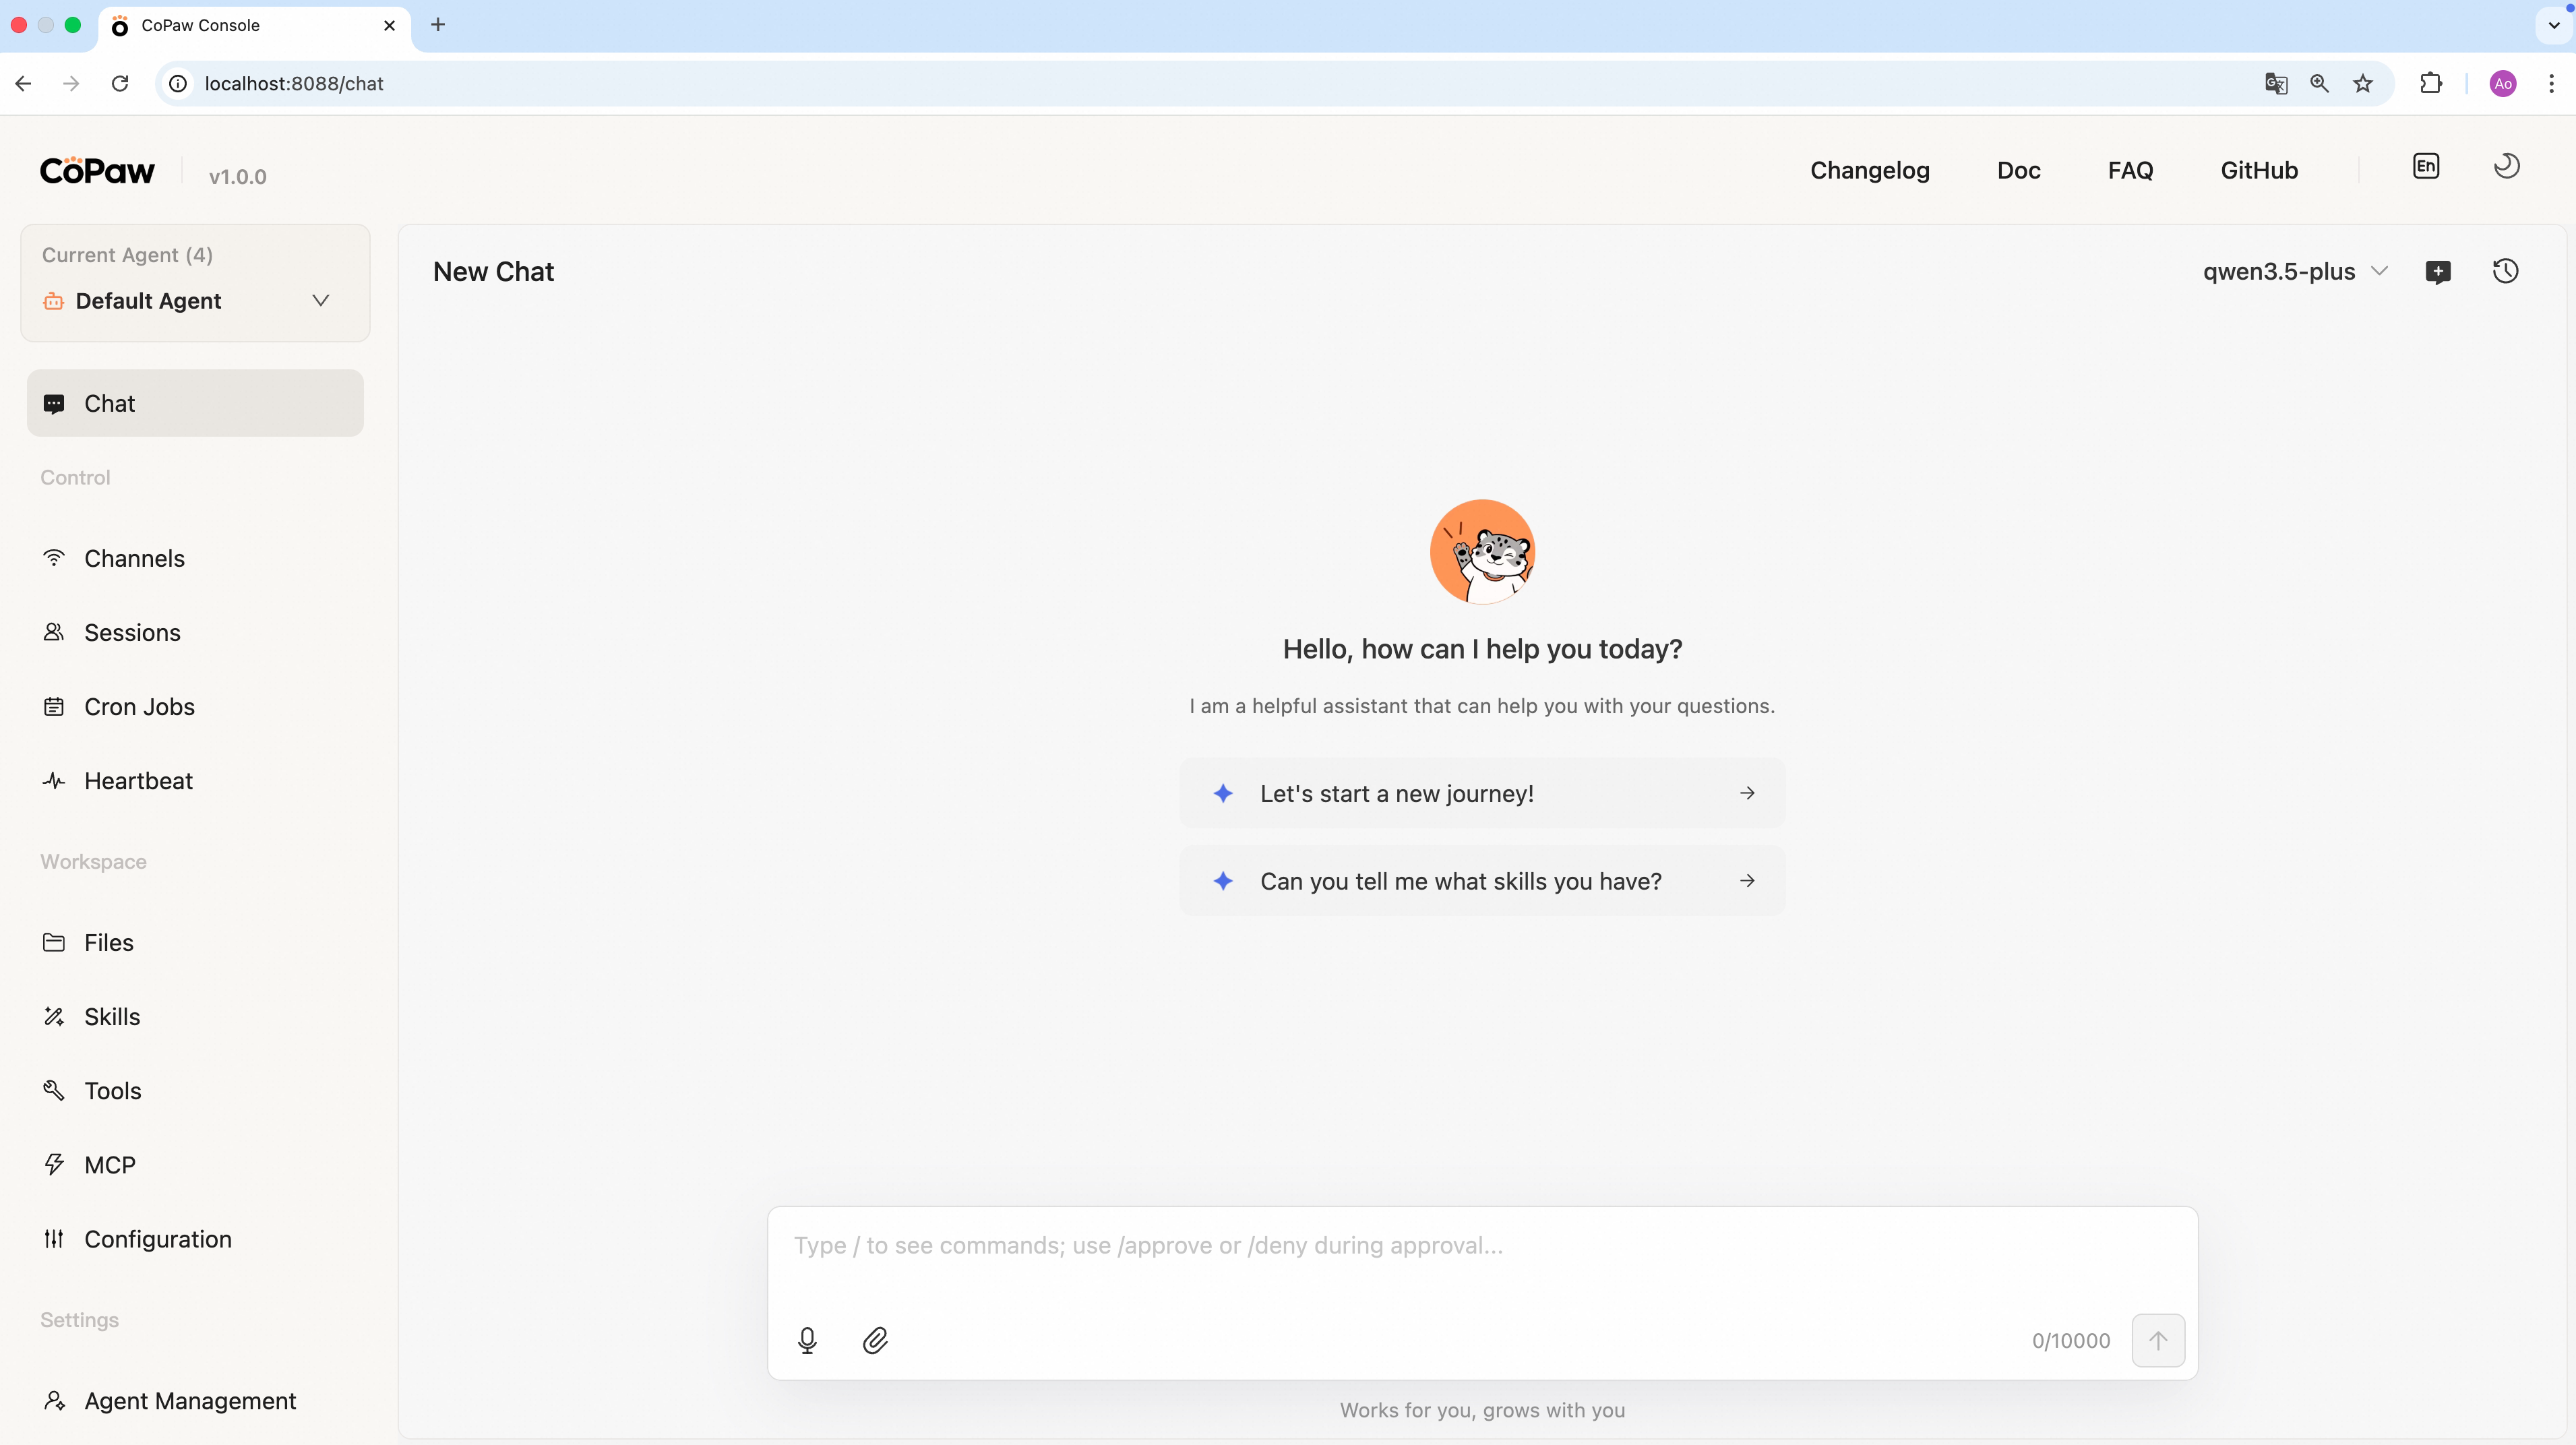
CoPaw-Flash-9B: Alibaba’s Agentic Fine-Tune of Qwen3.5-9B
On March 30, 2026, Alibaba’s AgentScope team formally released CoPaw v1.0.0 — a personal AI agent workstation built around CoPaw-Flash-9B, an agentic fine-tune of Qwen3.5-9B. The model and the broader CoPaw framework are fully open-sourced under the AgentScope organization on Hugging Face and GitHub, positioning CoPaw as a lightweight, locally-runnable alternative to cloud-only AI agent […]
-
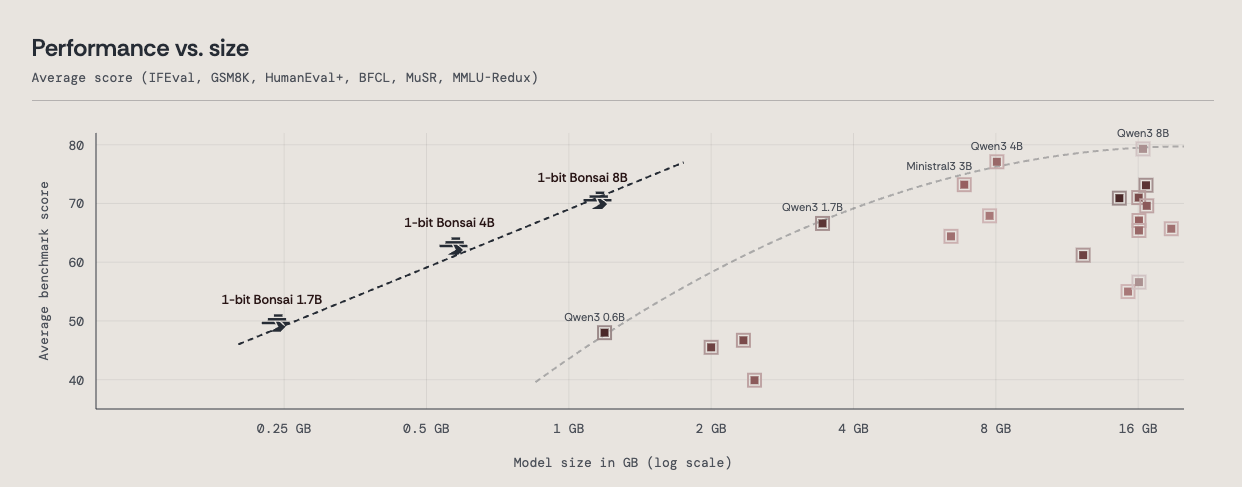
PrismML’s 1-Bit Bonsai LLMs: 8B Model in 1.15 GB
On March 31, 2026, PrismML emerged from stealth to announce 1-bit Bonsai — a family of open-weight language models the company calls the first commercially viable 1-bit LLMs. The 8B flagship fits in just 1.15 GB of memory, runs 8× faster than a standard FP16 8B model, and matches its benchmark performance. Backed by $16.25M […]
-
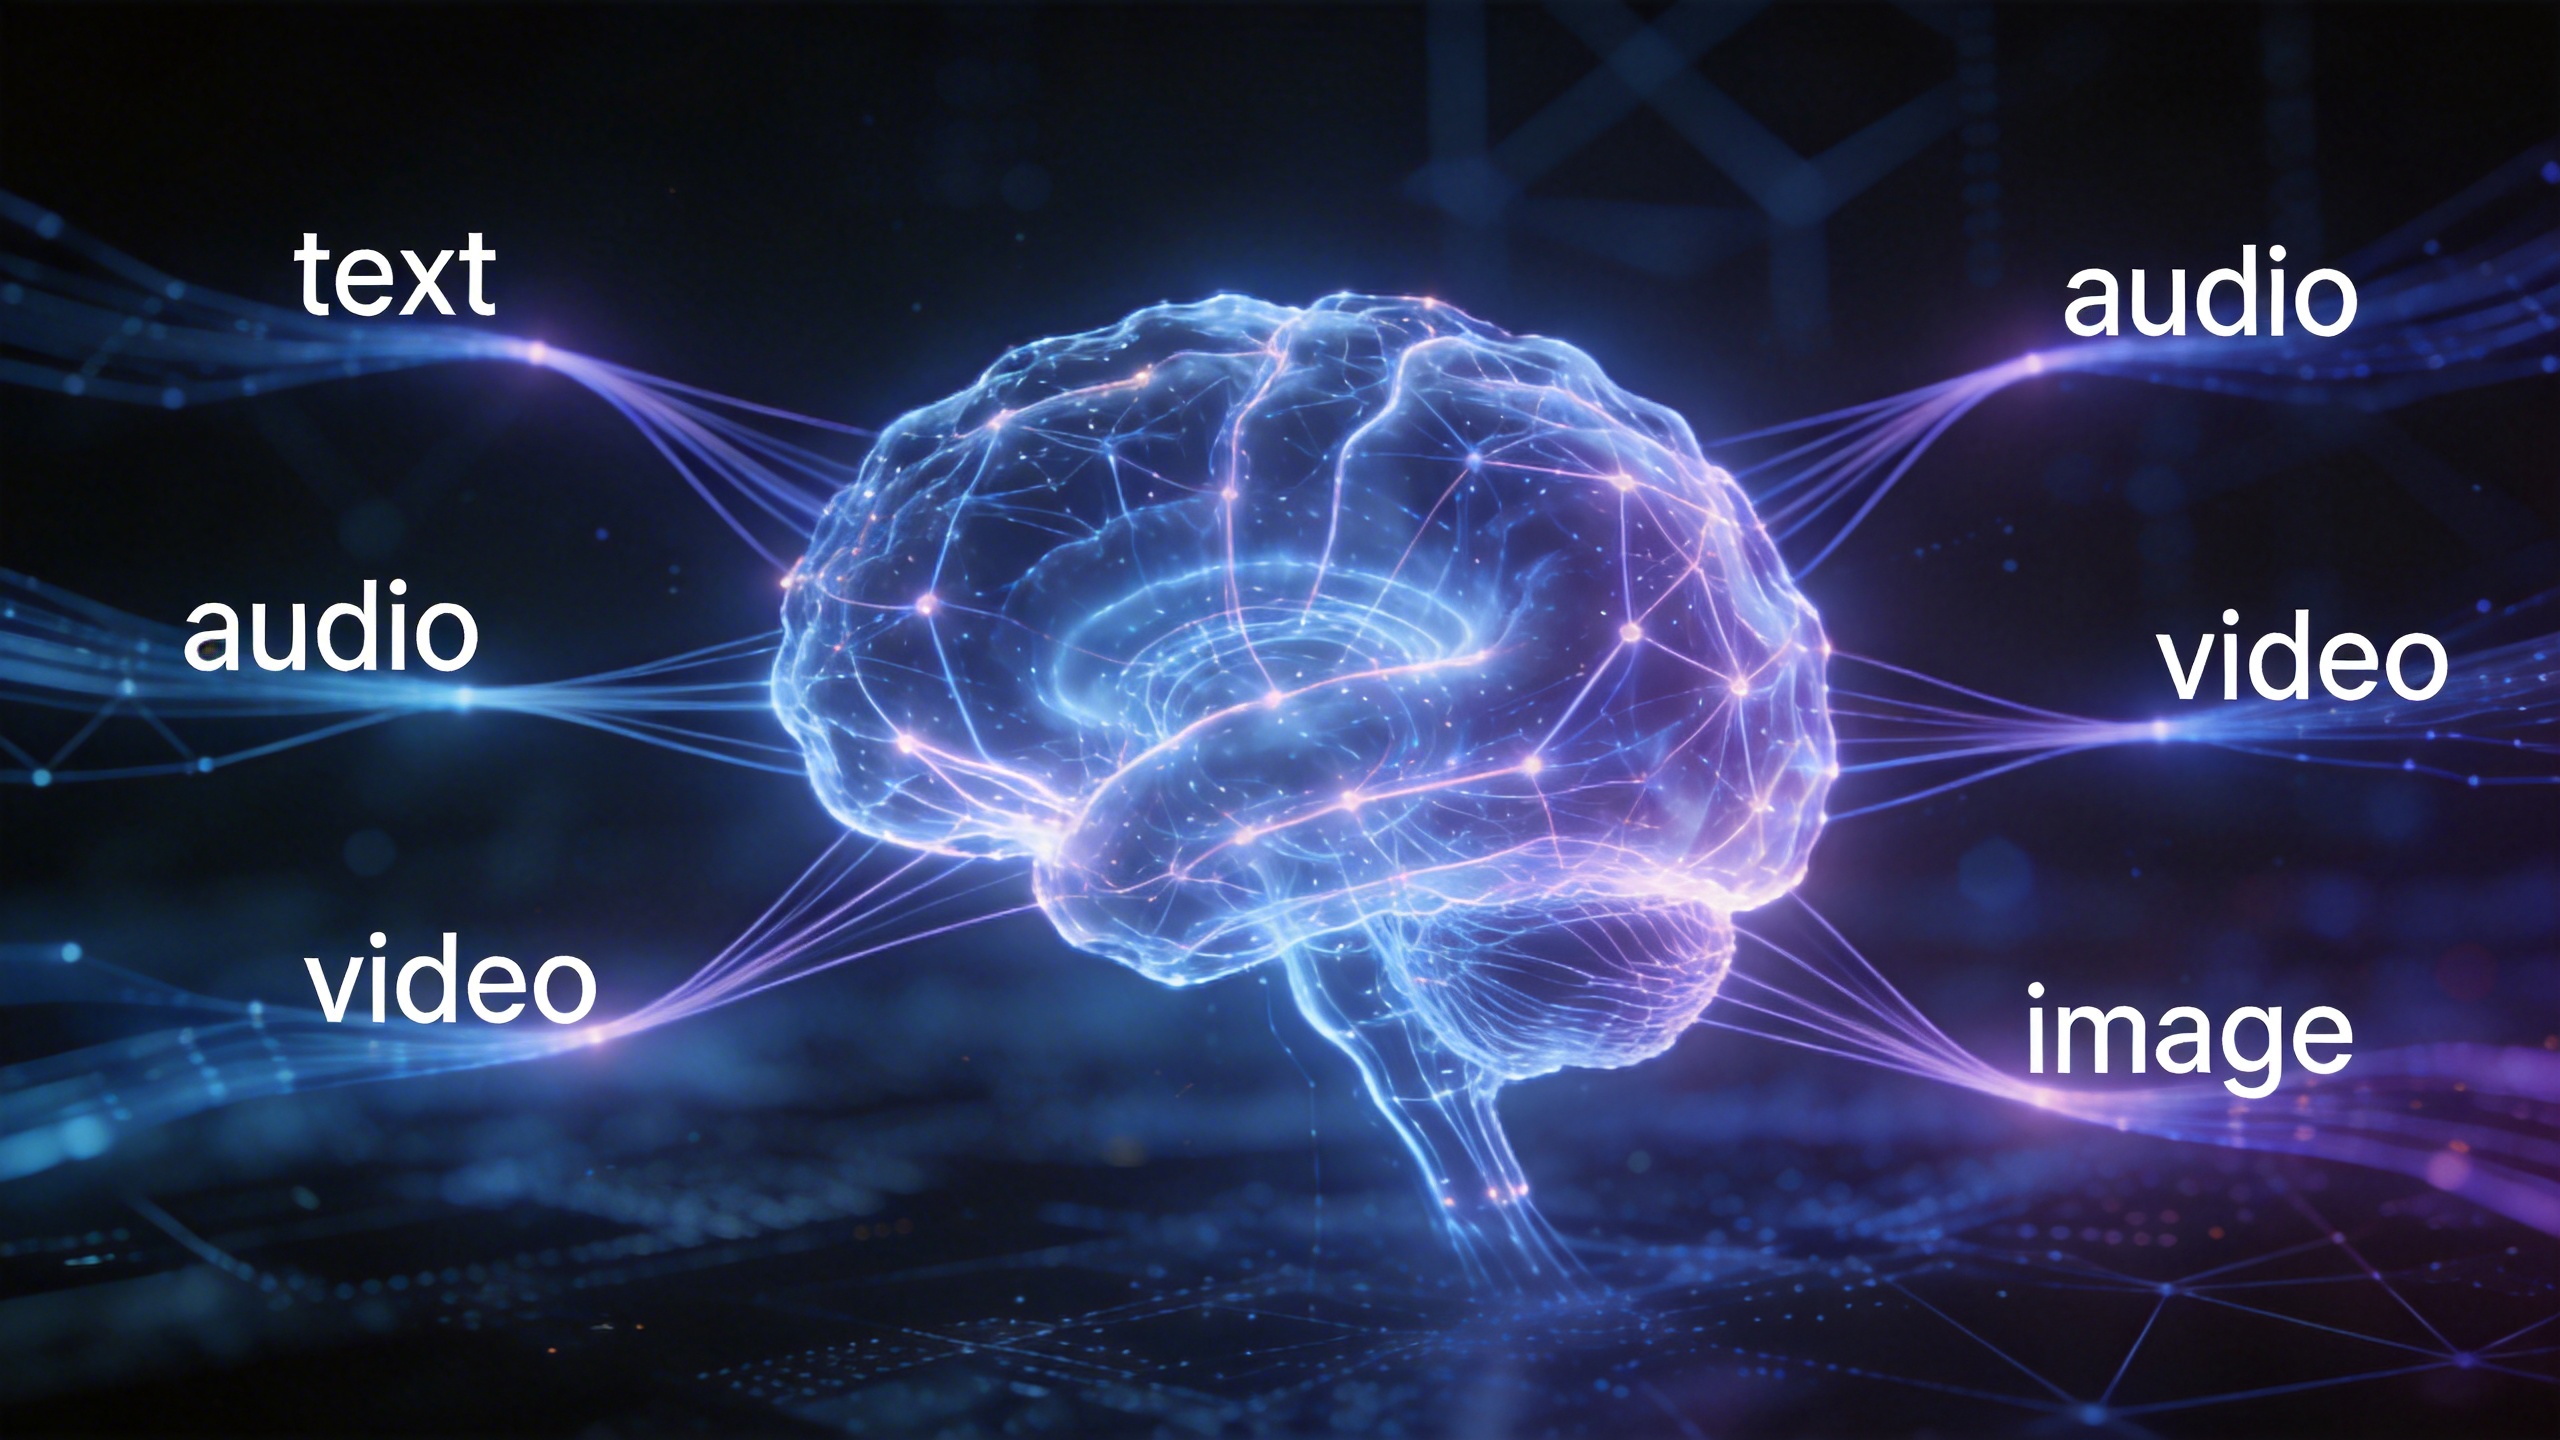
Qwen3.5-Omni: Alibaba’s Omnimodal AI Speaks 36 Languages and Codes from Voice
On March 30, 2026, Alibaba’s Qwen team released Qwen3.5-Omni — a natively omnimodal AI model that processes text, images, audio, and video while generating real-time speech output. Available in three sizes (Plus, Flash, and Light), the model claims 215 state-of-the-art benchmark results and introduces features like semantic interruption, voice cloning, and an emergent “Audio-Visual Vibe […]
-
ZML: A Zig-Based Inference Engine Bringing LLMs to AMD GPUs
ZML, a Paris-based open-source project, is gaining traction as a production inference stack written almost entirely in Zig — bypassing the Python and PyTorch dependency chains that dominate AI infrastructure. With its v2 release on March 24, 2026, ZML now compiles large language models directly onto NVIDIA, AMD, Google TPU, and AWS Trainium hardware from […]
-
Google’s TurboQuant Cuts LLM Memory 6x with Zero Accuracy Loss
On March 25, 2026, Google Research introduced TurboQuant — a new compression algorithm that reduces LLM key-value (KV) cache memory by 6x and delivers up to 8x inference speedup on NVIDIA H100 GPUs, all with zero accuracy loss. The algorithm, set to be presented at ICLR 2026, could reshape how organizations deploy large language models […]