Key points
- On February 4, 2026, Mistral AI launched Voxtral Transcribe 2, a dual-model family with a high-accuracy batch transcription model and an open-weights real-time model.
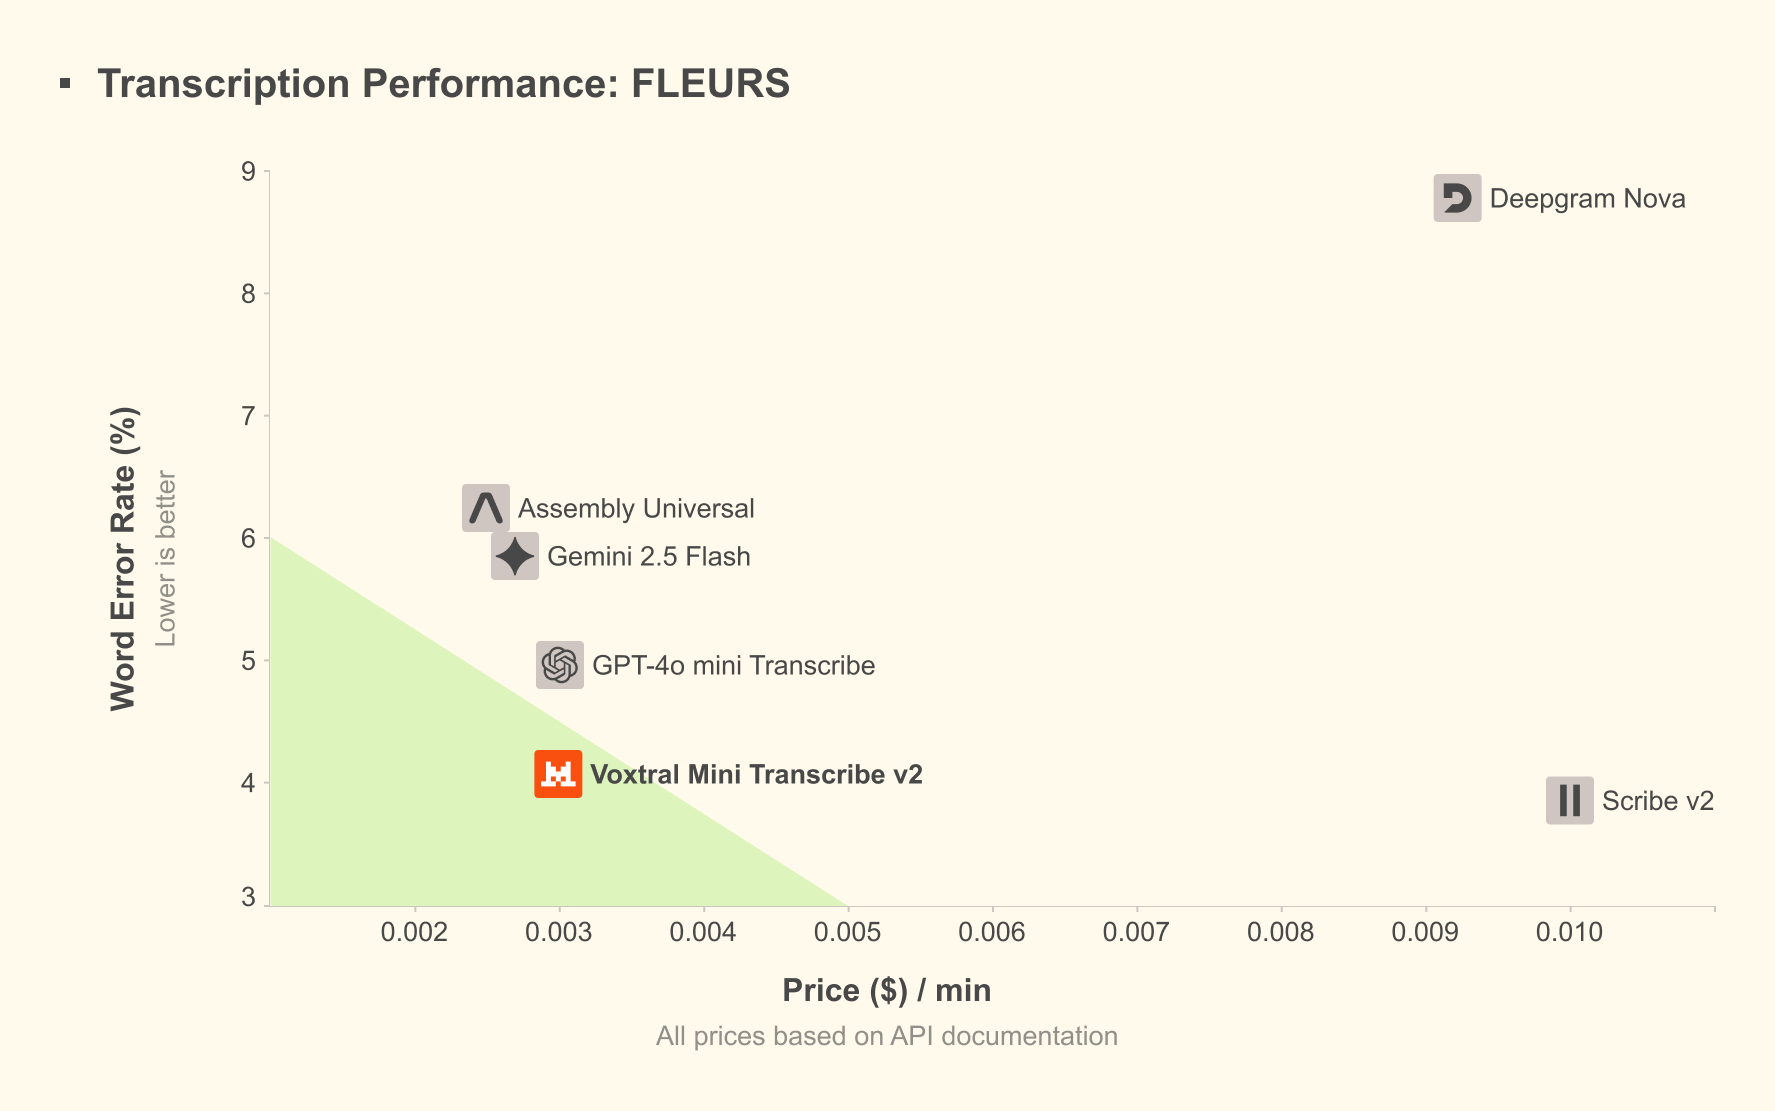
- Mistral’s batch transcription model, Voxtral Mini Transcribe V2, achieves approximately 4% word error rate on the FLEURS benchmark, outperforming GPT-4o mini, Gemini 2.5 Flash, AssemblyAI Universal and Deepgram Nova on accuracy, and is priced at $0.003 per minute.
- The batch model supports speaker diarization, context biasing with up to 100 custom vocabulary words, word-level timestamps, noise robustness and audio files up to 3 hours long.
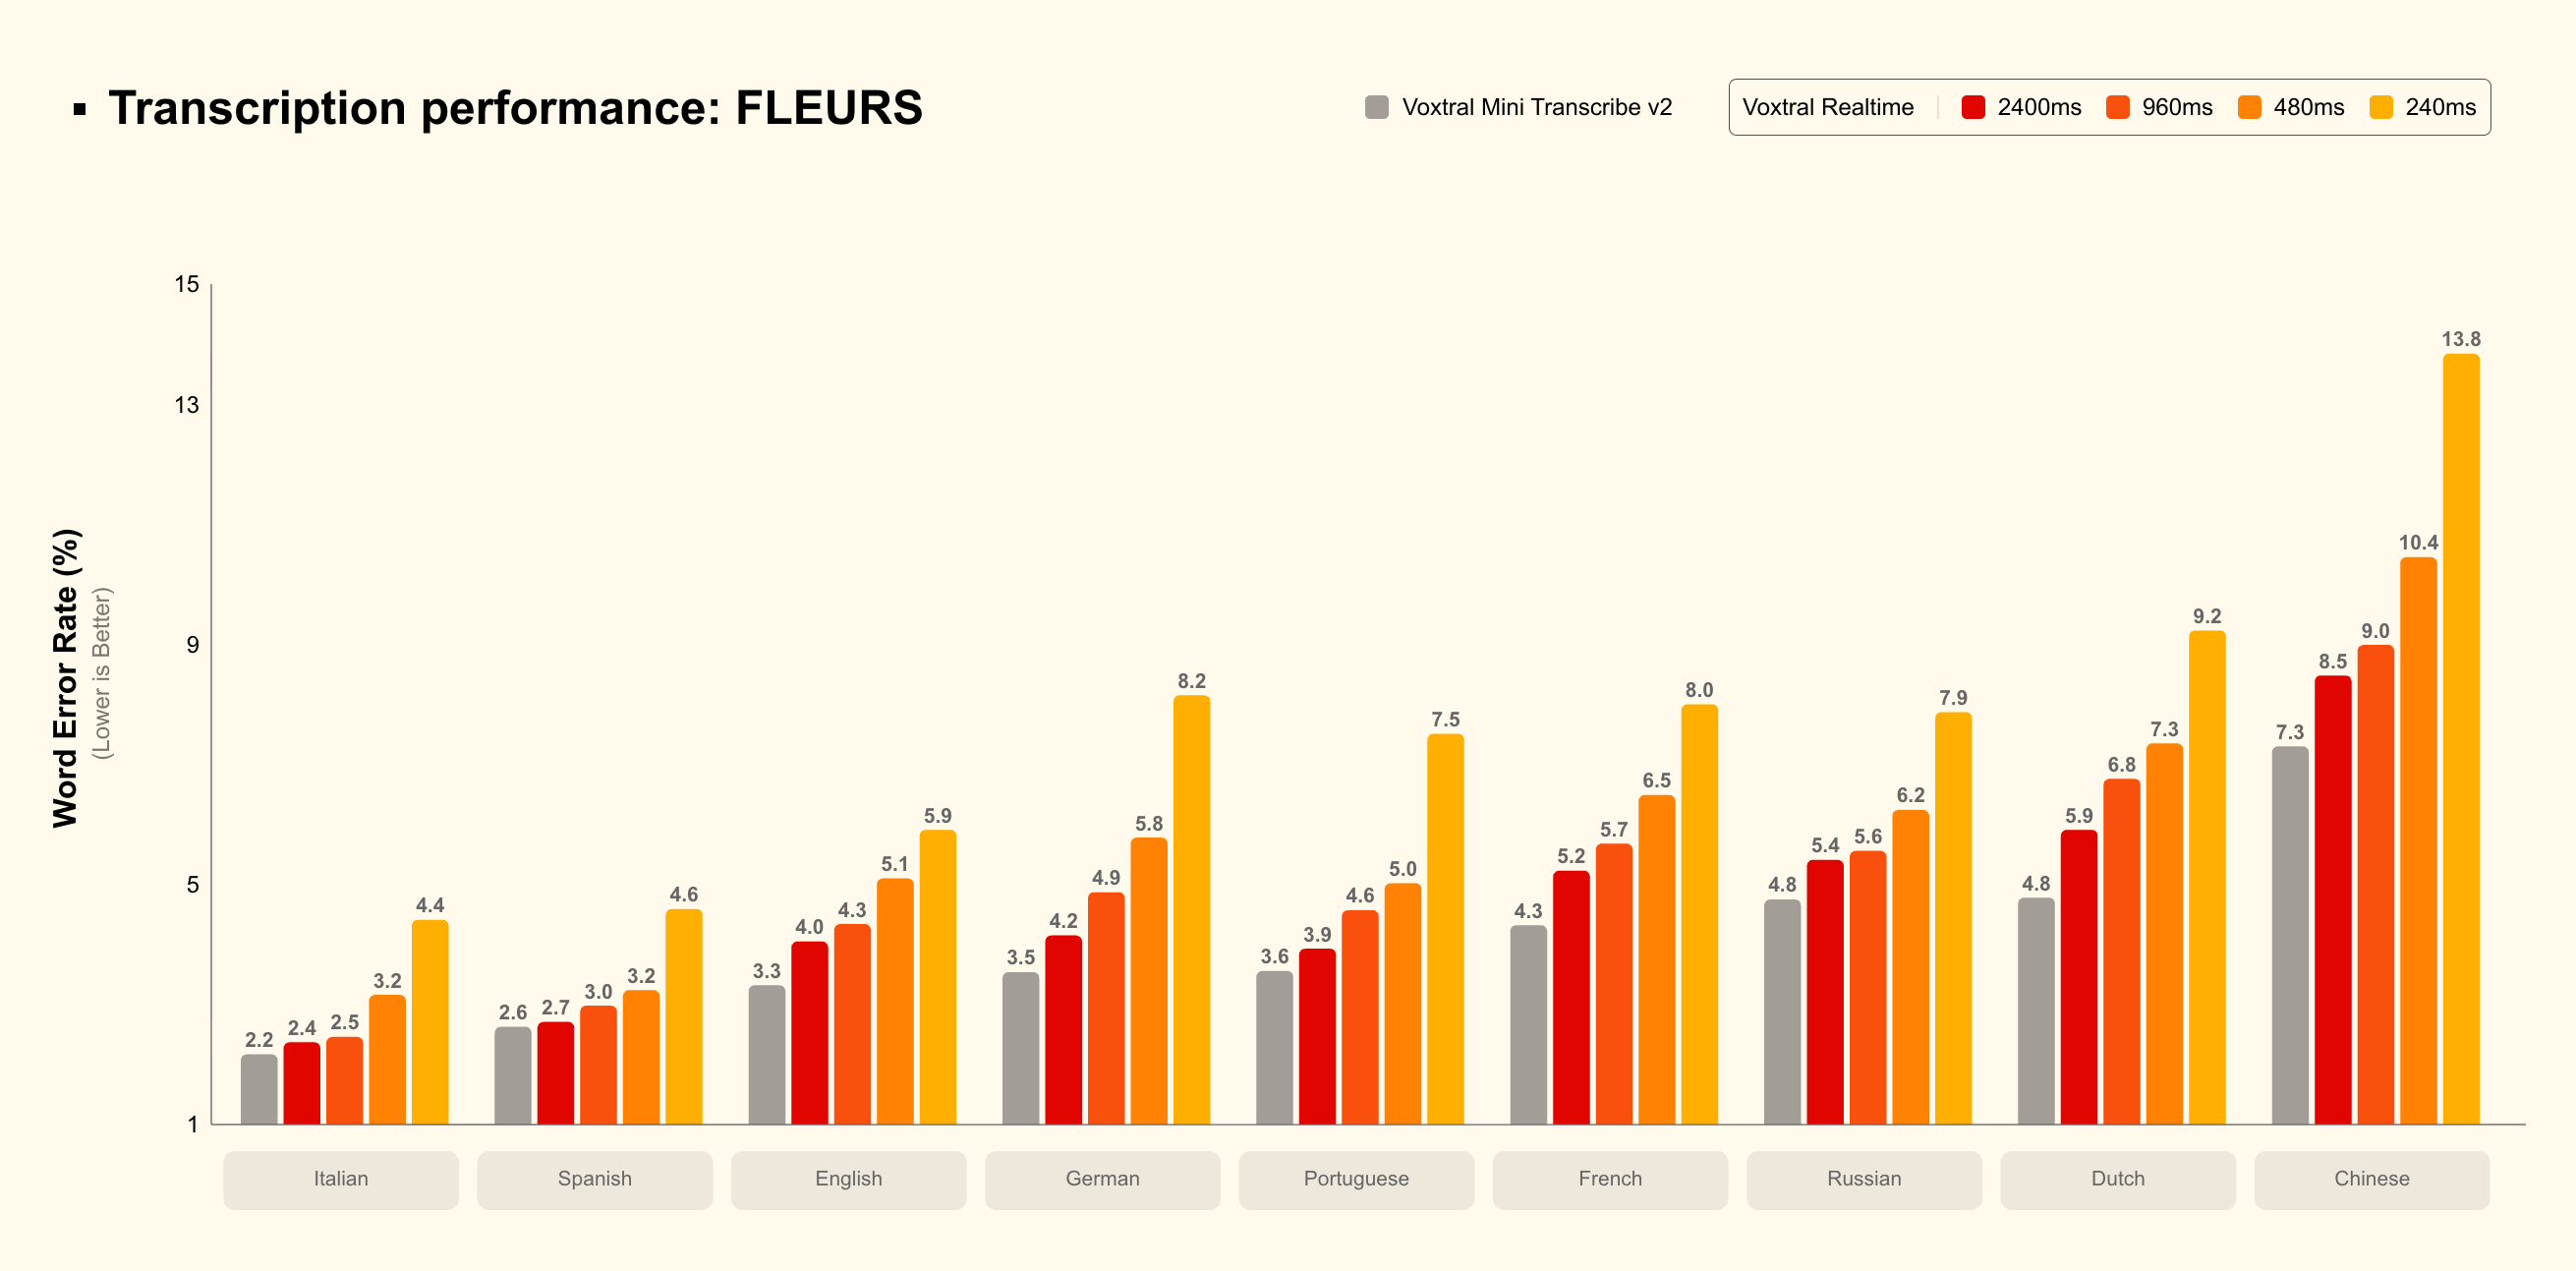
- Voxtral Realtime is built on a 4-billion-parameter architecture with configurable latency down to sub-200ms, staying within 1-2% word error rate at a 480ms delay setting.
- Voxtral Realtime is released as open weights under the Apache 2.0 license on Hugging Face, with API access priced at $0.006 per minute.
On February 4, 2026, Mistral AI launched Voxtral Transcribe 2 — a next-generation speech-to-text platform combining two specialized models: a high-accuracy batch transcription model and an open-weights real-time model for live applications. The release marks a significant step forward in open, production-grade audio AI, offering competitive accuracy, multilingual support, and pricing well below existing alternatives.
Two Models, Two Use Cases
Voxtral Transcribe 2 ships as a dual-model family designed to cover both asynchronous and real-time workloads.
Voxtral Mini Transcribe V2 targets batch processing pipelines where accuracy is paramount. It achieves approximately 4% word error rate on the FLEURS benchmark — outperforming GPT-4o mini, Gemini 2.5 Flash, AssemblyAI Universal, and Deepgram Nova on accuracy. Key capabilities include:
- Speaker diarization — automatic identification of who said what
- Context biasing — up to 100 custom vocabulary words to improve domain-specific accuracy
- Word-level timestamps for precise audio alignment
- Noise robustness and support for audio files up to 3 hours long
- 13 languages: English, Chinese, Hindi, Spanish, Arabic, French, Portuguese, Russian, German, Japanese, Korean, Italian, and Dutch
- Priced at $0.003/minute
Voxtral Realtime is built for latency-sensitive applications such as voice agents and live captioning. Based on a 4-billion-parameter architecture suited for edge deployment, it delivers configurable latency down to sub-200ms. At a 480ms delay setting, it stays within 1–2% word error rate — competitive with significantly larger batch-only models. It is released as open weights under the Apache 2.0 license on Hugging Face, making it one of the few production-quality open-source real-time ASR models available. API access is priced at $0.006/minute.
Speed, Cost, and Compliance
Beyond accuracy, Voxtral Mini Transcribe V2 processes audio approximately 3× faster than ElevenLabs Scribe v2 while matching quality at roughly one-fifth the cost. For organizations transcribing at scale — contact centers, media companies, or research institutions — this combination of throughput and cost efficiency is meaningful.
Both models are designed for GDPR-compliant deployments. Because Voxtral Realtime’s open weights allow on-premise or private cloud hosting, sensitive audio never needs to leave an organization’s own infrastructure. This addresses a growing concern in healthcare, legal, and financial use cases where audio data carries strict privacy obligations.
A new Audio Playground in Mistral Studio allows developers to test transcription quality interactively before committing to API integration.
What This Means for Voice AI
Voxtral Transcribe 2 arrives at a moment when speech-to-text is becoming infrastructure — embedded in meeting tools, voice agents, contact center platforms, and broadcast workflows. The release is notable for several reasons:
First, it closes the gap between open and proprietary ASR quality. Voxtral Realtime is open-weights and Apache 2.0 licensed, a combination that was previously hard to find at this performance level. Second, the integrated speaker diarization in the batch model removes the need for a separate diarization service — a common friction point in production pipelines. Third, the pricing model is aggressive: at $0.003/minute, a 1-hour meeting costs $0.18 to transcribe with full speaker identification.
The release also builds directly on Mistral’s earlier Voxtral family (July 2025), which introduced multilingual speech understanding. Voxtral Transcribe 2 sharpens the focus on transcription accuracy and deployment flexibility, suggesting a deliberate strategy to own the audio intelligence stack alongside their text LLMs.
Related Coverage
- Voxtral Mini 3B & Small 24B — Frontier Open-Source Speech Understanding by Mistral AI — The original Voxtral release from July 2025, introducing multilingual speech understanding models in Mini and Small sizes.
- Mistral AI Releases Magistral Small 2509 — Mistral’s reasoning-focused LLM released in September 2025.
This post was drafted with AI assistance and reviewed by RITS staff.
Leave a Reply