Key points
- MiniMax released M3.1 Flash on October 19, 2026, through its API, M Plan subscription and MiniMax Code, at $0.15 per million input and $0.60 per million output tokens.
- The launch post says weights will be released later, while several outlets report October 23; no M3.1 Flash repository existed in MiniMax’s Hugging Face organisation on October 20.
- MiniMax’s developer guide lists a 428B-parameter mixture-of-experts model with about 23B active parameters and a 1M-token context window.
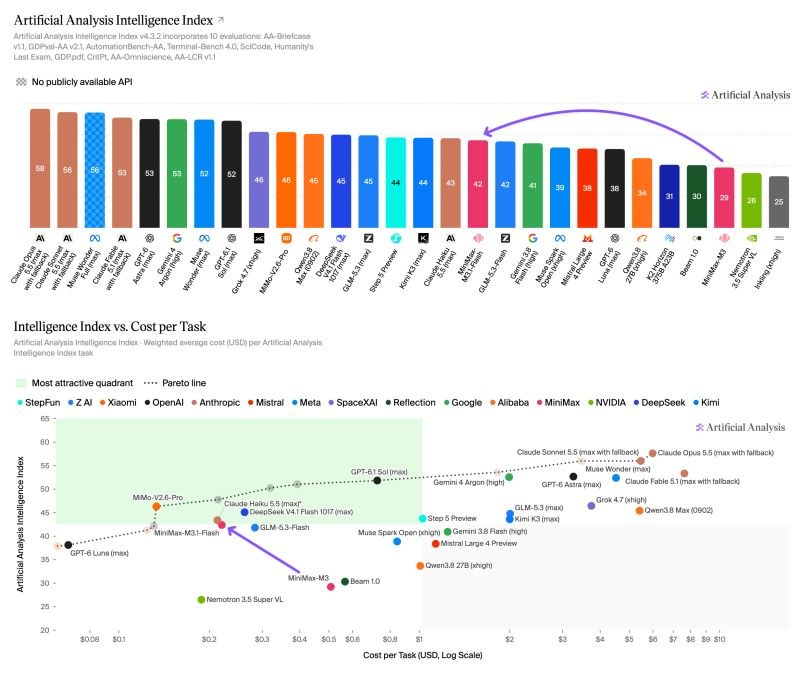
- Artificial Analysis lists M3.1 Flash at 43 on its Intelligence Index, up from 29 for M3, at roughly $0.22 per benchmark task.
- MiniMax confirmed that “Space Bunny”, an anonymous model that processed more than 200 trillion tokens on routing services, was an early build of M3.1 Flash.
Intermediate
What Actually Shipped
The release is live: M3.1 Flash is on the MiniMax API, the M Plan subscription and the MiniMax Code agent. Pricing is flat at $0.15 per million input tokens, $0.60 per million output tokens and $0.015 per million cached input tokens. The context window is 1,000,000 tokens, with up to 524,288 tokens of output, and it takes text, images and video. Reasoning cannot be switched off; developers pick one of five effort levels — low, medium, high, xhigh or max, the default. What has not shipped is the model file. MiniMax’s own post says the weights “will be released later”, and a search of MiniMax’s Hugging Face organisation on October 20 found no M3.1 Flash repository. OpenRouter’s listing says “open weights are planned”, and no licence for the new model has been published; M3’s weights have been on Hugging Face since June under a community licence. The reported October 23 date is a plan, not a checkpoint. Speed claims are vendor measurements for now. MiniMax says inference is nearly three times faster than M3, with 200+ tokens per second in everyday use; Artificial Analysis measured 123 tokens per second for the hosted model, above its 116 average.The Benchmarks, and Who Measured Them
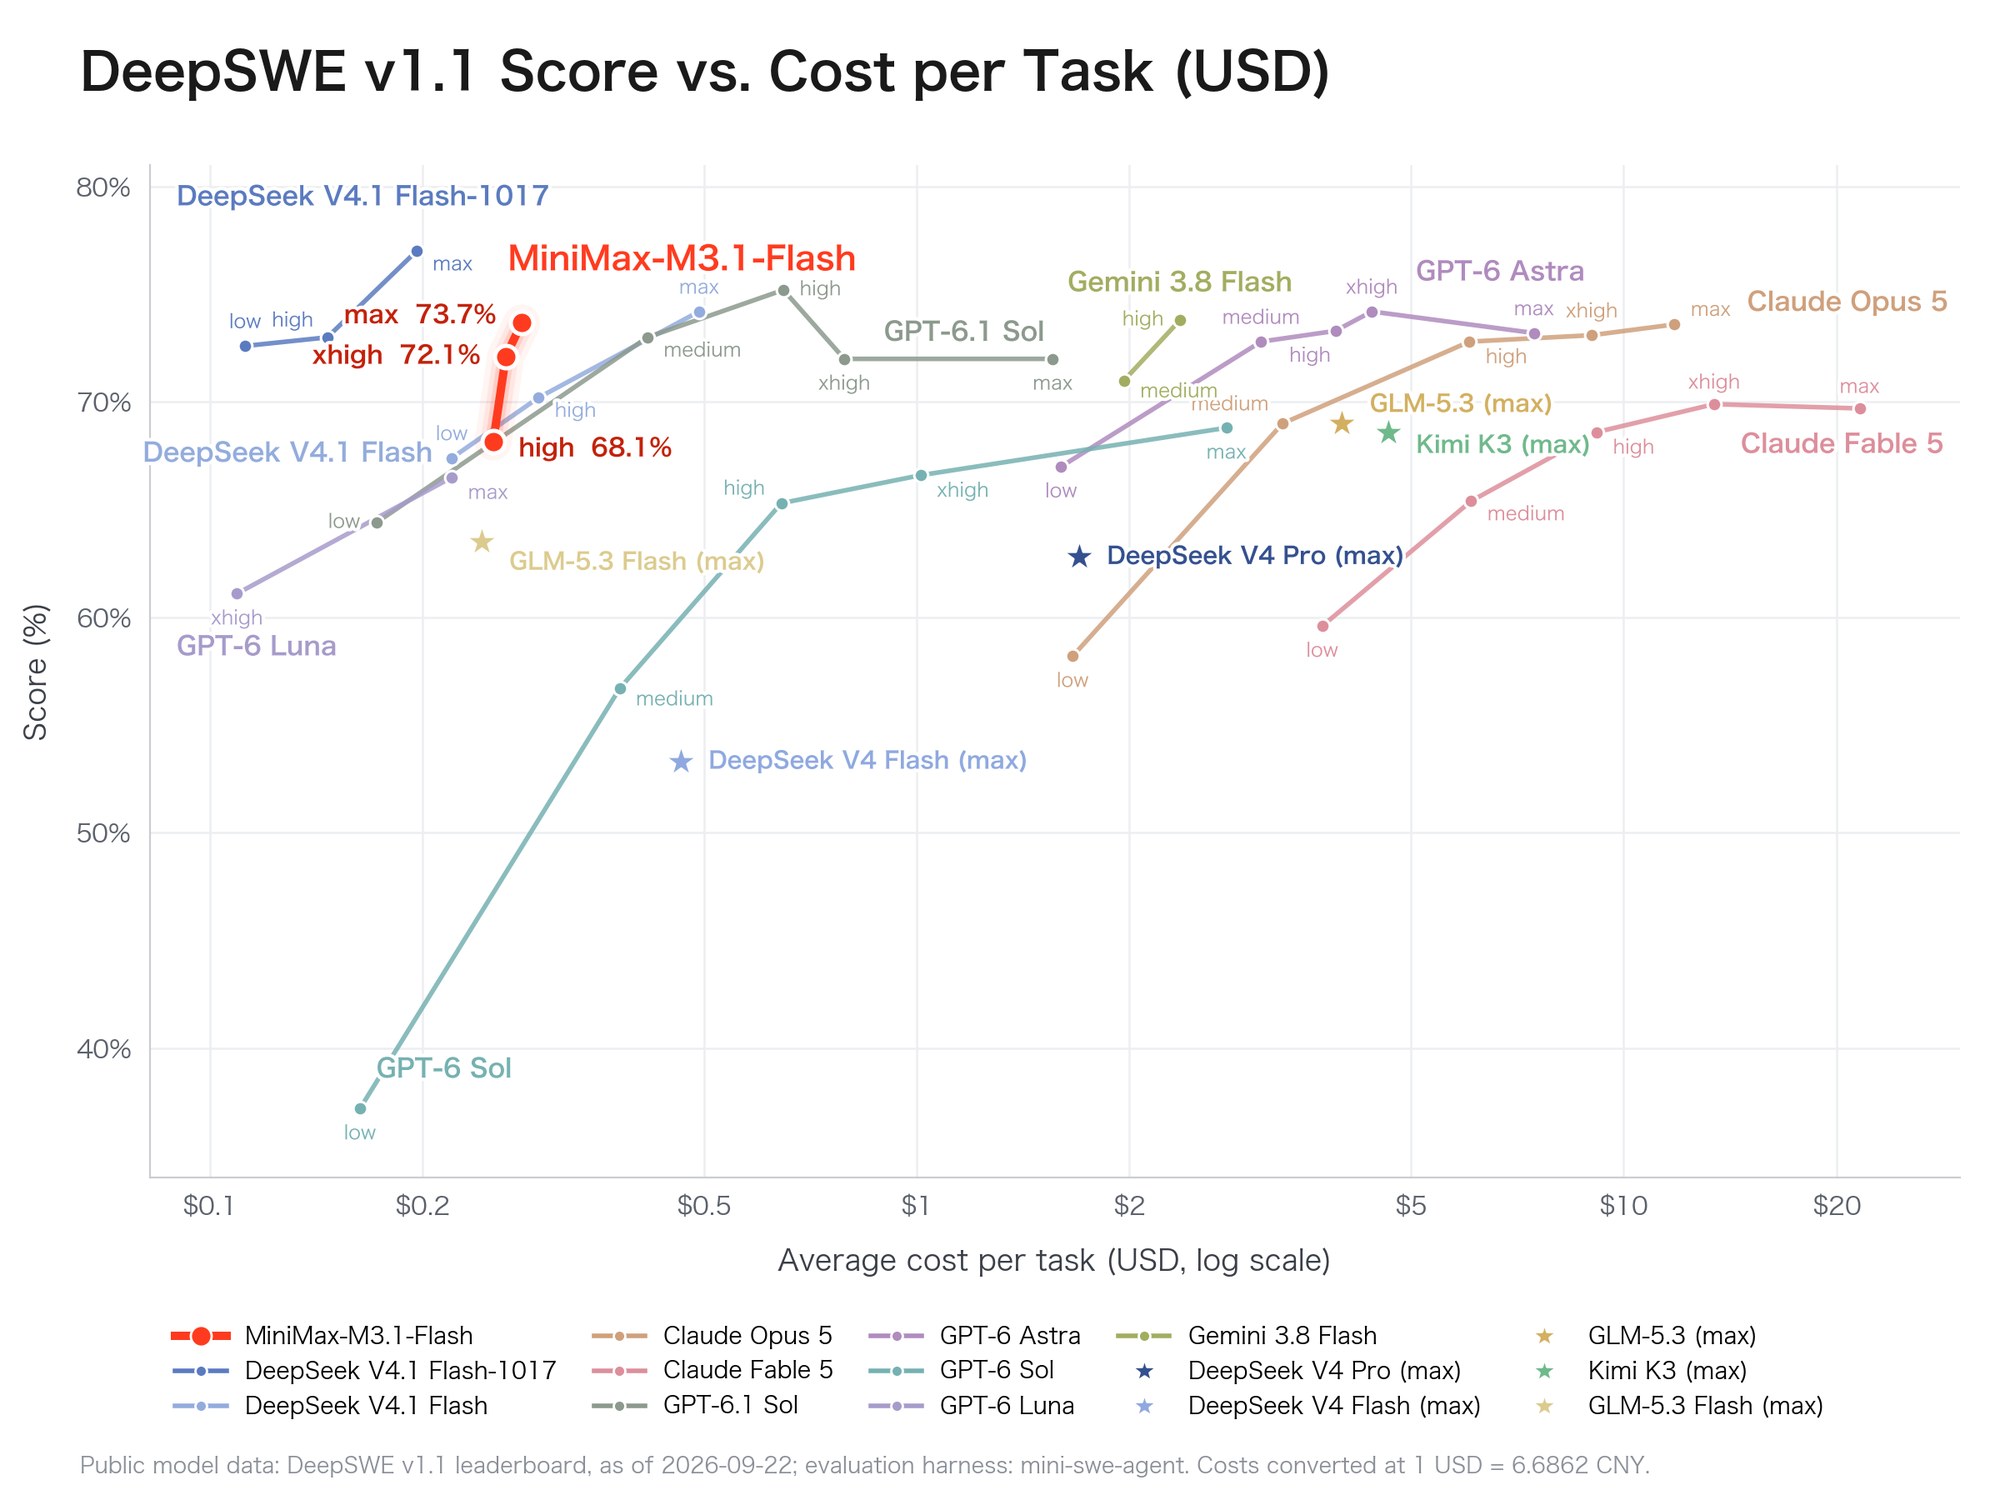
MiniMax’s table puts M3.1 Flash at 73.7% on DeepSWE v1.1, 62.8 on Automation-Bench v1.0.6, 76.2 on BankerToolBench, 61.7 on OSWorld 2.0, 29.6 on Agents’ Last Exam and 82.2% on CyberGym. The company says it ranks first among Chinese models on OSWorld 2.0 and ALE. In the same table DeepSeek’s V4.1-Flash-1017 scores 77.0 on DeepSWE, ahead of M3.1 Flash; none of these vendor numbers has been independently reproduced.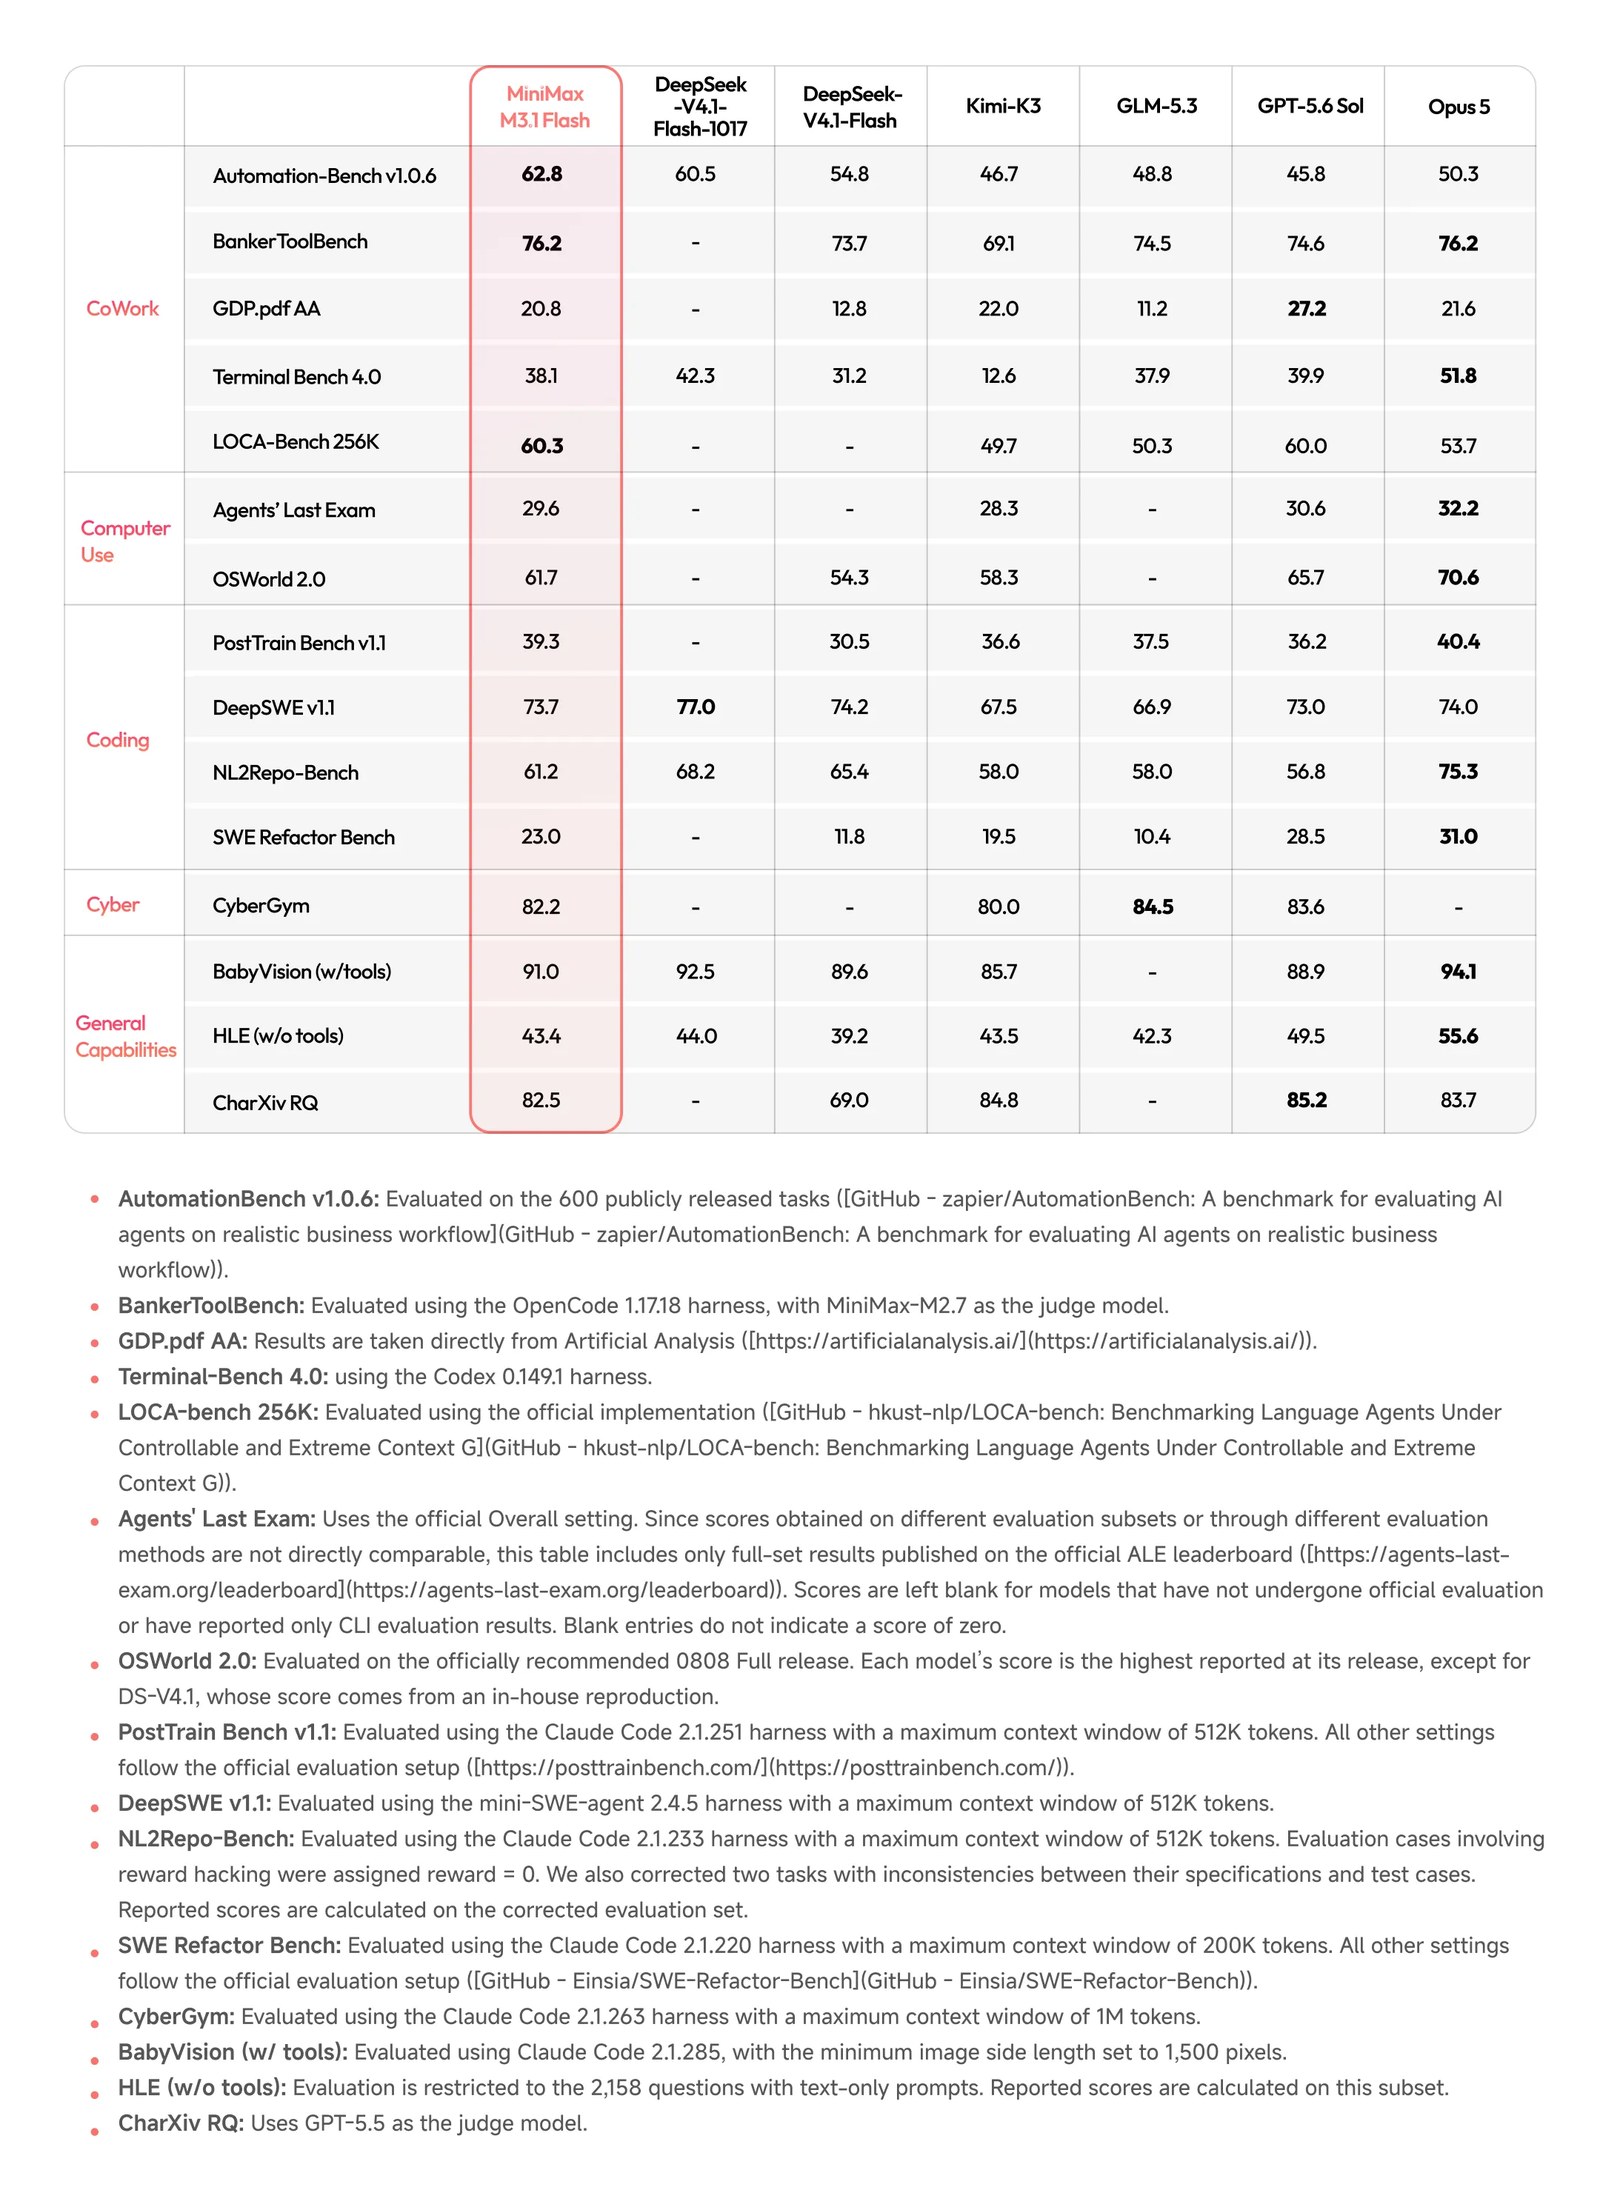
Same Size, More Sparsity
M3.1 Flash keeps the M3 architecture: a mixture-of-experts model with roughly 428 billion total parameters and about 23 billion active per token, per M3’s model card. The gain comes from what the company calls “more aggressive sparsity” at inference time rather than a larger model — a tuning of the MiniMax Sparse Attention mechanism M3 introduced in June, which selects blocks of the uncompressed key-value cache instead of attending over all of it. Hence a cost-and-throughput headline rather than a new capability ceiling. The launch also closes a two-week mystery. “Space Bunny”, which topped routing-service usage charts anonymously after appearing in late September, was an early M3.1 Flash build, MiniMax said, processing more than 200 trillion tokens. A “Pro” tier is promised for later.What This Means
The number that matters here is not the Intelligence Index but $0.22 per completed task. M3.1 Flash arrives in the same week as DeepSeek’s V4.1-Flash-1017 at an identical $0.15 input price; the two split the results: DeepSeek leads on the aggregate index, MiniMax on factual accuracy. For teams running multi-step agents, where one job can mean dozens of calls, that gap compounds. October 23 decides a second question. A 428B model is well over 200 GB at four bits per weight, so open weights matter most to inference providers and researchers, not laptop users. If the checkpoint lands under terms as permissive as M3’s community licence, M3.1 Flash becomes one of the cheapest frontier-adjacent models anyone can host. If the licence arrives with territorial or commercial restrictions, the API is the product and “open” is marketing. Nothing is downloadable today.Related Coverage
- MiniMax M3: Frontier Coding, 1M Context, and Sparse Attention — the June 2026 predecessor whose sparse-attention design M3.1 Flash inherits.
- MiniMax Opens Music 3.0 Weights — No Territorial Carve-Out This Time — MiniMax’s August licence terms.
- MiniMax Ships H3 Weights — With the US and EU Excluded — the territorial carve-out that makes the unpublished licence worth watching.
Sources
- MiniMax: “MiniMax M3.1 Flash: Redefining Agent Performance and Cost” (October 19, 2026)
- MiniMax API documentation: Model Invocation — MiniMax-M3.1-Flash
- Artificial Analysis: MiniMax-M3.1-Flash intelligence, performance and price analysis
- The Decoder: “MiniMax M3.1 Flash shows China’s AI price race has no floor in sight” (October 19, 2026)
- SiliconANGLE: “MiniMax launches M3.1 Flash model, says it cuts AI agent costs by 70%” (October 19, 2026)
- Hugging Face: MiniMaxAI/MiniMax-M3 model card and weights
- OpenRouter: MiniMax M3.1 Flash listing