Tag: open source
-
IBM Releases Granite 4.1: Dense 8B Matches Prior 32B MoE Flagship
On April 29, 2026, IBM Research released the Granite 4.1 family — a refreshed lineup of dense, decoder-only language models in 3B, 8B, and 30B parameter sizes, plus updated speech, vision, embedding, and Guardian safety models. All weights ship under an Apache 2.0 license, and the headline result is striking: the new 8B instruct model […]
-
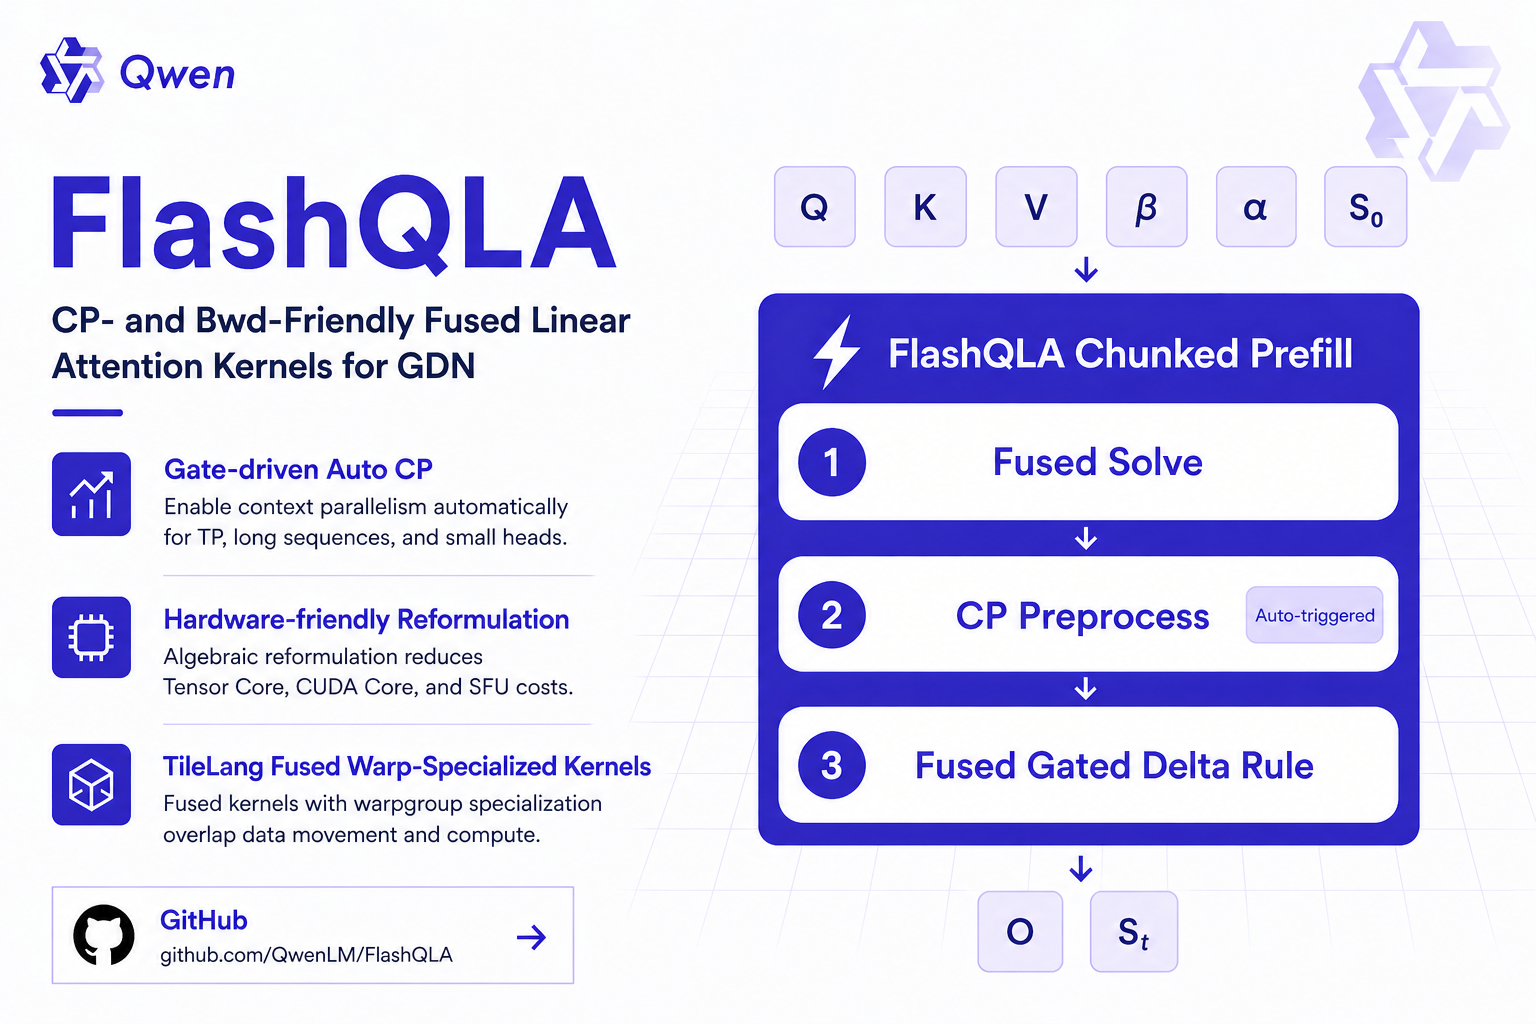
Qwen Releases FlashQLA: 2-3x Faster Linear Attention Kernels on Hopper
Qwen has open-sourced FlashQLA, a high-performance linear attention kernel library built on TileLang that targets the GDN (Gated Delta Network) Chunked Prefill workload. Released in late April 2026 under the MIT License, FlashQLA reports a 2–3× forward-pass speedup and roughly 2× backward-pass speedup over the FLA Triton kernels, and roughly 2× over FlashInfer 0.6.9 on […]
-
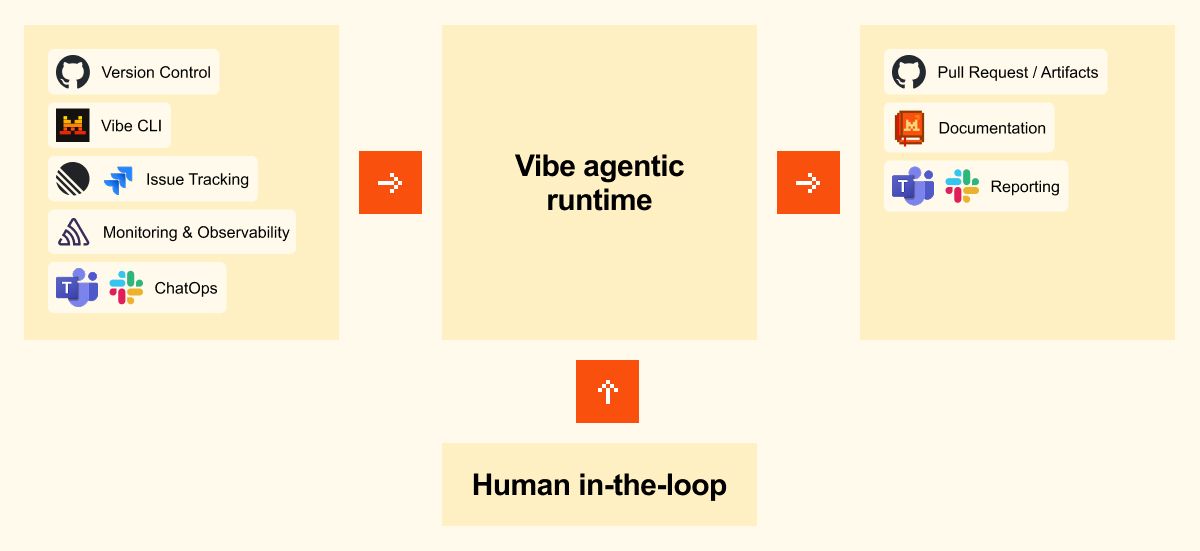
Mistral Medium 3.5 Launches with Vibe Remote Coding Agents
On April 29, 2026, Mistral AI launched Mistral Medium 3.5 — a 128-billion-parameter dense multimodal model with a 256k context window — alongside Vibe remote agents, a cloud-based system that runs coding sessions asynchronously and in parallel. The model unifies instruction following, reasoning, and coding into a single set of weights, replaces Devstral 2 in […]
-
Xiaomi Releases MiMo-V2.5-Pro: 1T-Parameter Open MoE Matches Frontier Coding Models
Xiaomi released MiMo-V2.5-Pro on April 22, 2026, a 1.02-trillion-parameter Mixture-of-Experts model with 42 billion active parameters that matches frontier coding and agentic benchmarks while costing a fraction of comparable closed models. The release also unifies reasoning and multimodal abilities into a single open-weights model with a 1-million-token context window. Intermediate Key points Xiaomi released MiMo-V2.5-Pro […]
-
Luce DFlash Brings 2x Speculative Decoding to Qwen3.6-27B on a Single RTX 3090
Luce DFlash now runs Qwen3.6-27B on a single RTX 3090, delivering up to 2× throughput over autoregressive decoding. The Lucebox Hub project, which hand-tunes LLM inference for specific consumer GPUs, ported its DFlash speculative decoding stack to Qwen3.6-27B in late April 2026. Because Qwen3.6-27B reuses the Qwen3.5 architecture string with identical layer and head dimensions, […]
-
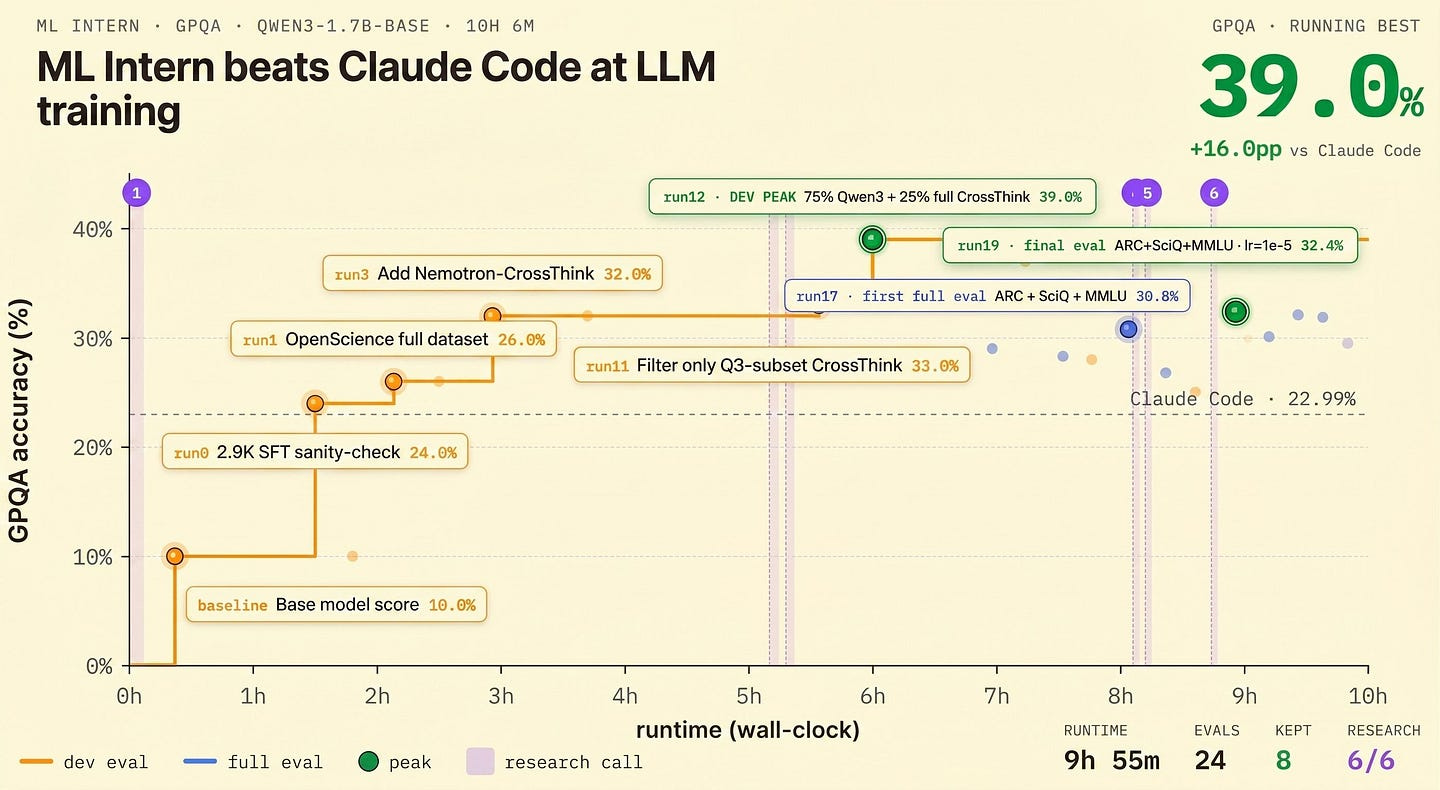
Hugging Face Releases ml-intern: An Open-Source Agent That Automates Post-Training
Hugging Face released ml-intern on April 21, 2026 — an open-source autonomous agent that runs the full LLM post-training loop, from literature review to evaluation. In benchmark testing, the agent took a Qwen3-1.7B model from a roughly 10% baseline to 32% on GPQA in under 10 hours on a single H100, surpassing Claude Code’s 22.99% […]
-
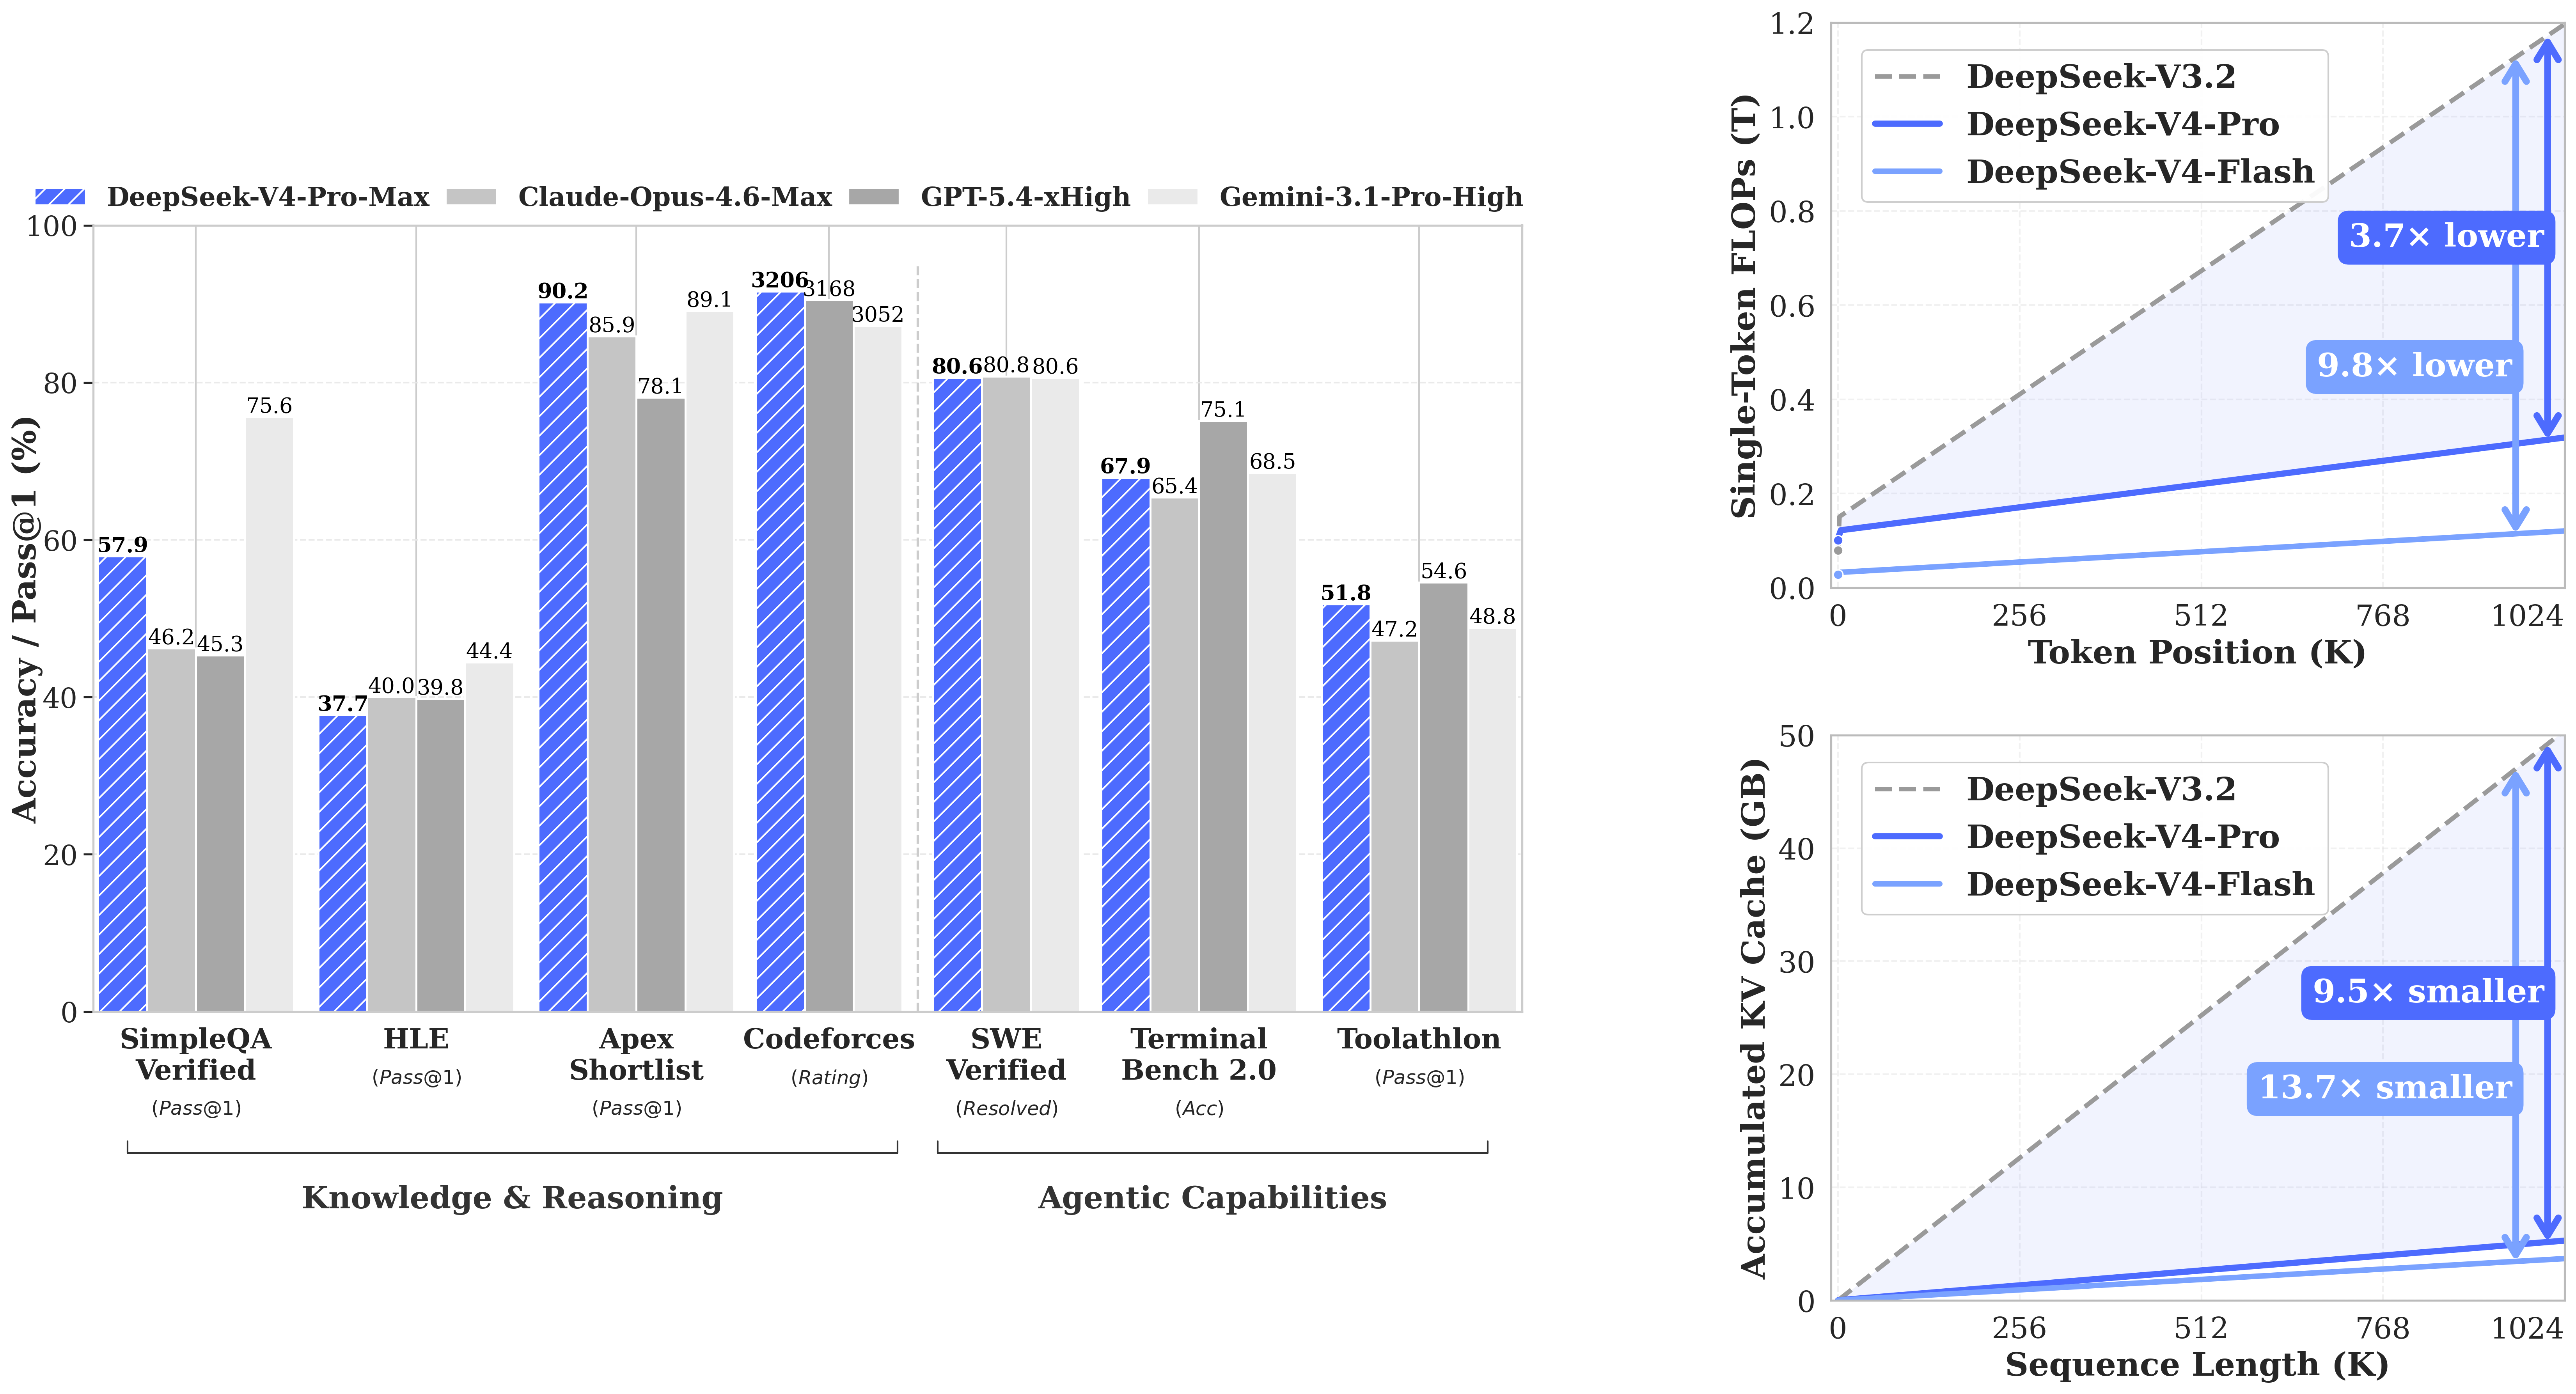
DeepSeek Releases V4: Open-Source 1.6T MoE with 1M Context
DeepSeek has launched V4, its newest flagship open-source language model, exactly one year after the V3/R1 releases that rattled Silicon Valley. Announced on April 24, 2026, the V4 family ships in two Mixture-of-Experts variants — a 1.6-trillion-parameter V4-Pro and a leaner 284-billion-parameter V4-Flash — both supporting a 1-million-token context window and both released with open […]
-
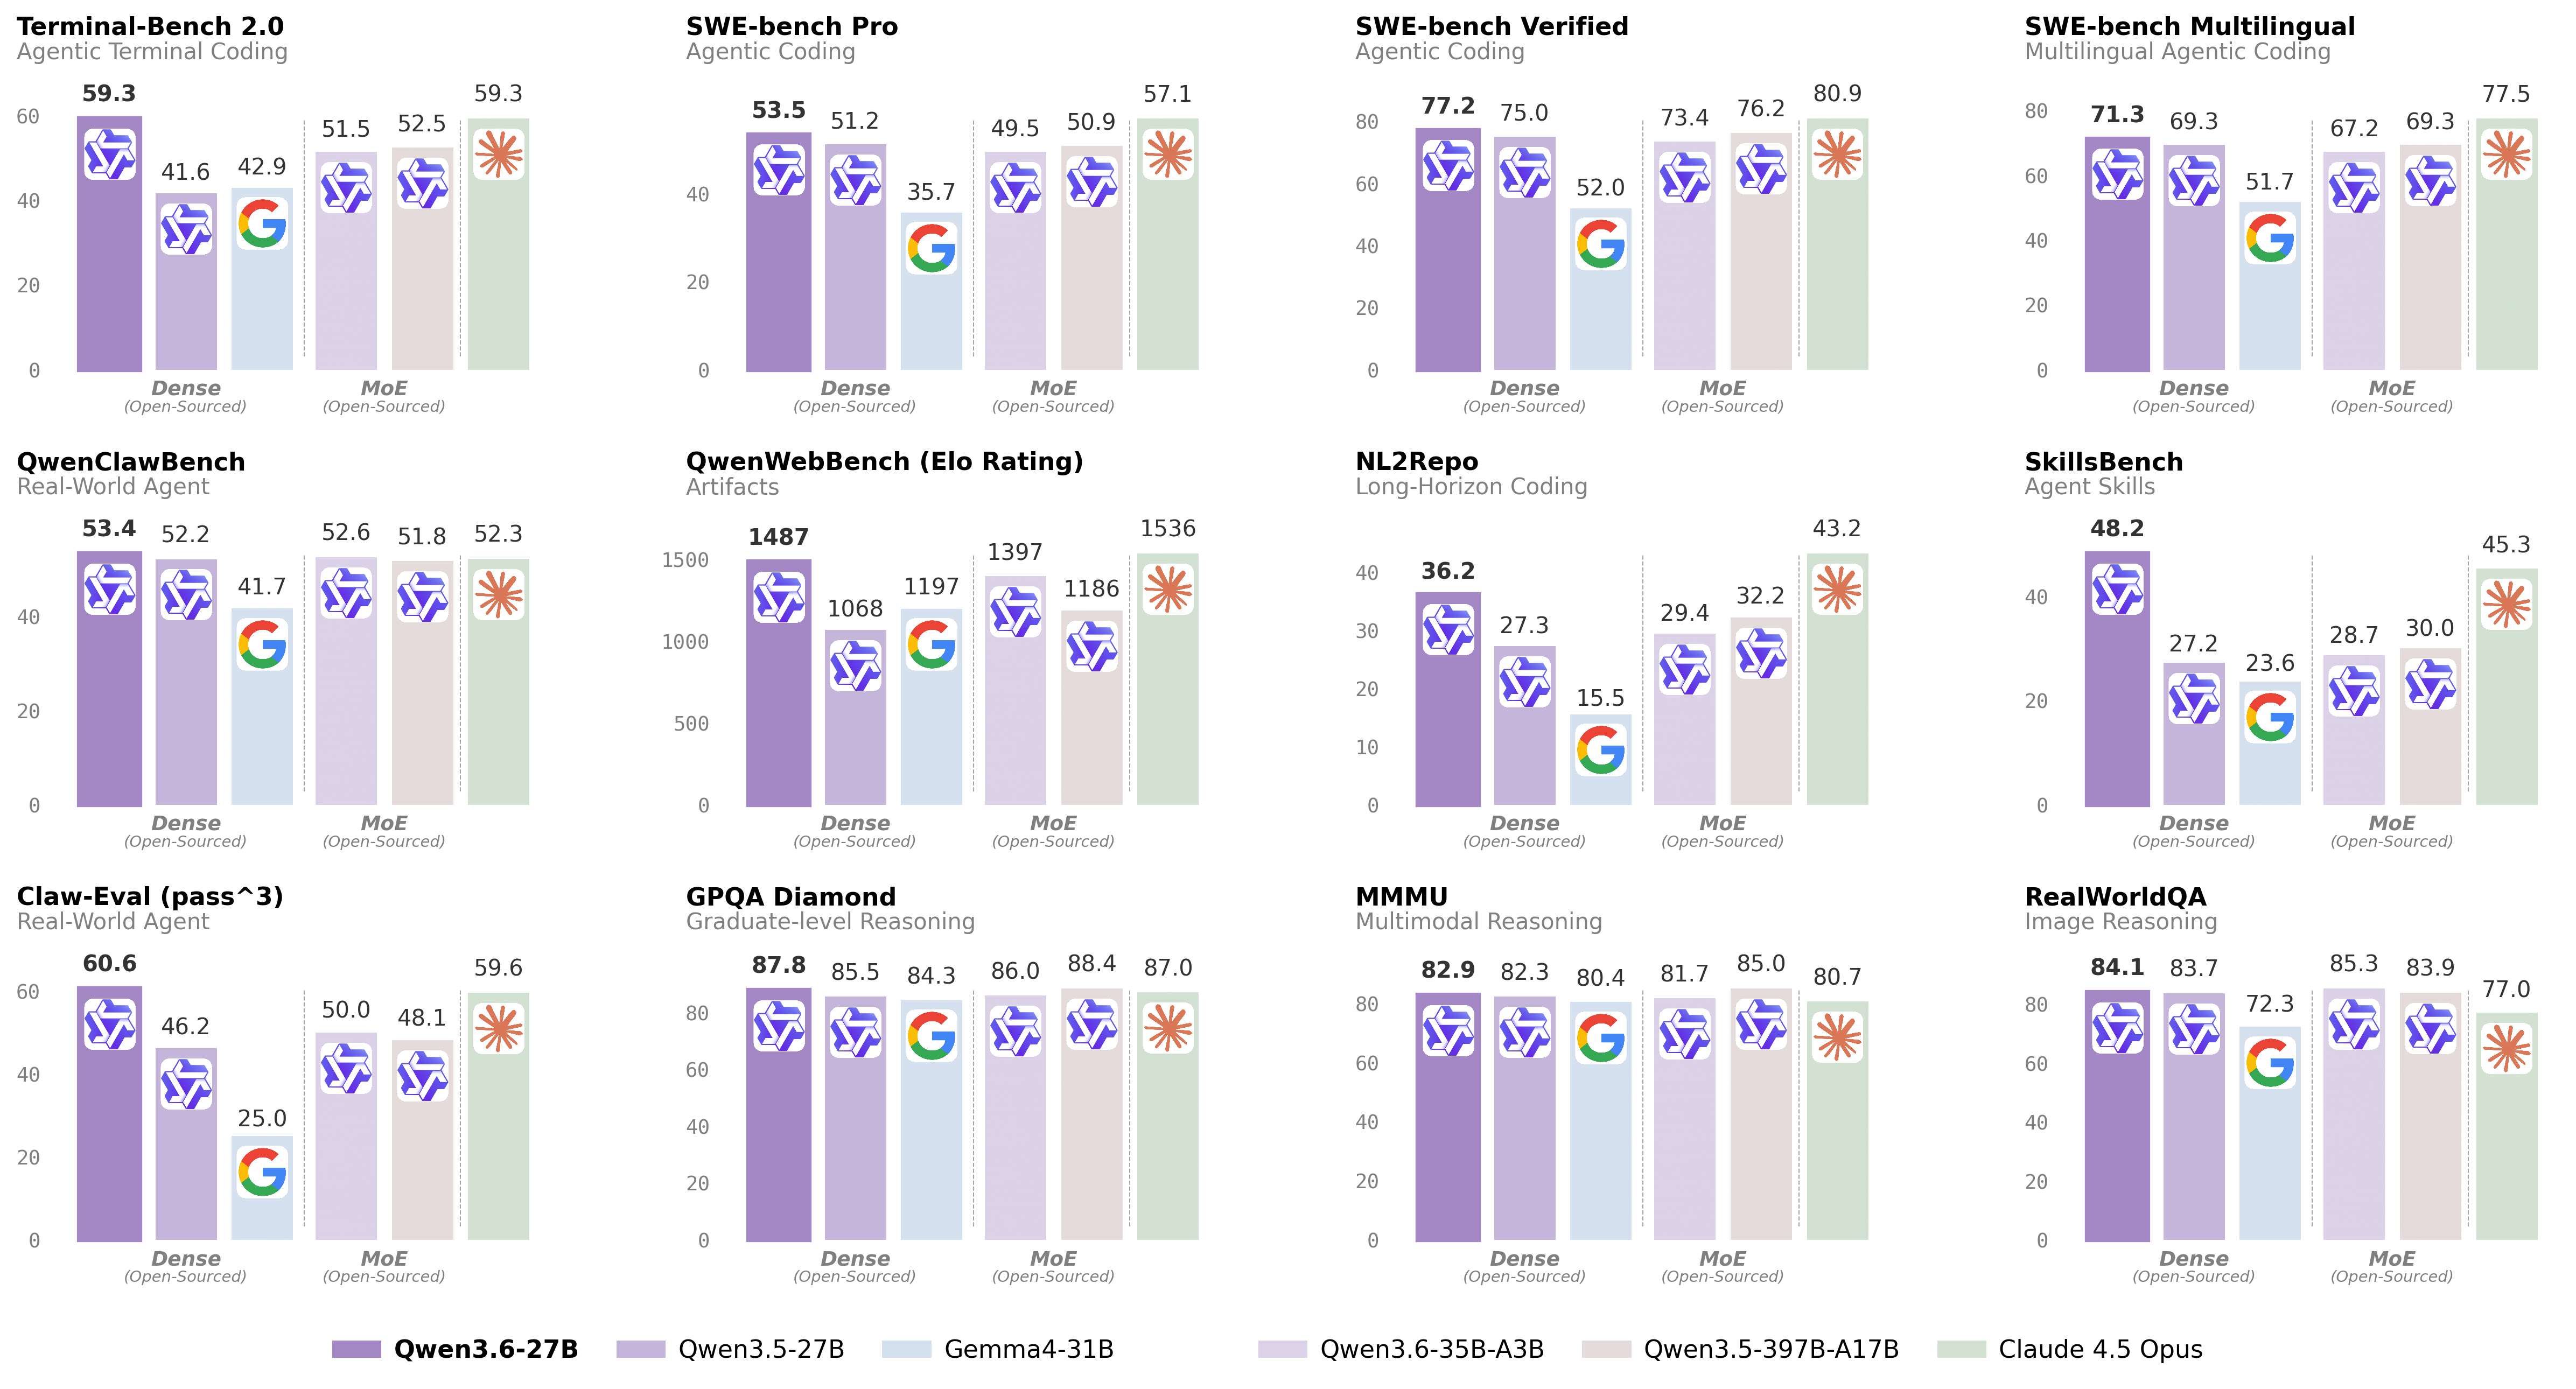
Qwen3.6-27B: A Dense 27B Model That Beats a 397B MoE on Coding
On April 22, 2026, Alibaba’s Qwen team released Qwen3.6-27B — the first dense open-weight model in the Qwen3.6 generation. Released under Apache 2.0 on Hugging Face, the 27-billion-parameter multimodal model posts flagship-level agentic coding scores that beat the team’s previous-generation 397B Mixture-of-Experts flagship across multiple benchmarks, while fitting into a 16.8 GB Q4_K_M quantization that runs […]
-
Moonshot AI Releases Kimi K2.6 with 256K Context and 300-Agent Swarms
Moonshot AI released Kimi K2.6 on April 20, 2026, shipping an open-weight trillion-parameter Mixture-of-Experts model that leads headline agentic and coding benchmarks against GPT-5.4 and Claude Opus 4.6, while pushing its Agent Swarm system to 300 sub-agents running 4,000 coordinated steps. The weights are available on Hugging Face under a Modified MIT License, and the […]
-
Qwen3.6-35B-A3B: Alibaba Open-Sources a Frontier-Class Agentic Coder
On April 2, 2026, Alibaba’s Qwen team open-sourced Qwen3.6-35B-A3B — the first open-weight variant of the Qwen3.6 generation. Released under Apache 2.0 on Hugging Face alongside the proprietary Qwen3.6-Plus API model, the 35-billion-parameter Mixture-of-Experts model activates just 3B parameters per token while posting frontier-level scores on agentic coding and reasoning benchmarks, including 73.4 on SWE-bench […]